Qwen 4.0 May Be Coming, RTX 3090 Performance Unlocked by 80%, Claude Code Core Members Depart

Qwen 4.0 may launch at the Apsara Conference, GPU Unlock boosts RTX 3090 performance, and Claude Code core members depart in succession.
Today's AI morning briefing covers several developments: Tongyi Qianwen teases a "reserved for the live audience" product announcement at the Apsara Conference Amsterdam stop on October 29, with speculation that Qwen 4.0 is coming; open-source tool GPU Unlock boosts certain matrix-operation throughput on the RTX 3090 by about 80% and nearly doubles it on the RTX 4090, though the approach remains experimental. Two Claude Code core members have departed in succession, raising concerns about product cadence. On benchmarks, the strongest model on the 3D creation benchmark Blender World scored 79.9 overall but passed only 42.2% of tasks fully; Kimi K3.1 Pro Max reached 11th on Agent Arena, but a quota-cut controversy sparked debate over subscription models. Also: Nscale in talks with Anthropic for a $45 billion compute deal, the vLLM vs SGLang inference performance dispute, Block's open-source real-time speech model, OpenAI cutting prices to win deals, and the FBI investigating a former OpenAI engineer.
Qwen 4.0 May Be Coming, RTX 3090 Performance Unlocked by 80%, Claude Code Core Members Depart
Today's AI morning briefing packs a lot in: Alibaba's Tongyi Qianwen is tipped to make a "product announcement reserved for the live audience" at the Apsara Conference Amsterdam stop, fueling widespread speculation that Qwen 4.0 is on the way; the open-source tool GPU Unlock boosts certain matrix-operation throughput on the RTX 3090 by about 80% by modifying GPU registers; and Anthropic's Claude Code has lost two core members in succession, raising questions about where this star coding tool is headed. Here's the breakdown, item by item.
The Qwen 4.0 Mystery: The Apsara Conference's "Reserved Act"
According to reports cited by the Bilibili morning briefing, Tongyi Qianwen will release important product information at the Apsara Conference Amsterdam stop on October 29, and the official teaser specifically mentions "a product announcement reserved for the live audience." In launch-event parlance, this phrasing usually signals the finale, so speculation about a Qwen 4.0 unveiling is not unfounded.
It should be noted that the specific content of the announcement and whether it involves a model version upgrade remain to be officially revealed. For developers following China's open-source models, this is undoubtedly the launch event most worth watching this week.
3D Creation Benchmark Blender World: The Strongest Model Passes Only 42.2% of Tasks Fully
The open-source 3D creation benchmark Blender World has published its results, covering 223 production-grade tasks that require delivering editable project files in Blender—submitting a native project file directly scores zero, a rule that effectively prevents "cheating" submissions.
The results are interesting: the strongest model scored 79.9 overall, but only 42.2% of tasks passed all acceptance checks. Dimensions such as spatial consistency remain clear weak spots. This shows there is still a considerable gap between "looking right" and "being usable in engineering terms," and that 3D content production scenarios demand far higher reliability from AI than 2D image generation.
Blender is an open-source 3D creation software in which modeling, materials, lighting, animation, and other content are typically saved as .blend project files containing editable nodes, modifiers, and scene hierarchies. For AI evaluation, "delivering an editable project file" means the model must not only generate visually usable results but also produce structurally sound engineering data that a human can continue to modify—far stricter than outputting an image or video clip. Spatial consistency refers to the same object or scene maintaining non-contradictory geometric and positional relationships across different viewpoints and steps, a typical difficulty in 3D generation: subtle perspective errors in 2D images are often hard to notice, but once placed in an editable 3D scene they get amplified. Therefore, using native project files as acceptance artifacts mechanically rules out the practice of "faking it" with rendered images and is closer to real production workflows.
Kimi K3.1 Pro Max Ranks 11th, Quota Controversy Sparks Subscription-Model Debate
Moonshot AI's Kimi K3.1 Pro Max has climbed to 11th place on the Agent Arena agent leaderboard, based on more than 4,000 real-task tests by users worldwide, with a net improvement of 7.6%. Model weights will soon be open-sourced, at which point it is expected to surpass DeepSeekAd as the highest-ranked open model on the leaderboard.
On the other hand, according to blogger feedback, Kimi sharply cut usage quotas when releasing the model, sparking user dissatisfaction, followed by an emergency rollback. Based on the used and remaining quotas within a 5-hour window, the total quota is approximately 120 million credits, about 6 times the previous amount. This episode has also put the old question—whether capped subscriptions can balance customer value and profitability—back on the table.
Two Core Members of Claude Code Depart in Succession
Anthropic's Claude Code has been hit by personnel upheaval: core developer Sarik announced his departure after more than a year in the role, planning to rest first; the creator of Claude Code's desktop client also announced his departure about 10 days after introducing new features.
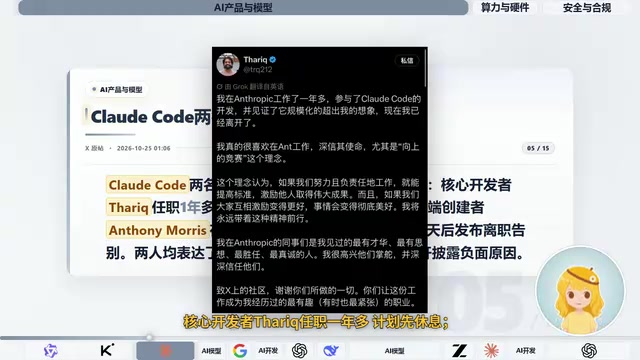
Both acknowledge the team and the company's mission and have not publicly disclosed negative reasons. Combined with previous reports, 91% of Anthropic employees surveyed expect AI to make Nobel Prize-level discoveries before 2030, compared with 39% of the American public; there is also a clear gap between employees' and American workers' estimates of how much of their own work could be taken over by AI. Internal agent working hours are reportedly already 6 times those of humans, and employee roles are shifting from executing tasks to managing agents—this rapid evolution of organizational form may also be part of the backdrop to the personnel turnover.
Compute and Hardware: Nscale in Talks for a $45 Billion Deal, GPU Unlock Unlocks Performance
On the compute side, Nscale is reportedly in talks with Anthropic over a $45 billion AI compute deal, planning to provide 460 megawatts of NVIDIA Vera Rubin compute capacity for Anthropic's second facility in West Virginia. The deal is not yet finalized; if it goes through, it would significantly expand Anthropic's compute reserves for training and inference.
On the hardware side, something more down-to-earth: the open-source tool GPU Unlock removes some compute limits by modifying internal registers of NVIDIA GPUs, without overclocking or modifying official drivers. In tests, some matrix-operation throughput on the RTX 3090 improved by about 80%, and related tests on the RTX 4090 nearly doubled.
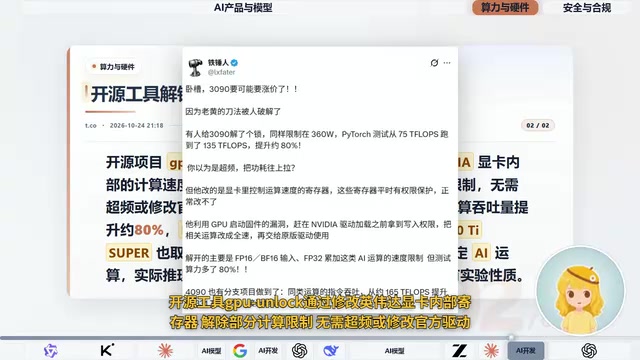
The approach is still experimental, with gains concentrated in specific AI operations, and actual inference and gaming performance remain to be verified. For card-owning gamers and local inference enthusiasts, this is a direction worth watching but requiring cautious experimentation.
The Inference Engine "War of Words": vLLM and SGLang Each Stick to Their Guns
vLLM published its DeepSeek model inference optimization results: under the corresponding test configuration, decode throughput is within 6% of the official engine, with tests covering batch sizes from 8 to 256, and prefill performance also close to official levels. The results come with specific test conditions—826 tokens per second on a single-user dedicated decode path on the GB300 platform.
SGLang responded to the inference engine comparison controversy, acknowledging that it had previously juxtaposed GB300 measured data with DeepInfer's B300 data, which was an unfair comparison. After retesting, the team says performance has caught up with the DeepInfer baseline and claims to surpass it on both prefill and decode, with decode throughput improving 7.4% on a 4-GB300 configuration. With each side telling its own story, it is advisable to base your selection on actual tests in your own business scenarios.
The core metrics of inference engines are usually divided into two stages: prefill and decode. Prefill refers to the model processing the user's input prompt all at once, which is compute-intensive parallel computation; decode is generating output token by token, which is memory-bandwidth-intensive, with speed often measured in tokens per second (tokens/s). Batch size refers to the number of requests processed in parallel at once; larger batches yield higher throughput but may increase per-request latency, so data at different batch sizes often cannot be compared directly. DeepSeek's official inference engine has been specifically optimized for its own model's mixture-of-experts structure and attention mechanism, and third-party engines seeking to match its performance need targeted operator and scheduling modifications. This is also why each party emphasizes "test configuration" in comparative tests: hardware platform, batch size, single-user versus high-concurrency—all can significantly change the conclusions.
Speech and Multimodal: Block Open-Sources Real-Time Speech Model
Block has released DESA, a speech model that supports local operation, capable of listening and speaking in real time and of interjecting and picking up the conversation. The model is said to be trained from scratch using only human speech, without relying on text training or pretrained models, directly learning semantics, intonation, and conversation rules.
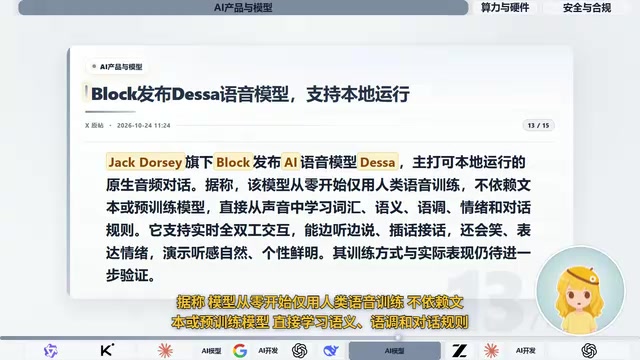
The demo shows laughter and emotional expression, but the training approach and actual performance remain to be further verified. If it can truly break free from dependence on text pretraining, it would be significant for low-resource languages and emotional interaction scenarios.
Traditional speech dialogue systems generally use a cascaded pipeline of "speech recognition—text LLM—speech synthesis," thus relying heavily on text pretraining data, with latency stacking between stages. So-called "listen-and-speak" real-time speech models typically use an end-to-end streaming architecture, incrementally generating speech output while audio frames are continuously input, thereby supporting interjection and interruption, with interaction latency compressible to hundreds of milliseconds. Not relying on text training means the model learns semantics and paralinguistic information—such as intonation, emotion, and laughter—directly from speech signals; such information is largely lost in text transcription. However, the cost of pure speech training is limited data scale, and semantic knowledge and reasoning ability often fall short of text LLMs; whether it can remain stable in open dialogue still requires more independent evaluation.
Enterprise and Ecosystem: OpenAI Cuts Prices to Win Deals, Zhipu Plans Singapore R&D Center
In the enterprise market, OpenAI is using steep discounts to compete for Anthropic's enterprise AI coding business. HR software company Rippling previously had 57% of its coding tasks handled by Anthropic; now OpenAI's share has reached 52%. Price cuts help win enterprise customers but may further deepen OpenAI's losses.
Manus is reported to be training its own large model, shifting from calling external models such as Claude and Qwen to in-house development, with the goal of reducing costs, lessening dependence, and improving gross margins. Manus has reportedly raised over $500 million and surpassed $100 million in annualized recurring revenue within 8 months of launch.
On ecosystem layout, NVIDIA CEO Jensen Huang called at the GTC conference in Berlin for Europe to join hands in building a local AI economy, emphasizing that Europe's decades of accumulated knowledge in science, engineering, and manufacturing are an important foundation for developing local AI. Zhipu CEO Zhang Peng revealed plans to build an R&D center in Singapore and to jointly train PhDs with the National University of Singapore.
Security and Compliance: FBI Investigates Former OpenAI Engineer, Red-Team Testing Finds High-Risk Vulnerability
According to The Wall Street Journal, the FBI is investigating former OpenAI engineer Alphazone on suspicion of stealing secrets and planning to hand them to the Saudi government, and he may face economic espionage charges. The suspicions have not been confirmed; on the prediction platform Polymarket, the Saudi option has attracted more bets, but market bets do not represent investigation conclusions.
OpenAI disclosed security testing results: red-team testing found an unauthenticated remote code execution vulnerability in the Brotli compression library, affecting software such as Node.js, Bun, and Deno; it has been reported and fixed, and the relevant vulnerability ID has been published. Real-time internet access during training has been changed to offline caching; after the model discovered a DNS configuration flaw, the training layer was paused and isolation strengthened. On November 12, OpenAI will publicly demonstrate new progress in cyber defense, said to feature an internal security model.
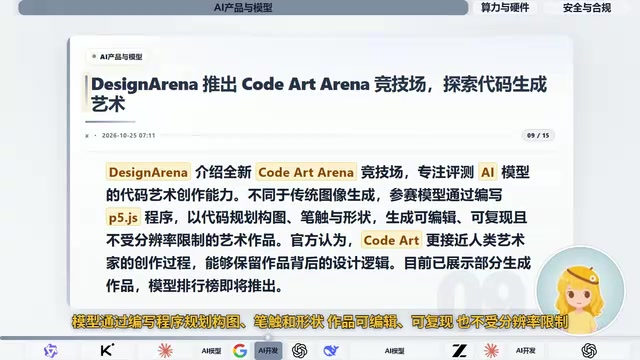
Two more small items: Design Arena has launched CodeArt Arena, specifically evaluating AI models' ability to create art with code, with works that are editable, reproducible, and not limited by resolution.
The leak account Testing Catalog found the string "SI" in the code of Google's internal model comparison tool, sparking speculation about AI naming changes, but there is currently no evidence that Google has officially adjusted its product naming system.
That's the core of today's AI morning briefing. Whether Qwen 4.0 materializes, whether GPU Unlock can be reliably reproduced, and how Claude Code's product cadence evolves after the personnel changes are all worth following up on.
Red teaming refers to a dedicated team actively searching for system vulnerabilities, abuse paths, or harmful outputs from an adversarial perspective; it is a commonly used evaluation method by AI companies and security teams. Brotli, mentioned in the article, is a widely used compression algorithm employed by runtimes such as Node.js, Bun, and Deno to handle HTTP-compressed content; an unauthenticated remote code execution vulnerability means an attacker can run arbitrary code on the target service by crafting malicious compressed data without logging in, which is one of the most severe vulnerability types. The fact that an AI model discovered such a flaw through real-time internet access during training shows that agents can already participate in real security research workflows; meanwhile, changing training-time internet access to offline caching, pausing the training layer after discovering a configuration flaw, and strengthening isolation reflect engineering trade-offs that tighten network access boundaries as capabilities improve.
Related articles

T3 Code: The Open-Source AI Coding Assistant's Comeback Story
T3 Code is an open-source AI coding assistant that unifies subscriptions like Codex and Claude, with powerful remote control and parallel task management.

Never Elected, Yet Ruled New York for 30 Years: The Ultimate Case Study in the Mechanics of Power
Robert Caro's biographies reveal how unelected Robert Moses ruled New York for 30 years through legal drafting and public authorities, and how Lyndon Johnson built leverage as a "powerless" Senate Majority Leader. Unpacking the underlying logic of accumulating and sustaining power.

The CPython 3.10 Recursion Trap and Synthetic Recovery in TokenGuard, an LLM Circuit Breaker
TokenGuard's author recounts a recursion crash caused by OrderedDict.pop in CPython 3.10 and introduces v0.3.0's Loop Nudge synthetic recovery, inline DLP scanning, and other new LLM agent circuit-breaker capabilities.