Reddit Announces Shutdown of RSS Feeds, Dealing Another Blow to Local AI Workflows

Reddit will shut down RSS on November 13, forcing local AI information pipelines to seek alternatives.
Reddit announced it will discontinue its RSS feed service on November 13, directly impacting developers who rely on RSS scraping to build local AI information pipelines. A user in the r/LocalLLaMA community described that his automated workflow—aggregating topic-specific posts via RSS and handing them to a local model for summarization—will lose its most stable entry point; Reddit's earlier forced-login policy had already blocked agents from retrieving posts. The article outlines Reddit's tightening trajectory from anonymous access to lightweight subscription channels, noting that affected use cases are precisely non-commercial, low-frequency personal ones. Alternatives include the official API, third-party aggregation services, or migration to communities that still support RSS, but all involve trade-offs in compliance, privacy, or reliability. The event once again exposes local AI workflows' fragile dependence on a single data source.
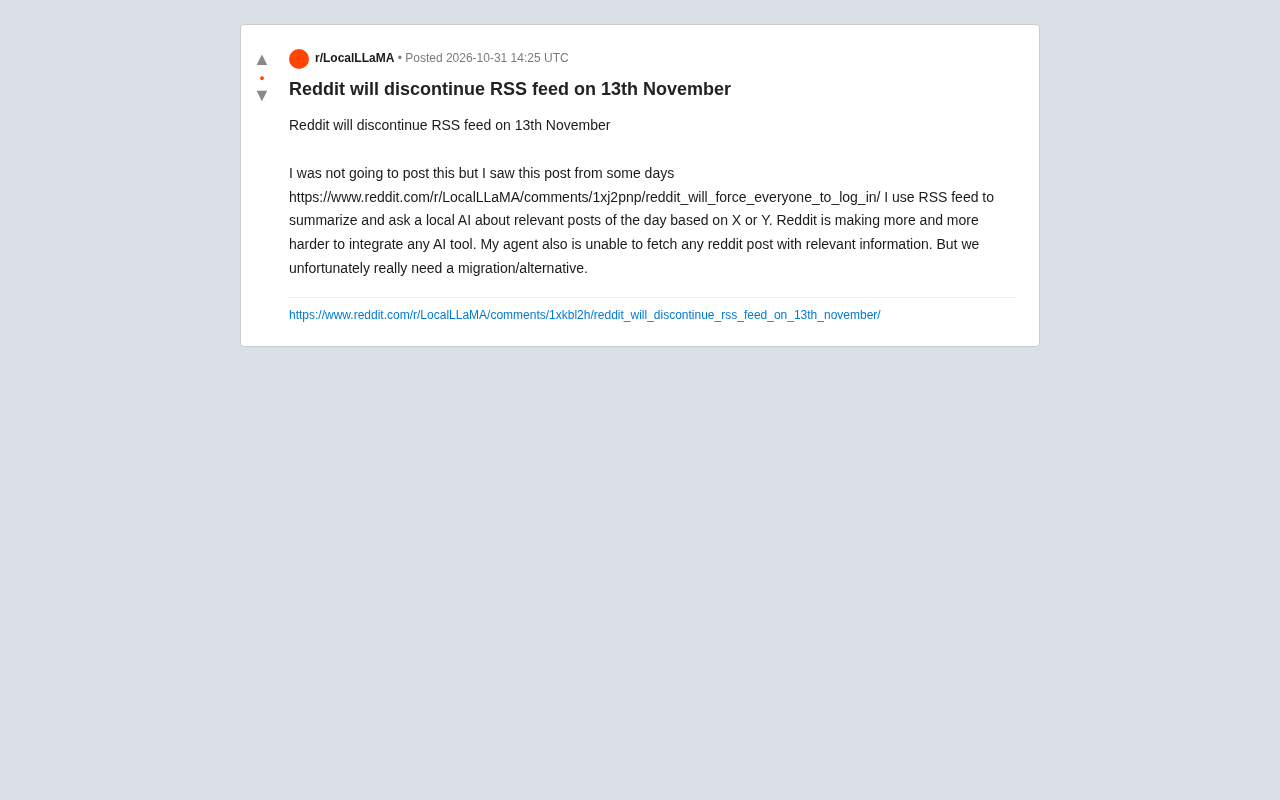
Reddit is tightening the gate on third-party access step by step. The latest move: RSS feeds will be discontinued on November 13. For ordinary users, this may seem like an insignificant change; but for developers who rely on RSS to build local AI information pipelines, it means a well-functioning automated workflow is being forced to hit pause.
The daily routine of an RSS user is being cut off
In the r/LocalLLaMA community, a user posted that he originally didn't intend to make a fuss, but after seeing another discussion a few days ago about "Reddit will force everyone to log in," he decided to bring this issue to the table.
His use case is very specific: scraping Reddit posts on specific topics via RSS, aggregating them, and feeding them to a local AI model so that the model can summarize content related to a certain keyword or community for the day and answer related questions. This pipeline runs entirely locally, does not depend on Reddit's official API, and has no commercial purpose—it's more like an automated extension of personal knowledge management.
The news means this information pipeline will be cut off directly. After RSS service stops, this local AI assistant will lose its most stable data entry point.
RSS (Really Simple Syndication) is an open content syndication protocol based on XML, born in the late 1990s. Websites publish their latest content in a unified format as RSS feeds; users only need a reader or script to periodically pull the feed to automatically obtain updates, without visiting pages one by one, logging in, or calling platform-specific interfaces. Because RSS feeds are public, stateless, and read-only, they have long been regarded as a "lightweight data pipeline" and are widely used for news aggregation, podcast distribution, and automated workflows. For local AI information pipelines, the value of RSS lies in being stable, structured, and independent of authorization, so it is often treated as the easiest input layer. But RSS is only a transport format; whether a platform continues to publish feeds is entirely up to the platform itself, which also sows the hidden risk of abrupt shutdowns.
Reddit's "siege" against AI tools is getting higher
The user made a very blunt judgment: "Reddit is making it increasingly difficult to integrate any AI tool."
This is not an isolated case. The previously discussed "forced login" policy has already disabled many automation scripts and anonymous scraping methods. His agent can now no longer obtain any Reddit posts containing relevant information. From forced login to shutting down RSS, Reddit's control over external access shows a clear tightening trajectory: first cut off anonymous access, then close the lightweight subscription channel, leaving only the official API that requires authorization and is bound by terms.
For local AI enthusiasts, the damage of this change lies precisely in that it targets the most "harmless" kind of usage—not scraping the whole site, not making high-frequency requests, not commercial use, just reading public content into one's own model for summarization. But the platform's security and business considerations obviously will not open a small window for this kind of personal use.
The difference between the official API and RSS is key to understanding the impact of this change. The Reddit official API requires registering an app, obtaining OAuth credentials, and complying with explicit rate limits (counted by minute and daily quotas) and terms of use; some large-scale commercial access also requires payment. In contrast, RSS requires neither authentication nor similar quota constraints, and has extremely low integration cost. Therefore, shutting down RSS is technically not "turning off a feature," but rather consolidating public reading that originally had zero threshold into identity-authenticated, auditable, and billable interfaces. For developers, this means they must add authentication flows, handle token refresh and rate-limit retries, and also assess whether the terms allow sending data to third parties or local models.
Migration and alternatives: no perfect option, but action is necessary
The post ended with a hint of helplessness: "We really need a migration plan or an alternative."
This is probably the shared sentiment of all local AI users who rely on RSS. The reality is that Reddit's alternative data entry points are narrowing, and a fully equivalent replacement does not exist. There are roughly several feasible paths: switch to the Reddit official API (requires registering an app and complying with rate limits and terms), obtain content indirectly through third-party aggregation services, or simply migrate information sources to communities and forums that still support RSS.
Each path has its cost. The official API brings improved compliance and stability, but integration complexity and restrictions also rise accordingly; third-party services add an intermediate layer, and reliability and privacy boundaries need to be reassessed. For users who regard "local" as a core value, any solution that introduces external dependencies is a compromise.
When evaluating alternatives, several dimensions are worth including in the decision: first, stability—the official API is the most stable but has the highest threshold, third-party aggregation services are in the middle, and self-built scraping is the most fragile; second, privacy boundaries—whether content passes through third-party servers and whether it is logged directly affects the value proposition of "local processing"; third, switching cost—differences in interface protocols (RSS's XML vs. API's JSON) require an adaptation layer, and it is best to abstract a unified data source interface so that upstream replacement does not affect downstream summarization logic. In addition, you can consider using open-source scraping frameworks with caching and deduplication strategies to reduce dependence on a single source, but you need to pay attention to platform terms and access frequency to avoid crossing anti-scraping boundaries. No solution can simultaneously satisfy stability, cost-free use, privacy, and compliance; the trade-off depends on which one your personal workflow is most sensitive to.
The fragility of local AI information pipelines is once again highlighted
The real point worth considering in this news is not RSS itself. As an old open protocol, RSS has long ceased to be mainstream, but it represents an internet contract that "content can be freely read." When platforms gradually withdraw this contract, local AI workflows built on public data expose structural fragility: no matter how strong your model is or how elegant your pipeline is, once the data entry point is closed, the entire pipeline goes to zero.
For developers in the local AI community, this may be an opportunity to re-examine data source strategies—do not tie information pipelines to a single platform, prioritize sources that still respect open protocols, and reserve switching costs in the architecture for "a source suddenly disappearing." Reddit's RSS shutdown is just a specific event, but the trend it points to deserves serious attention from anyone building a personal AI information pipeline.
One-line Summary
Reddit will shut down RSS on November 13, forcing local AI information pipelines to seek alternatives.
Paragraph Summary
Reddit announced that it will discontinue its RSS feed service on November 13, directly impacting developers who rely on RSS scraping to build local AI information pipelines. A user in the r/LocalLLaMA community described that his automated workflow—which aggregates posts on specific topics via RSS and hands them to a local model for summarization—will lose its most stable entry point. Reddit's earlier forced-login policy had already prevented agents from retrieving posts. The article outlines Reddit's trajectory of continuously tightening access, from anonymous access to lightweight subscription channels, and points out that what is affected is precisely non-commercial, low-frequency personal use. Alternatives include the official API, third-party aggregation services, or migration to communities that still support RSS, but all require trade-offs in compliance, privacy, or reliability. The event also once again exposes local AI workflows' fragile dependence on a single data source.
Related articles
 Tech Frontiers
Stylome Bot Slammed as Useless Junk: Why Do AI Detection Tools Keep Failing?
Reddit users test the Stylome AI detection bot: Gemini-rewritten text judged human-written, consistently low confidence. An analysis of AI text detection's technical dilemmas, privacy concerns, and credibility crisis in community governance.
 Tech Frontiers
When AI Becomes a Productivity Divide: Clarity or "AI Psychosis"?
A civil engineer's deep use of agentic AI boosted efficiency but bred contempt for peers who refuse to learn. Is this clarity or AI psychosis? An analysis of the cognitive and psychological challenges behind the AI productivity divide.
 Tech Frontiers
Opus 5.5 Benchmark Scores Climb, Community Says Its "Weights Are Blessed"
Reddit community discusses Opus 5.5's rising scores on the Benchmaxxing Bench, with users describing its performance as "weights are blessed." This article interprets the community reaction and cautions against conflating benchmark scores with real capability.