Reddit Ask: Can't Find a Real ML Project for Your Thesis? Here's What the Community Suggests

A Reddit student's request for real-world ML thesis topics reflects the gap between coursework and independent projects and offers topic-selection methods.
Starting from a Reddit post where a student seeks real-world machine learning project ideas, the article notes that many learners can run models but get stuck at topic selection. The author summarizes three common community directions: campus and local life scenarios, secondary problem design on public datasets, and lightweight tool-type projects, emphasizing that the key lies not in the idea itself but in three prerequisite judgments: data feasibility, narrowing problem boundaries, and evaluation criteria. Finally, it suggests that help-seekers clearly state their tech stack, data resources, and timeline constraints, because real projects often evolve from small annoyances into executable technical problems.
A Reddit Post That Struck a Chord: What Thesis Projects Lack Isn't Algorithms—It's Scenarios
In the machine learning section of Reddit, a student posted asking for help: "I'm looking for real-world machine learning project ideas for my final-year major project." The post title was brief, with no project description or tech stack constraints attached—just one keyword emphasized: "Real-World."
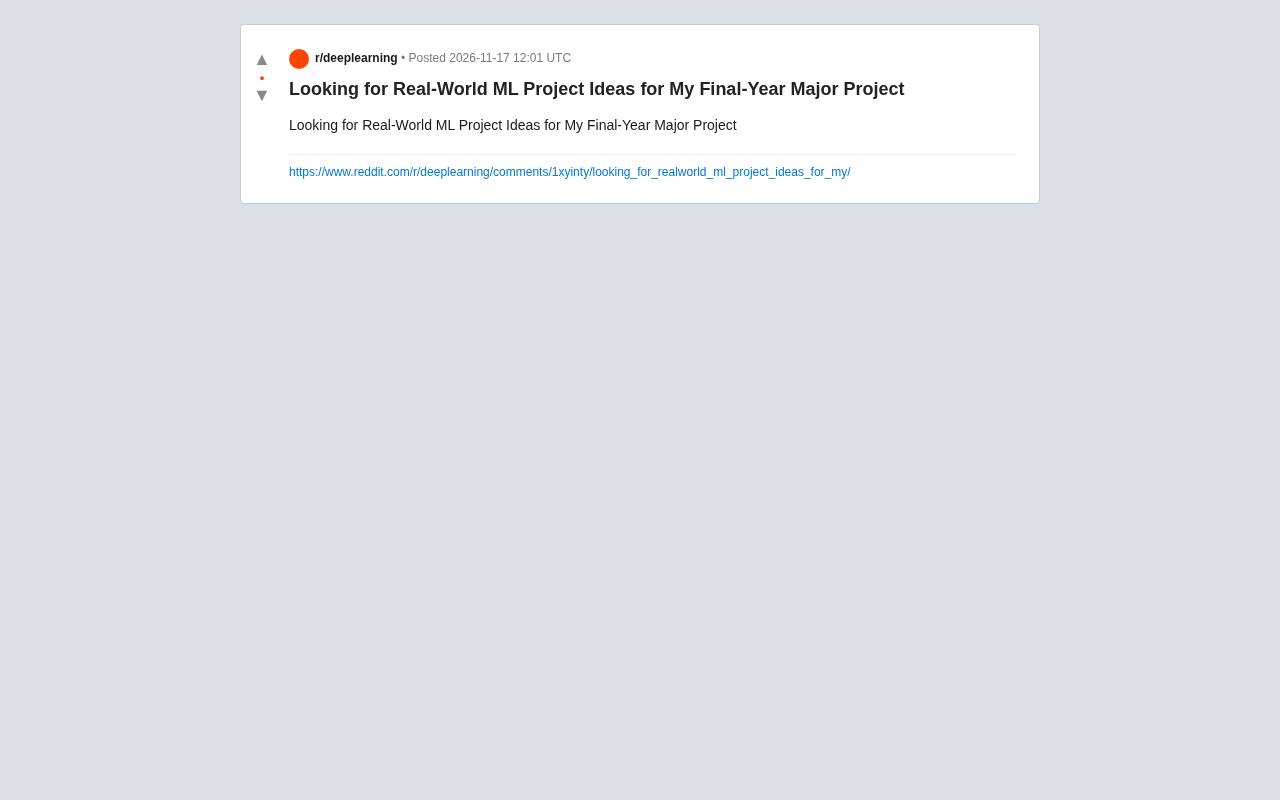
The post itself doesn't carry much information, but it hits a widespread pain point dead-on: many machine learning learners have mastered the basic workflow of model training and hyperparameter tuning, yet when it comes to independently completing a full project, they get stuck at the "topic selection" stage. Course assignments come with clear datasets and evaluation metrics, while real-world problems are fuzzy, messy, and have no ready-made labels.
Why "Real-World" Became a Barrier
In academic settings, projects usually have inputs and outputs pre-defined by instructors, sometimes even with cleaned data provided. Real-world ML projects, however, require you to define the problem boundary yourself, assess whether data is obtainable, evaluate labeling costs, and answer a more fundamental question: does this problem really need machine learning? It's precisely these non-engineering skills that create the gap between "can run a model" and "can build a project."
Common Topic Ideas in the Community: Start from Scenarios Around You
Although the original post didn't elaborate on specific replies, this type of request has been discussed repeatedly in the ML community, giving rise to some generally recognized topic directions. What these directions share: low barriers to data acquisition, clear problem boundaries, and verifiable baseline solutions.
Direction 1: Campus and Local Life Scenarios
Campus environments come with rich data sources and well-defined user groups. For example, using public course reviews to predict enrollment popularity, estimating queue times based on cafeteria foot traffic, or image recognition for library seat occupancy. The advantage of such topics is that you can directly reach both the data producers and end users, making demand validation extremely low-cost.
Direction 2: "Secondary Problems" on Public Datasets
You don't have to insist on collecting brand-new data. Platforms like Kaggle, UCI, and HuggingFace host plenty of public datasets, and you can propose a problem around the same data that differs from the original competition goal. For instance, if the original task is classification, you can pivot to uncertainty estimation or out-of-distribution detection; if the original task is prediction, you can try interpretability analysis. This approach shifts your topic-selection effort from data collection to problem design.
Uncertainty Estimation is about having the model output a confidence score alongside its prediction, helping determine whether that prediction is reliable. Common methods include Bayesian neural networks, MC Dropout, deep ensembles, and more. Out-of-Distribution Detection (OOD) focuses on whether the model can identify samples outside the training distribution, avoiding blind confidence. Both are especially important in safety-critical scenarios (healthcare, autonomous driving), and both can be used to construct research-worthy new problems based on existing classification datasets.
Direction 3: Lightweight Tool-Type Projects
Embed ML into a specific small tool rather than chasing SOTA metrics. For example, build a resume-job matching assistant based on text descriptions, or a retrieval-augmented question-answering prototype for domain-specific documents. The evaluation criteria for such projects are closer to practical usability, and it's easier to articulate the value clearly during your defense.
Retrieval-Augmented Generation (RAG) is a technical paradigm that combines external knowledge base retrieval with large language model generation: the system first retrieves relevant passages from a document library based on the user's question, then feeds these passages as context to the model for answer generation. Compared to fine-tuning, RAG can inject domain knowledge without retraining the model, making it suitable for resource-constrained scenarios like thesis projects. Evaluation can focus on retrieval hit rate and answer faithfulness.
Three Key Judgments Behind Topic Selection
From community discussions on such questions, we can distill that the real difficulty in choosing a "real-world" project lies not in the idea itself, but in three prerequisite judgments.
Data Feasibility Takes Priority Over Model Sophistication
No matter how interesting an idea is, if you can't get the data or labeling costs are too high, the project can't move forward. Before finalizing a topic, you should first answer: Where does the data come from? How large is it? Does it require manual labeling? How long does it take to label one sample? The community consensus is: confirm the data pipeline before deciding on the model approach.
Problem Boundaries Must Be Narrow Enough to Deliver
Thesis projects have a clear time window. A common failure mode is defining the problem too grandly—for example, "build a general-purpose medical diagnosis system." A reasonable approach is to narrow the scope to a verifiable sub-problem, ensuring you can complete the full loop from data processing to evaluation within the limited time.
Evaluation Criteria Must Be Thought Through in Advance
Real-world projects often lack ready-made accuracy leaderboards. You need to determine upfront which metrics measure success: classification accuracy, response latency, user completion rate, or relative improvement over a baseline method? Without clear evaluation criteria, it's easy to fall into the trap of "it's done but I don't know if it's good" in the later stages.
Baseline refers to the reference standard for evaluating a new approach, typically a simple rule, a traditional machine learning model, or an existing public method. Real-world projects lack leaderboards, and the role of a baseline is to provide an anchor for "minimum acceptable performance": if your model can't even beat the baseline, something is wrong with your approach; if it significantly outperforms the baseline, then the improvement is convincing. It's recommended to select an easy-to-reproduce baseline early in the project and run through the entire pipeline.
Advice for Students Currently Stuck
Back to that Reddit post—the most telling detail is that it didn't provide any constraints: no mention of one's technical background, available resources, timeline, or interests. This also explains why such requests often receive generic replies.
If you're at the same stage, a more effective way to ask is to clearly state your constraints: what tech stack you know, what kind of data you can access, how long your project period is, and whether you prefer research-oriented or engineering-oriented projects. With this information, the community can offer targeted directions rather than a generic list of topic ideas.
Real-world project ideas rarely appear as "perfect topics"—more often, they start from a specific small annoyance and get gradually defined by you into an executable technical problem.
Related articles

Snapchat Opens AI Assistant Lens Building: Supports Claude Code and Cursor
Snapchat lets Lens creators describe AR filters in natural language, with AI assistants like Claude Code and Cursor handling the full build process, greatly lowering the AR creation barrier.
Is the Planck Length the Smallest Distance? Why Physicists Are Skeptical
The Planck length is often called the smallest distance in the universe, but science videos point out this claim has never been experimentally confirmed. This article explains the origins of the Planck length, the obstacles of microscope thought experiments, and what it really tells us—the scale at which quantum gravity becomes unavoidable, not spacetime pixels.

AI Agents Drive Spend Management: Payhawk Raises $280M
Payhawk raises $280M at a $2B valuation. The 2018-founded enterprise finance platform uses AI agents to track and manage expenses and procurement. This article analyzes its product evolution, valuation signals, and impact on the spend management space.