Reddit Content Removal: The Data Archiving Dilemma in the AI Era
An official Reddit removal erased a post entirely, exposing systemic risks in the archivability and reproducibility of web corpora that AI relies on.
Using the official removal of a Reddit post for content policy violations as a starting point, the article notes that such removals not only hide the original text but sever the entire discussion chain of comments, context, and authorial intent, with templated reasons obscuring the actual cause. It analyzes the automation bias of platform moderation and chain reactions in the archiving ecosystem. For AI, Reddit data is widely used in model training and sentiment research, so removals cause missing samples, data contamination, and broken reproducibility. The article suggests local or decentralized archiving for individuals, more granular removal explanations from platforms, redundant data sources for researchers, and treating "data will disappear" as a default assumption.
When a Post Disappears: A Typical Reddit Content Removal Case
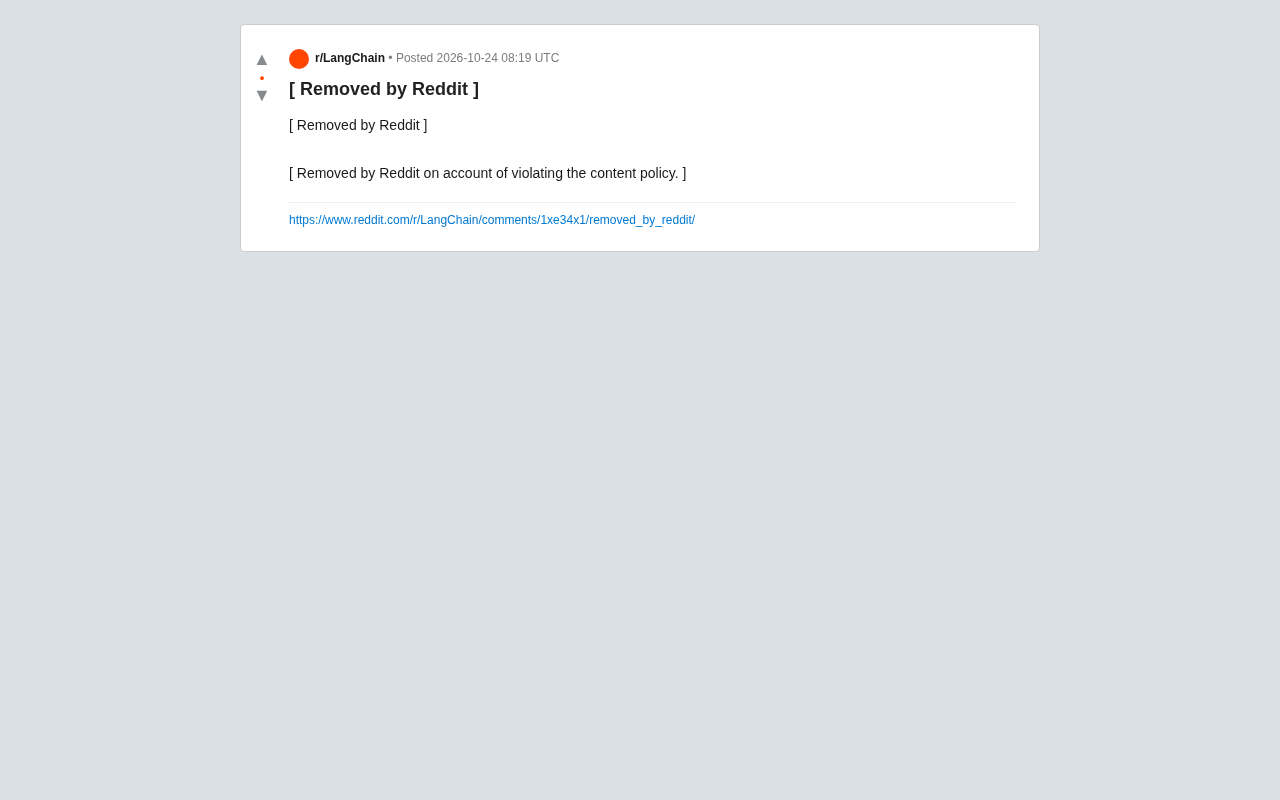
Seeing a "[ Removed by Reddit ]" notice on Reddit is no longer unfamiliar to many users. The material at hand is a typical case: both the original post's title and body were removed by the platform for violating its content policy, leaving only two cold lines of removal notice and the statement "[ Removed by Reddit on account of violating the content policy. ]"
For content creators and researchers, the problem posed by this kind of removal isn't merely "the original text can't be seen"—it's the rupture of the entire discussion chain: comments, context, and authorial intent all become void. More subtly, the removal rationale itself is templated, and readers cannot tell whether the cause was a copyright complaint, a privacy leak, or a misjudgment by automated moderation.
The Technical and Governance Logic Behind Removal Mechanisms
The Automation Bias of Platform Moderation
Reddit content removal generally falls into two categories: deletion by moderators within a subreddit, and global removal by Reddit admins. The latter carries higher authority and broader impact, often involving legal risk or platform-level policy. In recent years, platforms have increasingly relied on automated tools for initial screening, which creates a structural contradiction: the cost of erroneous removal is borne by users, while the channels for correction are not transparent.
Reddit's moderation system is layered: subreddit moderators have autonomy within their communities and can remove posts or comments according to self-defined rules, while Reddit admins enforce site-wide content policy, and their removals override moderator authority and typically appear under the fixed marker "[ Removed by Reddit ]." Admin removals are often triggered by legal subpoenas, DMCA copyright complaints, high-risk situations involving minor safety or doxxing, and may also come from bulk identification by automated systems. Unlike moderator removals, admin removals do not disclose the specific clause to ordinary users—even moderators see only limited explanations—constituting a typical "higher authority, lower transparency" structure in platform governance.
Chain Reactions Across the Archiving Ecosystem
Reddit has long been a key node of internet archiving, and numerous third-party services (such as Pushshift and various mirror sites) rely on its public API to scrape data. When an official removal occurs, whether these archives synchronize and whether they retain copies depends on each service's own policy. In this case, not even the title was retained, meaning the content was almost completely erased at the public level.
Pushshift was once the core infrastructure of Reddit's data archiving ecosystem, continuously scraping posts and comments through Reddit's public API and providing historical data queries to researchers, moderator tools, and various mirror sites. After Reddit adjusted its API policy in 2023, Pushshift's public access was drastically restricted to certain moderators only, directly changing the availability of the entire archiving chain. Since then, Academic Torrents, various mirror sites, and decentralized archiving projects (such as ArchiveTeam) have become alternative sources, but their coverage, update frequency, and retention policies vary widely. Thus, when an official removal occurs, whether a copy still exists depends on whether a service completed scraping before the removal and whether that service is willing to retain it after receiving a removal notice—this is essentially a decentralized and unguaranteed archiving network.
The Practical Impact on AI Training and Research
For the AI field, such events have direct real-world significance. Reddit discussion data has long been used for language model training, social sentiment analysis, and dialogue dataset construction. When a post is removed in its entirety, models or studies relying on that data source face missing samples, often with no way to trace the cause of the absence.
The deeper problem lies in reproducibility. If a researcher cites a Reddit discussion in a paper and that discussion is later deleted, subsequent verification becomes impossible. This is not an isolated case but a systemic risk shared by all open web data.
In the context of AI training, Reddit data is often used as a source of dialogue corpora, instruction fine-tuning data, and human preference data—typical examples include WebText (a significant component of GPT-2's training corpus) and numerous subsequent open-source dialogue datasets. These datasets typically store only text snapshots at construction time without preserving the accessibility status of the original URLs, so when a source post is deleted, samples in the dataset may still exist but can no longer be traced back to their original context. This creates two opposing risks: first, data contamination and privacy issues—deleted content may contain personal information that users later withdrew yet remains in the training set; second, broken research reproducibility—subsequent researchers cannot verify the source of samples. Both point to the same governance gap: dataset version records and source-tracking mechanisms have not yet become industry practice.
Approaches After Content Disappears
Archiving Habits at the Individual Level
For ordinary users, the most realistic strategy is to archive important content locally or in a decentralized manner—screenshots, exports, or tools that support version snapshots. This sounds clumsy, but it is far more reliable than depending on a platform's single point of storage.
Room for Improvement at the Platform and Researcher Levels
What platforms can do is provide more granular explanations of removal reasons and, within the limits of the law, retain "removal records" rather than completely erasing content. Researchers, meanwhile, need to establish redundant mechanisms for data sources to avoid a single platform becoming the sole entry point.
At the platform governance level, the industry already has some reference practices: for example, introducing "removal reason category codes" (such as copyright, privacy, policy violation, law enforcement request) to let users and researchers understand the nature of the removal without disclosing sensitive details; or providing a "removal audit log" interface that records when content was removed and under which category. The academic data management field emphasizes the "traceability" and "versioning" of data sources—for instance, attaching hash values or timestamps of source snapshots to datasets so that subsequent researchers can determine whether samples were complete at the time of collection. These mechanisms cannot prevent content from disappearing, but they can turn "disappearance" itself into a recordable, analyzable event rather than a silent black box.
Conclusion
The information in this Reddit content removal case is limited, but it is a clear signal: in an era when AI is heavily dependent on web corpora, the accessibility and archivability of content have become unavoidable infrastructure issues. Whether you are a content creator or an AI practitioner, it is worth designing your workflows with "data will disappear" as a default assumption.
One-line Summary
An official Reddit removal caused a post to vanish completely, exposing systemic risks in the archivability and reproducibility of the web corpora that AI depends on.
Paragraph Summary
Taking the official removal of a Reddit post for violating content policy as its entry point, the article points out that such removals not only make the original text invisible but also sever the entire discussion chain formed by comments, context, and authorial intent; moreover, removal reasons are templated, making it impossible to determine the specific cause. The article further analyzes the automation bias of platform moderation and the chain reactions across the archiving ecosystem, explaining that official removals carry higher authority and lower transparency, and that whether third-party archives relying on the public API can retain copies is uncertain. For the AI field, Reddit data has long been used for model training and sentiment research, and removals cause missing samples, data contamination, and broken reproducibility. The article concludes that individuals should archive locally or in a decentralized manner, platforms should provide more granular removal explanations, researchers need redundant data sources, and everyone should treat "data will disappear" as a default assumption.
Related articles
Getting Started with Gemini 4 Argonne: A Hands-On Guide from Building Sites to Agents
Complete Gemini 4 Argonne tutorial: build a calorie tracker app with one prompt in Google AI Studio, review 10-page technical documents with long context, develop a browser game as a coding Agent in Anti-Gravity, plus API Key setup, pricing, and subscription requirements.
Cursor vs. Claude Code vs. Copilot: A Scenario-Based Selection Guide
Cursor, Claude Code, or GitHub Copilot? A scenario-based guide covering daily coding, large refactors and long tasks, and teams locked into existing IDEs—plus common pitfalls and combined-use advice.
DB Chat: Conversing with PostgreSQL in Natural Language, with AI Auto-Generating SQL
dbchat lets users converse with a PostgreSQL database in natural language, with an AI agent auto-generating SQL and returning live results. This article analyzes its MCP Server + Next.js + AWS full-stack architecture and anti-hallucination guardrail design.