Replacing FFNs with Shared Product-Key Memory: Matching MoE at 23M Params
Shared product-key memory replaces FFN, ties MoE at 23M params but doesn't win; authors open-source negative result and benchmark.
A Reddit experiment replaced the Transformer FFN with a shared product-key memory module. At 23M parameters, it matched the perplexity of an equivalent MoE model but did not surpass the standard FFN Transformer. The authors call it a negative result, suggesting retrieval overhead, early-training key noise, and cross-layer access conflicts offset parameter savings. They also open-sourced a reasoning benchmark. The article analyzes why it didn't win and suggests future directions like hierarchical sharing, sparse retrieval, MoE combination, and larger-scale tests.
In the Transformer architecture, the feed-forward network (FFN) accounts for most of the parameters and computation. Recently, an experiment shared by the Reddit community attempted to replace the FFN with a shared product-key memory, tying with a Mixture of Experts (MoE) model at the 23 million parameter scale, but the authors characterized it as a "negative result." This experiment, along with an open-sourced reasoning benchmark, provides valuable reference for efficient model design.
Experimental Background: Exploring FFN Alternatives
The FFN layer in a Transformer typically accounts for more than two-thirds of the model's parameters. To reduce computational cost, researchers have proposed various alternatives, including MoE (Mixture of Experts) and memory-based modules. Product-key memory is a structure that stores and retrieves information via key-value pairs; its core idea is to use the inner product of learnable key vectors and query vectors to weight and aggregate value vectors.
The starting point of this experiment was: can a single shared product-key memory module completely replace the FFN, thereby reducing parameters or computation while maintaining performance? The authors conducted comparisons on a small-scale model with 23 million parameters, with baselines including a standard Transformer (using FFN) and an MoE model with an equivalent parameter count.
Product-Key Memory is a neural network module based on key-value retrieval, first proposed by Lample et al. in 2019. It organizes memory as the Cartesian product of two sets of key vectors: each memory slot is indexed by the product of a pair of keys (k₁, k₂); the query vector computes inner products with the two sets of keys to obtain weights, which are then used to aggregate the corresponding value vectors. Compared to traditional dense memory, the product-key structure expands memory capacity from O(N) to O(N²) while requiring only O(N) storage and computation, thus accommodating more memory slots at the same cost. In a Transformer, it is typically inserted after the attention layer as a replacement or supplement to the FFN, used to store factual knowledge or patterns. Its core hyperparameters include the key dimension, the number of keys in each group, and the value vector dimension; these choices directly affect the balance between retrieval accuracy and computational overhead.
Experimental Results: On Par with MoE, But Not Surpassing
According to information disclosed in the Reddit post, the Transformer using shared product-key memory achieved a perplexity comparable to MoE on language modeling tasks, with a total parameter count of 23 million. However, compared to the standard FFN Transformer, this approach did not show a clear advantage. The authors called this result a "negative result," meaning the hypothesis was not validated—the shared memory module did not bring the expected efficiency or performance gains.
This finding echoes some existing research: at smaller scales, the benefits of memory modules may be offset by their own overhead. Product-key memory requires computing the inner product of the query with all keys; when the number of keys is large, the computational complexity increases significantly. In addition, shared memory means all layers use the same set of key-value pairs, which may limit the model's ability to learn differentiated representations at different levels of abstraction.
Perplexity is the most commonly used intrinsic evaluation metric in language modeling, defined as the reciprocal of the geometric mean of the model's predicted probabilities for each token in the test set, i.e., PPL = exp(-(1/N)Σ log p(xᵢ)). Lower perplexity indicates more accurate predictions. It is equivalent to the model's average branching factor per token: a perplexity of 20 means the model is on average choosing among 20 candidate words. Under the same vocabulary and dataset, perplexity can directly compare the modeling capabilities of different architectures, but it is sensitive to tokenization and vocabulary size, so comparisons across settings should be made with caution. In this experiment, shared product-key memory achieved perplexity similar to MoE, indicating that both have comparable ability in likelihood fitting for language modeling, but perplexity does not directly reflect downstream task performance or inference efficiency, which is why the authors emphasize the need for comprehensive judgment combining other metrics.
Why Did Shared Product-Key Memory Not Win?
From an architectural design perspective, the FFN acts independently at each position, increasing model capacity through nonlinear transformations; whereas memory modules rely on retrieval mechanisms, whose effectiveness highly depends on the quality of keys and the distribution of queries. In the early stages of training, key vectors are randomly initialized, and retrieved information may be noisy, leading to unstable gradient signals. The sharing mechanism further exacerbates this problem because different layers' access patterns to memory may conflict with each other.
Another possible reason is the way parameter efficiency is measured. Although memory modules may reduce the parameter count of the FFN, the retrieval operation introduces additional computational graph and memory access overhead. On a small model with 23 million parameters, the relative proportion of these overheads is higher, which may mask the benefits of parameter reduction.
Mixture of Experts (MoE) is a conditional computation architecture consisting of multiple parallel "expert" sub-networks and a gating network. The gating network computes weights for each expert for each input token, typically activating only the top-k experts (e.g., top-2), thereby keeping the computation per token constant while the total parameter count is large. The advantage of MoE is that the parameter scale can grow linearly with the number of experts while computation remains approximately constant, but the cost is routing imbalance, training instability, and high memory usage. This experiment uses MoE as one of the baselines because it also aims to replace or enhance the capacity efficiency of the FFN: unlike the "retrieval-based" approach of shared product-key memory, MoE takes the "sparse activation" route. The two tie at 23M parameters, indicating that at this scale, the benefits of sparse activation and key-value retrieval are similar, but neither surpasses the cost-effectiveness of dense FFN.
Open-Source Reasoning Benchmark: Added Value
Besides the negative result itself, the authors also open-sourced a reasoning benchmark. This benchmark aims to evaluate model performance on logical reasoning tasks and may include multi-step reasoning, math problems, or commonsense reasoning. Although the post does not detail the specific content of the benchmark, open-source benchmarks are not to be ignored for community reproduction and comparison of different architectures.
The combination of a negative result and an open-source benchmark reflects the spirit of open research: even if the hypothesis does not hold, the experimental process and tools can still advance the field. Other researchers can test their own memory-augmented models based on this benchmark, avoiding repeated pitfalls.
Implications for Efficient Transformer Design
This experiment reminds us that architectural innovations on small-scale models need to be evaluated carefully. The FFN has become standard because it strikes a good balance between parameter efficiency and training stability. Any alternative needs to prove itself on multiple dimensions: fewer parameters, lower computation, no performance drop. Shared product-key memory has not yet demonstrated comprehensive advantages, but this does not mean memory mechanisms have no future.
Future directions may include: hierarchical sharing (different layers using different memory subsets), sparse retrieval (activating only some keys), and combining with MoE. For example, memory modules could handle high-frequency patterns, while FFNs handle long-tail knowledge. In addition, repeating the experiment at larger scales (e.g., over 100 million parameters) might reveal the scaling laws of memory modules.
Summary
The experiment shared on Reddit replaced the FFN with shared product-key memory, achieving performance comparable to MoE at 23 million parameters but not surpassing the standard Transformer. The authors honestly labeled it a negative result and open-sourced the reasoning benchmark. This work provides empirical data for exploring efficient model architectures and reminds the community that negative results at small scales are also valuable; they delineate the boundaries of current methods and guide subsequent research to avoid inefficient paths.
For developers interested in AI programming and model architecture, it is worth following this open-source benchmark and testing variants of memory modules in their own projects.
One-line Summary
Shared product-key memory replacing FFN ties with MoE at 23M params but does not win; authors disclose negative results and reasoning benchmark.
Paragraph Summary
An experiment shared by the Reddit community attempted to completely replace the feed-forward network (FFN) in a Transformer with a shared product-key memory module. At the 23 million parameter scale, it achieved perplexity similar to a Mixture of Experts (MoE) model with an equivalent parameter count, but did not surpass the standard FFN Transformer. The authors characterized this as a "negative result," suggesting that the retrieval overhead of shared memory, noise in key vectors during early training, and conflicts in cross-layer access patterns may have offset the benefits of parameter reduction. The experiment also open-sourced a reasoning benchmark for the community to reproduce and compare different architectures. The article analyzes the architectural and training reasons why shared product-key memory did not win, and points out future directions such as hierarchical sharing, sparse retrieval, combination with MoE, and larger-scale experiments. This work demonstrates the reference value of negative results and open-source tools for efficient model design.
Related articles
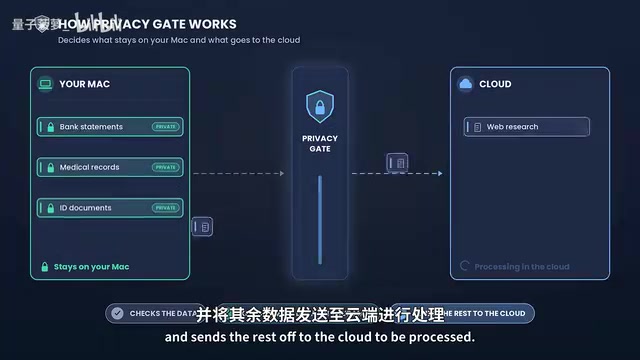
Perplexity Hybrid Compute Tested: Privacy Data Never Leaves the Mac
Perplexity Hybrid Compute tested: how PrivacyGate intercepts sensitive data, how local and cloud models divide work, model differences on 16GB vs 32GB Macs, and privacy protection in real scenarios like bank statements and medical records.
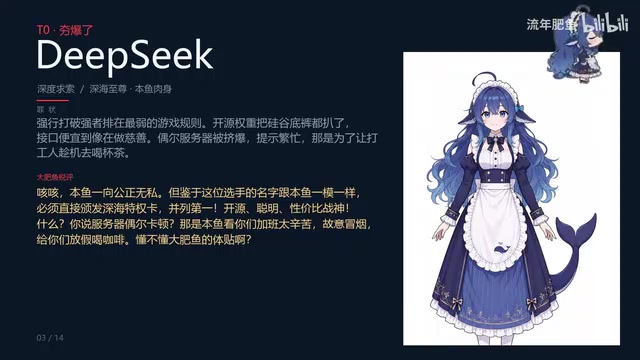
Big Fat Fish Roasts Mainstream LLMs at Home and Abroad: Doubao Takes the Crown, DeepSeek Tied for First
Bilibili creator Big Fat Fish roasts mainstream LLMs: Doubao tops for emotional value, DeepSeek ties first for open-source value, with ERNIE, Hailuo, Yuanbao, Kimi, Qwen, Kling, Claude, Gemini, and Grok each branded with a distinct persona.
How to Truly Test AI Agents Before Production? A Practical Testing and Monitoring Framework
BotGage founder Pramin Pradeep shares a three-step framework for testing AI Agents before production: Agent registration visibility, red teaming, and production observability — plus a real case cutting QA costs from $180K to $80K and an analysis of IT roles shifting to Agent supervisors.