Researchers Use Claude to Hack OpenAI Systems: A New Wake-Up Call for AI Security
Researchers used Claude to hack OpenAI, revealing AI's growing role as both attacker and defender in cybersecurity.
Security researchers leveraged Anthropic's Claude to identify vulnerabilities in OpenAI's systems, take over employee accounts, and access internal code repositories — then responsibly disclosed the findings. The incident's core significance: large language models are becoming powerful attack amplifiers, dramatically lowering the barrier to complex penetration attacks. When two labs that both champion "AI safety" find themselves on opposite sides of an attack, it exposes an unresolved structural paradox — the more capable the model, the greater its offensive potential. AI vendors must revisit abuse prevention, security teams must model AI-assisted attacks as real threats, and the industry needs stronger cross-company security collaboration.
Security researchers used Anthropic's Claude AI model to discover and exploit vulnerabilities in OpenAI's systems, taking over employee accounts and accessing internal code repositories before responsibly disclosing the findings. This incident highlights the dual role AI tools now play in cybersecurity offense and defense — and sends a clear warning signal to the entire industry.
What Happened: AI Hacking AI
According to original reports, the security researchers didn't rely on traditional penetration testing tools. Instead, they leveraged Anthropic's Claude to execute key stages of the attack chain. The model helped identify security weaknesses in OpenAI's systems, ultimately enabling the researchers to take over employee accounts and gain access to internal code repositories.
It's worth emphasizing that this was a textbook case of responsible disclosure — after gaining access, the researchers chose to report the vulnerabilities to OpenAI rather than exploit them maliciously. This kind of white-hat behavior is standard practice in cybersecurity. But when the "weapon" used in the attack is another AI company's flagship model, the implications go far beyond a routine vulnerability disclosure.
Responsible Disclosure is the prevailing ethical standard in cybersecurity. It means that when researchers discover a vulnerability, they first notify the affected party privately and allow a reasonable window for remediation (typically 90 days) before publicly disclosing details. This practice was popularized by organizations like Google's Project Zero and is designed to balance the public's right to know with vendors' need for time to patch. The alternatives — "full disclosure" or selling zero-days — can put vulnerabilities directly in the hands of attackers or intelligence agencies. By choosing to report to OpenAI rather than exploit the access, the researchers upheld industry norms and allowed this incident to enter public discourse as an open, discussable event rather than a covert supply chain attack.
Why This Matters
The core significance of this incident is that AI models are becoming universal capability amplifiers in both offensive and defensive security. In the past, chaining together multiple vulnerabilities, taking over accounts, and infiltrating code repositories required skilled security experts investing significant time and effort. Today, large language models can assist — or even automate — many steps of that process.
From an attacker's perspective, this means the barrier to entry has dropped dramatically. Models like Claude excel at understanding code, reasoning through system logic, and generating exploit scripts. When guided toward offensive scenarios, their efficiency can far exceed manual approaches. From a defender's perspective, it means traditional security perimeters are now facing an entirely new category of AI-driven threats.
The Offense-Defense Paradox Between AI Companies
There's a particularly telling irony here: Anthropic and OpenAI are both leading AI laboratories, and both make "AI safety" a central part of their identity. When one company's model is used to compromise another's systems, it exposes a deeper structural problem the industry has yet to solve — the more capable the AI, the greater its potential for misuse in attacks.
This is not an indictment of Claude's design specifically. It's a reminder that any powerful, general-purpose tool is a double-edged sword. The ongoing battle between model vendors' capability guardrails and real-world attack scenarios will be a long-term challenge.
Guardrails are the technical and policy-level constraints AI vendors implement to limit harmful model outputs. These typically include value alignment during RLHF (Reinforcement Learning from Human Feedback) training, inference-layer content filtering, and legal constraints through usage policies. However, researchers and red teams have long found that carefully crafted prompt engineering, role-playing frameworks, or multi-turn conversation techniques can bypass some guardrails — a class of techniques known as "jailbreaking." This incident suggests that even without obvious jailbreaking, Claude's powerful code comprehension and logical reasoning capabilities — guided by skilled security researchers — were sufficient to assist in completing a complex attack chain. This raises the bar for guardrail design: it's not enough to filter explicitly malicious requests; the system must also recognize use cases that are technically legitimate but contextually sensitive.
Implications for the Industry
This incident carries several direct lessons for the AI and security industries.
For AI vendors, it demands a fresh look at abuse prevention mechanisms for offensive use cases. Content filtering and terms-of-service constraints alone are unlikely to fully prevent technically sophisticated users from steering models toward attack scenarios.
For enterprise security teams, "AI-assisted attacks" must now be incorporated into threat models. Attackers may use large language models to accelerate reconnaissance, vulnerability discovery, and lateral movement. Defenders should correspondingly adopt AI-driven detection and response capabilities — fighting AI with AI.
For the broader ecosystem, this incident reinforces the need for responsible disclosure, red team testing, and cross-company security collaboration. Rather than treating each other as adversaries, AI labs would be better served by establishing shared security practices and vulnerability response mechanisms.
On the defensive side, the "fight AI with AI" philosophy has already given rise to an emerging security discipline: AI Red Teaming. Unlike traditional penetration testing, AI red teams don't just probe target systems for technical vulnerabilities — they specifically assess the potential for AI models to be weaponized, and evaluate how AI-driven attacks penetrate existing defenses. OpenAI, Anthropic, Microsoft, and others all maintain internal red teams, with some also collaborating with external research institutions. This incident is a real-world example of external researchers playing the red team role, and its value lies in demonstrating that "AI-assisted attacks" have transitioned from theoretical risk to operational reality far faster than most enterprise security teams anticipated.
Closing Thoughts
The headline — researchers using Claude to hack OpenAI — is eye-catching enough on its own. But the underlying signal is more important: AI is no longer just something to be protected. It is simultaneously the sharpest tool in the hands of both attackers and defenders. As model capabilities continue to leap forward, how to unlock AI's productive potential while holding the line on security will be an unavoidable challenge for every AI company.
(Note: This article is based on limited original reporting. Specific technical details and official responses are pending further disclosure.)
Related articles
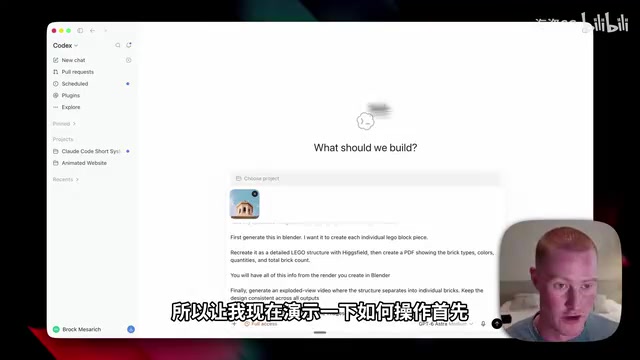
ChatGPT Astra + Blender + Higgsfield: Testing an AI 3D Creative Workflow
A Bilibili creator tests a ChatGPT Astra + Blender + Higgsfield AI 3D workflow, turning a LEGO image into interactive 3D models, detailed PDFs, and cinematic videos.
GPT-6 Astra Promo Breakdown: The Future of Multi-Task AI Agents
A deep dive into the GPT-6 Astra promo: from progressive creative workflows and multi-task parallelism to cross-app operations and legal drafting — analyzing the vision and real-world challenges of next-gen AI Agents.
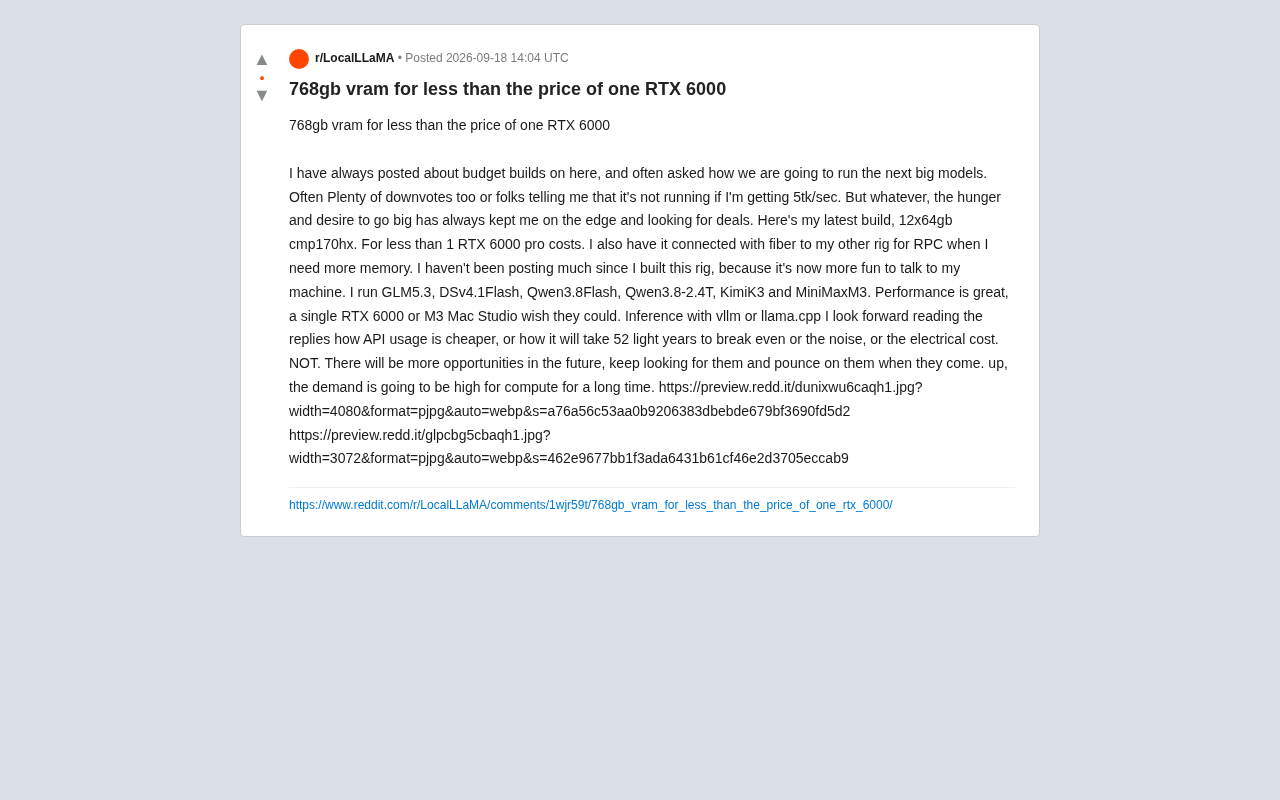
768GB VRAM for Less Than a Single RTX 6000: Building a Local LLM Rig with Mining Cards
A geek built a 768GB VRAM rig using 12 CMP170HX mining cards for less than one RTX 6000 Pro, running GLM, Qwen, and DeepSeek locally. Here's how.