Retrieval Is a Decision Problem, Not a Similarity Problem: Lessons from GPT Researcher Experiments

Decision-based retrieval raises effective context ratio from 46% to 73%, reframing RAG as a decision problem.
Drawing on a GPT Researcher experiment, this article reframes retrieval in RAG systems from "similarity matching" to a "decision problem." Traditional embedding retrieval relies on semantic distance ranking and cannot sense task goals or contextual dynamics, often recalling redundant or superficially relevant content. The experiment shows that decision-based retrieval (Jev) raises effective context to 73%, versus 46% for embedding retrieval. The article further argues this paradigm shift extends beyond retrieval to tool calling, context management, and step planning across the Agent execution framework — while cautioning that the findings come from a single experiment and should be treated as directional guidance rather than definitive conclusions.
Redefining Retrieval: From Similarity to Decision-Making
In building RAG (Retrieval-Augmented Generation) systems, the dominant approach has long been to treat retrieval as a similarity problem — using vector embeddings to compute semantic distance between a query and document chunks, then selecting the closest results as context. But a perspective circulating on Twitter is challenging this default assumption: retrieval is fundamentally a decision problem, not merely a similarity problem.
The distinction may seem subtle, but it touches on the core design philosophy of the entire retrieval pipeline. Similarity tells you "which content looks relevant," while a decision model answers "which content should actually go into the context window" — the latter requires judgment, trade-offs, and situational awareness, not just distance ranking.
Embedding-based retrieval works by mapping text into a high-dimensional vector space, computing distance between queries and documents via cosine similarity or dot products, and selecting the Top-K closest chunks. Built on vector databases like FAISS, Weaviate, and Pinecone, this approach is highly efficient at scale and remains the most common technical choice for RAG systems today. Its limitation: the embedding space captures statistical semantic similarity, not logical "usefulness for the current task." The same query may require completely different information at different reasoning stages, but embedding retrieval cannot sense this dynamic context shift — every query is an isolated, static match. Decision-based retrieval attempts to introduce goal-awareness at this step, meaning the retrieval component understands why it's retrieving, not just what looks similar to the query.
The GPT Researcher Comparison Experiment
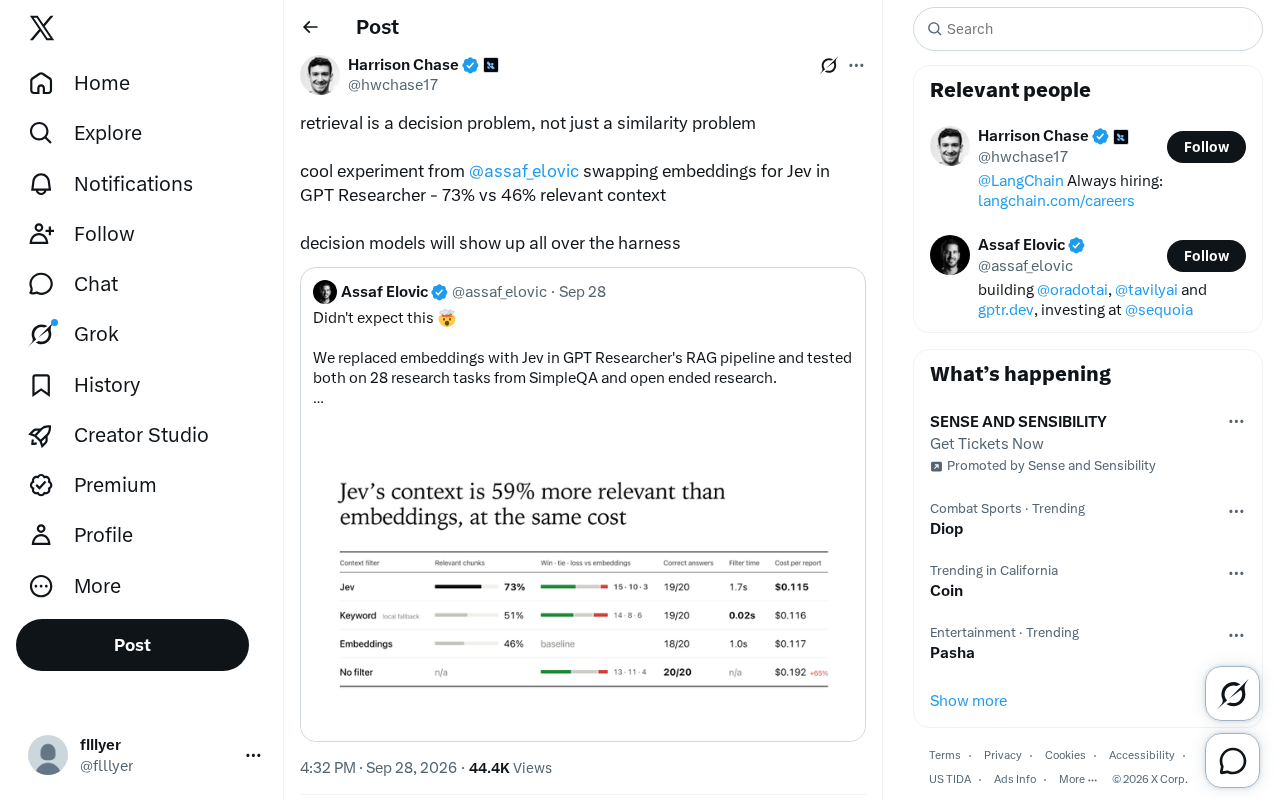
According to the tweet citing an experiment by @assaf_elovic on GPT Researcher, the team replaced traditional embedding retrieval with a decision-based retrieval approach called Jev. The results were striking:
- Decision model (Jev): 73% of retrieved context judged as relevant
- Traditional embedding retrieval: only 46% of context relevant
This means that under the same task conditions, the decision-based approach raised the proportion of effective context by nearly 27 percentage points. For a research-oriented Agent that depends heavily on context quality, this improvement directly impacts the accuracy and reliability of the final generated output.
Why Is the Gap So Large?
The core limitation of embedding retrieval is that it performs "stateless" semantic matching: it doesn't understand task goals, doesn't consider whether already-retrieved content is redundant, and can't make the judgment that "this one is more worth putting in the limited context window." When queries are ambiguous, semantically polysemous, or surrounded by many superficially similar but actually useless chunks, pure similarity ranking is easily misled.
A decision model can introduce richer evaluation dimensions — such as a chunk's information gain, its fit with the current reasoning step, or whether it adds new facts. It treats "what to retrieve" as an active trade-off rather than a mechanical nearest-neighbor lookup.
Information Gain is a core evaluation dimension in decision-based retrieval — it refers to how much new, non-redundant factual or reasoning value a piece of content adds relative to the context already collected. Traditional embedding retrieval lacks this capability and tends to recall multiple near-duplicate expressions of the same fact, creating "semantic redundancy" — the context looks rich but has low effective information density. This problem is especially pronounced in multi-hop reasoning scenarios: an Agent needs to sequentially retrieve multiple interrelated facts, and each hop should incrementally build on the conclusions of the previous one rather than re-searching the same semantic region. A decision model can explicitly track the "known information set," avoiding redundant recalls and allocating the limited context budget to content that genuinely advances the reasoning.
Decision Models Will Permeate the Entire Agent Framework
One of the more forward-looking claims in the tweet is: decision models will appear at every stage of the harness (Agent execution framework).
This points to a trend that is taking shape. In a modern AI Agent's execution pipeline, there are far more points requiring "choices" than just retrieval:
- Tool calling: which tool to use, and when to call it
- Context management: which historical information to retain, and what to discard
- Step planning: what to do next, and whether to backtrack
- Retrieval selection: the core scenario discussed in this article
If all of these stages are upgraded from "rule-based or similarity-driven heuristics" to "explicit decision modeling," the Agent's overall performance could see systematic improvement. Retrieval is simply the first domain where this paradigm shift is becoming visible.
Agent Harness broadly refers to the orchestration layer that drives an AI Agent to complete complex tasks, coordinating interactions between the LLM, tool calls, memory modules, and external retrieval. Typical implementations include LangGraph, AutoGen, and CrewAI, which decompose tasks into a series of composable step nodes. Most current frameworks still rely on rule templates or simple model output parsing for routing decisions between nodes — they lack explicit modeling of "which action has the highest expected value given the current reasoning state." Introducing decision models into each node of the harness is essentially injecting reinforcement learning or Bayesian decision-making thinking into the Agent's control flow — treating each step not as an isolated classification task, but as part of a sequential decision process aimed at a final goal. This aligns with the emerging architectural direction of "LLM as a Planner + specialized decision head."
Implications for RAG System Design
For developers building RAG systems or research-oriented Agents, this experiment offers several practical takeaways:
First, don't treat embedding retrieval as the finish line. Vector recall can serve as an initial candidate filter, but adding a decision-based reranking or filtering layer after recall typically improves the purity of context fed into the model significantly.
Second, focus on context "relevance ratio" rather than "recall count." The 73% vs. 46% comparison shows that the key metric for retrieval quality should be the proportion of effective context — not simply expanding the recall window, which can introduce noise and dilute the limited context budget.
Third, make "selection" explicit. Rather than relying on the model to implicitly ignore irrelevant content, filter content at the architecture level with a dedicated decision component, so that every piece of information entering the context has been actively evaluated.
A Direction Worth Watching
It's worth noting that the data above comes from a single-source experiment and has not yet been validated through large-scale, multi-scenario reproduction. The specific experimental setup — dataset, task type, and implementation details of Jev — was not fully disclosed in the original post. So the 73% vs. 46% finding is better treated as an inspiring directional signal rather than a conclusion to be directly replicated.
Regardless of the exact numbers, the value of framing "retrieval as a decision problem" lies in prompting us to reexamine the underlying assumptions of RAG. As AI Agents grow increasingly complex and context windows become an increasingly scarce resource, making smarter retrieval decisions could well be one of the key breakthroughs in the next phase of performance gains.
Related articles

Agent Skills Beginner's Guide: From Concepts to Multi-Agent Collaboration in Practice
A comprehensive guide to Agent Skills: core concepts, components, the importance of Description, standardization, beginner learning paths, and multi-agent collaboration.

One Neuron Detects Both Cats and Cars? We Reproduced It and Found a New Explanation
The cat-car neuron reinterpreted: researcher Cammarata argues it distinguishes pointy from round, not cats from cars. We reproduced the experiment and found the new explanation holds on most inputs—but cars are the exception. The interpretability debate continues on language models.

MCP Server + Python Assistant: A MicroStation Design Efficiency Revolution
Explore the early preview of the MCP Server and Python Assistant in MicroStation 2026: custom tools in five minutes, intelligent sheet index checks, and how AI is reshaping drawing workflows to unleash design creativity.