Running a 284B-Parameter LLM on 64GB RAM and CPU Alone? Open-Source Project LamaMotric Sparks Debate
Open-source LamaMotric compresses a 284B model to 56.56G, letting it run on CPU with 64GB RAM alone.
LamaMotric 2.4 claims it can run a 284B-parameter model with just 64GB RAM and a CPU, sparking wide discussion. The key is its custom compression: second-order compression alone saves 20.31G, shrinking the model to 56.56G so it resides fully in memory — peak memory stays under 59G even at 256K context, with no disk swap. On a 16-core Ryzen, prompt processing hits 44.36 tokens/s and generation 9–14.7 tokens/s, entering the usable range. The method also scales down, with a 30B MoE model running on a 16GB laptop. Its significance: shifting the local-LLM barrier from GPU to RAM — though accuracy impact and batch throughput remain unverified.
Running a 284B-Parameter LLM on 64GB RAM and CPU Alone? Open-Source Project LamaMotric Sparks Debate
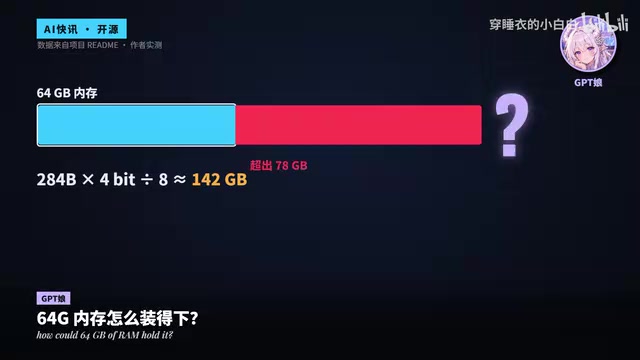
No GPU at all — just 64GB of RAM and a CPU, and you can run a 284B-parameter large model? The open-source project LamaMotric, at version 2.4 on GitHub, makes this seemingly counterintuitive claim, and it has sparked plenty of discussion on platforms like Bilibili. After all, even with standard 4-bit quantization, a 284B-parameter model weighs well over 100GB — so how could 64GB of RAM possibly hold it? And how did the project pull it off?
A Head-On Collision with Memory Capacity
By conventional wisdom, a model's parameter count directly determines its appetite for VRAM and RAM. 284B parameters means the model weights themselves are enormous; common quantization methods can shrink the footprint, but their compression ratios are limited, and squeezing a 100GB+ model into 64GB of RAM is very hard. LamaMotric's answer is a custom compression method of its own — one technique called "second-order compression" alone saves 20.31G, bringing the entire model down to 56.56G.
That number is the key to the whole scheme. 56.56G means the model can reside entirely in 64GB of RAM, and the author emphasizes that even with the context length maxed out at 256K, peak memory stays under 59G — the whole model lives in RAM, with no reliance on disk swapping whatsoever. This matters: if you lean on disk swap, inference speed gets completely dragged down by I/O, and "full in-memory residency" is the precondition for a pure-CPU setup to achieve usable speed.
Large-model quantization is the mainstream way to shrink model size. Its principle is to convert model weights from high-precision floating point (such as FP16, BF16) to low-precision integers (such as INT8, INT4), thereby multiplying reductions in storage and compute overhead. Common 4-bit quantization can compress each parameter's storage to roughly 0.5 bytes, but for 284B parameters, the theoretical size still exceeds 140G. Quantization is also generally divided into weight-only quantization and joint weight-activation quantization; the latter can speed things up further but is more complex to implement. In addition, Mixture-of-Experts (MoE) architectures use sparse activation so that each inference call only invokes part of the parameters, which is another important approach to reducing actual compute. Understanding this background is what makes it clear just how aggressive a compression strategy is needed to fit a 284B model into 64GB of RAM.
Pure-CPU Inference — Will It Really Stutter Like a Slideshow?
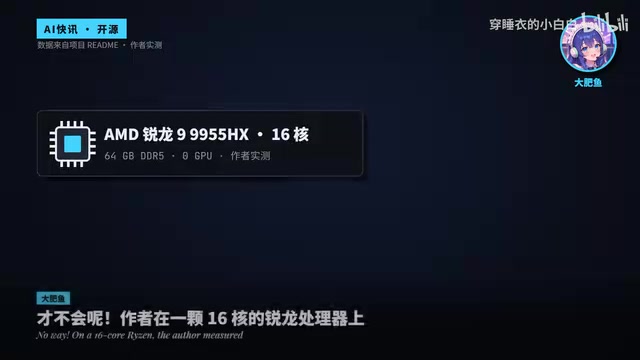
Without GPU acceleration, many people's first reaction is: won't this stutter like a slideshow? The author's measured data says otherwise. On a 16-core Ryzen processor, prompt processing reaches 44.36 tokens per second, while generation runs at 9 to 14.7 tokens per second.
It's worth clarifying that token generation speed and reading speed are not the same thing. A generation speed of 9 to 14.7 tokens per second is roughly a pace somewhat slower than normal reading — not exactly smooth, but already in the "usable" range rather than unbearable stutter. Prompt processing is much faster: 44.36 tokens per second means even fairly long inputs can be processed in an acceptable amount of time.
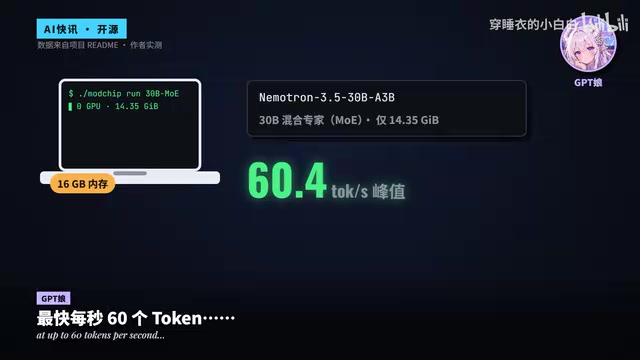
The approach also scales down to smaller models. According to the source material, a 30B Mixture-of-Experts model can run on a 16GB-RAM laptop, reaching up to 60 tokens per second. This shows the compression method isn't a one-off tuned for a single giant model, but a reusable approach that benefits low-memory devices as well.
In pure-CPU inference, prompt processing (prefill) and token generation (decode) are two qualitatively different stages. The prefill stage must process the entire input in parallel at once; it is compute-intensive and can make full use of multiple cores, so throughput is usually high. The decode stage, by contrast, generates tokens one at a time autoregressively, and each step must read all model weights — it's a memory-bandwidth bottleneck, and speed is often far below prefill. This explains why prompt processing can hit 44 tokens per second while generation only reaches 9 to 14.7 tokens per second. When judging the experience, decode speed is the key metric for whether it "feels laggy to read" — the industry generally considers around 10 tokens per second close to human reading speed, and reaching that level is enough to support everyday conversation and document processing.
Why This Matters
Getting a 284B-class model onto a home computer matters most not for benchmark scores, but for the barrier to entry. For a long time, the barrier for local large models has been the GPU — VRAM capacity and bandwidth determine how large a model you can run, and high-end GPU prices put many people off. If a pure-CPU-plus-RAM approach can truly run giant models, then the deciding factor shifts from "do you have a good GPU" to "do you have enough RAM" — and the latter is far cheaper.
Of course, there are also reasons to stay level-headed. A generation speed of 9 to 14.7 tokens per second suits scenarios like personal conversation and document processing, but it's still a clear distance from high-throughput batch inference. And while the compression method brings size advantages, whether it affects model accuracy is not backed by any evaluation data in the source material — something worth verifying before actual use. Also, the project name differs from how it's described in the source material, so if you're interested, it's best to check the original project and measured details directly on GitHub.
A New Way to Run Large Models on Home Computers
The value of LamaMotric 2.4 lies in offering a technical path different from "stacking more GPUs": trading more aggressive compression for a lower hardware barrier. A model size of 56.56G, peak memory under 59G, and pure-CPU generation speeds that are usable — put these numbers together, and "run large models locally without buying a GPU" really does turn from a joke into a possibility. For ordinary users with plenty of RAM and a modest GPU, this may be a direction worth watching.
How much RAM does your computer have right now? Dare you try running one locally?
Background Notes
Hardware swapping (swap) refers to the mechanism by which the operating system moves some data to disk when memory is insufficient. For pure-CPU large-model inference, once model weights can't all reside in memory, every generated token may trigger disk reads and writes — and the bandwidth and latency of SSDs differ from RAM by one to two orders of magnitude, so inference speed drops sharply to the point of being nearly unusable. "Full in-memory residency" means ensuring that model weights and the KV cache during inference all stay resident in RAM, avoiding any swap. This is also why LamaMotric emphasizes that peak memory stays below 59G even with 256K context — only by leaving headroom and eliminating page swapping can a pure-CPU approach maintain usable generation speed.
Related articles
Seven Years of Evolution: How Far Has the Foldable Come From the First Generation?
From the first foldable to today's latest models, what has seven years changed? Shallower creases, higher brightness, thinner bodies, and smoother software migration—has the foldable crossed the chasm from enthusiasts to ordinary users? This article discusses the question based on a video comparison.
When Did Humans Start Eating Salt? A 10,000-Year History of Salt
When did humans start eating salt? From salt use at the dawn of agriculture 11,000 years ago to ancient seawater evaporation and rock salt mining, and on to the salt trade, salt taxes, and Gandhi's Salt March, this article traces salt's key role in human civilization.
Microsoft Paza Research: How African Language Speech Recognition Breaks Through Architecture and Data Bottlenecks
Microsoft's Paza research evaluates 53 speech models across 39 African languages, revealing architecture choice matters more than pre-training coverage, 200-300 hours is the practical data threshold, and language typology deeply influences recognition performance.