Running Postgres on Object Storage: How Caching Turns the Performance Problem Around

Building Postgres on object storage and serving reads from cache shifts the cost from read latency to architectural complexity and the persistence window.
The article responds to the classic objection "don't put Postgres on object storage." The objection's rational core is that object storage's high latency and object-level write granularity don't match Postgres's assumptions about WAL sequential appends, random data page reads, and checkpoint flushes—not capacity or reliability. The article argues that "served from cache" means putting the cache first: object storage handles persistence and capacity scaling, while the cache serves low-latency reads on the serving path, confining high latency to cold paths. Cache hit rate then replaces disk IOPS as the core performance metric. The write path is the real challenge: WAL appends conflict semantically with object writes, requiring batching or a near-side intermediate layer, and checkpoint cadence must be redesigned. This architecture suits workloads with clear hot/cold tiering and tolerance for an asynchronous persistence window—not general-purpose use.
A Frequently Cited Objection
"Don't put Postgres on object storage." This is a widely circulated rule of thumb in database circles. The reasoning sounds solid enough: Postgres's storage engine was designed for local block devices, assuming low-latency, randomly overwritable disks. Object storage, by contrast, offers a high-latency, object-granular read/write interface—the two sets of assumptions barely line up.
But this rule of thumb is being reconsidered. A recent technical article discussing "Built on object storage, served from cache" directly addresses this classic objection: if you build the architecture on top of object storage while using a cache to serve read requests on the serving path, can Postgres's storage assumptions be satisfied again? The answer to this question is more interesting than a simple "yes" or "no."
The Rational Core of the Objection
To understand why a caching approach might work, we first need to acknowledge that the objection is not unfounded. Postgres relies heavily on several storage behaviors at runtime: sequential appends to the write-ahead log (WAL), random reads of data pages, and flushing dirty pages back to disk during checkpoints. WAL's append writes have a natural friction with object storage's "whole-object write" semantics, while random reads are directly constrained by object storage's higher first-access latency.
In other words, the problem isn't that object storage lacks capacity or reliability—it typically excels at both—but that its latency characteristics and write granularity don't match what the database engine expects. Any database solution based on object storage must answer the question of "how to absorb these mismatches."
The write-ahead log (WAL) is the core mechanism by which Postgres guarantees data durability and crash recovery. Before any data modification is written to data files, it must first be appended to the WAL. WAL's design assumes sequential, low-latency append writes—local disks or SSDs can support this pattern efficiently. Object storage, however, only supports "whole-object upload/overwrite" and cannot append bytes to the end of an object. Putting WAL directly on object storage therefore turns every log write into a full object operation, with unacceptable write amplification and latency. This is why object-storage-based solutions typically need to write WAL to a low-latency intermediate layer first, then batch-aggregate it into objects for persistence.
Checkpoints are the mechanism by which Postgres periodically flushes dirty pages from memory back to disk and advances the WAL reclamation point. Their purpose is to limit the length of WAL that must be replayed during crash recovery, thereby controlling recovery time. The more frequent the checkpoints, the faster the recovery, but the higher the flush overhead; the less frequent, the larger and more efficient the flush batches, but the longer the WAL chain that must be replayed after a crash. On object storage, frequent small-batch flushes are expensive, so checkpoint cadence must be redesigned, which directly affects the recovery time objective (RTO) setting.
Cache as the First-Order Architectural Choice
The phrase "served from cache" in the article's title points to the core idea: object storage handles persistence and capacity scaling, while the cache layer handles low-latency reads on the serving path. This isn't treating the cache as an optional acceleration add-on but placing it at the forefront of the architecture—most data read by the serving side should come from the cache rather than punching through to object storage every time.
The immediate benefit of this division of labor is that the latency characteristics seen by the database engine on the hot path are closer to local or in-memory semantics, with object storage's high latency confined to relatively insensitive paths such as cold data reads, cache misses, and background flushes. Persistence and performance are thus decoupled into two problems that can evolve independently.
Cache Hit Rate Becomes the Real Performance Metric
In traditional local-disk deployments, performance is often determined by disk IOPS and bandwidth; in this kind of architecture, cache hit rate rises to become the core metric. When the hit rate is high, read requests barely touch object storage and the system behaves like an in-memory database; when the hit rate drops, latency drifts toward the object storage baseline. This means capacity planning and cache capacity planning must be done together, rather than bolting on a cache layer after the fact.
Cache hit rate refers to the proportion of read requests satisfied directly at the cache layer without punching through to backend storage. In this architecture, the reason it replaces IOPS as the core metric is that the cost of a cache miss is no longer a single seek on a local disk but a high-latency round trip to object storage (typically on the order of tens to hundreds of milliseconds). When the hit rate drops from 99% to 95%, it looks like only a few percentage points, but the volume of penetrating requests multiplies several times over, and tail latency (p99) deteriorates significantly. Capacity planning must therefore consider both the ratio of total data to cache capacity and the hot/cold distribution of access—if the workload's access pattern is highly uniform, the cache struggles to distinguish hot from cold, the hit rate can't rise, and the benefits of this architecture are greatly diminished.
The Write Path Is the Real Challenge
Compared with the read path, the write challenge is harder to mask with caching. WAL requires sequential appends, but object storage writes are object-level—you can't append bytes at the end the way you would with a local file. Common approaches include batching WAL into aggregated objects or landing writes in a low-latency intermediate layer first and uploading asynchronously. The direction discussed in the article likewise points to this tiering: writes are first handled by a near-side component, and persistence completes asynchronously.
The trade-off this design introduces is clear: persistence is no longer synchronous, and the system must redraw the lines among throughput, latency, and durability. For businesses that can tolerate a certain persistence window, this is entirely feasible; for scenarios with extremely high durability requirements, the reliability design of the intermediate layer needs more careful evaluation.
Checkpoint and Flush Cadence Need to Be Redesigned
The checkpoint mechanism was originally intended to limit crash recovery time, but on object storage, frequent small-batch flushes are expensive. Background flushes therefore tend toward larger-granularity batch writes, which lengthens the window between persistence events and means crash recovery must rely on a longer WAL chain. This is a trade-off that must be made explicit at the design stage, not a detail that can be sidestepped through tuning.
Who This Architecture Is For
From the article's reasoning, the outline of the target scenario can be inferred: data scale that exceeds what a single machine's local disk can hold, read/write workloads with clear hot/cold tiering, and a business that can tolerate the brief window introduced by asynchronous persistence. In such scenarios, object storage's elastic capacity and cost advantages, combined with the low-latency serving path provided by caching, yield considerable overall benefits.
Conversely, for write-intensive workloads, zero-tolerance durability, or highly uniform access patterns (where the cache struggles to distinguish hot from cold), the complexity of this architecture may outweigh the benefits. Promoting it as a general-purpose solution would be a misreading of the article's original intent.
Conclusion: The Focus of the Debate Has Shifted
The real point of divergence in the debate over "can Postgres run on object storage" isn't feasibility but who bears the cost. The caching approach shifts the cost from "high latency on every read request" to "architectural complexity and the persistence window"—the former affects user experience, the latter affects engineering and operations. Only by understanding the specific terms of this trade can you judge whether it's worth signing for your business.
Related articles
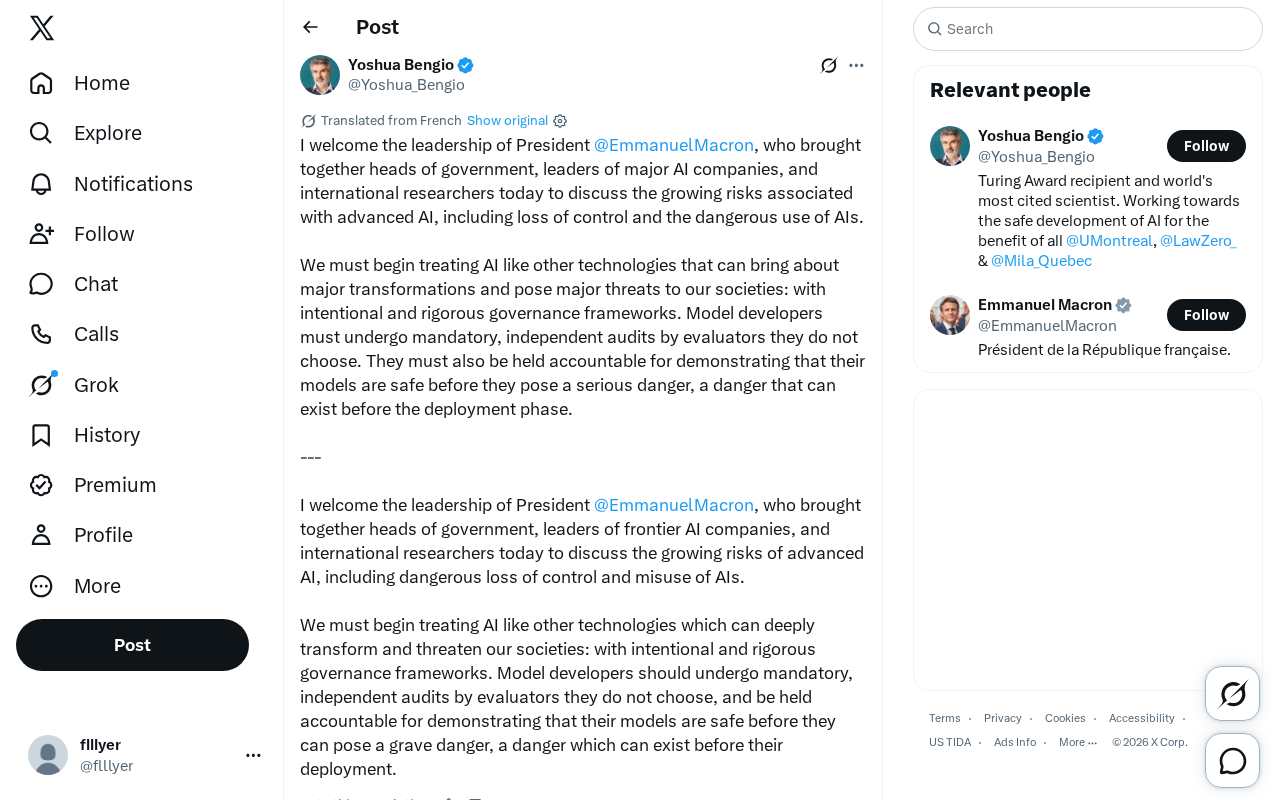
New AI Governance Initiative: Mandatory Independent Audits and Pre-Deployment Safety Proof
Macron convened government leaders, AI company executives, and researchers to discuss advanced AI risks. Statements call for a rigorous governance framework requiring mandatory independent audits and pre-deployment safety proof.

Roblox Funds Controversial Anorexia Treatment
Roblox funds flow to a controversial creator who promotes ketogenic diets over conventional treatment for anorexia and bulimia, raising medical and regulatory concerns.
GitHub Daily · November 19: Veteran Frontend Framework Returns to the Charts, Historical Map Project Gains Nearly a Thousand Stars in a Day
GitHub Trending Nov 19: jQuery and SolidJS both make the list, Appwrite adopts an agent-oriented positioning, and Jiangshan Shixu gains nearly 1,000 stars in a day.