Social Signal Bench: Evaluating Co-occurring Social Signals with Evidence-Weighted F1

Social Signal Bench proposes a co-occurring social signal benchmark and evidence-weighted F1, with a post-trained 7B open-source model performing impressively.
Existing affective computing benchmarks mostly evaluate a single social signal, and traditional multi-label F1 ignores semantic associations and annotation disagreement. Social Signal Bench includes video (25 hours, ten signals) and audio (22 hours, six signals) datasets, each with a public training set (10 hours of expert annotation + pseudo-labels) and a private expert test set, covering four conversation domains. The authors propose evidence-weighted F1 (EW-F1), which weights reference labels according to annotation evidence and gives graded credit to semantically related predictions; controlled experiments show it distinguishes semantically related from unrelated errors. Under a shared protocol, a 7B open-source model post-trained on this benchmark outperforms general frontier models on video tasks and matches them on audio tasks, demonstrating the effectiveness of specialized training for small models.
Existing affective computing benchmarks rarely evaluate social signals that co-occur in conversations, and traditional multi-label F1 also ignores semantic associations and annotation disagreements. Social Signal Bench was proposed precisely to fill this gap.
Why a New Social Signal Benchmark Is Needed
Social signals such as interest and hesitation often depend on contextual behavior for interpretation and may co-occur within a conversation. However, mainstream benchmarks typically evaluate only a single signal, and when measured with multi-label F1, they cannot distinguish semantically related errors from unrelated ones. Social Signal Bench includes two datasets: a video version of 25 hours covering ten social signals in audiovisual recordings, and an audio version of 22 hours covering six signals in audio-only recordings. Each dataset comes with a public training set (online conversation videos, of which 10 hours are expert-annotated and the rest are pseudo-labeled) and a private expert-annotated test set, covering four conversation domains.
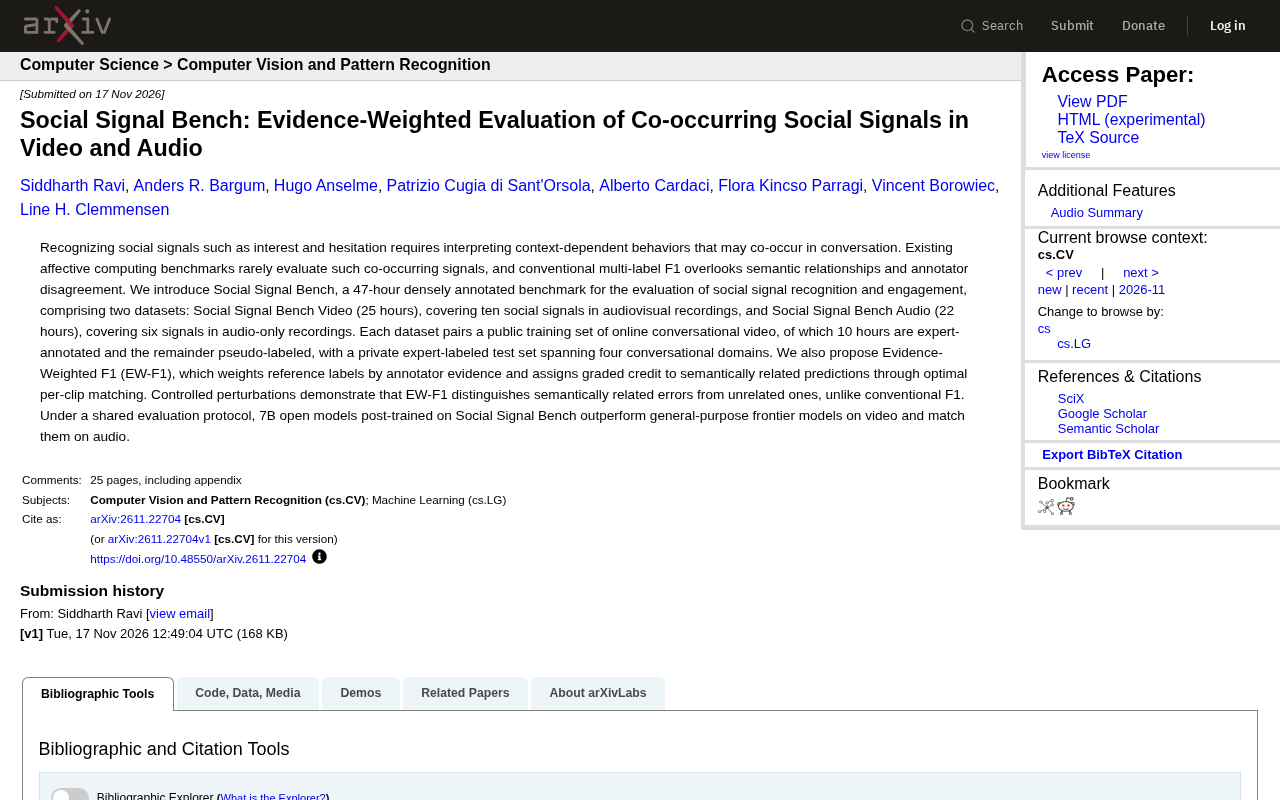
Social Signals refer to nonverbal or paralinguistic cues in conversation that convey attitudes, emotions, and intentions, such as interest, hesitation, agreement, and confusion. They usually do not appear in isolation but are expressed jointly through multimodal behaviors such as facial expressions, eye contact, nodding, vocal intonation, and pauses, and multiple signals may occur at the same moment (i.e., "co-occurrence"). Early work in affective computing mostly focused on a single modality (e.g., facial expression recognition) or single-signal detection, whereas social signals in real conversations have three major characteristics—multi-label, context-dependent, and annotation subjectivity—which make the traditional single-label classification paradigm difficult to apply directly.
EW-F1: Making Evaluation Closer to Semantics
To address the shortcomings of traditional F1, the authors propose evidence-weighted F1 (EW-F1). It weights reference labels according to annotator evidence and, through optimal matching for each segment, gives graded credit to semantically related predictions. Controlled perturbation experiments show that EW-F1 can distinguish semantically related errors from unrelated errors, whereas traditional F1 cannot. This means the evaluation results better reflect a model's true understanding of social signals.
Multi-label F1 is a common metric for evaluating multi-label classification. It computes precision and recall for each label separately and then averages them (macro-F1) or averages over samples (micro-F1). However, in multi-label settings, different labels may have semantic associations (e.g., "hesitation" and "confusion" often co-occur). A model misclassifying "hesitation" as "confusion" is not semantically equivalent to misclassifying it as "interest," but traditional F1 treats all errors indiscriminately as false positives/false negatives and cannot reflect this semantic hierarchy. In addition, when multiple annotators disagree on the same segment, traditional F1 usually takes majority voting or a single gold standard, discarding annotation uncertainty. EW-F1 is designed precisely to address these two shortcomings.
Evidence Weighting is a label aggregation strategy for handling annotation disagreement. Unlike majority voting, it assigns continuous weights to reference labels based on the evidence provided by each annotator (e.g., annotation confidence, annotation consistency, annotator reliability), thereby preserving information about "partially correct" labels. In EW-F1, reference labels are no longer 0/1 hard labels but weighted soft labels; predictions receive graded credit through optimal matching for each segment—semantically similar predictions earn partial scores, while semantically unrelated predictions earn none. This approach makes the evaluation metric more robust to annotation subjectivity and closer to human understanding of social signals.
7B Open-Source Model Performs Impressively
Under a shared evaluation protocol, a 7B open-source model post-trained on Social Signal Bench outperforms general frontier models on video tasks and matches frontier models on audio tasks. This result shows that specialized training for social signals can significantly improve the performance of small models.
Post-training refers to continuing supervised fine-tuning or instruction tuning on top of a pretrained foundation model using domain data, so that the model adapts to a specific task. In this paper, the 7B open-source model is post-trained on the Social Signal Bench training set to learn to recognize co-occurring social signals. Compared with general frontier models (such as GPT-4V), post-training gives small models a specialization advantage in a specific domain: surpassing general frontier models on video tasks and matching them on audio tasks. This suggests that for fine-grained, context-sensitive tasks such as social signals, high-quality domain data plus targeted post-training may be more effective than simply scaling up model size.
Multi-Source Perspectives
According to analyses from Bilibili creators and YouTube channels, the benchmark's dense annotation and evidence-weighting approach provide a new direction for affective computing evaluation. Although different sources disagree on the evaluation of the specific methods, the consensus is that evaluating co-occurring social signals requires more refined metrics.
Conclusion
Social Signal Bench not only provides high-quality data but also introduces a more reasonable evaluation metric, advancing social signal recognition toward a more practical stage.
One-line Summary
Social Signal Bench proposes a co-occurring social signal benchmark and evidence-weighted F1, with a post-trained 7B open-source model performing impressively.
Paragraph Summary
Existing affective computing benchmarks mostly evaluate a single social signal, and traditional multi-label F1 ignores semantic associations and annotation disagreement. Social Signal Bench includes two datasets—video (25 hours, ten signals) and audio (22 hours, six signals)—each with a public training set (10 hours of expert annotation + pseudo-labels) and a private expert test set, covering four conversation domains. The authors propose evidence-weighted F1 (EW-F1), which weights reference labels according to annotation evidence and gives graded credit to semantically related predictions; controlled experiments show it can distinguish semantically related from unrelated errors. Under a shared protocol, a 7B open-source model post-trained on this benchmark outperforms general frontier models on video tasks and matches them on audio tasks, demonstrating the effectiveness of specialized training for small models.
Related articles
FBI Warns: Hackers Weaponize AI Agent ARTEX to Attack 200+ Organizations
FBI warns that AI penetration framework ARTEX is being used to attack 200+ organizations, with CrowdStrike tracking the VaporPanda group. We break down ARTEX's agent orchestration architecture, the real attack chain, loss data, and the FBI's five defense recommendations.
FBI Warns: Free AI Hacking Tool Artex Spirals Out of Control, Breaches Cloud Systems in Three Hours
FBI warns that the free open-source AI penetration tool Artex is being abused by criminals and state-backed hackers to breach cloud systems in as little as three hours. This article analyzes real attack cases, overlooked side-door risks, and defense measures enterprises and individuals can take immediately.

Verse Engine: Turn Blender/Unity/Unreal Scenes into Browser 3D Links in One Click
Verse Engine by Ctruh is a browser-native 3D and XR engine that publishes Blender, Unity, and Unreal scenes as browser links in one click. View-based streaming opens a 1.03 billion-triangle city scene on a laptop. It offers embeds, API, and SDK for developers, 3D artists, architecture, and e-commerce teams.