Stop Lying to Yourself: Six Traps in Agent Benchmarking and the Honest Way Out

Six structural traps in agent benchmarking and the discipline for honest evaluations.
Most agent benchmarks aren't deliberately faked but structurally self-deceiving. This piece breaks down six traps — contamination, drift, judges reading claims, missing negative controls, easy cases inflating averages, and irreproducibility — and gives concrete discipline for each, stressing that honesty is about method, not budget.
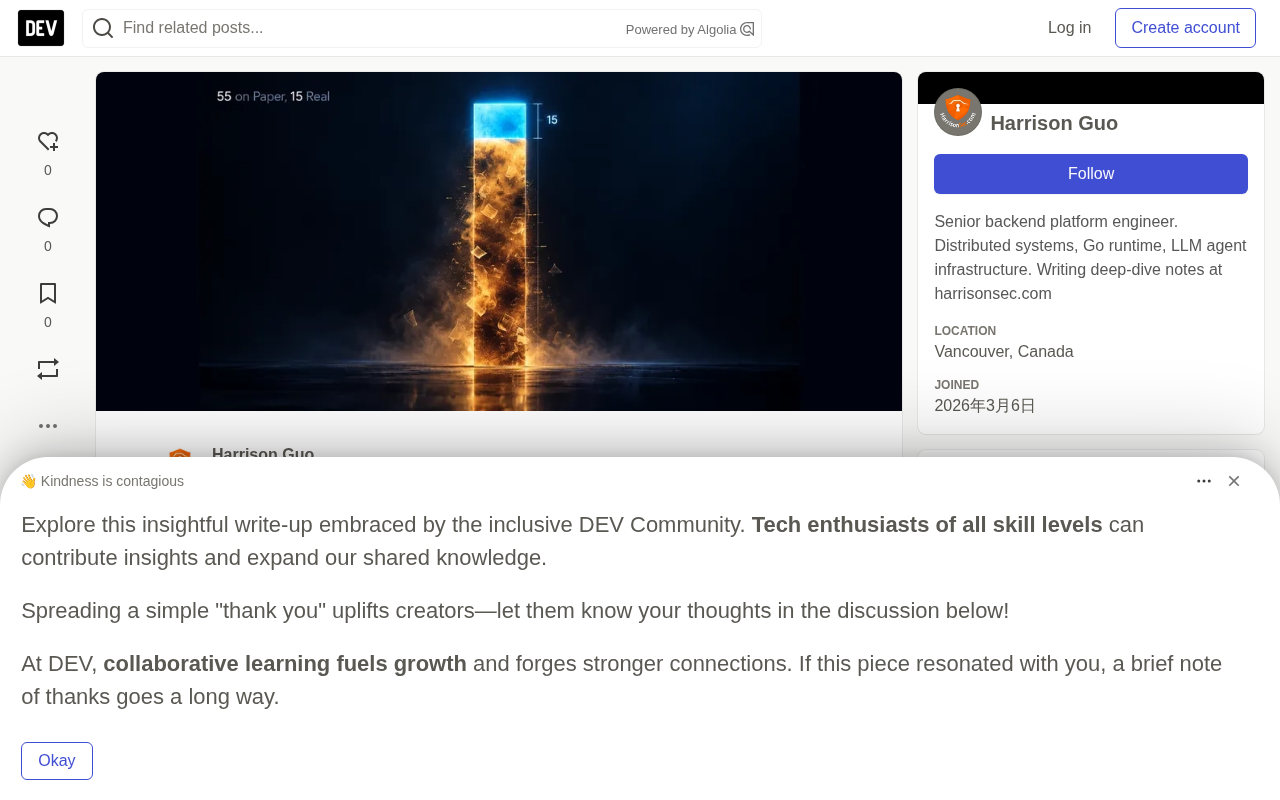
Most agent benchmarks don't lie on purpose — they lie structurally. Nobody sits down to fabricate numbers, but they run a contaminated benchmark and happily accept the flattering score. The problem is that this kind of "lie" is systematic and comfortable, because it happens to be exactly the answer you wanted.
This article, based on a technical analysis from the Harrison Security blog, breaks down six common traps in agent benchmarking and offers actionable discipline to help you get evaluations you can actually trust.
Six Traps: How to Spot Them and Defend Against Them
The table below systematically summarizes these traps and the countermeasures:
| Trap | How it sneaks in | Countermeasure discipline |
|---|---|---|
| The model has seen the test | Tasks scraped from the internet are already in the training data | Deterministic or held-out task sets, never public, never recorded |
| The test drifts | Fixtures or prompts change between runs, scores aren't comparable | Frozen, versioned task sets; lock everything down |
| The judge only reads claims | The grader reads the agent's self-report instead of the result | Judge reasons over verified facts, uses rules as a lie detector |
| Everything passes | No inputs that should fail are included | Negative controls and a noise floor |
| Easy cases carry the average | Clear tasks inflate the mean; hard tasks are where the failures hide | Split by difficulty: clear, adversarial, fuzzy |
| You can't rerun it | No random seed, no saved responses, no traces | Reproducibility: fixed seeds, saved raw output, captured traces |
Now let's go through them in order of destructive power, from greatest to least.
Contamination: The Test Set Is in the Training Data
This is the most severe and most invisible problem. If the tasks you're scoring on are ones the model may have read, the score is inflated by memorization — and you have no way to know by how much. A model that has seen the answers always looks smart.
The only defense is a task set the model cannot possibly have seen. Generate from rules with a fixed seed, so it's provably synthetic and reproducible. Or hold out a private set that has never touched the public internet and has never been pasted into a prompt where it might be logged. Once evaluation tasks go public, they have a shelf life — after that, you're measuring recall, not capability.
Test Drift: Scores That Aren't Comparable
If the task set, prompts, fixtures, or model version change between runs, the two scores aren't measuring the same thing, and a claim like "improved from 61 to 68" is meaningless. Lock everything down: version the task set, version the prompts, record the model ID rather than "latest." A benchmark you can't freeze is a benchmark you can't compare — and comparison is the entire point of benchmarking.
The Judge Reads Claims, Not Results
If the model or judge scores by reading the producer's description of what it did, then a run that did everything wrong can sail through with a perfect pass. The grader has to look at the actual artifacts, reason over independently verified facts, and have veto power when the key evidence is false. This opens up a separate topic — LLM-as-Judge is fundamentally a reasoning contract, not a simple score, and benchmarking inherits all of its failure modes.
The reasoning contract of LLM-as-Judge means this: when you use a large language model as a grader, you shouldn't treat it as a black box that outputs a score — you should require it to output a complete chain of reasoning: first state which facts it observed, on what rules it based its judgment, and finally what conclusion it reached. This differs fundamentally from calling a deterministic scoring function in a traditional benchmark: a deterministic function's behavior is guaranteed by code, whereas an LLM judge's behavior is jointly determined by the prompt, the context, and the model version — any one of which changing can give the same answer a different score. So treating LLM-as-Judge as a contract means you must explicitly stipulate: what counts as an acceptable source of facts, which evidence counts as fabricated, and that it must veto when invalid. Without that contract written clearly, the judge's failure modes — sycophancy, flattery, being misled by self-reports — pass directly into the benchmark score.
Everything Passes Because No Failure Was Designed In
This is a discipline almost nobody has, yet it catches the most flawed metrics: negative controls.
Deliberately include inputs in the test that the system should fail or score poorly on. If the metric passes them, the metric is broken — not the system is good. The statistical version is a noise floor: run a trivial or random baseline on the same test and see what it scores. If a do-nothing baseline gets 40, then your agent's 55 is only 15 points of signal, not 55.
**The noise floor** is a statistical tool for measuring how many "free points" a benchmark itself hands out. Concretely: run a completely random, trivial, or no-op policy on the same task set and see how many points it gets. That score is the lower bound any system can reach without genuine capability. For example, in a binary classification task where the positive-to-negative ratio is 6:4, a brainless baseline that always outputs "positive" already gets 60. If an agent then scores 65, the real signal is only 5 — not 65. The noise floor also reflects the random fluctuation of the test framework itself: if you resample many times and the baseline score bounces between 58 and 62, then any "improvement" smaller than that band can't be trusted. A benchmark without a noise floor is a free-fall measurement without subtracting gravity.
# The key question is never "what score did my agent get"
# It's "how much better did my agent do than a baseline that can't possibly do the task"
signal = agent_score - baseline_score  # baseline = random/trivial/no-op
# If the signal is small, your benchmark is measuring what every system gets for free
A benchmark without negative controls can't tell you whether that number is capability or gravity.
Easy Cases Carry the Average
A single average hides its own composition. Clear tasks are easy and numerous, pulling the mean up while the hard cases that actually matter quietly fail underneath. Split the set by reason for difficulty: clear, adversarial, fuzzy. Report each separately. The clear number tells you what you already know; the adversarial and fuzzy numbers are the real review. A model can put up a beautiful average and still be useless where it counts — and you'll never see it in the mean.
Clear, adversarial, and fuzzy — these three difficulty categories correspond to different sources of challenge for the model. Clear tasks have well-defined goals, standardized inputs, and a single correct answer, and models can usually solve them by pattern matching; adversarial tasks deliberately include misleading information, leading premises, or distractors that conflict with the goal, testing whether the model can resist surface cues; fuzzy tasks have goals that aren't unique and require clarification or external context, testing whether the model can still make reasonable decisions when information is incomplete. The reason a single average masks problems is that clear tasks tend to be the majority and easy to pass, which "averages away" the failures on adversarial and fuzzy tasks. Only by reporting the three scores separately can you tell whether the model is genuinely reasoning or just reciting and guessing.
Can't Rerun: The Irreproducibility Trap
Without fixed seeds, without saved raw output, without captured traces, you're not running a benchmark — you're having an experience. Reproducibility isn't a nice-to-have. Save the seed, save every raw response, capture the full trace of the agent's behavior rather than just the final answer, because in the trace you can see it skip verification, retry three times, or do something it shouldn't have. An irreproducible number can't be defended and can't be debugged.
What the Honest Version Looks Like
Put all the discipline together and the shape is simple.
This isn't idle theory. A recent calibration test cost about five cents for roughly 1,200 decisions: a deterministic task set the model couldn't possibly have seen, a resampled noise floor as a negative control, scores split by difficulty, every raw response saved so anyone can rerun it. The core point is this: honesty is about method, not budget. It costs discipline, not money.
A deterministic task set is a set of tasks generated from a fixed random seed and rules, rather than written by hand on the fly or scraped from the public internet. Its key property is being provably synthetic: anyone using the same seed and rules generates exactly the same tasks, so the model can't have seen them in its training data. The opposite is a "scraped task set," which is convenient but enters the training corpus once public, inflating scores through memorization. Another advantage of a deterministic task set is controllable difficulty: you can systematically adjust generation parameters to increase adversariality or fuzziness, rather than relying on manual annotation. The trade-off is that the tasks may drift from real-world scenarios, which is why in practice they're often paired with a private held-out set — the former guarantees reproducibility and low contamination, the latter guarantees ecological validity.
One-Sentence Summary
A benchmark score is a claim, and most agent benchmarks are claims you haven't earned the right to make. Before trusting a number, ask six questions: Could the model have seen it? Is the test frozen? Does the judge check the result or the claim? What was supposed to fail? Which cases actually carry the score? Can you rerun it? Where the answers are good, the number means something; where they're bad, you've measured the test harness and called it a model, then published a story told with a number.
One-line Summary
Six structural traps in agent benchmarking and the actionable discipline of honesty.
Paragraph Summary
Based on a technical analysis from the Harrison Security blog, this article argues that most agent benchmarks aren't deliberately faked — they're structurally self-deceiving: running a contaminated benchmark and accepting a flattering high score. It breaks down six traps in order of destructive power: data contamination (test sets entering training data), test drift (fixtures or prompts changing so scores aren't comparable), judges reading an agent's self-claims rather than verified results, missing negative controls so everything passes, easy cases inflating the average and masking hard failures, and irreproducibility that makes numbers indefensible. For each trap it gives discipline: use deterministic or private held-out task sets the model couldn't have seen, lock and version everything, have judges reason over verified facts, design inputs that should fail plus a noise floor, report split scores across clear/adversarial/fuzzy, and fix seeds while saving raw output and full traces. It closes by stressing that honesty is about method, not budget, and lists the six questions to answer before trusting any benchmark number.
Related articles

WorkBuddy Full Tutorial: Build an AI Office Automation Agent from Scratch
A complete WorkBuddy tutorial: installation, three working modes, multimodal picture book video practice, expert team agent building, and workflow configuration for low-cost AI office automation.

WorkBuddy Agent Complete Guide: From Beginner to Automation in 7 Days
Based on Bilibili's 256-episode WorkBuddy masterclass, this systematically breaks down Tencent's AI office workbench core capabilities: Agent principles, Skill encapsulation, cross-platform connectors, scheduled automation, knowledge bases, and zero-code development, with learning path recommendations.

8 AI Accounts, 7 Failed: An Honest Review of Using AI to Get Work Done
Only 1 of 8 AI-run Bilibili accounts succeeded. We break down the real difference between "performing AI" and "using AI to get work done."