Strategist: Evolving Reasoning Strategies with Meta-Agents

Strategist uses meta-agents to evolve reusable code blueprints across tasks, automatically generating and optimizing reasoning strategies.
The article introduces Strategist, a meta-agent that automatically evolves reasoning strategies across tasks. It represents strategies as executable code blueprints and assembles them into a library, retrieving, generating, testing, and revising candidates for new tasks. On 30 benchmarks, it surpasses the strongest baseline on 24, matches average accuracy (74.7% vs 74.0%) while cutting inference cost by 39%, and transfers to unseen tasks and models.
Title
Strategist: Evolving Reasoning Strategies with Meta-Agents
Meta Description
Strategist is a meta-agent that evolves reasoning strategies across tasks. It writes strategies as executable blueprints and builds a blueprint library, automatically improving reasoning pipelines through a loop of retrieval, generation, testing, and revision. Across 30 benchmarks, Strategist surpasses the strongest baseline on 24, matches average accuracy (74.7% vs 74.0%) while cutting inference cost by 39%, and its strategies transfer to unseen tasks and models.
Article Content
Building an AI agent system is half about the model and half about the reasoning strategy—the reasoning pipeline that turns model calls into responses. Today, this other half is written by hand, and the experience gained from building one strategy cannot be reused for the next task. To address this, researchers propose Strategist, a meta-agent that evolves reasoning strategies across tasks.
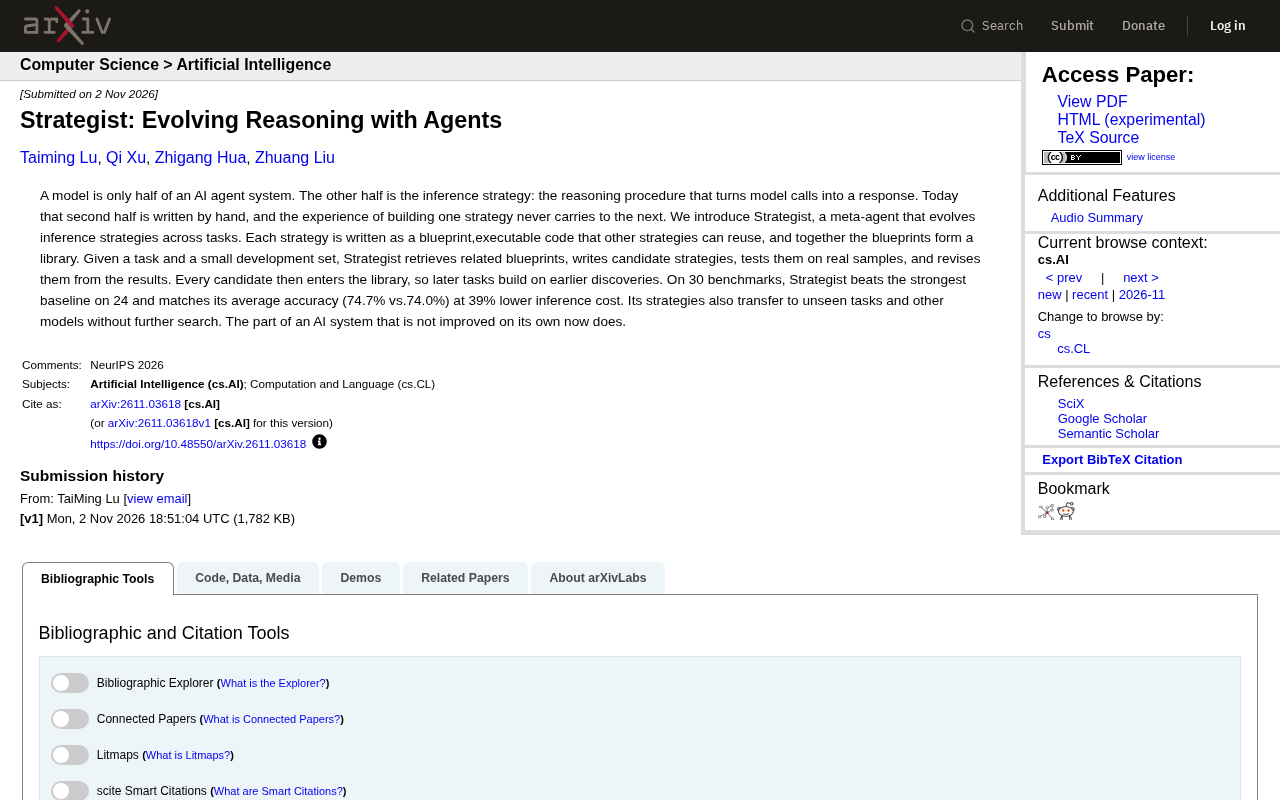
Each strategy exists as a blueprint, i.e., executable code that other strategies can reuse. Together, these blueprints form a library. Given a task and a small development set, Strategist retrieves relevant blueprints, writes candidate strategies, tests them on real samples, and revises them based on the results. Every candidate strategy enters the library, enabling subsequent tasks to build on prior discoveries.
Reasoning Strategies: The Missing Other Half of Agents
There is a fundamental disconnect in how AI agent systems are currently built: model capabilities are advancing rapidly, but the strategies that organize model calls into effective reasoning pipelines still rely on manual design. Developers hand-write prompt chains, tool-calling logic, or reflection loops for specific tasks, and these strategies are often highly customized—switching to a different task means starting from scratch. Experience cannot accumulate, and building each new strategy is an exploration that begins from zero.
Strategist's core insight is that a reasoning strategy itself can be treated as an evolvable program. Rather than writing it by hand, a meta-agent can automatically generate, test, and improve strategies. This effectively automates the meta-level work of "strategy design."
A meta-agent refers to a class of agents that do not directly solve the target task but instead operate on, generate, or improve other agents (or their components). In the context of Strategist, the meta-agent does not directly answer task questions but works on the object of "reasoning strategies": it reads task descriptions and development sets, retrieves from the blueprint library, writes candidate reasoning strategy code, and iterates based on test feedback. This level of abstraction gives the system the ability to "learn how to solve problems," not just "solve problems." The concept of a meta-agent is in line with meta-learning, with the difference being that its object of operation is a strategy program composed of natural language and code, rather than model weights.
How Strategist Works: Blueprints, Retrieval, and the Evolution Loop
Strategist's operating mechanism can be broken down into several key components:
- Blueprint representation: Each reasoning strategy is written as an executable code blueprint. A blueprint is not merely a description but a module that can be directly invoked by other strategies. This code-based representation allows strategies to be composed, reused, and modified.
- Retrieval and generation: When facing a new task, Strategist retrieves relevant strategies from the blueprint library as references and then writes candidate strategies. The retrieval mechanism ensures that past experience is effectively utilized rather than starting from scratch each time.
- Empirical testing and revision: Candidate strategies are run on real samples for testing and revised based on the results. This closed loop grounds strategy evolution in evidence rather than subjective judgment.
- Continuous accumulation: Every candidate strategy ultimately enters the blueprint library, forming a positive feedback loop. Subsequent tasks can build on prior discoveries, and the value of the library grows over time.
This process is essentially an evolutionary search: generating mutations (writing candidates), environmental selection (test results), and retaining superior individuals (entering the library). But unlike traditional evolutionary algorithms, Strategist's mutations are driven by language models and possess semantic understanding.
Evolutionary search is a class of optimization methods inspired by biological evolution, with a typical process that includes: maintaining a population of candidate solutions, producing new solutions through mutation and crossover, and selecting better individuals based on a fitness function, looping repeatedly. Strategist borrows this framework: writing candidate strategies corresponds to "mutation," testing on real samples corresponds to "fitness evaluation," and retaining blueprints corresponds to "selection." The key difference is that the mutation operator is handled by a large language model, so the resulting candidates have semantic plausibility and diversity rather than random perturbations. In addition, the blueprint library serves as a cross-task shared "gene pool," so evolution does not need to restart from an empty population each time, thereby accelerating convergence and improving generalization.
Experimental Performance: Lower Cost, Stronger Generalization
The researchers evaluated Strategist on a set of 30 benchmarks and compared it with the strongest baseline. The results show:
- On 24 benchmarks, Strategist outperforms the strongest baseline.
- Average accuracy is on par with the baseline (74.7% vs. 74.0%), but inference cost is reduced by 39%. This means that with comparable effectiveness, Strategist's strategies are more efficient.
- Evolved strategies can transfer to unseen tasks and other models without further search. This validates the generalization value of the blueprint library—strategies are not artifacts overfit to specific tasks but reasoning patterns with a degree of generality.
These data support a core argument: automatic evolution of reasoning strategies can not only match the effectiveness of manual design but also bring additional gains in efficiency and generalization.
A benchmark here refers to a standardized set of task datasets and evaluation protocols used to compare the performance of different methods. The 30 benchmarks in the article cover multiple types of reasoning tasks, using average accuracy as the primary metric to measure strategy effectiveness. Inference cost usually refers to token consumption or API fees incurred by model calls and is a key constraint in the practical deployment of agent systems: if a strategy contains redundant reflection loops or multiple rounds of tool calls, accuracy may not be low but the cost can be high. Strategist reduces cost by 39% while matching accuracy, indicating that evolved strategies are more streamlined in step organization and number of calls—precisely the efficiency advantage that automated search may discover compared with manual design.
Significance and Limitations: The Boundaries of Strategy Evolution
Strategist's significance lies in bringing "the part that has not been automated" in AI system construction into the optimization loop. Previously, model parameters could be improved automatically through training, but improvements to reasoning strategies depended on humans. Strategist allows strategies to evolve through accumulated experience as well.
However, this method still has its boundaries. First, the quality of the blueprint library depends on the initial development set and the effectiveness of the retrieval mechanism; if a task differs too much from existing strategies in the library, the quality of generated candidates may decline. Second, although code-based blueprints are reusable, they also introduce the burden of execution safety and correctness verification. In addition, although the experimental scale covers 30 benchmarks, the long-term stability of strategy transfer still requires more validation.
Overall, Strategist points to a direction: future AI agent systems may no longer require hand-written reasoning pipelines but instead continuously evolve strategy libraries through meta-agents during tasks. As model capabilities gradually converge, the ability to evolve reasoning strategies may become the key to system differentiation.
One-line Summary
Strategist uses meta-agents to evolve reusable code blueprints across tasks, automatically generating and optimizing reasoning strategies.
Paragraph Summary
This article introduces Strategist—a meta-agent that automatically evolves reasoning strategies across tasks. In current AI agent systems, how model calls are organized into effective reasoning pipelines still depends on manual design, and experience is hard to reuse. Strategist represents reasoning strategies as executable code blueprints and assembles them into a library. When facing a new task, it retrieves relevant blueprints, generates candidate strategies, tests them on real samples, and revises them, with every candidate flowing back into the library to form a positive feedback loop. On 30 benchmarks, Strategist surpasses the strongest baseline on 24, matches average accuracy (74.7% vs. 74.0%) while reducing inference cost by 39%, and the evolved strategies can transfer to unseen tasks and other models. The article also points out limitations such as the blueprint library's quality depending on the development set and retrieval mechanism, and the burden of code execution safety verification.
Related articles

Bypassing DeepSeek Detection: Sneaky Reverse-Proxy Tricks to Avoid Bans and Their Risks
A Bilibili creator shares a DeepSeek reverse-proxy scheme to avoid bans: evading XML tags, using a single English word as trigger, and registering with overseas emails. This article breaks down the technical approach, Harness integration results, and the real risks of this "unlimited tokens" game in terms of rule confrontation, account stability, and compliance.

4 Must-Have Plugins for Saving Tokens in DSH — Stop Installing Blindly
A detailed guide to 4 must-have DSH token-saving plugins: DSH Shops shortens tool output, Billion Context compresses early context, Vision Router converts images to text, and Thinking Levels auto-adjusts thinking depth — plus backup and verification tips before installing.
Retested 51 Times: DeepSeek Harness Token-Saving Plugins — Use Them Right and Save Half, Use Them Wrong and Pay More
51 test runs of three DeepSeek Harness token-saving plugins: Ops saves half only in PTC mode, Flash Presets saves ~20% via rules, Billion Context saves context space but not money. Includes selection guide and pitfalls.