Teaching Propagators to Rank: Learned Priorities Boost Constraint Solving Efficiency
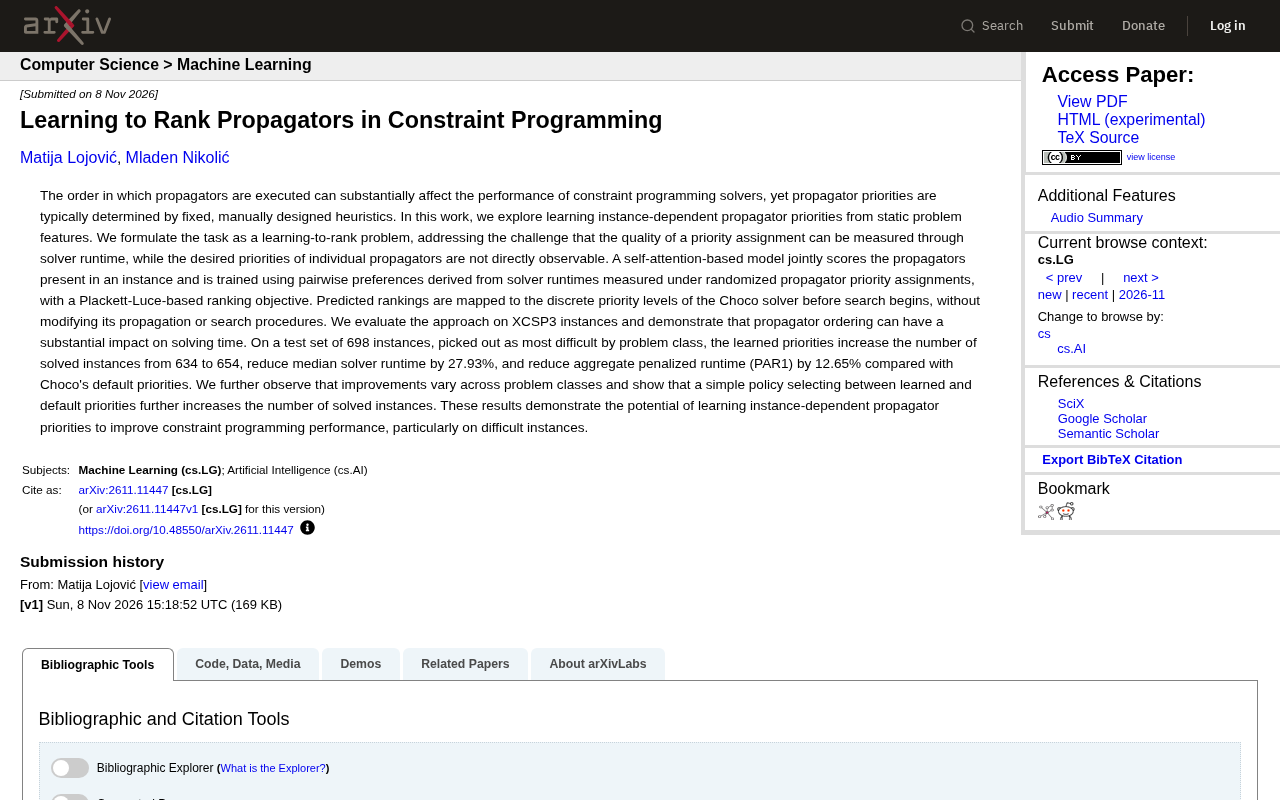
Machine learning learns propagator orderings, significantly improving Choco solving performance on hard XCSP3 instances.
This study addresses the reliance on hand-crafted heuristics for propagator execution order in constraint programming solvers by formulating propagator priority assignment as a learning-to-rank task. It uses a self-attention model to jointly score all propagators in an instance, leveraging solver runtime under random priorities as weak supervision and training with a Plackett-Luce ranking loss. On 698 hard XCSP3 instances, learned priorities increased solved instances from 634 to 654, reduced median runtime by 27.93%, and lowered PAR1 by 12.65%. Further experiments show that dynamically choosing between learned and default priorities based on instance features can further increase solved instances. The method does not modify the solver core and is easy to integrate, but generalization to other solvers still needs verification.
In constraint programming (CP) solvers, performance depends heavily on the execution order of propagators. However, mainstream solvers (such as Choco) typically rely on fixed, hand-crafted heuristics to assign propagator priorities. A recent study proposes using machine learning to learn instance-dependent propagator priorities from static features of problem instances, and validates the effectiveness of this approach on the XCSP3 benchmark.
The Problem: Why Does Propagator Order Matter?
In constraint programming, propagators are responsible for reducing variable domains according to constraints, and the search process relies on these reductions for pruning. The execution order of propagators affects propagation efficiency and solving time. Traditionally, solvers use hand-tuned fixed priorities, such as prioritizing certain types of constraints. This fixed strategy ignores the structural features of specific problem instances and struggles to adapt to differences across problem classes.
This study formulates propagator priority assignment as a learning-to-rank problem: given an instance, the model must output a priority ordering for all propagators in it. The challenge is that the optimal priority of an individual propagator cannot be directly observed, but the overall quality of a priority assignment can be measured by solver runtime. This is a typical weakly supervised learning scenario.
Propagation and Search in Constraint Programming: Constraint programming solvers typically alternate between two phases—propagation and search. In the propagation phase, the propagator corresponding to each constraint removes impossible values based on current variable domains (i.e., reduces variable domains), and this process repeats until a fixed point is reached. In the search phase, branching strategies (such as selecting variables and values) make decisions that further narrow the problem space. The ability of propagators to reduce variable domains directly determines the pruning effectiveness of the search tree: the more thorough the domain reduction, the fewer nodes the search needs to explore. Therefore, the execution order of propagators not only affects the efficiency of a single propagation pass but also indirectly affects overall solving time by changing the convergence speed of propagation. Different propagators may trigger each other, forming propagation chains; different orders lead to differences in intermediate states, which in turn affect the final reduced domains. This is why heuristically arranging propagator order becomes a decision problem worth optimizing.
Method: Self-Attention Model with Runtime Preferences
The research team designed a model based on self-attention that jointly scores all propagators appearing in an instance. The model input is the static features of each propagator (such as constraint type, number of variables, etc.). Through the self-attention mechanism, it captures interactions between propagators and finally outputs a score for each propagator.
Training data is generated by randomizing propagator priorities and recording solver runtime. For the same instance, different random priorities produce different runtimes; the model extracts pairwise preferences from these runtimes (priority assignments with shorter runtimes are better) and trains with a Plackett-Luce-based ranking loss. In this way, the model learns "which ordering is more likely to yield shorter solving time" rather than directly fitting the absolute priority of each propagator.
The predicted ordering is mapped to Choco solver's discrete priority levels and injected before search begins. The entire process does not modify Choco's propagation or search algorithms—only propagator priorities are adjusted—so it offers good generality and low intrusiveness.
The Plackett-Luce Model and Ranking Loss: The Plackett-Luce model is a probabilistic model for modeling ranking data, commonly used in learning-to-rank tasks. It assumes there is a latent "utility value" corresponding to each item; given a set of items, the probability of a ranking is proportional to the exponentials of these utility values. Specifically, for a ranking π, its probability is ∏{i=1}^{n} exp(s{π(i)}) / ∑{j=i}^{n} exp(s{π(j)}), where s is the score output by the model. In this study, the model outputs a score for each propagator, and the Plackett-Luce loss encourages propagators with higher scores to rank earlier, making the overall ordering more likely to produce shorter runtime. During training, by comparing runtimes produced by different random priorities on the same instance, pairwise preferences are constructed (orderings with shorter runtime are preferred over those with longer runtime), and then the likelihood of these preferred orderings is maximized. This method does not require absolute priority labels for each propagator—only relative comparisons—making it very suitable for weakly supervised settings.
Experiments: Results on XCSP3
The study was evaluated on XCSP3 benchmark instances. The experiments selected 698 test instances labeled by problem class as the hardest, comparing learned priorities with Choco's default priorities. Main results include:
- More instances solved: Learned priorities increased the number of successfully solved instances from 634 to 654.
- Lower median runtime: Median solving time decreased by 27.93%.
- Lower penalized average runtime (PAR1): The PAR1 metric dropped by 12.65%.
These results show that even simple learned priority adjustments can bring significant performance gains on hard instances. The study also observed that improvements vary by problem class—some problem classes benefit more, while others show little change.
PAR1 and Median Runtime: PAR1 (Penalized Average Runtime with 1 second penalty) is a commonly used metric for evaluating solver performance, especially suitable for benchmarks with unsolved instances. For each instance, if the solver successfully solves it within the given time limit, the actual runtime is recorded; if it times out or fails, it is recorded as a multiple of the time limit (usually 2 times the time limit or a fixed penalty value). PAR1 is the average runtime over all instances, where unsolved instances are assigned a penalty value. Therefore, PAR1 reflects both solving speed and robustness: lowering PAR1 means either solving solved instances faster or solving more hard instances. Median runtime focuses on the typical performance of solved instances and is not affected by extreme values. Used together, these two metrics provide a more comprehensive evaluation of propagator priority learning.
Simple Strategy Fusion: Switching Between Learned and Default
Because improvement levels differ across problem classes, the researchers further tried a simple strategy: choosing between "learned priorities" and "default priorities" based on instance features. Experiments show that this selection strategy can further increase the number of solved instances, indicating that learned priorities are not always better than the default strategy and that dynamic selection can combine the advantages of both.
This finding also suggests that practical deployment may require a lightweight meta-decision layer that decides whether to use the learned ordering based on static instance features.
Significance and Limitations
The core contribution of this work is formalizing propagator priority learning as a ranking problem and using solver runtime as a weak supervision signal, avoiding the difficulty of directly obtaining propagator-level labels. The method does not modify the solver core and is easy to integrate into existing CP solvers.
However, current experiments are limited to the Choco solver and the XCSP3 benchmark; generalization to other solvers (such as Gecode and OR-Tools) and broader problem domains still needs verification. In addition, the training process requires a large amount of runtime data under random priorities, and the computational overhead cannot be ignored. Future work may explore more efficient training signals and cross-solver transfer learning.
Overall, this study provides a new perspective for heuristic learning in constraint programming and demonstrates the potential of machine learning for optimizing internal solver decisions.
One-line Summary
Machine learning learns propagator orderings, significantly improving Choco solving performance on hard XCSP3 instances.
Paragraph Summary
To address the reliance on hand-crafted heuristics for propagator execution order in constraint programming solvers, this study formulates propagator priority assignment as a learning-to-rank task. The method uses a self-attention model to jointly score all propagators in an instance and uses solver runtime under random priorities as a weak supervision signal, training with a Plackett-Luce ranking loss. On 698 hard XCSP3 instances, the learned priorities increased the number of successfully solved instances from 634 to 654, reduced median runtime by 27.93%, and lowered PAR1 by 12.65%. Further experiments show that dynamically choosing between learned and default priorities based on instance features can further increase the number of solved instances. The method does not modify the solver core and is easy to integrate, but generalization to other solvers still needs verification.
Related articles
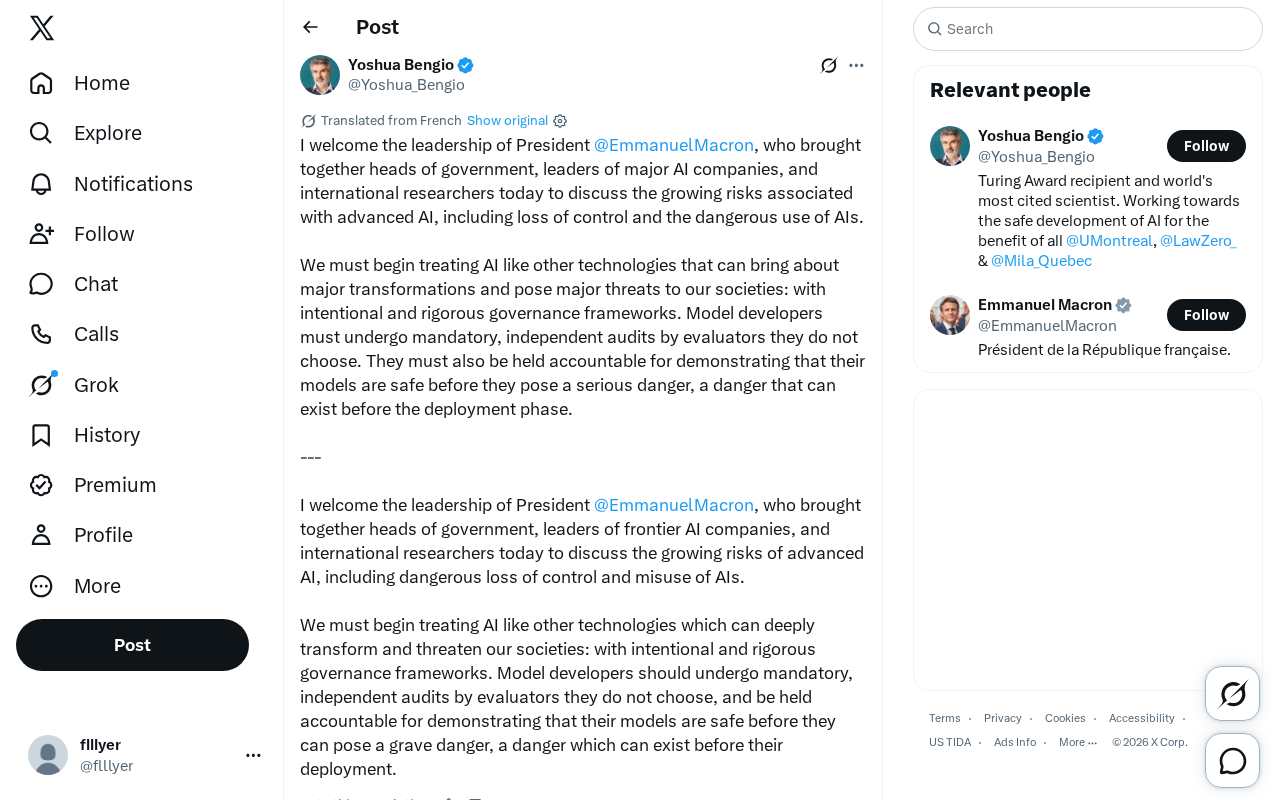
New AI Governance Initiative: Mandatory Independent Audits and Pre-Deployment Safety Proof
Macron convened government leaders, AI company executives, and researchers to discuss advanced AI risks. Statements call for a rigorous governance framework requiring mandatory independent audits and pre-deployment safety proof.

Roblox Funds Controversial Anorexia Treatment
Roblox funds flow to a controversial creator who promotes ketogenic diets over conventional treatment for anorexia and bulimia, raising medical and regulatory concerns.
GitHub Daily · November 19: Veteran Frontend Framework Returns to the Charts, Historical Map Project Gains Nearly a Thousand Stars in a Day
GitHub Trending Nov 19: jQuery and SolidJS both make the list, Appwrite adopts an agent-oriented positioning, and Jiangshan Shixu gains nearly 1,000 stars in a day.