The Gemini 4 Naming Puzzle: Argon, Carbon, and Hydrogen Compared
Google's Gemini 4 naming confuses developers; the community uses pricing and tier analogies to infer positioning.
The article examines the naming of Google's Gemini 4 series—Argon, Carbon, and Hydrogen—noting that the lack of official architecture documentation makes it hard for developers to understand. A YouTube creator draws analogies to model tiers developers know: Argon maps to the Opus tier, Carbon to Fable or Astra, and Hydrogen to Sonnet or even Haiku. The pricing page offers a harder clue—Carbon and Argon have identical unit prices (per million tokens, $4/$20)—suggesting similar underlying capabilities. Combined with Google's statement that "Carbon is built on Argon," the author speculates Carbon may be a reasoning-enhanced version of Argon, with the same unit price but higher token consumption on complex tasks, raising total cost. The article advises developers to triage model selection by task complexity and monitor actual token consumption.
Google's choice of the names Argon, Carbon, and Hydrogen for the Gemini 4 series has left many developers scratching their heads. In a video, a YouTube creator admitted that his limited chemistry knowledge meant he couldn't fully grasp the naming logic, but he offered a rough yet practical classification framework: Argon corresponds to the Opus tier, Carbon to the Fable or Astra tier, and Hydrogen to the Sonnet or even Haiku tier.
A Positioning Framework for the Three Models
In the absence of detailed official documentation, drawing analogies to model tiers developers already know is the fastest way to make sense of the new names. According to the video's analysis, Argon is seen as a frontier model that's always available, Carbon leans toward additional reasoning and more complex tasks, and Hydrogen is positioned as the lighter-weight option. Although this mapping is speculative, it gives developers an intuitive reference point for choosing a model.
It's worth noting that the analogy above comes from a single video source and is not an official Google definition. With no official architecture documentation available, this kind of community interpretation can serve as a reference for model selection, but it shouldn't be treated as a settled conclusion.
The names "Opus, Fable, Astra, Sonnet, Haiku" used for comparison in the article are product-tier names commonly used by other major model vendors, usually ordered from highest to lowest capability and price: Opus/Astra represent flagship model lines with the strongest reasoning capabilities, Sonnet/Fable are balanced mainstream models, and Haiku focuses on low latency and low cost. The developer community often borrows this hierarchy to compare model positioning across vendors, because each vendor's official naming is inconsistent, and tier-based analogies are more intuitive than memorizing model names. Keep in mind that this cross-vendor tier mapping is only a rough, empirical approximation; how each model performs on specific tasks still depends on details like training data, context length, and tool calling, and the models can't simply be treated as equivalent.
What the Pricing Reveals
The pricing page offers a harder clue. According to the video, Carbon and Argon have identical input and output pricing: $4 per million input tokens and $20 per million output tokens, effective from December 1.
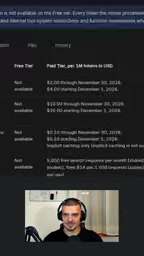
When two models share the same price, it often means their underlying capability ranges are similar, and the difference may lie in reasoning configuration rather than the base model itself. This aligns with the video creator's speculation and provides a basis for later judging Carbon's true cost.
A token is the basic unit of billing for large models, roughly understood as a chunk of text after splitting; typically one English word corresponds to one or two tokens, and Chinese uses more. Pricing input and output separately is standard industry practice, because generating output requires token-by-token forward computation, which usually costs more than processing input. The "$4/$20 per million tokens" mentioned in the article refers to the input and output unit prices respectively, calculated per million tokens to align with batch-call scenarios. When two models have the same unit price, the difference in total cost mainly comes from the actual number of tokens consumed—the more reasoning steps and the longer the context, the greater the consumption. This is why judging Carbon's true cost requires attention to call volume rather than unit price alone.
Inferences Amid Scarce Architecture Information
Google hasn't disclosed much architectural detail, saying only that Carbon is built on Argon. The video creator raises a question: does this mean the two are essentially the same model with different settings, using additional reasoning steps to handle more complex tasks—raising task costs while keeping the underlying architecture the same?
This inference is reasonable. If Carbon is merely a reasoning-enhanced version of Argon, then identical pricing may hide different billing logic—Argon is more economical for simple tasks, while complex reasoning tasks go to Carbon; despite the same unit price, the actual number of tokens consumed will drive up total cost.
Reasoning enhancement is a common configuration approach in current large-model products: the same base model can improve accuracy on complex tasks by adding "thinking" steps, multiple sampling, or self-verification, at the cost of more tokens and longer response times. This is sometimes presented as a separate model and sometimes controlled via a parameter switch. So "Carbon is built on Argon" can be understood as different reasoning configurations of the same underlying model, rather than two completely independent models. If this inference holds, developers should factor task complexity and token budget into model selection together, rather than judging by unit price alone.
What It Means for Developers
Until official architecture documentation is complete, developers can do a preliminary triage by task complexity: prioritize Argon for routine, high-frequency tasks, turn to Carbon for complex tasks requiring a stronger reasoning chain, and evaluate Hydrogen for lightweight scenarios. At the same time, pay close attention to actual token consumption during calls, because the same unit price doesn't mean the same total spend.
Whether this naming system takes hold depends on whether Google later provides more transparent architecture and capability documentation. Until then, the community's empirical analogies remain an important reference point.
One-line Summary
Google's Gemini 4 naming for its three models is confusing; the community uses pricing and tier analogies to infer their positioning.
Paragraph Summary
The article examines the naming of Google's Gemini 4 series—Argon, Carbon, and Hydrogen—noting that the lack of official architecture documentation makes it hard for developers to understand. A YouTube creator draws analogies to model tiers developers know: Argon maps to the Opus tier, Carbon to Fable or Astra, and Hydrogen to Sonnet or even Haiku. The pricing page offers a harder clue—Carbon and Argon have identical input and output unit prices ($4/$20 per million tokens), suggesting similar underlying capability ranges. Combined with Google's statement that "Carbon is built on Argon," the author speculates that Carbon may be a reasoning-enhanced version of Argon, with the same unit price but higher token consumption on complex tasks, raising total cost. The article advises developers to triage model selection by task complexity and monitor actual token consumption.
Related articles

OpenAI to Shut Down Agent Builder and Two Other Services on November 30, Developers Must Migrate Urgently
OpenAI will shut down Agent Builder, the evals dashboard, and reusable prompts on November 30; evals is already read-only. Here's the scope, OpenAI's migration paths (Agent SDK, PromptFu, your own code), and what developers should export and rebuild this week.

RankSpot: A Pay-Per-Use SEO & AI Search Execution Layer That Lets Agents Write, Publish, and Build Backlinks for You
RankSpot is an SEO & AI search execution layer for AI Agents. Connect via MCP to Claude or ChatGPT to write, publish & build backlinks. Pay-per-use, $3/article.

Appxiom: Giving AI Coding Assistants Production Context
Appxiom gives AI coding agents production context—crashes, jank, memory leaks, failed network calls—across Android, iOS, Flutter, KMP, and Web, ranking bugs by Goal Friction Impact.