The Microservices Regret Wave: Why Developers Want Their Monoliths Back
The Microservices Regret Wave: Why Dev…
Microservices costs are often underestimated; architecture should serve the business and team, not chase trends.
Using the 2019 article "Give Me Back My Monolith" as a starting point, the piece reflects on the underestimated costs of the microservices boom. It notes that microservices break a monolith's internal function calls and transactions into fallible remote requests and distributed consistency problems, with operational complexity, debugging difficulty, and deployment coordination costs hidden by the halo of "scalability." It further invokes Conway's Law: without clear organizational boundaries, forced decomposition only hardens chaos into the architecture. The author clarifies the original does not advocate retreating to monoliths but promotes a middle ground like the modular monolith, using team size, differentiated scaling needs, and observability maturity as pragmatic criteria—ending on a prudent architectural outlook: understand the problem first, then choose the tool.
A Belated Technical Reckoning
In 2019, an article titled "Give Me Back My Monolith" sparked discussion in the tech community and gained attention on Hacker News. The title was blunt to the point of being emotional—"give me back my monolith"—yet it precisely captured the genuine state of mind of many frontline developers at the time. Microservices architecture was then at the peak of its prestige; nearly every tech conference and every architecture upgrade proposal was discussing how to break systems into smaller services. The value of this short essay lies in the fact that it did not position itself against progress, but rather reminded people: the cost of architectural choices often only truly becomes apparent after implementation.
Discussions from different sources around this theme corroborate one another. Technical discussions on Hacker News and retrospective posts from multiple engineering blogs all point to a similar predicament: the growth in complexity brought by decomposition far exceeds what most teams anticipated. This cross-source consensus turns "microservices reflection" from an individual developer's complaint into an industry phenomenon worthy of serious attention.
The Underestimated Cost of Distribution
The appeal of monolithic architecture lies in its simplicity: one deployment, one process, one data source. When the business needs to modify a feature, developers only need to locate the logic in the codebase, make the change, package it, and ship it. But when microservices scatter this cohesion into network calls, what were originally function calls become remote requests that may fail, and what were originally transactions become distributed consistency problems that require coordination.
The core argument of the original article lies precisely here: the operational complexity, debugging difficulty, and deployment coordination costs introduced by microservices are often overshadowed by the halo of "scalability" on architecture diagrams. Teams need to maintain a whole infrastructure stack—service discovery, distributed tracing, configuration centers, message queues, and more—and building and maintaining these components is itself an enormous engineering effort. For smaller teams, these costs often translate directly into slower delivery speed. According to public retrospectives from multiple engineering teams, the most common problem after decomposition is not performance bottlenecks but longer troubleshooting time—a single request spans multiple services, logs are scattered everywhere, and problem localization goes from minutes to hours.
Distributed Tracing is core infrastructure for tackling the troubleshooting challenges of microservices. In a monolithic application, the complete call stack of a request naturally exists within the same process and can be reconstructed through logs or a debugger. In a microservices architecture, however, a single user request may span gateways, authentication, business logic, data, and other services, with each service recording only its own local logs and no correlation between fragments. Distributed tracing works by generating a globally unique Trace ID at the request entry point and passing Span IDs hop by hop along the call chain, stringing together log fragments scattered across services into a complete call tree. Tools such as OpenTelemetry, Jaeger, and Zipkin exist for this purpose. However, the cost of adopting distributed tracing itself is not low: it requires unified instrumentation across services, a unified context propagation protocol, and configured sampling strategies to control storage overhead—this is also the additional construction work teams must bear behind the "longer troubleshooting time" mentioned in the original article.
The Reverse Effect of Conway's Law
Microservices also carry a frequently mentioned implicit premise: it assumes that the organizational structure can support the independent evolution of services. Conway's Law states that system architecture mirrors the communication structure of the organization. Conversely, if the teams themselves are not clearly divided along business domains, forcibly splitting services will only solidify organizational chaos into the architecture.
The original article's observation on this point is quite insightful: many teams are motivated to split microservices not because the business truly needs independent scaling, but out of anxiety about "architectural advancement." The result is blurred service boundaries, teams bickering repeatedly over interface changes, and changes that could have been quickly negotiated within a monolith becoming cross-team collaboration processes. Some practitioners point out in discussions that the losses caused by such organizational friction are often harder to quantify and harder to repay than technical debt. It should be noted that this view is not without controversy in the community—those who support microservices argue that the difficulty of boundary划分 is precisely an opportunity to push organizations to clarify responsibilities, rather than a flaw of the architecture itself.
Conway's Law was proposed by computer scientist Melvin Conway in 1968 in the paper "How Do Committees Invent?" Its original formulation is: organizations that design systems produce designs that are copies of their own communication structures. In other words, if a company has four teams responsible for compilation, linking, loading, and execution respectively, the final delivered compiler will likely have four phases. This law was later popularized after being cited by Fred Brooks in "The Mythical Man-Month" and was reactivated in the microservices era—Amazon's "two-pizza team" principle is a typical example of its positive application. The key to understanding Conway's Law is that it describes a "necessary mapping" rather than an "ought-to mapping"; therefore, in practice, the "Inverse Conway Maneuver" emerged: design the desired architecture first, then adjust the team structure accordingly, rather than passively accepting how the organizational status quo shapes the architecture.
Monoliths Are Not Obsolete—They Just Need a Better Form
It is worth clarifying that the original article does not advocate that all systems should retreat to monoliths. Its true position is: architecture should serve business scale and team capability, rather than making teams cater to some popular paradigm. In recent years, the popularity of the concept of "Modular Monolith" is, to some extent, a continuation of this line of thinking—maintaining clear module boundaries within a single deployment unit, enjoying the operational simplicity of a monolith while reserving space for possible future decomposition.
Judging from the consensus in community discussions, more pragmatic criteria include: whether the team is large enough to require independent deployment, whether the business has genuinely differentiated scaling needs, and whether mature observability capabilities are already in place. If the answers to these questions are negative, then a monolith is often the more rational starting point. This judgment appears repeatedly in multiple engineering retrospectives, forming a powerful correction to the rhetoric that "microservices are correct by default."
Modular Monolith refers to organizing code within a single deployment unit and a single process through clear module division and boundary constraints, where modules communicate only through well-defined interfaces and direct access to internal implementations across modules is prohibited. Its difference from the traditional "big ball of mud" monolith lies in boundary discipline, and its difference from microservices lies in the degree of coupling in deployment and runtime. Typical practices include: dividing module packages by business domain, using compile-time or architecture testing tools (such as ArchUnit for Java and NetArchTest for .NET) to enforce dependency rules, and decoupling modules through domain events. Its advantage is retaining the deployment and debugging simplicity of a monolith while reserving clear seams for future service decomposition by module; its challenge is that boundary discipline requires team self-discipline and lacks the "physical enforcement" of a network boundary.
Lessons for Architecture Decision-Makers
The reason "Give Me Back My Monolith" is still repeatedly mentioned years after publication is that it touches on an enduring technical proposition: complexity has a cost, and the essence of architectural decisions is making trade-offs among different costs. Microservices solve the problems of large-scale collaboration and independent evolution, but at the same time they transfer the inherent difficulties of distributed systems to every team that uses them.
For today's developers, the lesson of this article is not to take sides between monoliths and microservices, but to establish a prudent architectural outlook: understand the problem first, then choose the tool. When someone tells you that a certain architecture is a "best practice," it is worth asking—whose problem does it solve, and who bears its cost?
Observability originates from cybernetics and refers to the ability to infer a system's internal state solely from its external outputs. In the context of software engineering, it usually consists of the three pillars of logs, metrics, and traces, and in recent years dimensions such as continuous profiling have been added. The difference between observability and traditional monitoring is that monitoring answers known questions such as "is the system normal," while observability supports exploratory troubleshooting of unknown problems. For teams considering decomposing into microservices, observability capability is a precondition rather than an after-the-fact patch—if a team has not yet established sufficient visibility into the system's internal state at the monolith stage, then after decomposition each service will become a harder-to-observe black box, and troubleshooting costs will rise multiplicatively.
Related articles
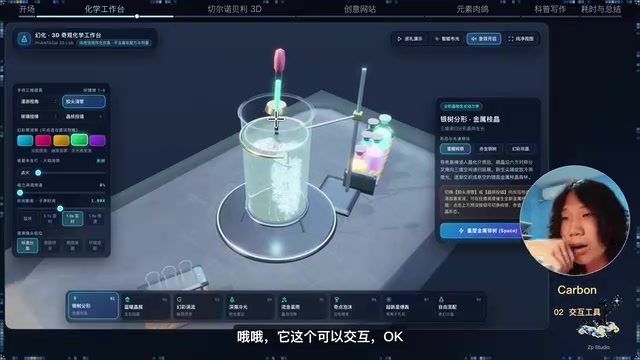
Gemini 4 Trio Hands-On: Which Is Stronger — Hydrogen, Neon, or Carbon?
Bilibili creator ZP Studio tested Gemini 4's Hydrogen, Neon, and Carbon across five tasks, comparing speed and detail: Hydrogen fastest, Carbon most detailed, Neon in between.
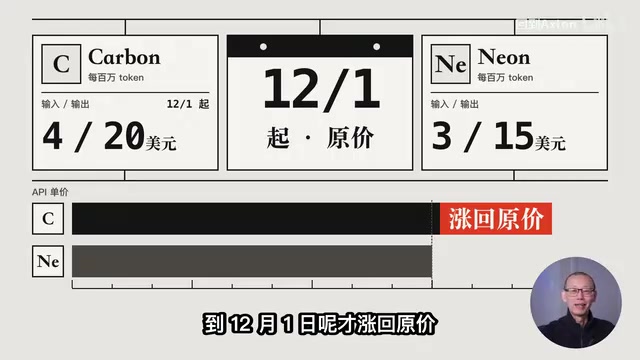
Deep Dive: Uncovering the Capabilities of the Entire Gemini 4 Model Family — Why Does the Default Tier Rank Last?
Double-blind testing of Gemini 4's four models — Argon, Carbon, Hydrogen, Neon — reveals why the default Neon High ranks last, how X High overtakes Carbon, and how Orchestrator sweeps 3-0, plus cost breakdown and four selection tips.
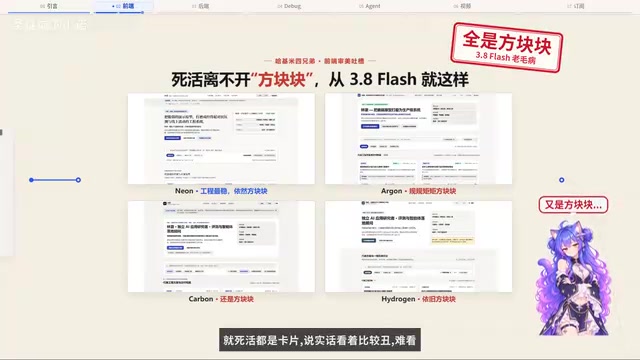
One Week with the Gemini 4 Family: Four Models Each Take a Crown on the Private Leaderboard, Carbon's Speed Polarizes
Bilibili creator tests the Gemini 4 family for a week: Neo, Argon, Carbon, and Hydrogen each top a private leaderboard, frontend aesthetics are weak, Carbon is strongest but slow.