The Race to Prove AI Models Are 'Dangerous': The Marketing Logic Behind Safety Narratives
AI companies are racing to highlight their models' dangers — because "dangerous" has become a proxy for "powerful."
A counterintuitive trend has emerged in the AI industry: rather than downplaying risks, major companies are competing to emphasize their models' dangerous capabilities in safety reports. The implicit logic is that dangerousness signals high intelligence and generality, making it a de facto endorsement of technical leadership. This dynamic blurs the line between genuine safety research and commercial marketing — risk disclosures may simultaneously serve transparency and brand-building, fear marketing objectively raises the industry's profile and valuations, and proactively showcasing danger may help incumbents construct regulatory entry barriers. The article urges observers to apply critical thinking and distinguish reproducible risk evidence from strategically motivated narratives.
A Paradox in the AI Industry
A seemingly contradictory trend is emerging in the AI industry: major AI companies appear to be competing to demonstrate that their models pose potential threats to humanity. This runs counter to the typical logic of tech product marketing — companies usually go to great lengths to downplay product risks. Yet in the AI space, highlighting a model's "dangerous capabilities" has become a distinctive form of competitive posturing.
This phenomenon was sparked by a discussion on Hacker News. While the original thread was brief, it touched on a fascinating underlying dynamic in today's AI industry: why does demonstrating a model's potential danger serve as proof of its power?
The Implicit Narrative: "More Dangerous = More Capable"
In the context of AI capability evaluation, a model that can exhibit "dangerous" behaviors is often interpreted as having reached a considerable level of intelligence and general-purpose capability. If a model can help design complex systems, write sophisticated code, or even theoretically participate in sensitive tasks, that in itself speaks to the breadth of its capability.
This has given rise to a subtle communications logic: when a company claims "our model is powerful enough to require special safety measures," it is effectively signaling to the market that its technology is at the cutting edge. Dangerousness becomes a proxy for capability, and safety evaluation reports become endorsements of technical prowess.
This narrative appears repeatedly in the technical reports of leading AI labs. The sections on "potential misuse risks" and "dangerous capability evaluations" in model cards serve a dual purpose: on one hand, they fulfill a genuine responsible disclosure obligation; on the other, they quietly shape public perception that "our model is sufficiently advanced."
The Blurring Line Between Safety Research and Marketing
AI safety research is supposed to be a serious scientific endeavor aimed at identifying and mitigating real risks. But when "dangerous capability demonstrations" become entangled with commercial competition, the boundaries start to blur.
Several layers of concern emerge:
The Dual Motivation Behind Risk Disclosure
When companies publish dangerous capability assessments, the motivation may be a genuine commitment to transparency — or it may be mixed with commercial incentives to project an image of technical leadership. When safety narratives are used as tools for competitive differentiation, it becomes difficult to discern which warnings are grounded in rigorous evidence and which are engineered to generate buzz.
The Potential Effects of Fear Marketing
Emphasizing AI's threat potential objectively draws attention from the public and regulators, which in turn inflates the visibility and valuation expectations of the entire industry. For AI companies operating under funding and competitive pressure, "our technology is powerful enough to be alarming" is an extraordinarily compelling message.
A Regulatory Strategy
Proactively showcasing a model's dangerous capabilities may also be a strategic move by leading companies in the regulatory game — by stressing the complexity and risks of the technology, they help lay the groundwork for high-threshold compliance frameworks that ultimately entrench their market position.
This phenomenon has a clear industry backdrop. In recent years, leading labs including OpenAI, Anthropic, and Google DeepMind have each established dedicated "frontier safety" or "dangerous capability evaluation" processes and publicly disclosed results at model launch. Anthropic calls its approach the "Responsible Scaling Policy," while OpenAI has a "Preparedness Framework" that evaluates model risk levels across dimensions such as chemical weapons, cyberattacks, and persuasion and manipulation. These frameworks carry a degree of academic rigor, but critics note that the timing of evaluation disclosures tends to align closely with product launches, and the language generally leans toward dramatizing capability boundaries rather than conveying uncertainty. This makes it difficult for outside observers to judge: are these assessments the product of independent safety research, or are they product launch materials dressed up in PR packaging?
This strategy has a corresponding economic theory, often referred to as "Regulatory Capture" or "entry barrier construction." When industry leaders actively lobby for stricter regulation, it is often because compliance costs are manageable for well-resourced large companies while imposing steep hurdles for startup competitors. In the AI space, OpenAI's Sam Altman has testified before the U.S. Congress multiple times and called for legislative oversight — a move some analysts interpret as an attempt by leading players to help shape the rules of the game before industry norms solidify, ensuring the resulting framework works in their favor. This is not necessarily malicious, but the intertwining of interests warrants ongoing scrutiny.
How to Think About This Rationally
Faced with these narratives, ordinary users and industry observers need to maintain a degree of critical thinking. AI capabilities and risks are both real, but when "dangerousness" becomes a competitive instrument, the information being presented may be deliberately amplified or selectively framed.
On one hand, we should not dismiss the value of AI safety research outright — identifying potential avenues for model misuse is genuinely important. On the other hand, we must remain alert to the tendency to co-opt safety assessments as marketing tools. The truly responsible approach is to conduct risk evaluations based on reproducible evidence, not to court attention by stoking fear.
The Hacker News discussion on this topic was brief, but it serves as a reminder: in the AI field, which is ripe with both opportunity and controversy, any claim about "capabilities" or "risks" deserves a follow-up question — is this a scientific finding, or a competitive strategy?
When evaluating the credibility of AI safety claims, a few practical dimensions are worth considering. First, has the risk assessment been independently reproduced by third parties, or does it rely entirely on the company's own internal data? Second, do demonstrations of "dangerous capabilities" come with clearly defined triggering conditions and failure rates, or do they only showcase the most dramatic edge cases? Third, does the timing of a safety report's release closely coincide with a funding round, a competitor's product launch, or a regulatory review window? It is also worth noting that the definition of "dangerous capability" varies considerably across reports — the same capability might be labeled "high risk" by one company and described as a "routine feature" by another. This lack of definitional consistency introduces substantial noise into any attempt to interpret the information.
Closing Thoughts
The race among AI companies to "prove" their models are dangerous reflects the unique communications ecosystem of this industry. Technical capability, safety responsibility, and commercial marketing converge here, creating a situation that resists simple judgment. As observers, perhaps the most essential skill we can develop in navigating this AI wave is a clear-eyed ability to distinguish genuine risk from marketing rhetoric.
Related articles
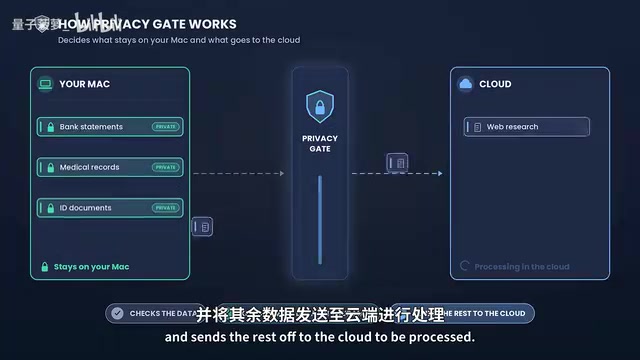
Perplexity Hybrid Compute Tested: Privacy Data Never Leaves the Mac
Perplexity Hybrid Compute tested: how PrivacyGate intercepts sensitive data, how local and cloud models divide work, model differences on 16GB vs 32GB Macs, and privacy protection in real scenarios like bank statements and medical records.
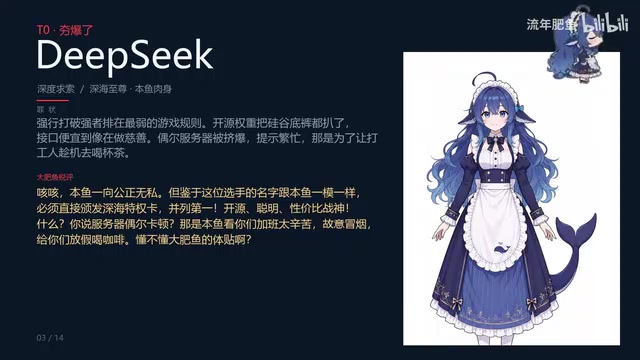
Big Fat Fish Roasts Mainstream LLMs at Home and Abroad: Doubao Takes the Crown, DeepSeek Tied for First
Bilibili creator Big Fat Fish roasts mainstream LLMs: Doubao tops for emotional value, DeepSeek ties first for open-source value, with ERNIE, Hailuo, Yuanbao, Kimi, Qwen, Kling, Claude, Gemini, and Grok each branded with a distinct persona.
How to Truly Test AI Agents Before Production? A Practical Testing and Monitoring Framework
BotGage founder Pramin Pradeep shares a three-step framework for testing AI Agents before production: Agent registration visibility, red teaming, and production observability — plus a real case cutting QA costs from $180K to $80K and an analysis of IT roles shifting to Agent supervisors.