The Real Efficiency Bottlenecks for AI Developers: It's Not the GPU — It's These Overlooked Areas

For AI developers, the real productivity bottlenecks are often RAM, SSDs, monitors, and workflows — not GPUs.
AI developers commonly assume more GPU power equals higher productivity, but the true efficiency bottlenecks often lie in overlooked areas: insufficient RAM causing system thrashing, slow storage starving data pipelines, single-monitor setups increasing cognitive load, and unoptimized workflows wasting hours daily. This article examines why GPU upgrades face diminishing returns and reveals the high-ROI alternatives — from NVMe SSDs and memory expansion to workflow automation and network optimization.
A Myth That Keeps Getting Repeated
In the AI and machine learning community, there's an almost default belief: if you want to boost your productivity, go buy a bigger, more powerful GPU. Whether it's deploying large models locally or training your own networks, the hardware arms race always seems to be at the center of the conversation.
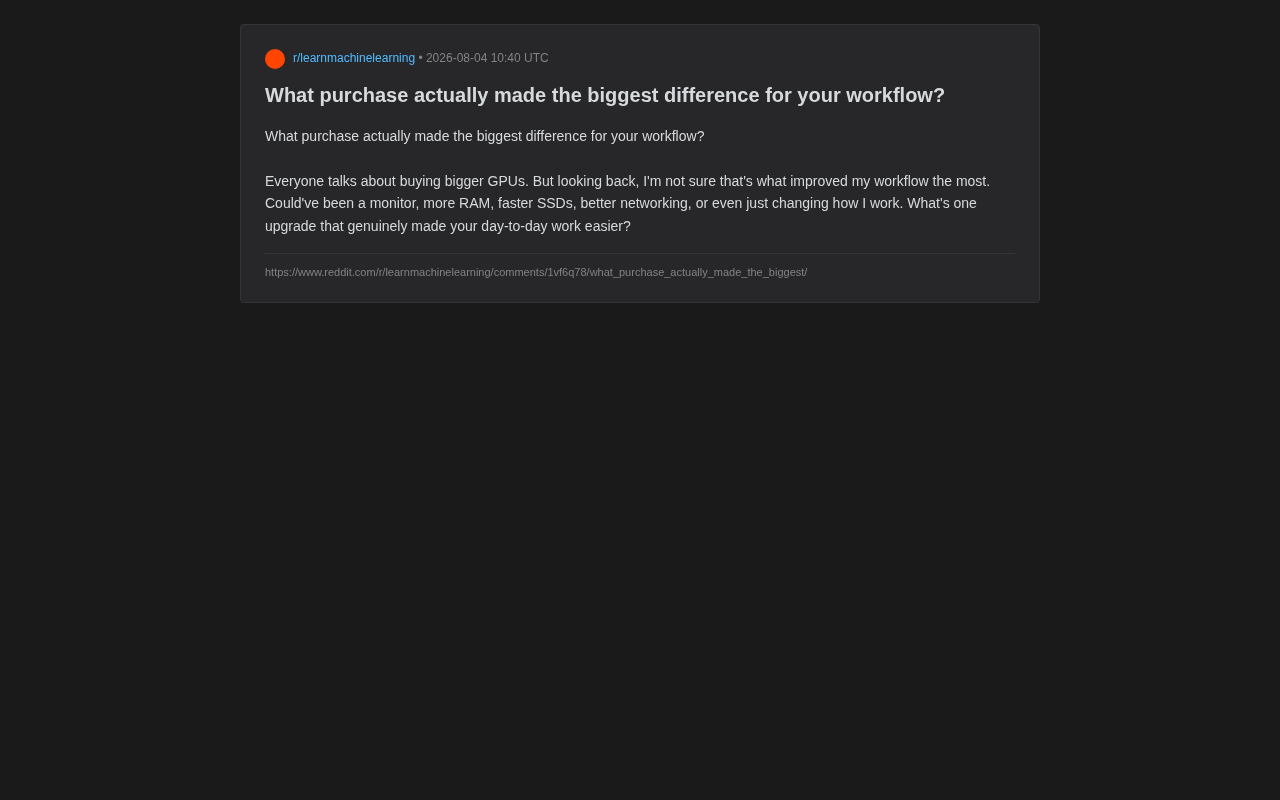
However, a heated discussion on Reddit posed a thought-provoking counter-question: "Looking back, what was the investment that actually improved your workflow?"
The poster admitted they weren't sure a bigger GPU was the key to better efficiency. It might have been a monitor, more RAM, a faster SSD, better networking, or perhaps just changing the way they work. The question resonated widely because it touches on a truth long obscured by hardware marketing: compute power ≠ productivity.
Why the GPU Isn't Always the Answer to Efficiency
The Bottleneck Often Isn't Where You Think
For most AI developers, daily workflows aren't dominated by full-throttle GPU training jobs running around the clock. More often, time is wasted on data loading, code debugging, environment configuration, file transfers, and waiting for compilations. The bottlenecks in these steps often have nothing to do with GPU compute power.
This relates to a classic concept in computer science — Amdahl's Law. The law states that a system's overall speedup is limited by the portion of the task that cannot be parallelized. In other words, even if you scale your GPU's compute power to infinity, if only 30% of your workflow time is spent on GPU computation, the theoretical maximum speedup only reduces total time to 70% of the original. The remaining time is consumed by I/O operations, serial CPU logic, and human interaction — areas the GPU simply cannot touch. Furthermore, the widely present "von Neumann bottleneck" in modern computing systems — the data transfer bandwidth limitation between processor and storage — means that even with the most powerful compute units, the problem of being unable to "feed" data fast enough will leave compute resources idle.
When your dataset needs to be repeatedly read from a slow disk, even the most powerful graphics card can only sit and wait. When your development environment frequently crashes due to dependency conflicts, the experience difference between an A100 and a consumer GPU is negligible. This is exactly why many people find that "the perceived improvement is limited" after spending a fortune on a GPU upgrade.
Diminishing Marginal Returns on GPU Upgrades
GPU upgrades exhibit clear diminishing marginal returns. The leap from nothing to something, from entry-level to mid-range, is indeed immediately impactful. But each step from high-end to top-tier sees costs growing exponentially while improvements to daily workflows become increasingly marginal.
Take NVIDIA's consumer product line as an example: going from an RTX 3060 (12GB VRAM, ~$280) to an RTX 4090 (24GB VRAM, ~$1,800), the price increases by over 6x, but actual throughput improvement in inference scenarios is only about 3-4x. In day-to-day development — loading models, debugging code, running small-scale experiments — this gap is compressed even further because the GPU spends most of its time idle. Research shows that in a typical model development cycle, GPU compute utilization is often only 30%-50%, with significant time spent on data preprocessing, hyperparameter search preparation, and results analysis. This "performance bottleneck migration" phenomenon means that once you upgrade the strongest component, the system's weakest link immediately reveals itself elsewhere.
Unless your core task is large-scale training strictly bottlenecked by compute, that budget likely has better cost-effective destinations.
Underestimated High-Value Upgrades
RAM Expansion: The Most Easily Overlooked Accelerator
In discussions like these, RAM almost always appears as a top answer. Sufficient memory means you can keep your IDE, browser, database, multiple Docker containers, and large dataset caches open simultaneously without constantly switching between applications or waiting on swap.
From a technical perspective, when physical memory is insufficient, the operating system activates the virtual memory mechanism, swapping memory pages out to disk. Even with an NVMe SSD, random read/write latency is on the order of microseconds, while DRAM latency is on the order of nanoseconds — a difference of roughly 1000x. This means that once frequent page swapping (thrashing) occurs, system performance degrades catastrophically rather than linearly. For data science workloads, a typical Pandas DataFrame operation might create multiple copies of data in memory — a 10GB dataset might require 30-40GB of peak memory during processing. Additionally, the Unified Memory Architecture (UMA) used in modern Apple Silicon chips means RAM simultaneously serves both CPU and GPU, making memory capacity even more directly impactful on AI inference tasks — if you don't have enough memory, the model simply cannot be loaded.
For data science workflows, the cumulative time wasted from stuttering and crashes caused by insufficient memory far exceeds the duration of a single training run.
NVMe SSD: The Invisible Foundation of Data Throughput
Faster NVMe SSDs deliver immediately noticeable results for workflows involving heavy data I/O. Dataset loading, model checkpoint saving, dependency installation, codebase indexing — speed improvements in these high-frequency operations accumulate into significant time savings every single day.
To understand why NVMe is so effective, you need to understand the evolution of storage interfaces. The traditional SATA interface was designed in the era of mechanical hard drives, with a maximum bandwidth of only ~600MB/s and using the AHCI protocol with a command queue depth of just 32. The NVMe (Non-Volatile Memory Express) protocol is an interface standard designed specifically for flash storage, running directly over the PCIe bus. Current mainstream PCIe 4.0 x4 lanes offer theoretical bandwidth of ~7GB/s with a command queue depth of up to 65,535. This means not only a leap in sequential read/write speeds but, more critically, massive improvements in random read/write performance and low queue depth response times — and the latter is precisely the most common I/O pattern in daily development: frequently reading many small files (like Python package dependencies, code index files) and randomly accessing different regions of large datasets. For the data pipelines common in machine learning workflows, storage bandwidth directly determines whether the GPU can be continuously "fed" with data.
Monitor Upgrades: The Pressure Relief Valve for Cognitive Load
A high-resolution large monitor, or a dual/multi-monitor setup, is an upgrade many developers agree they "can never go back from." Being able to simultaneously see code, documentation, terminal output, and results reduces the massive cognitive interruption caused by constant window switching. This improvement is difficult to measure with benchmarks but genuinely reduces daily mental burden.
Cognitive science research shows that human working memory capacity is extremely limited (typically only 4-7 information chunks can be held simultaneously), and every window switch breaks the current chain of thought, producing what's known as "context switching cost." A Microsoft Research study found that developers need an average of about 15-25 minutes to fully return to their previous deep work state after being interrupted. Multi-monitor setups effectively reduce this switching need by presenting information simultaneously within the field of view — essentially trading physical space for cognitive bandwidth. For AI developers, being able to simultaneously monitor training curves, reference formulas from papers, edit code, and observe terminal logs means the feedback latency across the entire experiment loop is dramatically reduced.
The Biggest Efficiency Upgrade Might Not Be Hardware at All
Restructuring Your Work Methods and Processes
The original poster mentioned "maybe just changing the way I work," which is perhaps the most profound insight in the entire discussion. No amount of hardware can compensate for an inefficient workflow.
This viewpoint aligns closely with the rise of MLOps (Machine Learning Operations) in recent years. MLOps borrows from the DevOps philosophy in software engineering — using automation, standardization, and continuous integration/deployment to improve delivery efficiency — and applies it to the full lifecycle management of machine learning. In Google's MLOps maturity model published in 2020, they noted that most teams are at Level 0 (manual, fully human-operated processes), where non-reproducible experiments and fully manual deployments consume far more time than model training itself. Evolving from Level 0 to Level 1 (pipeline automation) often delivers greater efficiency gains than any single hardware upgrade. This also explains why the adoption of tools like DVC (Data Version Control), MLflow (experiment tracking), and Weights & Biases is reshaping the productivity landscape for AI developers.
What truly brings transformative change are often these "zero-cost" or "low-cost" changes:
- Automating repetitive tasks: Replace manual operations with scripts; build reproducible experiment pipelines.
- Environment standardization: Use Docker, conda, or virtual environments to permanently eliminate the "it works on my machine" nightmare.
- Hotkey and toolchain optimization: Master editor shortcuts and terminal multiplexing tools (like tmux); small savings compound over time.
- Leveraging cloud and remote compute: Don't fixate on owning top-tier hardware locally — renting cloud GPUs on-demand is often more flexible and economical.
Network Optimization: The Hidden Necessity of the Distributed Development Era
For workflows that rely on remote servers, cloud resources, or team collaboration, the value of network speed and stability is chronically underestimated. Slow or unstable connections turn remote development, large file transfers, and data synchronization into nightmares. A single network upgrade delivering a smooth experience may far outweigh a new graphics card.
Network performance has two core metrics that are often confused: bandwidth and latency. Bandwidth determines how much data can be transferred per unit of time (analogous to how wide a pipe is), while latency determines how long each data packet takes from sending to receiving a response (analogous to how long the pipe is). For interactive operations in remote development (like SSH terminal operations, real-time completion in remote IDEs), latency has a far greater impact than bandwidth — even with gigabit bandwidth, 200ms of latency creates a noticeable lag on every keystroke. In distributed training scenarios, multiple GPUs/nodes need to frequently synchronize gradient information, and communication overhead can account for 30%-50% of total training time, making both network bandwidth and latency critical bottlenecks simultaneously. This is why NVIDIA developed high-speed interconnect technologies like InfiniBand and NVLink, and why data centers invest as much in network topology optimization as they do in GPUs themselves. For individual developers, a stable low-latency network connection combined with a sensible data caching strategy can make remote development feel nearly identical to local work.
Practical Efficiency Tips for AI Developers
The biggest takeaway from this discussion is: Before spending money on upgrades, diagnose where the real bottleneck lies.
- Observe your actual workflow: Spend a few days tracking where your time actually goes. Is it waiting for training, or waiting for loading, debugging, and environment configuration?
- Prioritize high-frequency pain points: The small stutters you encounter every single day accumulate to a cost far exceeding an occasional long-running task.
- Prioritize soft upgrades: Changing work habits and optimizing toolchains costs very little but can yield the highest returns.
- Be rational about GPU investments: A big GPU is only the optimal solution when compute is genuinely the bottleneck holding you back.
Tech communities easily fall into the trap of "spec obsession," chasing more VRAM and more CUDA cores. But truly efficient developers understand that workflow smoothness is a systems engineering challenge — any single weak link can drag down the whole system. Sometimes, the investment that changes everything might just be a cheap stick of RAM, or simply a free change in habits.
Key Takeaways
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.