The Truth Behind AI Benchmark Leaderboards: Real-World Performance Is the True Moat

AI benchmark scores reflect test-taking skill, not real-world capability — product data flywheels are the true moat.
AI benchmark leaderboards are increasingly gamed through targeted training and data contamination, making high scores poor proxies for real-world performance. Real users send messy, ambiguous inputs that expose model robustness failures invisible to clean test sets. The true competitive moat lies in product data flywheels powered by RLHF, where large user bases generate irreplaceable real-world feedback that continuously improves model quality.
The "Teaching to the Test" Trap in AI Benchmarks
The large language model space is caught in an arms race over leaderboard rankings. Vendors fight tooth and nail over fractions of a percentage point, as if a slight lead on a benchmark signals absolute technical superiority. But this obsession is, at its core, a form of self-deception.
The root of the problem lies in the benchmark evaluation mechanism itself. Today's LLM evaluation pipelines typically provide models with complete questions and explicit conditions, then conduct targeted training on specific test sets. Getting a high score this way isn't particularly difficult — the logic is all too familiar to anyone who has gone through a test-oriented education system. Drilling practice problems, predicting exam content, targeted preparation — all of it produces an impressive scorecard that may not reflect genuine capability.
Hiding beneath this is an even deeper technical problem: Data Contamination. When a model's training data contains questions from the test set — or highly similar content — the model is essentially taking an exam it has already seen the answers to.
Data contamination arises because vast amounts of publicly available academic question banks, competition problems, and answer keys get swept into pretraining corpora, which overlap heavily with mainstream benchmarks like MMLU, HumanEval, and GSM8K. Researchers using n-gram overlap detection and Membership Inference Attacks have confirmed widespread contamination across multiple leading models. Notably, even unintentional contamination systematically overstates a model's true generalization ability — the model hasn't learned problem-solving logic; it has learned a surface-level mapping from questions to answers. Multiple academic studies have shown that a significant portion of the high scores achieved by models like GPT-4 and LLaMA on these classic benchmarks can be attributed to overlap between training and test sets. This casts serious doubt on the credibility of these widely cited benchmarks — yet the issue is rarely acknowledged at vendor launch events.
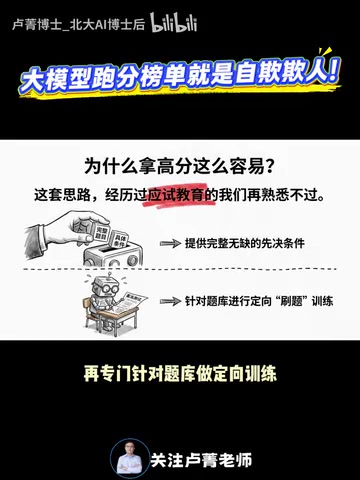
In other words, benchmark leaderboards measure a model's ability to "take tests," not its ability to solve real problems. As the entire industry optimizes for "test-taking skills," the practical value of these rankings is being steadily eroded.
Real Users Don't Follow the Script
A top-scoring student in the lab immediately runs into trouble once deployed in a real application. The key reason is the enormous gap between actual users and standardized test sets.
Real users don't ask questions in neat, standard formats. They send fragmented, poorly structured, even ambiguous messages — and they follow up repeatedly or change their requirements mid-conversation. This kind of "messy" input is precisely what's most absent from evaluation sets.

A model that excels on LLM benchmarks can stumble on even basic questions when faced with this kind of open-ended, underspecified input — because it never truly learned how to understand a user's real intent when information is incomplete and phrasing is irregular.
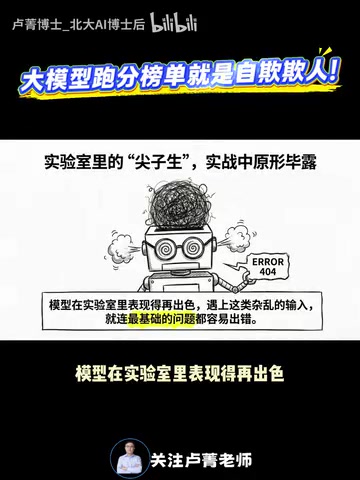
These are exactly the blind spots that benchmark tests can never surface. The underlying issue is a lack of model robustness. Robustness refers to a model's ability to maintain stable output quality when inputs contain noise, ambiguity, or distribution shifts.
From a technical standpoint, there is an "Out-of-Distribution (OOD) Generalization" gap between standard benchmarks and real-world scenarios: test sets represent a controlled, cleaned input distribution, while real user inputs constitute a fundamentally different distribution. Deep neural networks naturally tend to overfit to their training distribution, and their ability to handle OOD samples often degrades significantly. Typos, semantic ambiguity, code-switching, and conflicting instructions in real user input are all classic OOD cases. Research shows that two models with similar scores on clean test sets can diverge dramatically in performance when faced with noisy, real-world inputs. Leaderboards only measure how a model performs on "clean data" — they cannot reflect robustness in the "noisy environments" of the real world. And it's the latter that ultimately determines the quality of the user experience.
Product Data Is the True Moat
So what is the real competitive moat in the second half of the AI race? The answer isn't leaderboard gaming — it's owning real product data pipelines.
The logic chain is straightforward: products with massive user bases collect an enormous variety of real-world queries and feedback; this frontline data continuously feeds back into the model through correction mechanisms; the model iterates round after round, closing gaps and improving real-world performance. This is the virtuous cycle of the Data Flywheel effect.
The data flywheel's technical mechanism is especially pronounced within the Reinforcement Learning from Human Feedback (RLHF) framework. The core RLHF pipeline has three stages: first, Supervised Fine-Tuning (SFT) establishes baseline conversational capability; next, human annotators rank different model outputs by preference, training a Reward Model to predict human preferences; finally, the language model's parameters are iteratively updated using the Proximal Policy Optimization (PPO) algorithm, guided by reward model scores, gradually aligning outputs with human expectations. User behaviors such as upvotes, corrections, retries, and rewrites are all implicit preference signals that continuously calibrate the model's output distribution. The larger the user base, the richer the real interaction data collected, the more accurate the reward model, the more precise the iteration, the better the product experience — which in turn attracts more users. This positive reinforcement loop is precisely why both OpenAI's ChatGPT and Google's Gemini have publicly acknowledged that user feedback is a core training signal.

This also explains why the advantages of leading AI products become increasingly difficult to challenge over time. Technical architectures can be replicated and parameter counts can be matched, but the behavioral data from real users, the feedback loop, and the product refinement built up over time cannot be fast-tracked through benchmark optimization.
The Barrier to Entry for the Data Flywheel
The moat formed by real product data is essentially a compound barrier of "time × scale." New entrants, even with equivalent compute and algorithms, lack a sufficiently large real user base to continuously feed the model. This inherent deficit cannot be compensated with short-term capital investment — data flywheels require time to accumulate, and time is precisely what late movers lack most.
More critically, what a data flywheel accumulates is not general-purpose text, but high-value interaction data specific to a given product context: users' genuine task intentions, error patterns from failure cases, and contextual dependencies across multi-turn conversations. This type of data carries far higher information density than generic text scraped from the internet. Its scarcity and irreproducibility together form the truly insurmountable technical barrier in the LLM competitive landscape.
The Shift from Benchmark Scores to User Experience
For everyday users and developers, this means you shouldn't blindly trust leaderboard rankings when evaluating LLMs. More reliable criteria are a model's actual performance within your own workflows: Can it understand vague requirements? Can it maintain contextual consistency across multi-turn follow-ups? Can it reliably handle non-standard inputs? These are the core dimensions that determine real productivity.
A practical evaluation approach is to build a "personal test set" — compile the real tasks you encounter in your day-to-day work into a fixed set of test cases, and run side-by-side comparisons across different models during selection. This kind of workflow-anchored evaluation is far more targeted than referencing third-party leaderboards, because the relative importance of different model capabilities varies enormously across professions and use cases — no single leaderboard can capture every user's actual needs.
Closing Thoughts
AI benchmark leaderboards aren't entirely meaningless — they still offer some reference value along specific dimensions. But treating them as the sole measure of a model's quality, or engaging in targeted optimization to gain a few percentage points, is fundamentally misguided.
In the second half of the AI race, the deciding factor has shifted from "who scores higher" to "who can actually solve user problems." Those who control real data pipelines and have built closed-loop feedback and iteration systems are the ones with sustainable competitive advantage.
Now that you've read this — which model comes to mind first as one that ranks high on benchmarks but disappoints in real-world use?
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.