This Week in AI: Claude Removes Limits, GPT-6.1, Qwen Comes to Apple

This week, leading AI players shifted from model races to combined competition over task cost, system entry points, and ecosystem positioning.
Over the past week, OpenAI, Google, Anthropic, and Alibaba released a dense wave of updates. OpenAI launched GPT-6.1 Terra for computer operation, claiming the same task costs about one-ninth of Opus 5.5, and disclosed three research results pending external verification. Google released Gemini 4 Argon and Carbon within two weeks, with the latter topping the intelligence leaderboard at 59 points, and for the first time sent a TPU into space to run inference. Anthropic renamed Claude Max 20X to Ultra and removed the 5-hour limit, prompting OpenAI to double Codex Pro and enterprise premium usage limits. Alibaba's Qwen is being integrated into Apple Intelligence, with a developer beta planned for November 4 and an official rollout in December. On the open-source and hardware side, MiniMax H3 Flex compressed sampling to 6 steps, and BAAI released Go3 and Lingqu OS. Anthropic also disclosed that a research model found vulnerabilities across five major platforms and chained them into 5 executable attack chains. Overall, the focus of competition is shifting toward task execution cost, system-level entry points, and developer quotas.
This Week in AI: From Model Races to Ecosystem Positioning
Over the past week, the pace in the AI field has clearly accelerated. OpenAI, Google, Anthropic, and Alibaba have all rolled out major updates in succession, covering dimensions from model capabilities and product pricing to device entry points and space computing. According to a roundup by a Bilibili creator, these changes are not isolated events but point to the same trend: leading players are shifting from pure model competition toward a combined competition over task execution, ecosystem lock-in, and cost control.
OpenAI: GPT-6.1 Terra Focuses on Computer Operation, Research Capabilities Also Revealed
This week, OpenAI released GPT-6.1 Terra, whose core selling point is helping users operate computers. According to the official statement, completing the same task costs about one-ninth of what Opus 5.5 costs. If this cost gap holds true, it means that in scenarios such as automated office work and browser operation, the economics of model calls will improve by an order of magnitude.
OpenAI President Greg Brockman said that using this model to operate a computer is now faster than doing it himself. This statement carries a certain promotional tone, but it also indirectly shows that the model's fluency in executing task chains has improved.
Beyond product updates, OpenAI also disclosed that its models delivered three scientific research results this week, one of which proved a conjecture that had puzzled mathematicians for decades and incidentally solved the famous Kakeya conjecture. OpenAI has now invited external experts to verify the results. Scientific research capability is a manifestation of a model's deep reasoning ability, but external verification has not yet been completed, so the conclusions should still be viewed with caution.
A model "operating a computer" falls under the direction of Computer Use Agents: the model understands the interface through screenshots and then generates actions such as mouse clicks and keyboard input to complete multi-step tasks in browsers or desktop applications. Compared with traditional API calls, such tasks place higher demands on visual grounding, state tracking, and error recovery, and are more prone to cascading failures from a single misstep. Therefore, evaluating such models cannot rely only on single-step accuracy; it must also consider the completion rate and cost of long task chains. The "one-ninth the cost" mentioned in the article usually refers to the inference cost per task at the same task completion rate, rather than the token unit price alone; actual economics will fluctuate with task complexity, number of retries, and human takeover rate.
Google: Two Gemini 4 Releases in a Row, TPU in Space
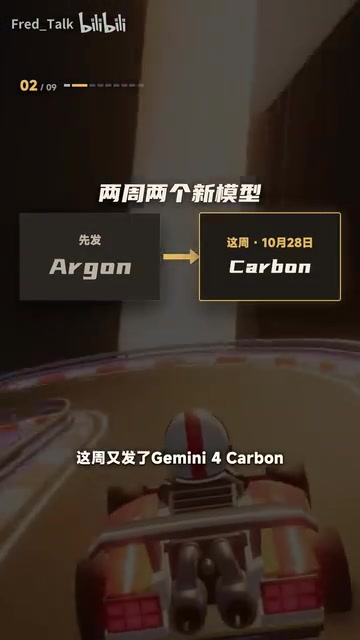
Google released two models within two weeks: first Gemini 4 Argon, and this week Gemini 4 Carbon. According to the intelligence leaderboard data from Artificial Analysis cited by the Bilibili creator, Gemini 4 Carbon directly topped the list with 59 points. In vulnerability-finding tests, it achieved a score of 88.2%. However, ordinary users cannot use it yet; Google is first opening it in batches to cybersecurity teams, which indicates that the model's capability direction leans more toward security research and high-risk scenarios.
Even more noteworthy are the moves at the hardware level. Google sent a TPU into space on a satellite and, for the first time, successfully ran model inference in space; the first reply received on the ground was a poem. Space computing is currently more of a technical validation, but it provides a reference sample for future in-orbit data processing and low-latency inference.
TPU (Tensor Processing Unit) is Google's self-developed dedicated AI accelerator chip, mainly used for matrix-computation-intensive model training and inference. Sending a TPU into space and running inference successfully is technically difficult not because of the computing power itself, but because of the space environment's radiation, heat dissipation, power supply, and remote operations: cosmic rays can cause bit flips, and a satellite's power and thermal budgets are extremely limited. The value of in-orbit inference lies in reducing the bandwidth pressure and latency of downlinking raw data; for example, remote sensing images can be filtered or initially identified on the satellite, with only key results transmitted back. However, this is still validation in nature, and there is still a distance to go before large-scale in-orbit computing centers.
The Quota Game Between Anthropic and OpenAI
Anthropic renamed Claude's Max 20X plan to Ultra, kept the price unchanged, and directly removed the 5-hour limit for Ultra users. For developers who use Claude heavily, this is a tangible improvement in experience, as long sessions are no longer interrupted by a window.
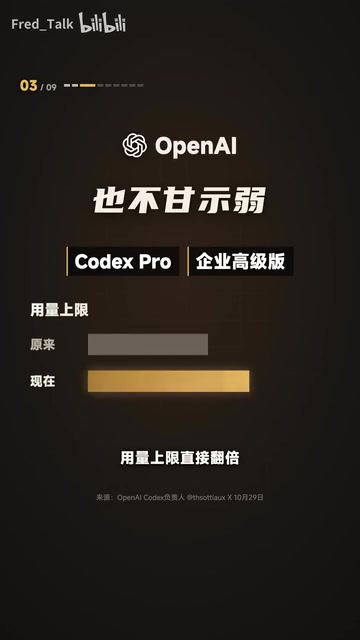
OpenAI responded immediately by directly doubling the usage limits for Codex Pro and enterprise premium versions. Competition between the two in coding assistance tools has extended from model capabilities to quota policy, and users are the direct beneficiaries of this round of maneuvering.
Qwen Comes to Apple Intelligence, Domestic Models Enter System-Level Entry Points
Alibaba announced that Qwen is being integrated into Apple Intelligence, with Siri, Writing Tools, and Visual Intelligence all able to call Qwen. According to the plan, a developer beta will launch first on November 4, followed by an official rollout in December.
The significance of this step is not in model parameters but in the entry point. System-level integration means Qwen can be invoked without users actively opening a standalone app, significantly expanding reach and usage frequency. For domestic large-model vendors, this is a key battle for ecosystem positioning.
Open Source and Hardware: MiniMax, BAAI, and Google Each Make Moves
On the open-source side, Pika continued training on MiniMax H3 and open-sourced H3 Flex sampling, compressing the number of sampling steps from 50 to 6. The official statement says that a 15-second video with music can be generated in as fast as 7 seconds. The speed bottleneck in video generation is being gradually compressed, which has a direct impact on content production workflows.
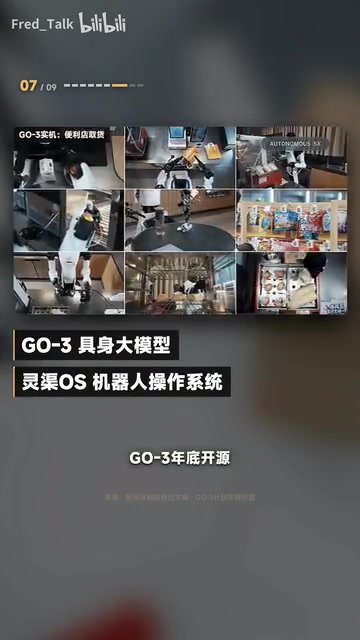
At its Innovation Day, BAAI released the Go3 large model for giant sounds and the Lingqu OS robot operating system; Go3 is planned to be open-sourced by the end of the year. The release of a robot operating system shows that domestic institutions have also begun to lay out the foundational software layer for embodied intelligence.
Anthropic's Security Research: Five Executable Attack Chains
Anthropic disclosed that an internal Claude research model found vulnerabilities in Chrome, Safari, Android, Windows, and Linux and chained them into 5 attack chains that could actually run. All related vulnerabilities have been fixed.
The value of this information lies in the fact that it demonstrates the model's actual output capability in security audit scenarios. Vulnerability discovery moving from assisted hints to the construction of executable attack chains shows that the model's depth of understanding of complex systems is increasing, while also reminding defenders that they need to accelerate their response pace.
"Executable attack chain" refers to chaining multiple independent vulnerabilities in exploitation order to form a complete path from initial entry to final control or data theft. A single vulnerability may only cause information leakage or privilege escalation, but when combined, it can break out of a sandbox and bypass mitigation mechanisms, greatly amplifying the harm. Such work usually follows a responsible disclosure process of "discovery—verification—fix—disclosure," and vendors only make details public after patches are released. A model being able to autonomously complete vulnerability discovery and build attack chains shows that it has practical value in code auditing and system reasoning, but it also brings dual-use risks: the same capability could be used for attacks. Therefore, the industry generally emphasizes access control, usage auditing, and model behavior monitoring.
This Week's Observations
Looking at the above events together, several main lines are relatively clear. Model capabilities are still iterating rapidly, but the focus of competition is shifting toward task execution cost, system-level entry points, and developer quotas. OpenAI is entering computer operation with a cost advantage, Google is using security scenarios and space computing for differentiated validation, Anthropic is consolidating developer stickiness by removing limits, and Alibaba is expanding reach through Apple's ecosystem. Worth watching next week are the actual performance of the Qwen developer beta and the progress of external verification of OpenAI's scientific research results.
Related articles

AI Can Read Neural Network Weights Directly: Do Models Already Exceed Expectations?
A Reddit developer experiment shows language models can directly read neural network weights and infer their function. Astra, Opus 5.5, and Muse Spark 1.3 all passed the test, sparking discussion on model generalization and training sources.

India's Microdrama Market Explodes: EloElo Secures $80M Investment from NBCUniversal
EloElo secures $80M from NBCUniversal to boost StoryTV, its microdrama platform with over 33M monthly active users, as India's microdrama market draws global capital.

Acoustic Detection of Multi-Rotor UAVs: Fusing Handcrafted Features with Pre-Trained Embeddings
Study reveals data leakage from random splits in UAV acoustic detection, proposes source-disjoint protocol with stacked ensemble of handcrafted features and YAMNet embeddings, achieving 95.29% accuracy for low-cost drone detection.