Training a Video Generation Model on a Laptop: A Hands-On Experience and Bottleneck Analysis

A developer honestly documents training a video generation model on a laptop, including plateaus and paths forward.
This article chronicles a developer's end-to-end experiment building and training a video generation model from scratch on a personal gaming laptop. Using a flow matching-based spatiotemporal UNet with ~20.8M parameters, trained on ~6,000 Tom and Jerry clips, the goal was to generate 16-frame, 64×64 videos. Results revealed a clear loss plateau — MSE dropped only 0.006 over 130 epochs and later rebounded — with outputs capturing only color and vague layouts but no clear character detail. The article analyzes root bottlenecks including model scale, resolution limits, and MSE loss shortcomings, and proposes improvements such as LPIPS perceptual loss, cosine annealing, and stronger attention mechanisms.
Building a Video Generation Model from Scratch
A developer shared on Reddit their complete experience training a video generation model from scratch on a personal laptop. This case demonstrates the possibility of exploring cutting-edge AI technology on small-scale hardware, while also revealing the typical challenges of model training in resource-constrained environments.
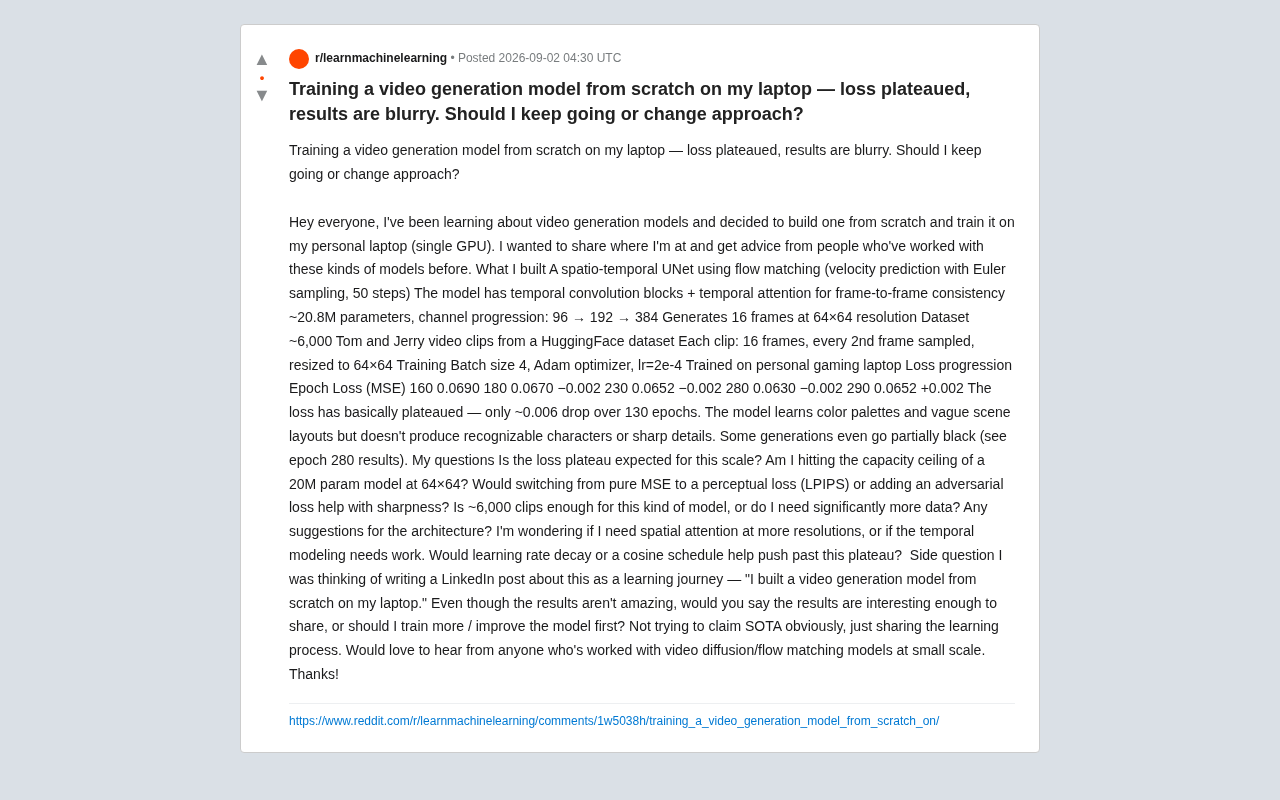
The developer built a spatiotemporal UNet architecture based on flow matching, using velocity prediction and Euler sampling (50 steps). The model contains approximately 20.8 million parameters, with channel dimensions progressing as 96→192→384, and supports generating 16-frame video clips at 64×64 resolution. The model design incorporates temporal convolution blocks and temporal attention mechanisms to enhance inter-frame consistency.
Training Dataset and Configuration
The training data came from a Tom and Jerry video dataset on HuggingFace, containing approximately 6,000 video clips. Each clip had 16 frames extracted with every other frame sampled, resized to 64×64 resolution. This data preparation strategy reduces computational overhead while preserving basic temporal information.
The training configuration used a batch size of 4, the Adam optimizer, and a learning rate of 2e-4. The entire training process was completed on a single GPU in a gaming laptop — a testament to the creativity of individual developers working under resource constraints.
Training Results and Performance Bottleneck Analysis
The training progress showed clear plateau characteristics. From epoch 160 to epoch 290, MSE loss dropped from 0.0690 to 0.0652 — a decrease of only about 0.006 over 130 epochs. More notably, at epoch 290, the loss rebounded (+0.002), suggesting the model may have approached the performance ceiling of its current configuration.
The generated outputs can capture color tone and vague scene layouts, but fail to produce clear character details. Some outputs even exhibit localized black-screen artifacts (as seen in the epoch 280 outputs). These phenomena point to several potential bottlenecks:
- Insufficient model scale: 20.8 million parameters may be too small for video generation tasks
- Resolution constraints: The low 64×64 resolution severely limits the model's ability to express detail
- Limited loss function: A pure MSE loss struggles to capture the visual quality perceived by the human eye
Optimization Directions for Video Generation Models
Several improvement approaches can be explored across multiple dimensions to address the current challenges.
Improving the Loss Function
Introducing perceptual loss (LPIPS) or adversarial loss could significantly improve generation quality. MSE tends to produce blurry results to minimize pixel-level error, whereas perceptual loss better captures visual similarity as humans perceive it.
Adjusting Training Strategy
Learning rate scheduling strategies such as cosine annealing may help the model break through the loss plateau and avoid getting stuck in local optima.
Scaling Architecture and Data
On the architecture side, consider introducing spatial attention mechanisms at more resolution levels, or strengthening the temporal modeling modules. In terms of data volume, 6,000 clips may be somewhat insufficient for a video generation model, especially given the high-dimensional complexity of video data.
The Value of Learning from Imperfection
Interestingly, the developer proposed sharing this as a learning journey on LinkedIn. Even when results fall short of ideal, the spirit of exploration and the transparent presentation of challenges carry their own value — they showcase the real process of AI research, rather than simply showcasing success stories. For the learning community, failed experiments and improvement ideas are often more instructive than polished results.
Related articles

LLM Application Development: A High-Paying Career Guide for Ordinary People
LLM application development offers fresh graduates up to 35K/month, with SP offers reaching 600K. This article explains the core skills, how to break in, and how ordinary people can seize AI opportunities through learning by doing.

Say Goodbye to AI Influencer Faces: A Complete Guide to Creating Visual Assets for AI Comic Dramas from Scratch
Bilibili creator shares a full workflow for zero-basics AI comic drama visual assets: use Doubao Work skills with script-first, visual references, and real-person texture to escape AI influencer faces, then lock character and scene consistency with asset sheet layouts, weapon detail images, scene nine-grids, and cinematic color palettes.

The AI Production Pipeline Behind Great Videos: From Research to Agent Validation
AI video production isn't just a model race. This article breaks down a transferable four-step pipeline: researching professional workflows, organizing a skill checklist, configuring agents, and experimental validation—and explains how general-purpose LLMs like DeepSeek can replace paid tools to run the entire process.