Triton Kernel Matches bitsandbytes: Why Both Lose to Math

A hand-written Triton W4 kernel matches bitsandbytes on RTX 3060, but bf16 wins on bandwidth efficiency.
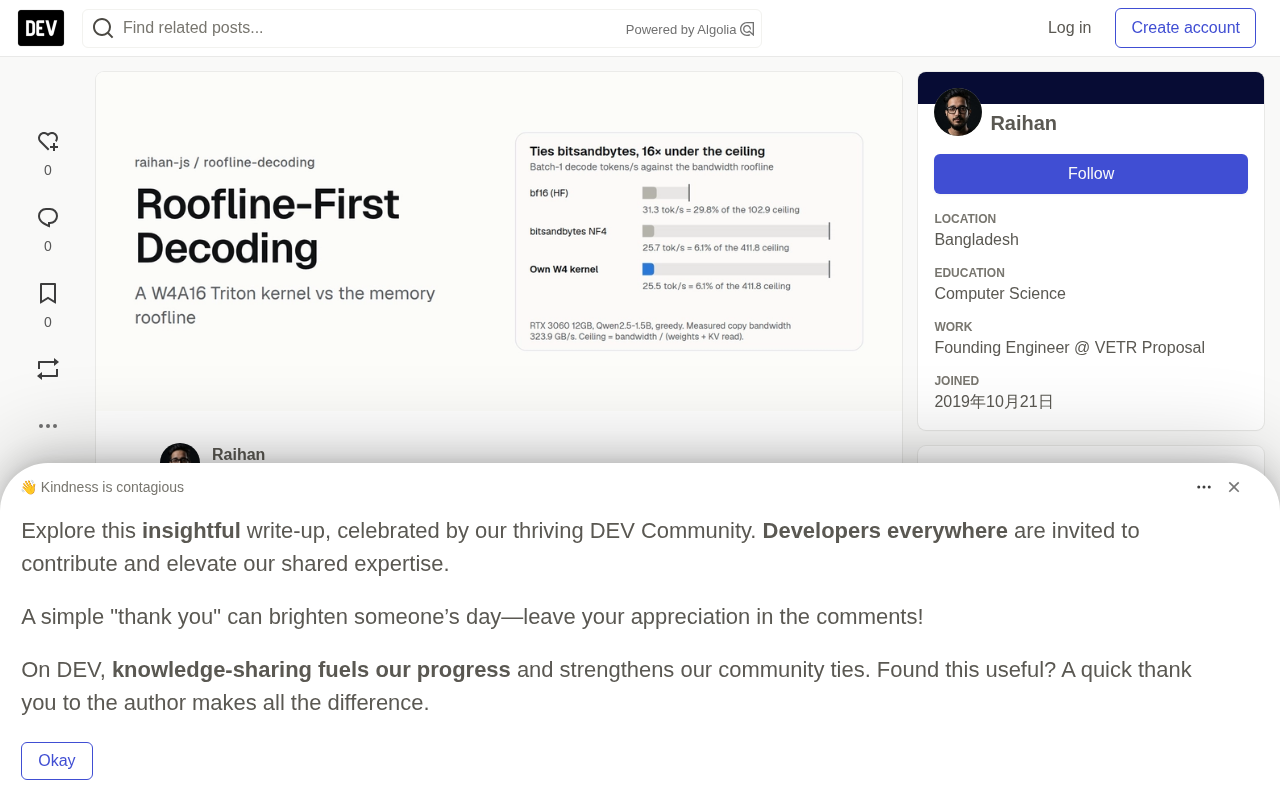
A developer hand-wrote a fused W4A16 GEMV kernel in Triton for batch-1 decoding on an RTX 3060, matching bitsandbytes NF4 at 25.5 tok/s vs. 25.7 tok/s with lower perplexity (15.76 vs. 18.98). But the bf16 baseline won at 31.3 tok/s, reaching 29.8% of roofline, while quantized schemes reached only 6.1%. The project used a roofline methodology to measure memory bandwidth first (323.9 GB/s), calculate theoretical ceilings, and localize gaps layer by layer. The main bottleneck was the scalar nibble unpacking loop, and the author also honestly reported that the gap is 9.6x rather than 16x when measured by actual bytes moved.
Triton Kernel Matches bitsandbytes: Why Both Lose to Math
On an RTX 3060, a developer hand-wrote a fused W4A16 GEMV kernel in Triton for batch-1 decoding, matching the speed of bitsandbytes' NF4 quantization scheme—both landing around 25.5 tok/s. Yet the bf16 baseline easily won with a measured 31.3 tok/s, reaching only 29.8% of the theoretical roofline. This result seems counterintuitive: quantization clearly reduces weight size, so why is it slower? The answer lies in the three-way tug-of-war between memory bandwidth, dequantization overhead, and kernel engineering.
Roofline First: Calculate the Ceiling Before Writing Code
The project's core methodology is "measure first, write code, then explain the gap." The developer started by benchmarking the RTX 3060's actual memory bandwidth with a torch copy benchmark: 323.9 GB/s (vs. the 360 GB/s spec, so about 90% in practice). From this, the roofline ceiling for batch-1 decoding can be directly computed—each token requires reading all weights once, plus reading the 2048-token KV-cache.
| Model | dtype | Weights (GB) | Theoretical Ceiling (tok/s) |
|---|---|---|---|
| Qwen2.5-1.5B | bf16 | 3.087 | 102.9 |
| Qwen2.5-1.5B | int4 | 0.772 | 411.8 |
| ORCH-Fusion | bf16 | 0.550 | 539.7 |
| ORCH-Fusion | int4 | 0.137 | 2158.8 |
Two notable details: Qwen2.5's tied embedding (151,936 tokens) accounts for about 15% of the weights; ORCH-Fusion's matrices are extremely small, so launch overhead may become the dominant factor. This means int4 theoretically has a ceiling of 411.8 tok/s, but the measured value is only 25.5 tok/s—a roughly 16x gap. That gap itself is the point of the project.
The Roofline model is a performance analysis framework proposed by researchers at Berkeley to determine whether a kernel is limited by compute throughput or memory bandwidth on given hardware. Its x-axis is arithmetic intensity—the number of computation operations performed per byte of data read; its y-axis is achievable performance (FLOPS or tok/s). Hardware exhibits a "roof" shape: the low-arithmetic-intensity region is a sloped line (the memory-bandwidth-limited region), the high-arithmetic-intensity region is a horizontal line (the compute-peak-limited region), and the intersection is called the "ridge point." For autoregressive inference like batch-1 decoding, each generated token requires reading all weights from VRAM once while performing only a tiny amount of matrix multiply-add, so arithmetic intensity is inherently extremely low—meaning it inevitably falls on the sloped side, i.e., the memory-bandwidth-bound region. This is why the article can directly compute the theoretical token ceiling by multiplying measured bandwidth by weight bytes: in the bandwidth-limited region, the performance ceiling is entirely determined by "bytes that must be moved per token," independent of GPU compute power.
Three Kernel Versions and Two Bugs That Tripped Things Up
The developer implemented three progressively evolving Triton kernels, all validated for correctness against the PyTorch reference implementation on real matrix shapes:
- v1 (dequantize first, then matmul): materializes fp16 then calls torch matmul, demonstrating the cost of extra memory traversal—3 to 7 times slower than v2.
- v2 (fused): a single kernel, dequantizing on the fly, without materializing intermediate results.
- v3 (split-K + tuning): autotuned tiles, using split-K parallelism for large matrices.
A counterintuitive finding was that v3 was not faster than v2 on microbenchmarks across five shapes (v2 was 1.0 to 1.4 times faster), yet end-to-end decoding used v3. The fused kernel itself was up to 5.5 times faster than the pre-dequantized reference on wide MLP-gate shapes, indicating that swapping v2 into the decode loop is the obvious next experiment.
Two "load-bearing" bugs were encountered along the way. The first was missing the +8 zero-point during packing, which corrupted all weights and was caught in code review before the first GPU run. The second was more subtle: a conflict between @triton.autotune and atomic_add—autotune would time all configurations about 500 times using the same output buffer, while the split-K kernel accumulated results into that buffer, causing about 500 stale copies to pile up. The first-tuned configuration was effectively benchmarked on garbage data. The fix was explicit tuning: allocate a fresh buffer for each trial and cache the winning configuration.
split-K is a parallelization strategy for matrix multiplication. Standard GEMM splits the output matrix into tiles by rows and columns, with each thread block responsible for all accumulation for one tile. But when one dimension of the matrix is extremely small (e.g., in GEMV where the output dimension is small and the K dimension is long), the number of tiles available to split is insufficient to fill all SMs on the GPU, leaving many compute units idle. split-K instead slices the reduction dimension K into several segments, letting multiple thread blocks each compute partial sums, then merging the partial sums via atomic_add or a second-stage reduction. The cost is write conflicts and extra atomic operation overhead, which can actually slow things down when K is not long enough—this explains the counterintuitive phenomenon in the article where v3 loses to v2 on microbenchmarks across multiple shapes: for small matrices, the parallelism gains from split-K do not outweigh the atomic accumulation and scheduling overhead.
@triton.autotune is an automatic tuning decorator provided by Triton: it actually runs and times multiple compilation configurations of the same kernel (such as BLOCK_SIZE, num_warps, num_stages), then caches and selects the fastest configuration. Its default behavior reuses the same input/output buffers for repeated timing to ensure fairness. But when it is not known in advance which configuration is correct, and the kernel itself performs accumulating writes to the buffer (such as split-K accumulating with atomic_add), that reused buffer will keep accumulating intermediate results from each configuration, causing subsequent timings to read polluted data. The fix is therefore to change "autotune" to "explicit tuning": allocate a fresh buffer for each trial, benchmark separately after running, and then cache the winning configuration.
Measured Numbers: Matching bnb, but Both Lose to bf16
| Scheme | tok/s | Probe ppl | GB/s | % of roofline |
|---|---|---|---|---|
| bf16 (HF) | 31.3 | 12.91 | 96.6 | 29.8% |
| bitsandbytes NF4 | 25.7 | 18.98 | 19.8 | 6.1% |
| Custom W4 (v3) | 25.5 | 15.76 | 19.7 | 6.1% |
The custom kernel matches bitsandbytes in speed, with better perplexity (15.76 vs. 18.98). But both lose to bf16—which, at 29.8% of roofline, becomes the best engineering path overall. This result shows that in batch-1 decoding, the bandwidth saved by weight quantization is offset by dequantization compute overhead and kernel efficiency losses.
Why Marlin Is Still Faster, and the Honesty of 6%
Layer-by-layer breakdown shows: GEMV time totals about 25 ms, while the full decode step is about 39 ms, with the rest being attention, norm, sampling, and Python scheduling. Within GEMV time, the scalar nibble unpacking loop (shift, mask, subtract, scale for each element) dominates the overhead—about 6 ALU operations per MAC with no pipelining. Marlin hides this using async copy, software pipelining, and early bit staging. The developer tried rewriting with tl.dot, and the result was 4 to 7 times slower—the cost of dequant-scatter into the dot tile exceeded the savings from dot, and this negative result was reported honestly.
There is also a fairer denominator regarding the 6.1% figure: the 412 tok/s int4 ceiling assumes all weights are int4, including the tied embedding/lm_head. In the replaced model, that matrix remains bf16, so each token actually reads 1.263 GB of weights (plus about 0.06 GB of KV cache). Based on bytes actually moved, 25.5 tok/s corresponds to about 34 GB/s, roughly 10% of measured bandwidth, and the model's own ceiling is about 245 tok/s—a gap of about 9.6x rather than 16x. Both accounting conventions are written into the results file; the headline 6.1% figure is relative to the all-int4 ideal.
Marlin is a highly optimized int4/int8 weight-quantized inference kernel in the vLLM ecosystem, designed specifically for LLM decoding at very small batch sizes (including batch-1). Its core trick is to overlap dequantization and matrix multiplication at the pipeline level: it prefetches weights from VRAM to on-chip memory via cp.async asynchronous copies, uses software pipelining to parallelize the three stages of "fetch weights—unpack—multiply-add," and completes bit staging before data enters the compute units (expanding packed 4-bit nibbles into a multiply-ready form ahead of time). In this way, the scalar ALU operations of nibble unpacking—which dominate naive kernels—are hidden behind memory latency, and the effective bottleneck returns to bandwidth itself. This is exactly the gap between the custom kernel in the article and Marlin—the algorithms are the same, but the maturity of the engineering implementation differs. The author tried replacing the scalar loop with tl.dot but it was 4–7 times slower, showing that for extremely low-arithmetic-intensity shapes like GEMV, the cost of scattering dequantized values into the dot tile exceeds the benefit brought by tensor cores.
Limitations and Next Steps
The author candidly lists the limitations: probe perplexity used only 4 sentences (high noise); bnb-quantized layers differ from the custom swap, so the ppl gap is directional rather than conclusive; Marlin could not compile (torch 2.13 / CUDA 13), and llama.cpp was not installed, so both lack comparisons; single-prompt timing, batch-1 only, greedy only. ORCH-Fusion end-to-end remains to be completed.
Next steps include: GPTQ-style calibration scales to narrow the ppl gap, wrapping the decode step in CUDA graphs to validate the launch-overhead hypothesis on ORCH shapes, and writing a dedicated checkpoint loader for ORCH-Fusion. The repository has 46 tests all green.
The value of this project is not in beating Marlin, but in using the roofline methodology to quantify every performance gap into something explainable—which is more educational than a pretty speedup number.
One-line Summary
A hand-written Triton W4 kernel matches bitsandbytes on an RTX 3060, but the bf16 baseline wins on bandwidth efficiency.
Paragraph Summary
A developer hand-wrote a fused W4A16 GEMV kernel in Triton for batch-1 decoding on an RTX 3060, matching bitsandbytes NF4 at 25.5 tok/s vs. 25.7 tok/s with lower perplexity (15.76 vs. 18.98). But the bf16 baseline won at 31.3 tok/s, reaching 29.8% of roofline, while the quantized schemes reached only 6.1%. The project used a roofline methodology to first measure memory bandwidth (323.9 GB/s), then calculate theoretical ceilings, and localize the gap layer by layer. The main bottleneck was the scalar nibble unpacking loop, at about 6 ALU operations per MAC with no pipelining; Marlin hides this overhead with async copies and software pipelining. The author also hit the autotune vs. atomic_add conflict and honestly reported two accounting conventions: the gap is 9.6x rather than 16x when calculated by bytes actually moved.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.