Turning a Classifier into a Chatbot: The Jev Experiment That Reveals the True Nature of AI Generation
A developer forced pure classifier Jev to generate text, proving generation is just continuous classification.
A developer used seven techniques — including presenting complete candidate replies, word tournaments, temperature tuning, and pruned vocabularies — to force Jev, a pure classifier, into producing coherent sentences. The core finding: models judge well but guess poorly, so showing full candidate outputs beats blind next-token prediction. One sentence cost up to 90 API calls, 6 cents, and 30 seconds. The same approach was explored with BERT back in 2019. The experiment's value isn't practical engineering, but in concretely demonstrating that text generation is fundamentally a series of classification choices over a vocabulary.
An AI model called Jev — whose homepage explicitly states "we are not a chatbot" — was coaxed into producing complete sentences through a series of clever techniques. This seemingly absurd experiment actually uncovers a technical truth many people overlook: generation is, at its core, just classification. This article breaks down the technical logic and insights from one developer's Jev tinkering session, shared on Bilibili and YouTube.
What Is Jev: A Classifier That "Isn't Allowed to Talk"
Jev's documentation is refreshingly blunt: it was not trained to generate text. If you force it to write, the results will be poor and "painfully slow." It does one thing only — give it a question and several options, and it picks one, telling you how confident it is.
In other words, Jev is a pure classifier, not a generative language model like ChatGPT. Its capability boundary is intentionally narrow: take a set of candidates as input, output a single choice with a confidence score.
The developer's goal was to do exactly the opposite — if every letter becomes a multiple-choice question, could that force it to "write"? The entire experiment revolves around one central question: can a model that only judges be turned into one that generates?
The architectural difference between a classifier and a generative language model is worth clarifying. A classifier maps input to one of a finite set of predefined categories, outputting a probability distribution over those categories, trained to maximize the probability of the correct class. Generative language models (like the GPT series), by contrast, predict at each step the probability distribution over an entire vocabulary — typically tens of thousands to over a hundred thousand tokens — and build output incrementally through autoregression. The fundamental difference is that a classifier's "candidate space" is fixed and closed, while a generative model's candidate space at each step is the full open vocabulary. Jev is designed as the former — it excels at comparative judgment among given options, not at "inventing" the next word from scratch. This design constraint is precisely what made this experiment possible.
First Attempt: Blindly Guessing the Next Letter Almost Always Fails
The most naïve approach: feed the current text to Jev, have it pick the next letter from the entire keyboard, append it, and ask again. The developer tried to get it to output "hello world." H came back at 91% confidence, E at 81% — and then it started outputting L infinitely, eventually producing something like "hell."
Where's the problem? Jev is blindly guessing the next letter. It can't see the complete result of its choice; it can only evaluate each character in isolation. And prediction isn't a classifier's strong suit.
The turning point came from a different approach: instead of guessing a single letter, present Jev with the complete reply that would result from each possible keystroke — letting it choose between HE, HF, HG, and so on as whole strings. With this change, Jev wrote "hello world" perfectly in just 13 API calls.
Core insight: Jev isn't good at guessing what comes next, but it's excellent at judging what it has already seen.
This is the pattern the entire experiment keeps validating — guessing is hopeless; judging is effective.
Seven Approaches: From Temperature Tuning to Real Tokens
When the developer vented about this on Hacker News, they discovered at least seven other people had built nearly the same thing around the same time — and one had even published a paper. So they went ahead and tested all seven implementations.
Temperature and Randomness
The first repository shuffled the option order before each call, preventing Jev from "sticking" to a preferred option, and introduced temperature perturbation to the probabilities — just like a normal LLM. At the lowest temperature, this "never-speaks" model wrote "I am an artificial being" (7 calls). Cranked up to 1, it "acted drunk"; at 2, it turned into a raving poet.
Temperature is a hyperparameter that controls the randomness of a language model's output, applied to the model's output logits (raw probability scores). Specifically, each class's logit is divided by temperature value T, then passed through softmax normalization to get the final probability distribution. When T < 1, the distribution becomes sharper — high-probability options gain a stronger advantage and output becomes more deterministic and conservative. When T > 1, the distribution flattens — probability differences between options shrink and output becomes more random and diverse, sometimes producing unexpected or semantically incoherent results — the "drunk" effect described here. Temperature was originally designed for generative models; applying it to a classifier's inference process is one of this experiment's key creative moves: by perturbing the probability preferences among options, it prevents the model from perpetually "sticking" to the same high-confidence letter, giving the output a more natural linguistic rhythm.
Give It a Real Keyboard
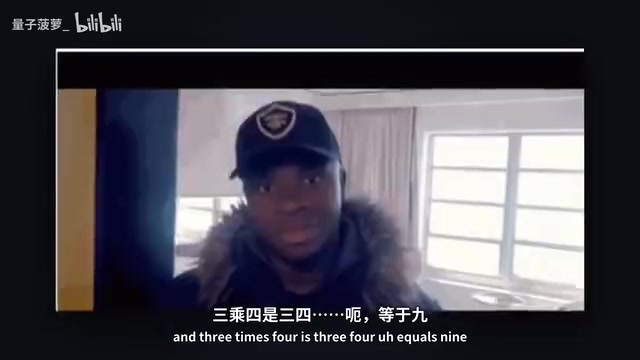
The second repository gave Jev a full keyboard, including a backspace key and a send key. It correctly answered "3×4=12" — but digging deeper revealed that before typing, it had run about 36 calls to hold a "tournament" among over eight thousand words to select an answer. Remove that cheat sheet, and 3×4 becomes "3 4 equals 9."
This exposed a cost problem: one answer cost roughly 40 API calls and half a cent, while the same response from Opus would be 40 times cheaper. The model advertised as "200× faster" turned out to be 40× more expensive at the task of randomly making things up.
Real Tokens and a Pruned Vocabulary
The third repository gave Jev actual GPT tokens — all one hundred thousand of them — but since Jev can only handle 255 at a time, it had to build a shortlist of candidates first. The correct token almost never made it onto the shortlist. The fourth repository took the opposite approach: limit options to a few hundred of the most common words, one word at a time. The result? It "actually started talking" — like someone learning English from refrigerator magnets.
Interestingly, when the developer removed "no," "nope," "not," and "never" from the vocabulary and asked whether the Earth is flat, it still found a forgotten negation word to express disagreement. When asked whether it should buy a meme coin, it responded that keeping money in a bank was better — even with its vocabulary tampered with, it was still more financially sound than many crypto Twitter users.
Judgment Is Its True Calling: Generation Is Classification
The fifth repository took the "judgment" path to its extreme. Jev never guesses anything — instead it picks several likely candidates from thousands of words, assembles them into hundreds of phrases, and then selects the one that "doesn't sound stupid" to repeat.
Asked "what happens after death," it answered "experts might know nothing about that" — which happens to be the standard answer from every AI lab when asked how their models actually work.
More compelling was the "judge yourself" test: Jev was asked to compare one of its own terrible jokes against a classic joke (about a scarecrow winning an award). In both orderings, it chose the classic joke with 99% confidence. The one thing it was truly designed to do — judge — it does mercilessly, even to itself.
This Isn't New: It Was Possible in 2019
The last repository, the one with a paper attached, is simply called Generation is Classification. It adds memory and a "commentator" that checks each response before sending. This was the first version capable of real conversation — but when asked the capital of France, it said "Berlin," the commentator flagged a grammar error and sent it anyway.
Half the comments under all these repos said: this isn't new. Any transformer since 2019 can do this, and there's even a paper called BERT has a Mouth, and It Must Speak. The developer ran the 2019 BERT implementation and got equally bad results — "three times four equals five," strawberries cost "$450."
This evidence is significant: turning a discriminative model into a generator is not magic — it's a technical path that has been explored before. It's slow, frequently wrong, and strangely confident about its mistakes.
BERT (Bidirectional Encoder Representations from Transformers) is a pretrained language model released by Google in 2018. It uses a discriminative rather than generative architecture — specifically, a bidirectional Transformer encoder pretrained through Masked Language Modeling (MLM), where random tokens in the input are masked and the model learns to predict them. This mechanism gives BERT a natural "fill-in-the-blank" capability that can theoretically be used for word-by-word text generation. The 2019 paper BERT has a Mouth, and It Must Speak systematized this idea: using iterative masking and filling to force BERT to generate coherent text. However, since BERT's training objective was never optimized for generating fluent sequences, its generation quality is generally low, with high factual error rates and an unusual degree of confidence in those errors — closely mirroring Jev's behavior in this experiment. This confirms that "forcing discriminative models to generate text" is a class of techniques with shared, fundamental limitations.
What the Experiment Means: Cost, Essence, and Limits
Across the whole experiment, producing a single normal sentence required 10 to 90 API calls, 1 to 6 cents, and 5 to 30 seconds. What you get is a slow, frequently wrong, and oddly confident "chatbot." From an engineering standpoint, this is completely impractical.
But its value lies in making an abstract concept concrete: the output of a generative model is also, fundamentally, a series of classification choices over a vast vocabulary. The reason a pure classifier like Jev can barely "speak" at all is that the boundary between generation and classification is far blurrier than product marketing would have you believe.
Finally, the developer stitched all the effective techniques together — using complete replies as options, word tournaments, and an end-stage judge — into a "Frankenstein" system and asked it: "What are you?" It first answered "I am AI." Pushed a little further, it burst out: "I am not a chatbot, I am a classifier."
A model whose homepage says "I am not a chatbot," spending an entire video insisting that it is — perhaps that's the most chatbot-like thing it could have done.
A note of caution: the content above comes from a single source (one developer's experimental writeup). The specific technical details and cost figures about Jev have not been cross-verified by third parties. Readers should treat this as an interesting technical exploration rather than a rigorous benchmark.
Related articles

ClaudeMem: An AI Agent Memory Layer That Lets Claude, ChatGPT, and Grok Share Memories
ClaudeMem provides shared memory across Claude, ChatGPT, GrokBot and other AI agents, solving context breaks in cross-model collaboration. This article breaks down its local-first architecture, installation, real-world workflows, and the creator's vision of a single orchestrator Bot.

OpenAI Codex CLI Practical Guide: The Open-Source AI Coding Agent in Your Terminal
OpenAI Codex CLI is an open-source AI coding agent that runs in your terminal. This guide covers its 2025 launch, 2026 desktop app, ChatGPT merger, and a three-step setup and workflow.

AI for Beginners Course Review: ChatGPT, Gemini, and AI Agents in Practice
A hands-on review of a complete beginner AI course covering ChatGPT, Gemini, Notebook LM, Manus, and DeepSeq, with 18,000-record dataset analysis, AI agent website building, and LLM principles and limits.