Unsloth Desktop Major Update: Command Palette Arrives, 4-bit Fine-Tuning VRAM Usage Drops by 45%
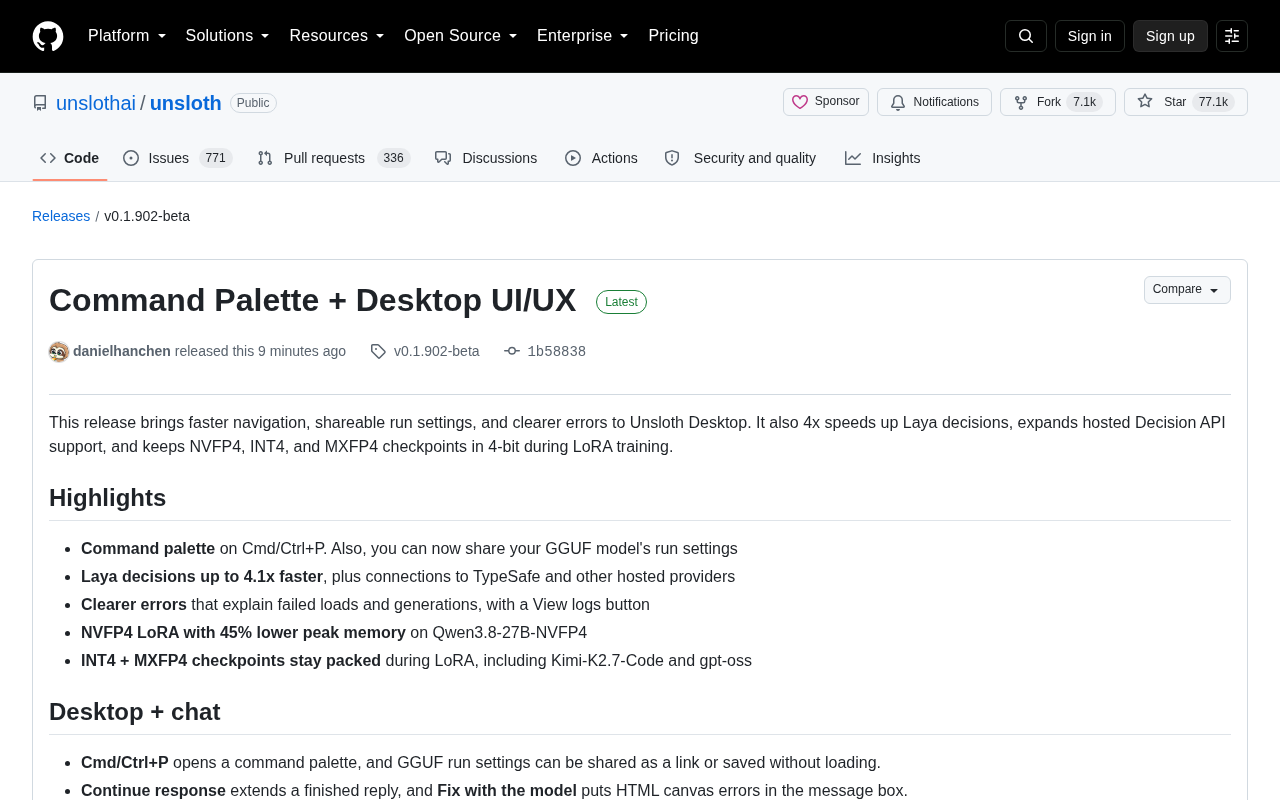
Unsloth Desktop cuts fine-tuning VRAM by 45% with packed 4-bit checkpoints and adds a Command Palette.
Unsloth v0.1.902-beta advances on two fronts simultaneously: the desktop experience gains a Command Palette (Cmd/Ctrl+P), shareable GGUF settings, and a Continue response feature; while the core technical breakthrough enables pre-quantized 4-bit checkpoints to be trained directly in packed state. By using Triton kernels for layer-by-layer on-demand dequantization and preserving exact INT4 format (avoiding the 1.6% perplexity increase from double quantization), peak VRAM for Qwen3.8-27B-NVFP4 on a single RTX PRO 6000 drops from 72.9 GB to 40.2 GB — a ~45% reduction. Laya decision model responses are up to 4.1× faster for short requests, FastModel now supports T5/BART encoder-decoder fine-tuning, and cross-platform support for AMD and Apple Silicon has been updated.
The open-source fine-tuning framework Unsloth has released v0.1.902-beta (Unsloth Desktop). This update goes beyond polishing the desktop UI/UX — the more significant achievement is a dramatic reduction in VRAM usage at the training level. Pre-quantized 4-bit checkpoints can now be trained directly in their packed state, making it possible to fine-tune large models with LoRA on a single GPU or a small number of GPUs where previously massive VRAM was required.
Command Palette and Desktop Experience Upgrades
The most immediately visible change on the desktop side is the new Command Palette, accessible via Cmd/Ctrl+P. This follows the interaction paradigm familiar to developers from tools like VS Code, reducing navigation overhead.
GGUF model run settings can now be shared as a link or saved without loading the model — a practical improvement for team collaboration and reproducing experimental configurations. Two handy features have been added to the chat interface: Continue response lets the model resume completing a response that has already ended, while Fix with the model feeds HTML canvas errors directly into the message box for the model to handle.
The update also includes a range of quality-of-life improvements: a warning now appears when a model can only partially fit in GPU memory; the image gallery prioritizes thumbnails over full PNGs; the desktop supports Cmd/Ctrl +/- zoom; Windows and Linux now use Windows 11-style window buttons; and the app checks whether training is in progress before applying updates to prevent accidental interruptions. Error messages are clearer too — failed loads and generations now explain the reason and include a "View logs" button.
Low-VRAM Checkpoint Training: A Core Technical Breakthrough
If the UI improvements are the surface, low-VRAM training is the heart of this update. Previously, loading pre-quantized 4-bit checkpoints typically required restoring a 16-bit copy first, which carried enormous VRAM overhead. Unsloth now allows these checkpoints to be trained directly in their packed state, reading them as originally released weights, so the post-load VRAM footprint is essentially equivalent to the 4-bit checkpoint itself.
The numbers speak for themselves:
- Qwen3.8-27B-NVFP4 on a single RTX PRO 6000: peak VRAM drops from 72.9 GB to 40.2 GB — a ~45% reduction — with training step time also shortened by 11%;
- Qwen3-8B w4a16 (INT4) on a B200: peak drops from 18.8 GB to 8.5 GB;
- Kimi-K2.7-Code can now be trained on 6× B200s with packed INT4 experts, whereas a 16-bit copy would require approximately 2 TB of VRAM;
- gpt-oss-120b can be trained on a single B200 by setting
load_in_4bit = Falseto retain MXFP4 experts.
Technical Approach: On-Demand Dequantization via Triton Kernels
The core mechanism relies on Triton kernels that dequantize layer by layer on demand, matching the compressed-tensors format bit-for-bit. During backpropagation, only the packed weights are retained. Crucially, INT4 remains exact rather than being re-quantized to NF4 — the latter causes each weight to undergo two rounds of rounding, which according to official figures raises perplexity on Qwen3-8B by 1.6%. For inference-only use of gpt-oss, setting UNSLOTH_MXFP4_KEEP_PACKED=0 restores native loading to accelerate prefill.
LoRA (Low-Rank Adaptation) is one of the most widely used fine-tuning methods for large language models. The core idea is to freeze the original pretrained weights and insert a pair of low-rank matrices alongside specific layers, training only these small matrices. This compresses the number of trainable parameters to roughly 0.1–1% of the full model, significantly reducing VRAM and compute requirements. 4-bit quantization is another approach to reducing VRAM: model weights are compressed from 16-bit floats to 4-bit integers, theoretically cutting weight size to one quarter. Combining both (the QLoRA paradigm) is the standard path for individual developers fine-tuning 70B or larger models on consumer GPUs. The previous pain point was that loading pre-quantized checkpoints required restoring a 16-bit copy in memory before gradient computation — this "decompression" step temporarily spiked peak VRAM close to full-precision levels, largely negating the savings. Unsloth's improvement directly addresses this bottleneck.
Triton is an open-source GPU programming language and compiler framework from OpenAI that lets developers write high-performance GPU kernels in Python-like syntax, with automatic handling of low-level optimizations like thread block scheduling and memory access coalescing. Unsloth's on-demand dequantization uses Triton kernels to temporarily restore packed INT4 weights to the required precision layer by layer during the forward pass, discarding them immediately after computation, and updating gradients directly from packed weights during backpropagation — no full 16-bit copy in VRAM at any point. NF4 (NormalFloat4) is a 4-bit data type designed for normally distributed weights, introduced in the QLoRA paper, while INT4 is the standard integer quantization format. Their quantization grids differ, so re-quantizing existing INT4 weights into NF4 means each weight accumulates two rounding errors — which is precisely what causes the perplexity increase. Unsloth preserves the INT4 format as-is to avoid this precision loss.
Decision API and Laya Speed Improvements
The Laya decision model has received a significant speedup, with responses to short requests up to 4.1× faster. On a B200, a 3-question guardrail check drops from 11.6 ms to 2.8 ms; performance on long inputs remains roughly the same. Laya's load time has been reduced from approximately 17 seconds to around 9 seconds, and peak host memory requirements have been halved.
Ecosystem expansion is also worth noting: users can now connect to TypeSafe or other hosted decision providers under Connections, then select the corresponding model in Settings > API. Once the Decision API is enabled, activating Unsloth Decisions in the chat's MCP menu provides a decide tool.
MCP (Model Context Protocol) is an open protocol proposed by Anthropic in 2024, designed to provide large language models with a standardized interface for tool calls and context injection — essentially a "USB port" for the AI application layer. Through MCP, models can call external tools, databases, or APIs in a unified way without custom integration for each service. A guardrail check refers to using a separate lightweight model (such as Laya) before or after user input or model output to assess whether content violates safety policies or matches expected intent, adding a content safety layer without disrupting the main model's inference pipeline. Laya's 2.8 ms response latency means it can be embedded into real-time conversation flows almost imperceptibly, with minimal impact on user experience.
Image, Video, and Cross-Platform Support
Image models can now maintain INT8 or FP8 precision during offloading. With a 10 GiB VRAM limit on a B200, Z-Image generation time drops from 38.4 seconds to just 2.3 seconds; Qwen-Image-2.1 renders 1536×1536 images up to 3.6× faster on a Radeon 8060S.
Training capabilities are also expanding: FastModel now supports fine-tuning text encoder-decoder models including T5, T5Gemma, BART, and Marian; a new unsloth eval command can run lm-evaluation-harness tasks on checkpoints or LoRA adapters; and Gemma 4 31B training and batch generation now work on models split across multiple GPUs.
On the cross-platform front, Windows users with RX 5000 through RX 9000 series GPUs can now obtain PyTorch from AMD's multi-arch index; MLX has been updated to 0.32.3 and mlx-vlm to 0.7.4; and Mac users can export LoRA adapters in PEFT or GGUF format for use on GPU machines.
Conclusion
This Unsloth Desktop update advances both usability and efficiency in a single release. The Command Palette and a host of UI refinements bring the desktop app closer to a mature productivity tool, while packed 4-bit checkpoint training meaningfully lowers the hardware bar for large model fine-tuning — a 45% VRAM reduction means more models become feasible for individual developers and small teams. As a completely free and open-source tool, Unsloth continues to push down the cost of LoRA fine-tuning, and is well worth trying for developers working in fine-tuning scenarios.
Related articles

macOS Is No Longer UNIX: Apple Didn't Renew Certification, But the Technology Is Unchanged
Apple did not renew macOS's UNIX certification, and the Open Group has removed Apple's entry. This article analyzes the technical reality behind the expiration, Apple's possible intentions, and the practical impact on developers.

Building Stateful Multi-Agent Systems with Azure Cosmos DB
Based on the official Azure Cosmos DB tutorial, this article explains how to use the Agent Memory Toolkit to add shared persistent memory to a multi-agent travel planner, covering short-term, long-term, episodic, and semantic memory plus cross-session state continuity.

Production AI Agent Operations: A Three-Step Framework for Observing, Evaluating, and Optimizing
Azure Cosmos DB team proposes a three-step framework for production AI Agent operations: observe trace tracking, evaluate with LLM as a judge and regression testing, optimize cost across RU, retrieval, memory, and LLM layers.