Unsloth New Release: Built-in Browser, Voice Cloning, and Low-VRAM Training Upgrades

Unsloth v0.1.903-beta brings a built-in browser, voice cloning, multimodal embeddings, and major VRAM optimizations.
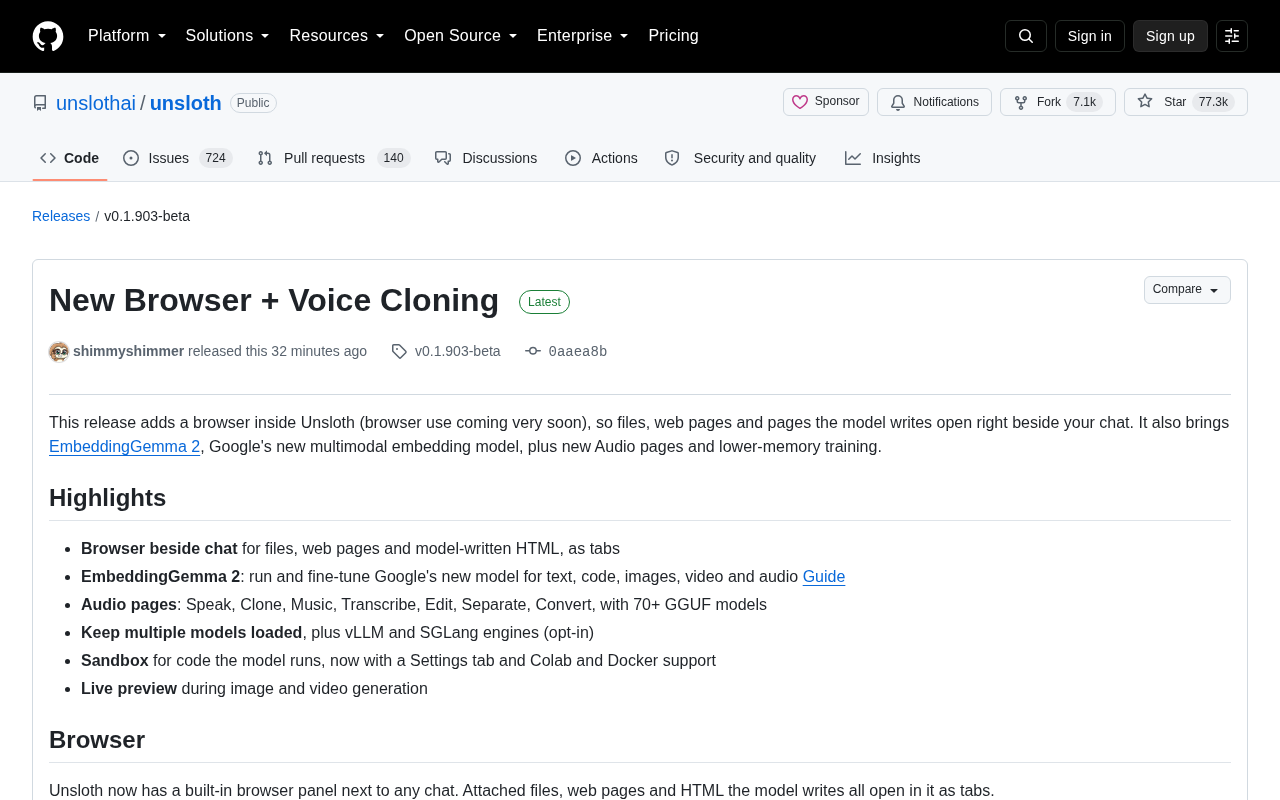
Unsloth's latest beta pushes forward on both feature breadth and low-level performance. A fully functional built-in browser panel, a voice cloning and audio toolchain backed by 70+ GGUF models, and first-day support for Google's EmbeddingGemma 2 multimodal embedding model all land in this release. On the performance side, layer offload drops Llama-3.1-8B 4-bit training VRAM to 7 GiB, padding-free training delivers 5–8× step speed gains on Colab, and Apple Silicon and AMD platforms receive targeted acceleration. This release marks Unsloth's evolution from a fine-tuning efficiency library into a more complete local AI integrated workstation.
Open-source AI training tool Unsloth has released v0.1.903-beta — an update that packs a full browser, a voice cloning suite, and Google's new multimodal embedding model EmbeddingGemma 2 into the local workflow, while delivering significant improvements to training VRAM usage and inference speed. For developers doing local deployment and model fine-tuning, this is a remarkably feature-dense release.
A Real Browser Alongside Your Chat
The most eye-catching change is that Unsloth now has a built-in browser panel right next to the chat interface. Files generated by the model, web pages, and HTML it writes all open directly as tabs beside the conversation — no more switching between windows.
This isn't a simple previewer. It's a fully functional browsing environment complete with an address bar, search, multiple tabs, in-page find, zoom, bookmarks, browsing history, and downloads. PDFs, Office documents, HTML, Markdown, code, and plain text can all be opened as tabs.
HTML and code written by the model opens with a preview, a console, and a "Request edits" entry point — the team explicitly states this feature will replace the existing Canvas. There's also a particularly thoughtful interaction design called "Ask about this page": users can highlight a section of the page and ask the model about it directly. Right-clicking a tab lets you pin it or fork it into a new chat.
In settings, users can choose their search engine, set a default zoom level, and import bookmarks from Chrome, Safari, Firefox, or Edge. On the security side, Unsloth emphasizes that the web environment is isolated from your account, chat history, and API — web pages cannot access that sensitive data. A "browser use" (browser automation) feature has also been teased as coming soon.
Voice Cloning and a Full Audio Toolchain
This update adds a dedicated audio page with a remarkably broad feature set, backed by over 70 GGUF models. Core capabilities include:
- Clone: Clone a voice from a short sample and save it.
- Edit: Directly modify words in a recording while preserving the speaker's original timbre.
- Separate: Split a song into vocals, drums, and other tracks.
- Convert: Transform one person's voice into another's.
- Music: Generate songs and sound effects, with the ability to edit specific sections of a clip.
- Transcribe: Transcription with timestamps and speaker identification, with subtitle export.
From Speak, Clone, and Music to Transcribe, Edit, Separate, and Convert, this audio toolchain covers virtually all common use cases for speech generation, recognition, editing, and separation. It's powered by the newly added audio.cpp native engine, built specifically for voice, music, and dictation tasks. For users who need local, privacy-conscious audio processing, this is a significant addition.
EmbeddingGemma 2: Google's New Multimodal Embedding Model
Unsloth was among the first to support Google DeepMind's new embedding model, EmbeddingGemma 2. It converts text, code, images, video, and audio into vectors for use in search, RAG (Retrieval-Augmented Generation), classification, and clustering tasks.
In terms of specs, the full version has 740 million parameters, while the text-only version has 270 million, with optional vision and audio encoders. It supports over 100 languages and has an 8K context window. On performance, the official figures show roughly a 14% improvement over the first-generation EmbeddingGemma on coding tasks (MTEB code score 78.68 vs. 68.76).
For usage, you can import GGUF or safetensors format into Unsloth to run locally, or use llama.cpp to serve text embeddings. The text model can be fine-tuned via FastSentenceTransformer, supporting 4-bit QLoRA or BF16 LoRA. One easily overlooked but highly practical detail: fine-tuning EmbeddingGemma and Qwen3-Embedding now saves the model's built-in query and document prompts rather than leaving them empty — this has a direct impact on embedding quality.
Background: Embedding models differ fundamentally from typical text generation models: instead of producing natural language, they compress input content into a fixed-dimension dense vector (an "embedding"). Semantically similar content sits closer together in vector space, making these models the foundational component of semantic search, RAG systems, and recommendation engines. RAG (Retrieval-Augmented Generation) is one of today's dominant deployment paradigms for large models: knowledge base documents are vectorized and stored in a database using an embedding model; when a user asks a question, it's also vectorized and the most relevant chunks are retrieved, then handed to a generative model to answer — injecting private knowledge without retraining the model. EmbeddingGemma 2's support for unified vectorization of text, code, images, video, and audio enables cross-modal retrieval — for example, using a text description to find matching images or video clips — which is impossible with text-only embedding models. MTEB (Massive Text Embedding Benchmark) is the standardized benchmark for evaluating embedding models, covering retrieval, classification, clustering, and more; its code subset specifically measures code understanding and retrieval.
Real Gains in Training VRAM and Speed
If the features above are application-layer additions, this section is Unsloth's home turf — making training more VRAM-efficient and faster.
Layer offload is the headline feature here — an optional capability for LoRA on NVIDIA and AMD GPUs. By using offload_layers to keep frozen layers in system RAM, the VRAM ceiling for 4-bit training of Llama-3.1-8B can be pushed down to 7 GiB.
In common environments like Colab, padding-free training (without flash-attn) is also faster: Qwen3-0.6B's VRAM usage drops from 5.45 GB to 1.87 GB, with a 5–8× speed improvement per step. Additionally, QLoRA for gpt-oss-20b is 2–3× faster on NVIDIA.
Image and video generation benefit too: real-time preview during rendering is supported on NVIDIA; Z-Image-Turbo on older GPUs is up to 20× faster; and identical seeds now reproduce identical images across restarts. On AMD, fine-tuned models can be exported for use with Ryzen AI NPUs. On Apple Silicon (MLX), Qwen3.6-35B-A3B replies are around 10% faster with quicker startup on long prompts; M5 chips also gain experimental Int8 Prefill, which can read long prompts up to 1.5× faster.
Background: LoRA (Low-Rank Adaptation) is one of the most widely used fine-tuning methods for large models. The core idea is to inject a small number of trainable low-rank matrices alongside the original pretrained weights, updating only those parameters during training — dramatically reducing VRAM and compute requirements. QLoRA goes further by quantizing the base model weights to 4-bit precision for storage, compressing VRAM requirements to roughly one-quarter of full-precision fine-tuning and enabling consumer-grade GPUs to fine-tune models with billions of parameters. Layer Offload is a complementary VRAM-saving strategy: since frozen layers in LoRA fine-tuning don't participate in gradient computation, they can be temporarily moved out of GPU VRAM and into system RAM, loaded back only when needed for the forward pass — at the cost of some CPU-GPU data transfer latency. Padding-free Training addresses the inefficiency of batching sequences of varying lengths — the traditional approach pads shorter sequences to the length of the longest in a batch, and all that computation on padding tokens is pure waste. Padding-free training concatenates all sequences and processes them directly, eliminating this redundant computation entirely; the gains are especially pronounced on datasets with high variance in sequence length.
More Flexible Model Management and Sandboxing
Beyond the major features, this release includes a lot of engineering polish. On model management, you can now load multiple models simultaneously (disabled by default, enabled in settings), with each request answered by its designated model. Optional support for vLLM and SGLang engines has also been added (Linux + NVIDIA GPU, experimental).
On the security side, code run by the model via Python and Terminal tools is confined to a sandbox with restricted computer access. Linux and macOS have OS-level sandboxing; Windows 11 Preview has an opt-in option; and it now works inside Colab and Docker.
Ecosystem integration has also received attention: you can import chat history from Cursor, Claude Code, and Codex into projects; unsloth start --app lets desktop apps like Codex, OpenCode, OpenClawAd, and Hermes call local models. Auto-compact now also supports Claude, OpenAI API models, and MLX chat.
Summary
Judging by the breadth of this update, Unsloth is evolving from a "high-efficiency fine-tuning tool" into a more complete local AI workstation. The built-in browser, audio toolchain, and multi-model loading are pushing it toward an integrated environment, while low-level optimizations like layer offload and padding-free training continue its tradition of keeping VRAM usage lean. For developers with limited GPU resources who want to handle fine-tuning, inference, embedding, and multimedia processing locally, this release delivers substantial real-world value. That said, since it remains a beta (with some engines marked experimental), thorough validation before production use is recommended.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.