Upper Bound for Planar Vector-Valued Regression Weighted Selection Improved to 11/6
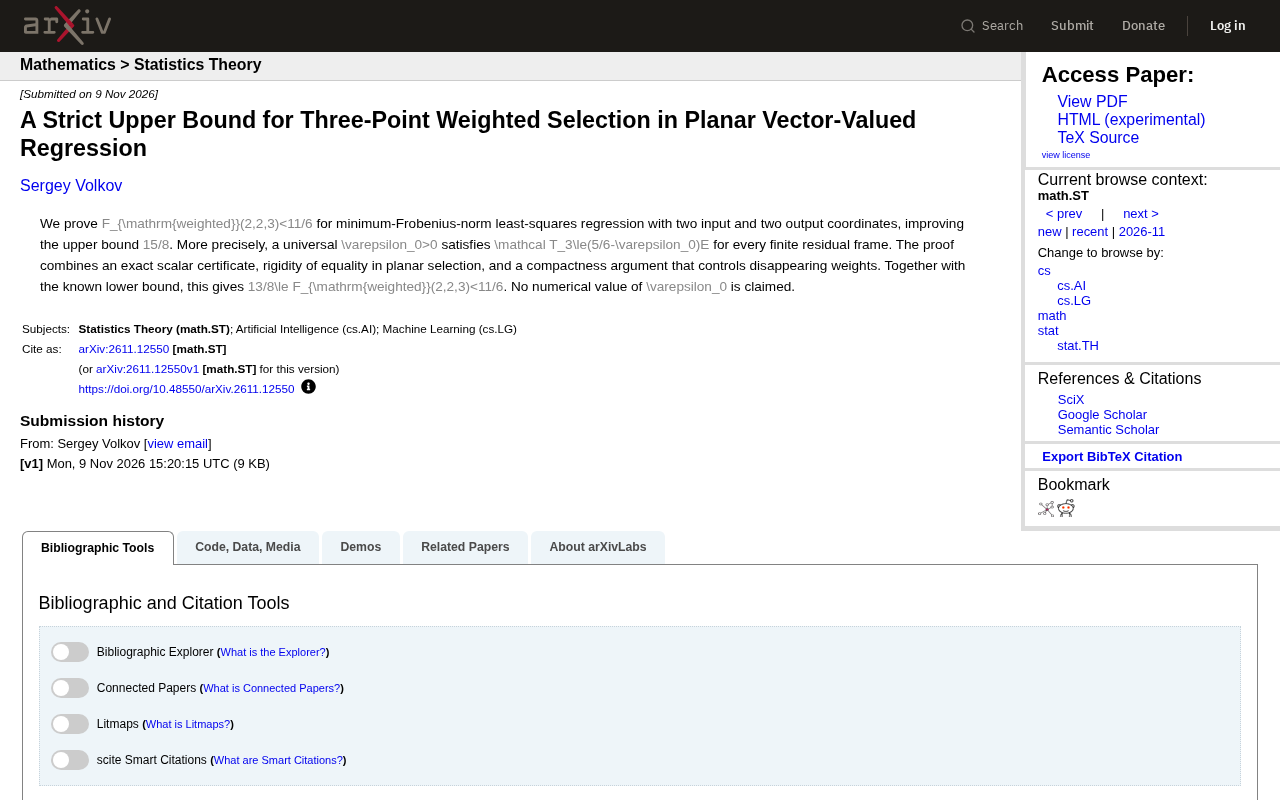
Upper bound for three-point weighted selection in planar vector-valued regression tightened from 15/8 to 11/6, with lower bound 13/8.
This article reports a theoretical advance in the weighted selection problem for minimum Frobenius norm least squares regression. For planar vector-valued regression with two input and two output coordinates, the paper proves an upper bound \(F_{\mathrm{weighted}}(2,2,3) < 11/6\), improving on the previously known \(15/8\). The proof combines exact scalar certificates, rigidity analysis at equality, and a compactness argument controlling vanishing weights, and establishes the existence of \(\varepsilon_0 > 0\) such that \(\mathcal T_3 \le (5/6 - \varepsilon_0)E\). Combined with the known lower bound, this yields \(13/8 \le F_{\mathrm{weighted}}(2,2,3) < 11/6\), narrowing the theoretical interval. Although \(\varepsilon_0\) is not given explicitly, the result provides tighter theoretical guarantees for sparse selection in data compression and active learning, and its proof techniques may generalize to higher-dimensional or larger-point settings.
From 15/8 to 11/6: A New Breakthrough in the Weighted Selection Problem
In minimum Frobenius norm least squares regression, a core theoretical question is: for given input and output dimensions, how many data points are needed at most to guarantee some notion of optimality for the fit? A recent mathematical preprint provides a rigorous upper bound for the three-point weighted selection problem in planar vector-valued regression (two input coordinates, two output coordinates).
The paper proves that for minimum Frobenius norm least squares regression with two input and two output coordinates, (F_{\mathrm{weighted}}(2,2,3) < 11/6), which improves upon the previously known upper bound of (15/8). More specifically, there exists a universal constant (\varepsilon_0 > 0) such that for any finite residual frame, (\mathcal T_3 \le (5/6 - \varepsilon_0)E). Combined with the known lower bound, this yields (13/8 \le F_{\mathrm{weighted}}(2,2,3) < 11/6).
Although abstract, this result has theoretical significance for understanding the robustness of regression models and data selection strategies.
Minimum Frobenius norm least squares regression refers to finding a coefficient matrix (X) in the linear model (y = Ax) that minimizes (|AX - Y|_F^2), where (|\cdot|F) is the Frobenius norm (the square root of the sum of squares of all matrix entries). Unlike ordinary least squares, which is solved independently column by column, the Frobenius norm couples all output dimensions, so the optimal solution (X^* = A^+ Y) (where (A^+) is the Moore-Penrose pseudoinverse) is often called "matrix least squares" in numerical linear algebra. It has applications in multi-response regression, tensor decomposition, and initialization of linear layers in neural networks. The "weighted selection" discussed in this paper further requires that at most (k) data points (rows) be retained to reconstruct the fit, and measures the worst-case upper bound on relative error, denoted (F{\mathrm{weighted}}(m,n,k)), where (m,n) are the input and output dimensions respectively.
Finite residual frames are the basic objects in the weighted selection problem. Given a data matrix (A) and responses (Y), the column space of the fitting residual (R = Y - AX^*) forms a finite-dimensional subspace. A set of row indices (S) is said to constitute a "residual frame" if the corresponding residual vectors span the entire residual space. In the core inequality of weighted selection, (\mathcal T_k \le c \cdot E), (E) typically denotes the total residual energy (the square of the Frobenius norm), and (\mathcal T_k) is the minimum energy required to reconstruct the residual from (k) points. The lower bound on the constant (c) characterizes "how much residual energy a small number of points can capture in the worst case." This framework was systematized by de Gooijer, Rote, and others in their study of least squares subset selection, and is closely related to "subspace embeddings" and "leverage score sampling" in numerical linear algebra.
Proof Approach: Scalar Certificates, Rigidity Analysis, and Compactness Arguments
The proof combines three tools. First, the authors construct an exact scalar certificate that reduces the vector-valued problem to verifiable scalar inequalities. Second, they analyze the rigid structure that arises when equality holds in the planar selection problem, thereby ruling out degenerate configurations near the upper bound. Finally, a compactness argument controls the limiting behavior as weights vanish, ensuring the existence of (\varepsilon_0).
As a detail, the paper does not provide an explicit numerical value for (\varepsilon_0), meaning the improvement is qualitative rather than quantitative. Nevertheless, the strict upper bound improvement from (15/8) to (11/6) still represents a substantial theoretical advance.
Scalar certificates are a common tool in optimization and proof complexity: an inequality involving matrices or vectors is transformed, through the construction of auxiliary scalar functions (such as potential functions, dual variables, or Lagrange multipliers), into a conjunction of finitely many scalar inequalities, making the proof verifiable term by term. In this paper, the authors exploit the low-dimensional structure of the residual space in the planar case to reduce the (2\times 2) matrix-valued inequality to several scalar algebraic inequalities with explicit coefficients. The advantage of this approach is that the proof does not rely on numerical search and is easy to check; the cost is that constructing the certificate often requires problem-specific insight and is difficult to mechanize directly.
Rigidity analysis originates from combinatorial geometry and structural stability theory, and studies the extent to which the configuration of objects is forced when a certain inequality achieves equality. In the planar selection problem considered here, equality corresponds to algebraic constraints satisfied by the residual vectors and selection weights, which restrict feasible configurations to a low-dimensional manifold. The role of rigidity analysis is to prove that if the upper bound (11/6) is approached, the configuration must be close to these rigid structures, which either contradict the known lower bound (13/8) or cannot be simultaneously satisfied, thereby ruling out degenerate cases. The compactness argument handles the limit as weights tend to zero: by proving lower semicontinuity of the function (F_{\mathrm{weighted}}) over the parameter space, it ensures that the limiting configuration remains in the feasible domain, so that the existence of (\varepsilon_0 > 0) follows by contradiction.
Theoretical Significance and Potential Applications
This result falls within the approximation theory of vector-valued regression. The weighted selection problem concerns the extent to which fitting quality can be maintained when only a small number of key data points are retained in regression. For the planar case (both input and output are two-dimensional), the improved upper bound for three-point selection means that theoretical guarantees in data compression or active learning scenarios can be tighter.
Although the current conclusion remains at the level of asymptotic constants, the scalar certificate and rigidity analysis techniques used in the proof may generalize to higher-dimensional or larger-point selection problems, providing methodological guidance for future research.
Conclusion
This work tightens the upper bound for three-point weighted selection in planar vector-valued regression from (15/8) to (11/6), and provides a lower bound of (13/8), narrowing the theoretical interval. Although no explicit constant is given, its proof framework is valuable for understanding sparse selection in regression.
Related articles

Daybreak Red Deployment Guide: A Reference Architecture for Supervised Security Investigation
A breakdown of the Daybreak Red reference architecture: security control design, deployment configuration process, and runtime monitoring for supervised security investigation.

Gemini 4 Neon Tops the Models Engineering Index
Gemini 4 Neon tops the Models Engineering Index, sparking Hacker News debate over ranking credibility and evaluation methods. Here's what it means for developers.

Apple's Self-Developed AI Agent: An Agent That Can Operate Your Mac Is Coming
Apple is reportedly developing an AI agent that can operate a Mac, targeting Meta Muse, Claude, OpenAI Dots, and others. This article analyzes Apple's system-level advantages, the competitive landscape, and likely rollout paths in the agent race.