VERITAS: Verbalising Model Computation to Reveal Chain-of-Thought Faithfulness
VERITAS tracks reasoning anchors via layer-wise Jacobian projection to detect and explain CoT unfaithfulness.
The article introduces VERITAS, a method for detecting whether Chain-of-Thought reasoning faithfully reflects a model's internal computation. Existing methods make binary judgments from output text or static activations, knowing only that the result is unfaithful without locating where deviation occurs. VERITAS applies layer-wise Jacobian projection at each CoT token to structurally record reasoning anchors' emergence, propagation, and output surfacing as a trace, then trains a classifier on these features. It achieves balanced accuracy 28.4% higher than LLM-as-Judge and 16.0% higher than activation probing across four datasets, generalising across datasets and architectures.
Chain-of-Thought (CoT) reasoning lets large models show their problem-solving steps, but do these steps truly reflect the model's internal computation? Existing verification methods mostly detect unfaithfulness from outputs or static activations, yet struggle to explain how unfaithfulness gradually forms during generation. A new paper proposes VERITAS, which "verbalises" model computation to trace the emergence, propagation, and output of reasoning anchors layer by layer, offering a more mechanistically interpretable perspective on CoT faithfulness detection.
Limitations of Existing Methods: Looking Only at Results, Not the Process
Current CoT verification mainly relies on two types of signals: directly analysing model output text, and probing static activation patterns. Both approaches can judge whether the final answer is faithful, but cannot answer a key question—at which layer and which generation step did the unfaithful reasoning deviate? In other words, we only know "the result is wrong," not "how the process went bad."
VERITAS starts precisely to fill this gap. It is not satisfied with a binary faithfulness judgment, but instead attempts to construct a "verbalised account" of the model's internal reasoning evolution, making the formation of unfaithfulness observable and explainable.
CoT faithfulness refers to whether the reasoning chain a model outputs truly reflects its internal actual computation process. A reasoning chain may be logically coherent and arrive at the correct final answer, yet not be the real path by which the model reached that answer—the model may fabricate plausible-looking steps after the fact, or "secretly" change the basis of its computation midway. Faithfulness and accuracy are two independent dimensions: a correct answer can come from unfaithful reasoning, and faithful reasoning can also yield a wrong answer due to an incidental error. Existing verification methods "look only at results" because they typically only check the consistency between output text and answer, or probe activations at a single static layer, and thus cannot locate the layer and generation step where deviation occurs.
VERITAS's Core Mechanism: Layer-wise Jacobian Projection
VERITAS employs layer-wise Jacobian projection, projecting the computational state of each model layer at every generated CoT token onto an interpretable feature space. The effect is that how "reasoning anchors" formed in different layers emerge, how they propagate between layers, and how they ultimately surface in the output can all be structurally recorded as a trace.
Based on these trace features, the research team trained a classifier to distinguish faithful from unfaithful reasoning. Compared with LLM-as-Judge and activation probing, this structured feature not only detects more accurately, but can also pinpoint the specific location and manner of reasoning deviation.
The Jacobian matrix describes all first-order partial derivatives of a vector-valued function with respect to an input vector, with elements J_ij = ∂f_i/∂x_j characterising the influence of a small change in the j-th component of the input on the i-th component of the output. In neural networks, the Jacobian can quantify the sensitivity and contribution direction of a layer's activations to subsequent layers or the final output. Layer-wise Jacobian projection computes this local linearisation relationship for each layer separately, then projects the high-dimensional sensitivity structure onto a low-dimensional, interpretable feature space. Compared with looking only at a single-point activation value, the Jacobian retains dynamic information about "how layers influence one another," and can therefore trace the propagation path of a reasoning anchor from lower to upper layers, not merely its instantaneous strength at a single layer.
A reasoning anchor is the unit of analysis introduced by VERITAS, referring to an internal representational state that carries a specific reasoning element (such as an intermediate conclusion, an entity relation, or an intermediate computational quantity). An anchor is not a manually annotated text fragment, but an internal pattern identified from layer-wise projection features that propagates stably across layers and ultimately influences the output. The significance of tracking anchors is that unfaithfulness often manifests as a key anchor being weakened, replaced, or bypassed during propagation while the final output remains superficially coherent. By recording an anchor's emergence layer, propagation path, and surfacing position in the output, VERITAS turns "how the process went bad" into comparable structured traces rather than a single faithfulness label.
Experimental Performance: Significantly Outperforming Baselines
On four datasets from FaithCoT-Bench and BonaFide, VERITAS achieved clear performance gains: balanced accuracy 28.4% higher than LLM-as-Judge, and an average improvement of 16.0% over activation probing. More critically, the method demonstrates generalisation across datasets and model architectures, indicating that the extracted features are not overfitted to a particular setting.
Further analysis in the paper shows that VERITAS can not only detect unfaithfulness but also provide insights into "how" and "where" reasoning deviates. This moves it from a mere detection tool one step toward mechanistic understanding.
Balanced accuracy is the arithmetic mean of per-class recall, suitable for binary classification evaluation with imbalanced positive and negative samples. In CoT faithfulness detection, the numbers of faithful and unfaithful samples often differ considerably, and ordinary accuracy would be dominated by the majority class, whereas balanced accuracy treats both types of error equally. LLM-as-Judge refers to using another large model as a judge to read the reasoning chain and determine whether it is faithful; it relies on the judging model's own reasoning ability, is costly, and is susceptible to the judge model's biases. Activation probing trains a linear classifier on the activations of one or several layers of the model to predict faithfulness; it is a static, single-point form of detection that struggles to capture inter-layer dynamics. Comparing VERITAS with these two types of baselines precisely illustrates the advantage of structured process features over "black-box judging" and "static probing."
From Detection to Understanding: The Value of a Mechanistic Perspective
The significance of VERITAS lies in proposing a new paradigm: examining CoT faithfulness by verbalising model computation. Traditional methods treat faithfulness as a black-box label, whereas VERITAS unfolds it into an inter-layer dynamic process, allowing researchers to see the migration trajectory of reasoning anchors. This perspective holds potential value for building more reliable and interpretable reasoning systems.
Of course, the method currently still relies on a classifier to discriminate trace features, and is still some distance from fully automatically "narrating" the model's reasoning story. But it clearly demonstrates a direction: understanding reasoning failure requires delving into the generation process itself, not merely inspecting the final output.
One-line Summary
VERITAS uses layer-wise Jacobian projection to track reasoning anchors, detecting and explaining CoT unfaithfulness.
Paragraph Summary
The article introduces the VERITAS method proposed in a new paper for detecting whether Chain-of-Thought (CoT) reasoning faithfully reflects a model's internal computation. Existing methods mostly make binary judgments from output text or static activations, allowing one to know only that the result is unfaithful, without locating which layer or generation step the deviation occurred at. VERITAS performs layer-wise Jacobian projection on each model layer at every CoT token, mapping internal computational states onto an interpretable feature space and structurally recording the emergence, inter-layer propagation, and output surfacing of reasoning anchors to form a trace, based on which a classifier is trained to distinguish faithful from unfaithful reasoning. On four datasets from FaithCoT-Bench and BonaFide, its balanced accuracy is 28.4% higher than LLM-as-Judge and an average of 16.0% higher than activation probing, and it demonstrates generalisation across datasets and model architectures. The article argues that its value lies in unfolding faithfulness from a black-box label into an observable inter-layer dynamic process, advancing from detection toward mechanistic understanding.
Related articles
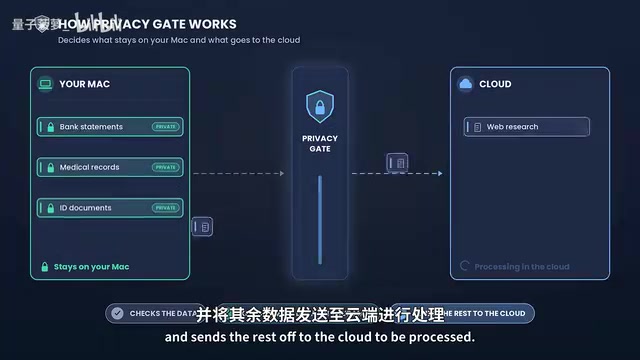
Perplexity Hybrid Compute Tested: Privacy Data Never Leaves the Mac
Perplexity Hybrid Compute tested: how PrivacyGate intercepts sensitive data, how local and cloud models divide work, model differences on 16GB vs 32GB Macs, and privacy protection in real scenarios like bank statements and medical records.
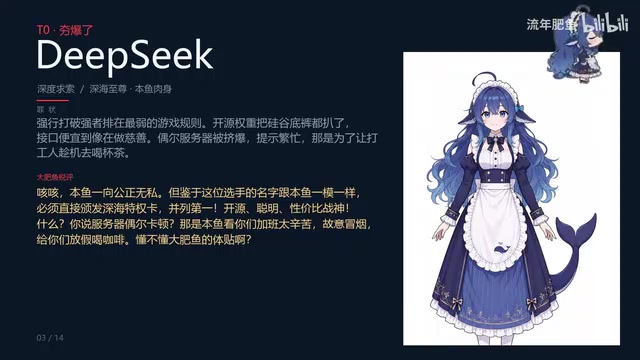
Big Fat Fish Roasts Mainstream LLMs at Home and Abroad: Doubao Takes the Crown, DeepSeek Tied for First
Bilibili creator Big Fat Fish roasts mainstream LLMs: Doubao tops for emotional value, DeepSeek ties first for open-source value, with ERNIE, Hailuo, Yuanbao, Kimi, Qwen, Kling, Claude, Gemini, and Grok each branded with a distinct persona.
How to Truly Test AI Agents Before Production? A Practical Testing and Monitoring Framework
BotGage founder Pramin Pradeep shares a three-step framework for testing AI Agents before production: Agent registration visibility, red teaming, and production observability — plus a real case cutting QA costs from $180K to $80K and an analysis of IT roles shifting to Agent supervisors.