Voice Agent Latency Benchmark: Pipecat vs. LiveKit vs. GPT-Live

Comparing cascaded and end-to-end voice agents in Spanish freight negotiations on latency, recognition, and interruption handling.
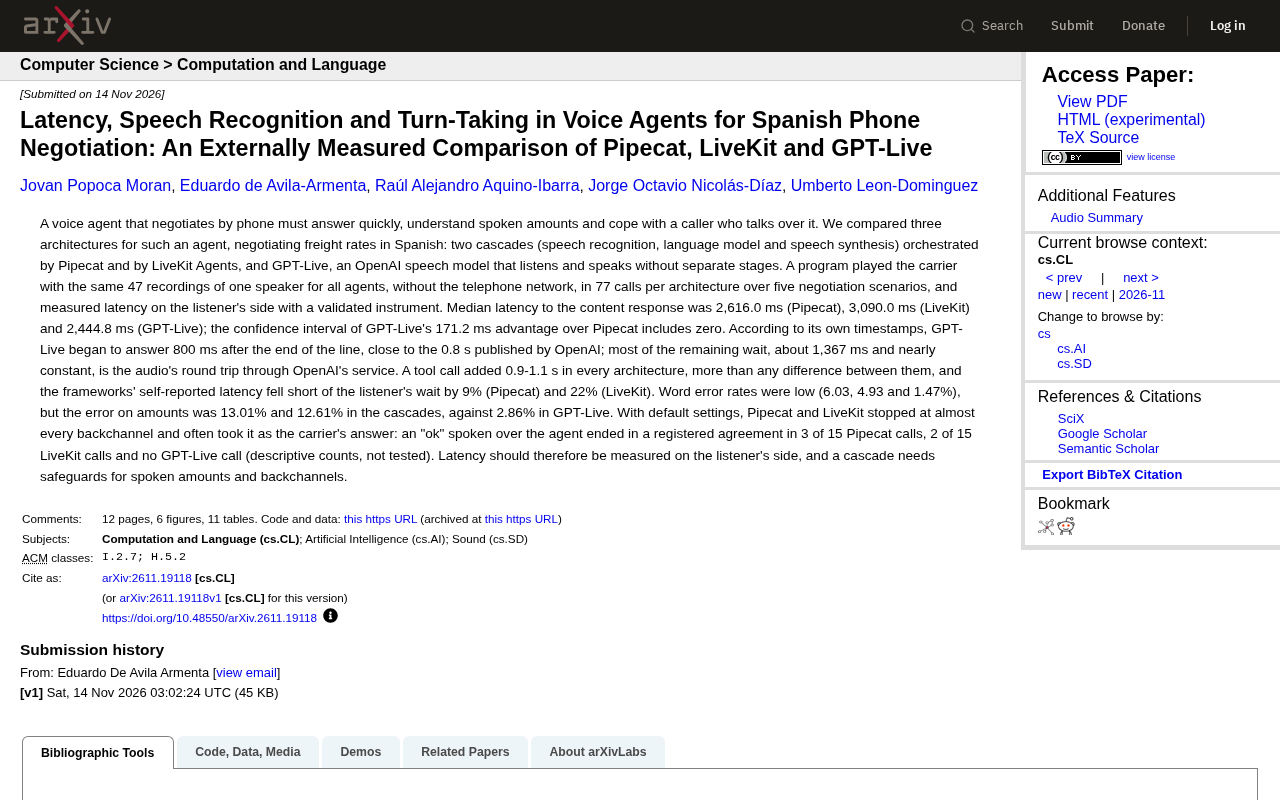
The study compared Pipecat and LiveKit cascaded architectures with OpenAI GPT-Live end-to-end model in a Spanish freight negotiation phone scenario. Using 47 recordings to simulate a carrier, each architecture underwent 77 call tests, with latency measured at the listening end. Results show GPT-Live median latency of about 2.4 seconds, slightly better than Pipecat's 2.6 seconds and LiveKit's 3.1 seconds, but the advantage is not statistically significant; tool calls add 0.9-1.1 seconds, exceeding architecture differences. Overall word error rate is only 1.47% for GPT-Live versus 4.93%-6.03% for cascaded systems; however, for amount recognition, cascaded systems exceed 12% error rate, while GPT-Live is only 2.86%. Under default settings, cascaded systems easily misjudge background "ok" as an answer, leading to incorrect agreement records. Framework self-reported latency is 9%-22% lower than user-perceived latency, emphasizing the need for listening-end measurement.
In a Spanish-language phone scenario involving freight rate negotiations, voice agents must not only respond quickly but also accurately recognize monetary amounts and handle user interruptions. An external measurement study compared three architectures: cascaded systems orchestrated with Pipecat and LiveKit (speech recognition + language model + speech synthesis) and OpenAI's end-to-end speech model GPT-Live. The experiment used 47 recordings from the same speaker to simulate a carrier, conducting 77 call tests per architecture in a no-telephone-network environment, covering five negotiation scenarios, with latency measured at the listening end.
Latency Performance: GPT-Live Slightly Better, but Gap Not Significant
The study shows that the median latency from when the user stops speaking to when the agent begins responding with content is approximately 2.6 seconds for Pipecat, 3.1 seconds for LiveKit, and 2.4 seconds for GPT-Live. GPT-Live has an advantage of about 0.17 seconds over Pipecat, but the confidence interval includes zero, meaning this advantage is not statistically significant.
According to GPT-Live's own timestamps, it begins responding about 0.8 seconds after the call ends, close to OpenAI's published data; the remaining wait is about 1.37 seconds and nearly constant, primarily from the round-trip transmission of audio through OpenAI's services. A detail worth noting: tool calls add 0.9-1.1 seconds of latency across all architectures, an effect that exceeds the differences between architectures.
Median Latency and Confidence Intervals: In latency measurement, the median is often used to describe the typical level of user wait time, as it is less susceptible to extreme values than the mean. The study also reports confidence intervals to quantify the uncertainty of estimates. When the confidence interval of the difference between two groups' latencies includes zero, it means that statistically the possibility of "no difference between the two" cannot be ruled out, so it cannot be asserted that GPT-Live is significantly faster. This criterion is particularly important in comparisons of voice interaction systems, because differences of tens to hundreds of milliseconds may be drowned out by noise such as network jitter and user speaking rate.
Gap Between Self-Reported and User-Perceived Latency
Framework self-reported latency is lower than the actual wait time at the listening end: Pipecat is about 9% lower, and LiveKit about 22% lower. This indicates that relying solely on framework internal metrics will underestimate the user's real experience. The study emphasizes that latency should be measured at the listening end, rather than trusting system logs alone.
Speech Recognition: Low Overall Word Error Rate, but Amount Recognition Is Concerning
The overall word error rates for the three architectures are 6.03% (Pipecat), 4.93% (LiveKit), and 1.47% (GPT-Live), respectively. However, in critical amount recognition, the cascaded systems have error rates as high as 13.01% and 12.61%, while GPT-Live is only 2.86%. For negotiation scenarios, amount errors may directly lead to business losses, and cascaded architectures need to add protective measures for digit recognition.
Limitations of Word Error Rate (WER): Word error rate is the most commonly used overall metric for speech recognition, calculated as the sum of substituted, inserted, and deleted error words divided by the total number of reference words. However, WER treats all words equally and cannot reflect errors in key entities (such as amounts, dates, flight numbers). In negotiation scenarios, a single digit error (for example, recognizing "1500" as "150") may have more serious consequences than ten function word errors. Therefore, the study separately calculated the amount recognition error rate, revealing the structural weakness of cascaded systems in digit recognition. In cascaded architectures, the acoustic model and language model are separate, and digits are often more error-prone due to short pronunciation and sparse context; end-to-end models may improve digit recognition through richer joint acoustic-semantic modeling.
Turn-Taking: Interruption Handling Deficiencies Under Default Settings
Under default settings, Pipecat and LiveKit stop responding to almost every background sound (such as "ok") and often mistake it for the carrier's answer. In 15 Pipecat calls, 3 were incorrectly recorded as agreements reached due to the interruption "ok"; LiveKit had 2; GPT-Live had none. These counts are descriptive statistics without hypothesis testing, but they reveal the fragility of cascaded systems in turn-taking logic.
Turn-Taking and Voice Activity Detection (VAD): Turn-taking refers to the coordination mechanism by which both parties in a conversation alternate speaking. In voice agents, systems typically rely on voice activity detection (VAD) to determine whether the user has finished speaking, combined with endpointing to decide when to begin responding. Under default settings, VAD also triggers a "user speaking" signal for brief background sounds (such as "ok"), causing the agent to mistakenly believe the turn has shifted. In cascaded architectures, ASR, LLM, and TTS process in stages, and interruption signals may be incorrectly fed into the dialogue state machine and recorded as valid responses. End-to-end models, on the other hand, can learn more robust turn boundaries within a unified model, reducing such misjudgments. Improvement directions include adjusting VAD sensitivity, introducing semantic-level interruption confirmation, and adding secondary verification before recording agreements.
Conclusions and Implications
For voice agents in telephone negotiation scenarios, end-to-end models show advantages in latency, amount recognition, and interruption resistance, but cascaded architectures can still improve reliability through targeted optimizations (such as amount verification and interruption suppression). Latency measurement should be based on the user side, not framework self-reported data.
Related articles
Anthropic Goes Public: AI Bubble or Buying Opportunity?
Anthropic lists on Nasdaq, opening about a third above its IPO price. We break down the $81.3B raise, $1.5T offering valuation, and $2T market valuation, plus Claude's growth and $567M quarterly operating loss.
Why the FBI's AI Hacker Warning Hinges on a Single Word from Microsoft
FBI says AI tool Artex attacked 2,250+ organizations, but the citation trail leads to Microsoft's wording of "attempted sign-ins." The gap between attempts and breaches reveals the attack's true scale.
Fable 5.2 Powers the Creation of Getsumen Express: A Browser-Based Lunar and Martian Exploration Game
A developer used Fable 5.2 to build Getsumen Express, a browser game where players explore the Moon and Mars, scan real landmarks, shoot aliens, and ride an interstellar train. Built on Three.js and WebGPU for about $730, it showcases AI-assisted development.