What Happens When AI Sleeps? Anthropic Agent Memory #TechMalayalam #AgenticAI #ClaudeAI
AI's "sleep" is really memory reconstruction between sessions, centered on orderly organization, retrieval, and discarding.
Using a TechMalayalam video, the article discusses memory management for AI agents between sessions, likening it to the agent's "sleep organization." Each session produces a large amount of context; retaining it all slows responses and lowers answer quality, so the key is memory reconstruction at session boundaries: deciding what enters long-term storage and what is discarded. Anthropic's approach on Claude is layered processing with a retrievable memory store that automatically loads relevant parts at the start of a new session rather than injecting everything. The article also covers self-evaluation loops and note-taking rules, using external constraints to reduce behavior drift, and gives developers three suggestions: write key facts into structured notes, set clear read/write rules, and verify memory loading when switching sessions.
When a user ends the day's conversation, does the AI agent also go into "sleep"? This seemingly anthropomorphic question actually points to one of the most practical aspects of agent architecture: memory management. In a video from the YouTube channel TechMalayalam, the discussion uses Anthropic's Claude and its Agent Memory design as an entry point to explore how agents save, retrieve, and discard information between user sessions.
Why AI's "Sleep" Is a Technical Problem
The video opens with an analogy: after a person falls asleep, the brain organizes the day's memories, and between the end of one session and the start of the next, an AI agent likewise needs a mechanism to handle historical information. According to TechMalayalam's explanation, each user session contains a large amount of context; if all of it is retained, the next conversation will carry too much irrelevant content, causing slower responses and lower answer quality.
The key here is not that the AI actually "rests," but rather memory reconstruction at session boundaries: which content enters long-term storage and which is discarded when the session ends. The video likens this process to the agent's "sleep organization," which is essentially part of context engineering.
Context Window is the maximum number of tokens a large language model can process at one time, including the system prompt, historical conversation, retrieved memories, and the current user input. It is not unlimited, and as length increases, the model's utilization of information in the middle often declines (commonly known in the industry as the "lost in the middle" phenomenon). Therefore, stuffing all history into the context is neither economical nor reliable: the more tokens, the higher the inference cost and latency, and the easier it is for key information to be drowned out by noise. This is precisely why the article emphasizes "memory reconstruction at session boundaries"—rather than retaining everything indiscriminately, it is better to inject only the fragments most relevant to the current task into the limited context window at each session initialization, thereby balancing cost, speed, and answer quality.
Anthropic's Agent Memory Design Approach
According to the video's summary, Anthropic's approach to Agent Memory can be summarized as layered processing. The agent maintains a retrievable memory store and automatically loads the part relevant to the current task each time a new session starts, rather than stuffing all previous conversations verbatim into the context window.
TechMalayalam specifically mentions a detail that is easy to overlook: memory loading is automatic. In other words, users do not need to manually "remind" the AI what was discussed last time; the system completes retrieval and injection during session initialization. This makes multi-turn, cross-session tasks possible, such as a writing project or code debugging process that lasts several days.
But the video also points out the cost—automatic loading means the model must make trade-offs within a limited context, and the quality of the retrieval strategy directly determines whether it "remembers the important things" or "misremembers the details."
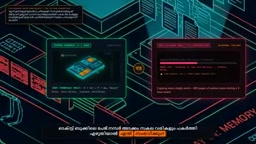
Retrieval-Augmented Generation (RAG) is the background concept for understanding a "retrievable memory store." Its basic process is: first split text into chunks and convert them into vectors stored in an index; at query time, use similarity to retrieve the most relevant chunks, then concatenate them into the prompt and hand them to the model to generate an answer. What the article calls "automatically loading the part relevant to the current task" is essentially using conversation history or structured notes as a retrieval library and performing a retrieval injection at session startup. RAG's advantage is that it decouples "what to remember" from the model parameters, turning it into updatable, auditable external storage; its limitation is that retrieval quality determines everything—if recall is inaccurate or chunking is inappropriate, the model will "misremember the details," which also echoes the article's reminder about trade-offs in retrieval strategy.
Forgetting Is Harder Than Remembering: Self-Evaluation and Rule Constraints
The latter half of the video discusses a more interesting practice: having Claude self-evaluate its own responses. TechMalayalam describes the approach as follows: after giving an answer, the model checks it again, identifies and corrects errors, and only then feeds the result back to the user. Multiple loops of self-evaluation and correction are believed to improve the reliability of the final answer.
Paired with this are "automatic read control" and note-taking rules. According to the video, the system can set rules for the agent, requiring it to fill in missing necessary notes or maintain a work record in a prescribed format. This is in fact using external rules to constrain the model's behavioral boundaries and reduce the drift caused by free-form generation.
The author uses a down-to-earth analogy here: make the memory mechanism like a notebook you can consult at any time, rather than having the model recite from impression. This idea offers direct inspiration for developers—memory is not better when it is bigger, but only when it is usable and verifiable.
Self-Reflection / Self-Critique refers to the loop in which a model, after generating an answer, performs a second check on its own output, identifies errors, and corrects them. A common approach is to have the model review item by item from a reviewer's perspective against the original requirements or factual basis, and then output a revised version. To some extent it can alleviate hallucination and format drift, but it is not a panacea: multiple rounds of self-evaluation increase latency and token consumption, and the model may turn a blind eye to its own errors. Therefore, in practice it is often combined with external rules and tool validation, just like the "automatic read control" and "note-taking rules" mentioned in the article—using deterministic constraints as a fallback so that self-evaluation can focus on semantic-level gap-filling.
What It Means for Developers
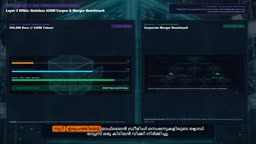
The video finally brings the perspective back to practical use. TechMalayalam mentions that when using Claude for long-document processing, differences in memory and context management are directly reflected in output length and accuracy. Some users have observed significant changes in the ratio of the processed result's length to the original document—under long contexts, the degree of compression and detail retention in model output are both affected. Although such observations come from a single channel, they align with the industry's general understanding of long contexts: the longer the context, the more likely the model's utilization of middle information is to decline.
For developers, there are three actionable practices: first, write key facts into structured notes rather than relying on model memory; second, set clear read/write rules for the agent and limit the scope it can modify; third, actively verify whether memory has been correctly loaded when switching sessions.
Summary
Although the question "What happens when AI sleeps" is posed in a lighthearted way, it points to the most practical engineering issue in the deployment of Agentic AI. Anthropic's memory design on Claude is not primarily about making AI remember more, but about enabling it to orderly organize, retrieve, and discard information between sessions. The two mechanisms of self-evaluation loops and note-taking rules provide a reference sample for "how to make agents use memory reliably."
It should be noted that some operational details in this video are the creator's personal practice summaries, and performance may differ under different model versions and configurations. Readers should still refer to the official documentation when using them in practice.
One-line Summary
AI's "sleep" is actually memory reconstruction between sessions, with the core being orderly organization, retrieval, and discarding.
Paragraph Summary
The article uses a video from TechMalayalam to discuss memory management for AI agents between sessions, likening the process to the agent's "sleep organization." Each session generates a large amount of context; if all of it is retained, responses become slower and answer quality declines, so the key lies in memory reconstruction at session boundaries: deciding which information enters long-term storage and which is discarded. Anthropic's approach on Claude is layered processing, maintaining a retrievable memory store and automatically loading relevant parts at the start of a new session rather than injecting everything. The article also introduces self-evaluation loops and note-taking rules, using external constraints to reduce model behavior drift, and offers three suggestions for developers: write key facts into structured notes, set clear read/write rules, and verify memory loading when switching sessions.
Related articles
Anthropic's Agent Memory Architecture: The Memory Philosophy of Less Is More
Anthropic's Pokemon Red experiment reveals a counterintuitive conclusion about agent memory: a Claude saving 413 files performed worse than one maintaining a short dashboard. This article analyzes the four-layer memory architecture, the Dreams offline correction mechanism, and CLAUDE.md best practices.
Behind the Nvidia CEO Scandal: The Key Person Risk of AI Infrastructure
Jensen Huang's scandal triggers an independent Nvidia board probe as chip stocks rally and Nvidia falls alone. We break down AI infrastructure's key person risk and how real estate investors can protect deals with a three-step check.
13 Practical AI Tips: Save Money, Protect Privacy, Upgrade Your Digital Life
A roundup of 13 practical AI tips from The Explainer: AI agents for cost-saving negotiations, data deletion requests, Claude Code for computer diagnostics, local offline models, in-car voice learning, and motion pose analysis—with emphasis on human oversight and safety boundaries.