What LLMs Can You Run with 1.9TB of RAM? Exploring the Ceiling of Local AI Deployment
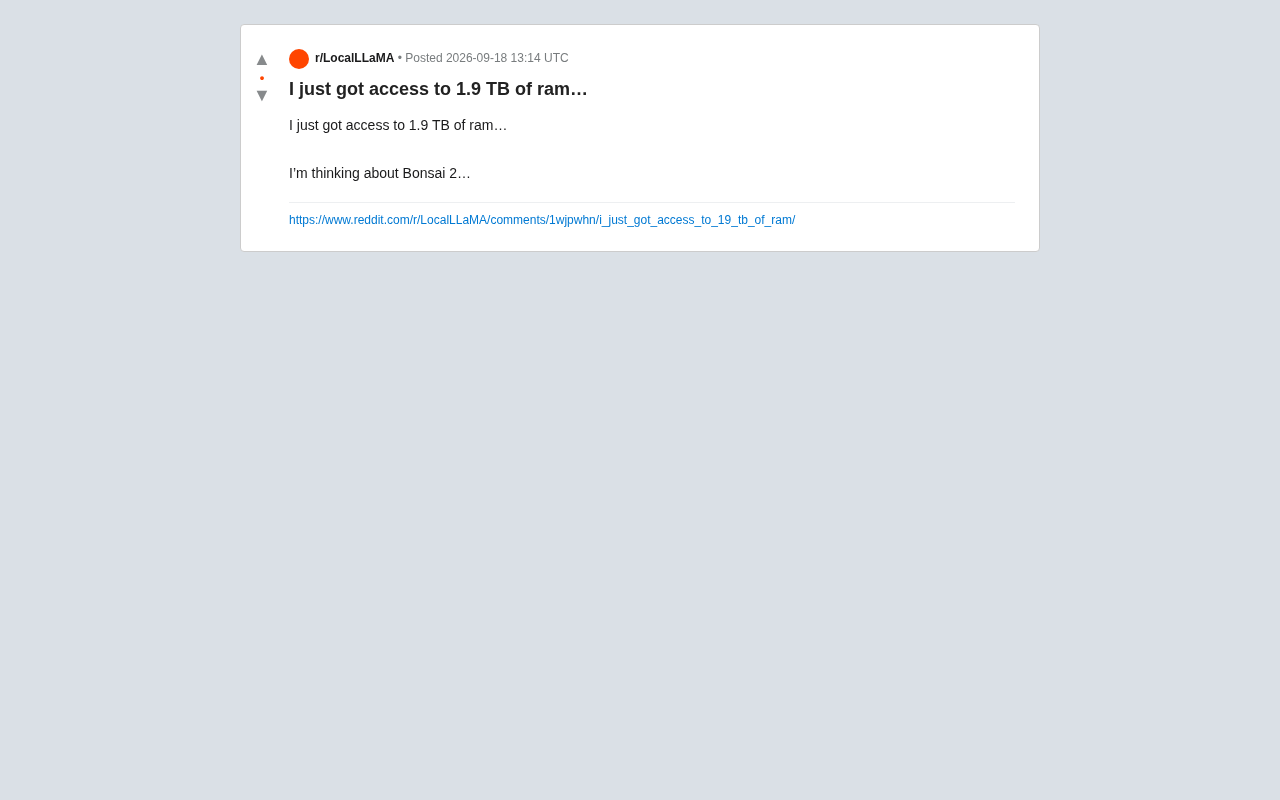
A Reddit user with 1.9TB RAM sparks debate on the real limits of running giant LLMs locally.
A Reddit post about gaining access to 1.9TB of RAM sparked discussion in the local LLM deployment community. The article examines what that kind of memory means in practice: enough to load hundreds-of-billions-parameter models at full precision and even run multiple models in parallel. However, CPU-based inference lags far behind GPU VRAM in memory bandwidth, making token generation speeds a serious bottleneck. The piece also speculates on the mentioned "Bonsai 2" model and argues that the real challenge of local deployment isn't fitting the model into memory — it's turning raw hardware into actual productivity through software optimization.
A Reddit Post That Got People Thinking
A Reddit user recently posted that they'd gained access to a machine with 1.9TB of RAM, mentioning they were considering running models like "Bonsai 2." The post was brief, but it touched on a core question in local LLM deployment: when you have an enormous amount of memory at your disposal, what can you actually do with it?
To put 1.9TB of RAM in perspective: a typical consumer PC ships with 16GB to 64GB, and even high-end workstations top out around 128GB to 256GB. 1.9TB is firmly server territory — the kind of hardware you'd find in a data center, a multi-socket enterprise server, or a purpose-built AI inference platform. With that much memory, you could load virtually any open-source large language model in existence entirely into RAM.
What Massive RAM Actually Means for Local LLM Deployment
When you deploy a large language model locally, the model weights need to be loaded into memory (or GPU VRAM) before inference can happen. The larger the model, the more memory it demands. As a rough benchmark using common quantization formats: a 70-billion-parameter model requires around 40GB in 4-bit quantization, while a full-precision unquantized version can easily consume over 100GB.
1.9TB of memory theoretically accommodates models with hundreds of billions of parameters — and could even hold multiple models simultaneously for side-by-side comparisons or parallel serving. For researchers and enthusiasts, this eliminates the physical constraint of "the model is too big to run," shifting the bottleneck away from memory capacity and toward inference speed and memory bandwidth.
The Real-World Limits of CPU-Based Inference
There's an important caveat: running a large model on CPU + system RAM versus GPU VRAM is not even close in terms of performance. Memory bandwidth on system RAM is far lower than on high-end GPUs, which means that even if the model fits comfortably, token generation speeds can be slow enough to seriously degrade the user experience. The original post didn't mention the CPU configuration or memory bandwidth — and those details matter enormously for real-world inference speed.
To put numbers on it: a modern high-end GPU like the NVIDIA H100 delivers up to 3.35 TB/s of memory bandwidth, while even top-tier server-grade DDR5 RAM peaks somewhere in the 300–500 GB/s range — roughly an order of magnitude slower. LLM inference during the decoding phase (generating tokens one by one) is a classic memory-bandwidth-bound task: compute units spend most of their time waiting for data to be transferred from memory rather than actually doing matrix math. On a CPU + large-RAM platform, real-world token generation speeds can drop to single digits per second or lower, making interactive chat feel sluggish. That said, offline batch processing tasks — large-scale text generation, dataset annotation — remain practical. Inference frameworks like llama.cpp have implemented multi-threaded optimizations for CPU inference, but software can only do so much to compensate for a physical bandwidth ceiling.
Quantization is the core technique for reducing memory requirements in local deployment. It compresses model weights from their original FP32 (32-bit float, 4 bytes per parameter) or FP16 representation down to lower-precision integer formats like INT8 or INT4, cutting memory usage by 2x to 8x. Taking the GGUF format (used by llama.cpp) as an example, Q4_K_M is one of the most widely used 4-bit quantization schemes today — it strikes a solid balance between memory footprint and model capability, with quality loss that's acceptable for most tasks. While quantization does introduce a slight precision tradeoff, it makes it possible to run models on consumer hardware that would otherwise be impossible to load. For someone with 1.9TB of RAM, the calculus flips entirely: they can skip quantization altogether and load FP16 or BF16 full-precision models, avoiding any quality degradation.
Speculation on "Bonsai 2"
The poster mentioned considering running "Bonsai 2." This name doesn't map clearly to any widely known public project — it could be a niche or emerging open-source model, or perhaps a personal experimental direction. Given the limited information in the original post, this remains an open question.
From a naming convention standpoint, "Bonsai" (盆景, the Japanese art of miniature trees) is often used to describe models that have been carefully pruned — maintaining performance while reducing scale. If "Bonsai 2" follows that philosophy, running it on a 1.9TB RAM machine would be a bit like using a freight truck to deliver a single package. A more likely scenario: the user is planning large-scale parallel inference or training experiments.
The Barrier to Local Deployment Is Shifting
This post reflects a broader trend: as the open-source model ecosystem matures, more individuals and small teams are attempting to deploy large models on their own hardware rather than relying entirely on cloud APIs. The availability of used enterprise-grade hardware and memory-rich servers has brought compute capabilities that once belonged exclusively to large tech companies within reach of enthusiasts.
That said, getting the hardware is just the starting point. Choosing the right model, selecting an appropriate quantization strategy, and balancing speed against accuracy — these are the real technical challenges of local deployment. 1.9TB of RAM opens up an exciting solution space, but converting that raw resource into genuine productivity still demands serious work on the software stack and tuning side.
Final Thoughts
A short Reddit post, but behind it lies the growing enthusiasm of the local AI deployment community. For anyone with access to large amounts of system memory, the directions worth exploring include: loading ultra-large models at full precision, running multiple models in parallel, and pushing the boundaries of long-context inference. The real challenge isn't "can you fit the model" — it's "can you run it fast enough and well enough to be useful." Hopefully the poster follows up with real benchmark data, giving the community a clearer picture of how this class of hardware actually performs in practice.
Related articles
Which ChatGPT Plan Should You Choose? A Full Breakdown of Go, Plus, and Pro Subscriptions
Not sure which ChatGPT plan to pick? This guide breaks down Go, Plus, and Pro pricing, Codex quota differences (5x vs 20x), and how to pay with Alipay step by step.
ChatGPT Astra + Blender + Higgsfield: Testing an AI 3D Creative Workflow
A Bilibili creator tests a ChatGPT Astra + Blender + Higgsfield AI 3D workflow, turning a LEGO image into interactive 3D models, detailed PDFs, and cinematic videos.
GPT-6 Astra Promo Breakdown: The Future of Multi-Task AI Agents
A deep dive into the GPT-6 Astra promo: from progressive creative workflows and multi-task parallelism to cross-app operations and legal drafting — analyzing the vision and real-world challenges of next-gen AI Agents.