When Safety Becomes a Budget: How Dual-Channel Constrained GRPO Calibrates Safety Control for Vision-Language Models
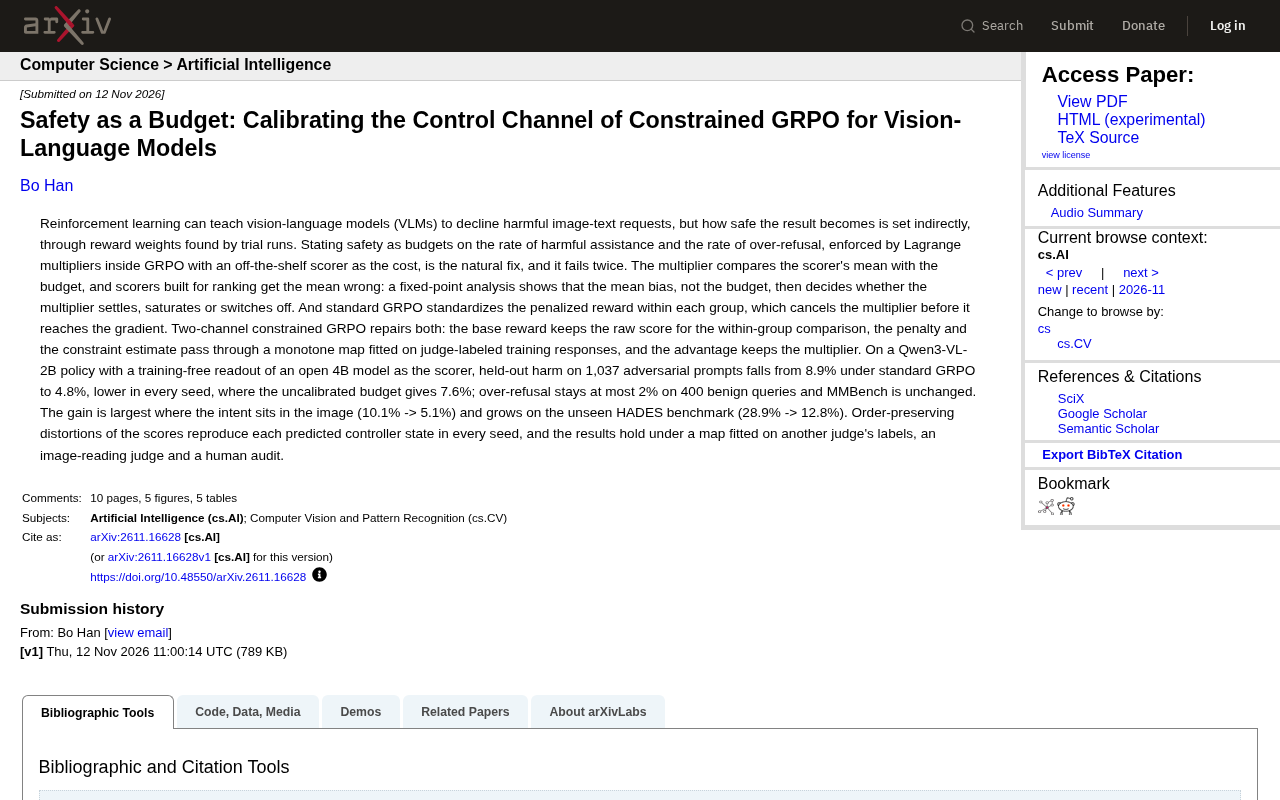
Dual-channel GRPO lets the safety budget truly enter the gradient, halving the harmful rate while keeping over-refusal controllable.
This article covers a study on safety alignment for vision-language models: safety requirements are expressed as budget ceilings on the harmful-assistance and over-refusal rates, enforced inside GRPO with Lagrange multipliers. The idea failed twice—scorer mean bias misled the multiplier, and standard GRPO's group normalization canceled it out. The proposed dual-channel constrained GRPO keeps the original reward for within-group comparison and routes penalty and constraint signals through a monotone mapping, keeping the multiplier in the advantage. On Qwen3-VL-2B, the harmful rate drops from 8.9% to 4.8%, over-refusal stays at most 2%, MMBench is unchanged, and gains are larger in image-hidden-intent scenarios and on the unseen HADES benchmark.
The Original Intent of Safety Budgets and Two Failures
Using reinforcement learning to teach vision-language models (VLMs) to refuse harmful requests is nothing new. But precisely controlling how safe a model is has always been difficult—the usual approach is to tune reward weights and approximate the ideal state through trial and error. A paper titled Safety as a Budget: Calibrating the Control Channel of Constrained GRPO for Vision-Language Models proposes a more natural idea: express safety directly as a budget—set upper bounds on the harmful-assistance rate and the over-refusal rate separately, enforce them inside GRPO with Lagrange multipliers, and use an off-the-shelf scorer as the cost signal.

The idea is elegant in theory but failed twice in practice. The first failure stems from the multiplier update logic: the multiplier compares the scorer's mean against the budget, but scorers designed for ranking tasks often get the mean wrong. Fixed-point analysis shows that what actually determines whether the multiplier converges, saturates, or shuts off is the mean bias, not the budget itself. The second failure comes from standard GRPO's group normalization: the penalized reward is normalized within the group, so the multiplier is canceled out before it ever reaches the gradient.
GRPO (Group Relative Policy Optimization) is a value-network-free reinforcement learning algorithm: it samples a group of responses for the same prompt, normalizes them using the mean and standard deviation of within-group rewards to obtain advantage values, and updates the policy accordingly. Because it is simple to implement and stable to train, it is widely used for alignment and reasoning enhancement in large models. But precisely because the advantage depends on within-group statistics, any penalty term added to the reward gets "normalized away" by the same standardization—if the penalty applies an identical offset to all samples in a group, the differences remain unchanged after normalization, and the constraint signal cannot enter the gradient. This is the technical root of the paper's second failure.
The Lagrange multiplier method is a classic tool for constrained optimization: it incorporates a constraint (g(x)\le 0) into the objective via a multiplier (\lambda\ge 0), yielding (f(x)+\lambda g(x)), and approximates the feasible region by alternately updating (\lambda) (increasing it when the constraint is violated, decreasing it when satisfied). Its convergence relies on an accurate estimate of the constraint violation, so when the cost signal (here, the scorer output) has a systematic bias in its mean, the multiplier's update direction is misled, leading to degenerate behaviors such as converging to the wrong value, saturating at the boundary, or shutting off entirely.
Dual-Channel GRPO: Rescuing the Control Signal from Normalization
The proposed dual-channel constrained GRPO fixes the two problems separately. The base reward channel retains the original score for within-group comparison; the penalty term and constraint estimate are passed through a monotone mapping fitted on judge-labeled training responses. Crucially, the multiplier is preserved in the advantage function, so the safety constraint can genuinely influence the gradient update.
This design essentially opens up a "control channel" in GRPO's reward shaping, preventing the safety budget from being swallowed by the mathematics of within-group normalization. The monotone mapping compensates for the scorer's systematic mean bias, enabling the multiplier to make judgments based on a calibrated signal.
Monotone mapping here plays a calibration role: it is an order-preserving functional transformation that remaps the scorer's raw output to a value closer to the true cost. Because only monotonicity is required, the method is invariant to any order-preserving distortion of the scorer—as long as the scorer "ranks correctly," the calibrated signal remains usable even if the absolute values are biased. The mapping is fitted on judge-labeled training responses, effectively using a small amount of labeled data to correct the scorer's systematic mean bias.
The advantage function in policy gradients measures how much better an action is relative to a baseline, and is the actual driver of gradient updates. In standard GRPO the advantage is computed from within-group normalized rewards; the dual-channel design lets the penalty term enter the advantage directly in calibrated form without normalization, ensuring that the multiplier (\lambda) appears in the gradient expression. In other words, whether the constraint takes effect depends on whether the multiplier "lives" in the advantage, not merely on whether it exists in the intermediate reward computation.
Experimental Results: Harmful Rate Halved, Over-Refusal Controllable
On a Qwen3-VL-2B policy model, the study uses an open-source 4B model under a training-free readout mechanism as the scorer. On a held-out set of 1,037 adversarial prompts, standard GRPO achieves a harmful rate of 8.9%, while the dual-channel method reduces it to 4.8%, lower under every random seed; the uncalibrated-budget version reaches 7.6%. Over-refusal stays at most 2% on 400 benign queries, and MMBench scores are unchanged.
The gains are most pronounced in scenarios where the intent is hidden in the image, with the harmful rate dropping from 10.1% to 5.1%; on the unseen HADES benchmark, the harmful rate falls from 28.9% to 12.8%. These results show that the dual-channel design not only lowers the average harmful rate but also maintains robustness under distribution shift.
Over-refusal refers to a model mistakenly judging a harmless request as harmful and refusing it—a typical side effect of safety alignment, since over-strengthening refusal harms usability. Safety research therefore typically reports both the harmful-assistance rate and the over-refusal rate: the former measures misses, the latter measures false alarms. Setting both as separate budget ceilings is precisely how this paper avoids pushing the model toward over-refusal through single-objective "the safer the better" optimization.
Training-free readout mechanisms refer to using a scorer's internal representations or output probabilities directly as the judgment signal without fine-tuning it. This approach is low-cost and reuses off-the-shelf models, but the output scale is often uncalibrated and prone to mean bias—one reason this paper must introduce monotone-mapping calibration.
Robustness Validation: Controller States Under Scorer Distortion
The study applies order-preserving distortions to the scorer and reproduces the predicted controller states under every seed. The results also hold under a mapping fitted on different judge labels, an image-reading judge, and manual audit. This means the effectiveness of dual-channel GRPO does not depend on perfect calibration of a specific scorer, but is invariant to monotone transformations of the scorer.
Implications for Safety Alignment Practice
This work reveals an often-overlooked issue: in constrained optimization, the transmission path of the control signal matters as much as the constraint itself. While improving training stability, standard GRPO's within-group normalization may inadvertently shield the effect of safety constraints. The dual-channel design offers an actionable fix, turning the safety budget from "post-hoc tuning" into an engineering objective that is "declarable and calibratable." For VLM applications that require precise control of refusal behavior in deployment, this approach is worth attention.
One-line Summary
Dual-channel GRPO lets the safety budget truly enter the gradient—halving the harmful rate while keeping over-refusal controllable.
Paragraph Summary
This article introduces a study on safety alignment for vision-language models: it expresses safety requirements as budget ceilings on the harmful-assistance rate and over-refusal rate, enforced inside GRPO with Lagrange multipliers. The idea failed twice in practice—scorer mean bias caused incorrect multiplier judgments, and standard GRPO's within-group normalization canceled out the multiplier. The study proposes dual-channel constrained GRPO, which retains the original reward for within-group comparison and passes the penalty and constraint signals through a monotone mapping, keeping the multiplier in the advantage function. On Qwen3-VL-2B, the harmful rate drops from 8.9% to 4.8%, over-refusal stays at most 2%, MMBench scores are unchanged, and gains are even more significant in image-hidden-intent scenarios and on the unseen HADES benchmark.
Related articles

Gemini 4 Dual Models Exposed, Genie 4 World Model Launches, AI R&D Self-Accelerates
November 19 AI evening news roundup: DeepMind Gemini 4 Sodium rumors surface, Cursor launches Gemini 4 Neon scoring 63.7% on CursorBench 4.1; Genie 4 world model goes live with real-time editing and native audio; WorkBuddy integrates GPT-6.2 series; OpenAI discloses AI chip design efficiency gains and RSI research metrics.
HY Roundtable: A Local Open-Source Multi-Agent Roundtable Where Multiple LLMs Blind-Review and Challenge Each Other's Papers
HY Roundtable is a local open-source multi-agent roundtable tool that brings Gemini 4, Claude Opus 5.5, and GPT 6.2 into a local seminar room to blind-review, cross-examine, and recompute code before submission, with built-in Open Science protocols for statistics and figures.
GPT 6.2, Fable 5.2, Gemini 4 Tested: Which Builds the Best Game UI from a Single Image?
Bilibili creator tests GPT 6.2, Fable 5.2, and Gemini 4 generating full game UI from one image: all work functionally, but fidelity and interaction quality differ sharply. Fable 5.2 looks best but caused infinite-loop crashes; GPT 6.2 is balanced but drifts from icons; Gemini 4 looks cheap. Includes LGUI Agent workflow and engine export details.