When the Subway Loses Signal, Offline AI Assistants Find a New Opening
Subway signal loss exposes AI tools' online dependency; on-device models and offline caching may be the breakthrough.
Starting from a tweet about subway disconnection and severed inspiration, the article analyzes the structural weakness of AI productivity tools' deep cloud reliance: in signal dead zones, creators' fleeting inspirations can't be captured by their tools. Vendors prioritize performance over availability, creating a stark experience gap. The article then explores offline AI feasibility — on-device small models and local cache preloading — noting that users value continuity more than feature completeness. It offers concrete offline workflow tips for creators and concludes that offline capability may become the key differentiator in the next phase of AI product competition.
Starting from a Tweet: Disconnection Anxiety and Creative Interruption
"how it feels to ride the subway and be disconnected from ur muse" — this tweet, paired with an image, precisely captures a daily predicament for modern creators: signal drops in the subway, and the flow of inspiration that depends on cloud-based AI tools is abruptly severed.
According to the source material, the author uses an image to convey this visceral sense of "disconnection." Although the image content isn't described in detail, in context it reads as a wry, helpless jab at "online dependency." Behind it lies a real product pain point: when AI assistants, note-taking apps, and inspiration-capture tools are all deeply tethered to the network, the experience gap in offline scenarios becomes glaringly obvious.
Online Dependency: A Structural Weakness of AI Tools
Most current AI productivity tools — whether conversational assistants, AI writing plugins, or cloud-based code completion — assume users are continuously connected. Subways, airplanes, elevators, and other signal dead zones are exactly where fragmented inspiration is most likely to strike, yet they are also the moments when these tools are most fragile.
This mismatch is no accident. Cloud inference relies on powerful compute, with model parameters often numbering in the billions — local devices struggle to handle them. Vendors prioritize performance over availability, and users are forced to accept the experience gap of "a dragon when connected, a worm when disconnected." The tweet author uses "disconnected from ur muse" to describe this state — emotionally closer to self-deprecating humor than anger, but the product-level problem is real.
The Feasibility of Offline AI: From On-Device Models to Local Caching
On-device small models are changing the picture. Quantization-compressed lightweight models can already handle text completion, inspiration capture, and simple Q&A on phones. While their capabilities fall short of cloud-based large models, they are sufficient to cover basic needs in "subway scenarios." Some note-taking apps have also begun supporting offline editing and local AI summaries, syncing to the cloud once connectivity returns.
Another path is smarter caching and preloading strategies: before a user enters the subway, automatically cache recently used context, materials, and conversation history locally, so a degree of continuity can be maintained when the network drops. This kind of engineering optimization doesn't require breakthrough model capabilities, yet it can significantly improve the felt experience of "inspiration disconnection."
Based on the scenario depicted in the tweet, users' sensitivity to "disconnection" often exceeds their demand for "feature completeness" — being able to jot down ideas and continue a conversation offline matters more than running a full large model in offline mode. This also provides a clear priority for product design: preserve continuity first, then pursue the capability ceiling.
On-device models refer to AI models that run directly on user devices (phones, PCs, tablets) rather than having data uploaded to cloud servers for processing. The core challenge lies in device compute, memory, and power constraints, so model compression techniques are typically required — such as quantization (converting floating-point weights to low-bit integers), pruning (removing redundant parameters), and knowledge distillation (using a large model to guide training of a small one) — to run smoothly on-device. In recent years, with the AI compute improvements of mobile chips like Qualcomm Snapdragon and Apple Neural Engine, and the maturation of inference frameworks like Llama.cpp and MLC-LLM, models under 7B parameters can achieve usable generation speeds on flagship phones. The biggest advantages of on-device models are privacy, low latency, and offline availability, but the trade-off is shallower knowledge breadth and reasoning depth compared to cloud-based large models.
Local caching and preloading in the context of AI applications refers to storing user's recent interaction context (such as conversation history, frequently used documents, and personal preferences) locally on the device, and prefetching potentially needed resources when the network is available. Its technical foundations include local databases (such as SQLite, IndexedDB) and offline-first web technologies like Service Worker. Unlike traditional HTTP caching, caching in AI scenarios must handle dynamically generated context windows and design reasonable expiration and synchronization strategies to avoid inconsistency between local and cloud states. This strategy doesn't depend on breakthroughs in model capability but rather ensures experience continuity through engineering means, so its implementation cost is low — suitable as a transitional solution before on-device models mature.
Creators' Offline Workflows: Keep the Muse Local
For creators who rely on AI assistance, rather than waiting for tools to evolve, it's better to proactively adjust workflows. A few actionable ideas: save your core inspiration library (notes, outlines, material snippets) locally with offline availability enabled; choose an input method or note-taking app that supports on-device AI as a "subway backup plan"; manually trigger a sync before entering signal dead zones to ensure critical context is saved locally.
These practices cannot fully replace the capabilities of cloud AI, but they can reduce the creative loss caused by "disconnection." The emotion in the tweet resonates precisely because so many people have experienced moments when inspiration strikes but cannot be recorded, or when a train of thought is flowing smoothly only to be interrupted by the network.
Conclusion: Offline Capability May Become an AI Product Differentiator
The subway disconnection scenario may be small, but it points to a larger product proposition: as AI tools increasingly intervene in creative workflows, availability is no longer just a "nice-to-have" — it's part of the baseline experience. On-device models, offline caching, and local-first data strategies are still at an early stage, but they may become the areas where AI products differentiate themselves in the next phase.
The muse shouldn't disappear just because there's no signal.
One-line Summary
Subway signal loss exposes the online dependency weakness of AI tools; on-device models and offline caching may be the breakthrough.
Paragraph Summary
Starting from a tweet about subway disconnection and severed inspiration, the article analyzes the structural weakness caused by current AI productivity tools' deep reliance on the cloud: in signal dead zones like subways and airplanes, creators' most fleeting inspirations cannot be captured by their tools. The article notes that vendors prioritize performance over availability, creating an experience gap of "a dragon when connected, a worm when disconnected." It then explores the feasibility of offline AI, including on-device small models (quantization-compressed to cover basic needs) and local cache preloading strategies, emphasizing that users' sensitivity to continuity exceeds their demand for feature completeness. Finally, it offers creators concrete ideas for building offline workflows and concludes that offline capability may become the key to differentiation in the next phase of AI product competition.
Related articles
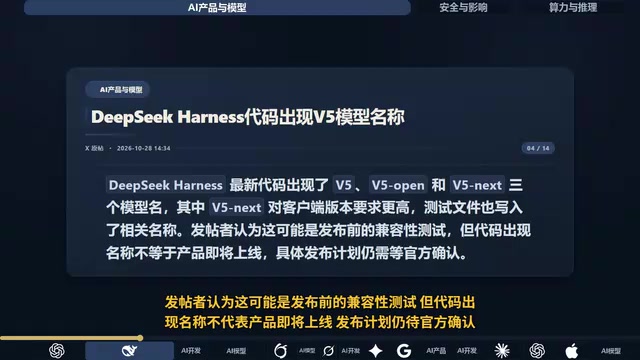
DeepSeek V5 Code Leak? It's Actually a Compatibility Test
AI Evening Report: DeepSeek Harness code shows V5 model names, deemed a compatibility test; Artificial Analysis V5 leaderboard released with DeepSeek tied for first among open-source models; Codex reset complete with news teased for tomorrow; coding agent security risks and OpenAI TPU procurement rumors analyzed.
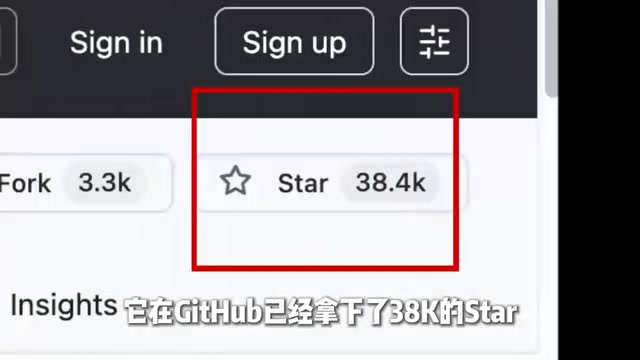
The AI Coding Terminal Built for DeepSeek: A Deep Dive into the 38K-Star Open Source Project
A deep dive into the open source AI coding terminal built for DeepSeek: 38K stars, 20 parallel agents, three security modes, and OS-level sandbox isolation for fully automated file reading, code editing, and command execution from a single-sentence requirement.
Wuzhen Conference Signals: Open Source Becomes China's Key Card for Changing Lanes and Overtaking in AI
The Wuzhen Internet Conference put open source and openness at center stage, with domestic open-source models from Huawei, Kimi, MiniMax, and DeepSeek showcased together. This article analyzes why open source has become China's key card for changing lanes and overtaking in AI, as well as the ecosystem standards battle, security governance, and commercialization challenges behind open source.