Where Does RAG Evaluation Noise Come From? The Judge or the Generator?

A decomposition experiment shows RAG evaluation noise sources vary by metric: faithfulness and relevancy come mainly from generated answers, recall and precision entirely from the judge.
This article analyzes run-to-run noise in RAG evaluation scores through a decomposition experiment. Using 15 papers, 18 questions, and k=8 retrieval, with gpt-oss-20b generating answers and Gemini 3.5 Flash Lite as judge, it computes four RAGAS metrics. Faithfulness variance is ~85% from generated answers, answer relevancy almost entirely from answers, while context recall and precision variance is 100% from the judge, since these two don't read generated answers. Judge temperature=0 still isn't repeatable due to random flips in claim counts and yes/no judgments. The author provides thresholds for comparing two single runs: ~0.15 for faithfulness, ~0.08 for relevancy, ~0.09 for recall, ~0.10 for precision. This overturns the earlier "optimal k=8" conclusion and suggests reproduction strategies vary by metric: recall and precision only need re-judging saved results, while faithfulness and relevancy require regenerating answers.
RAG system evaluation scores often fluctuate even when the configuration stays the same. Is this noise coming from the LLM judge's inconsistent scoring, or from the generator writing different answers each time? A developer ran a decomposition experiment on their own system, and the conclusion may be counterintuitive.
Key Finding: Noise Sources Differ Drastically by Metric
The experiment was based on 15 research papers, 18 evaluation questions, and a retrieval setting of k=8. The generator used gpt-oss-20b on Groq, the judge was Gemini 3.5 Flash Lite, and four metrics—faithfulness, answer relevancy, context precision, and context recall—were computed via RAGAS 0.2.15.
The key conclusion: about 85% of the run-to-run variance in faithfulness comes from the generated answers, answer relevancy comes almost entirely from the answers; while 100% of the variance in context recall and context precision comes from the judge—because RAGAS does not read the generated answers when computing these two metrics at all. They only compare the retrieved chunks against the question and reference answer. Given deterministic retrieval, regenerating answers cannot possibly change these two scores.
According to data the author recorded during the experiment, when only re-judging the same batch of saved answers, the standard deviation of the 18-question mean ranged from 0.021 (faithfulness) to 0.035 (precision); after regenerating answers, the standard deviation of faithfulness rose to 0.054, and relevancy rose from 0.002 to 0.028.
RAGAS (Retrieval-Augmented Generation Assessment) is an open-source framework for evaluating RAG pipelines that defines four core metrics requiring no human annotation. Faithfulness measures whether every claim in the generated answer can be inferred from the retrieved context; it works by extracting atomic statements from the answer and verifying each one with an LLM. Answer relevancy evaluates how relevant the answer is to the question—traditionally by having an LLM reverse-engineer possible questions from the answer, then computing the embedding similarity between the generated questions and the original question. Context precision checks how many of the retrieved chunks are actually relevant and whether relevant chunks are ranked near the top; context recall measures how much of the information in the reference answer is covered by the retrieved context. Among these four metrics, the first two require reading the generated answer, while the latter two depend only on retrieval results and the reference answer—so their noise sources are inherently different.
Judge Temperature Set to 0 Still Doesn't Repeat Itself
The author originally assumed that setting the judge's temperature to 0 would yield consistent output, but the experiment showed otherwise. When judging the same answers and chunks three times, the 18-question mean for precision fluctuated by 0.085, faithfulness by 0.042, and recall by 0.046; only relevancy remained relatively stable at 0.003.
The reason lies in how each metric is constructed. Faithfulness first splits the answer into claims and then verifies them one by one, but the number of claims the judge extracts from the same passage varies—one answer was split into 5, 10, and 11 claims across three runs, and when the denominator moves, the score moves. Precision and recall consist of yes/no judgments; among 148 chunk judgments, 5 flipped across the three runs, and among 22 reference-statement judgments, 3 flipped. Since 14 of the 18 reference answers consist of a single sentence, recall on those questions is either 0 or 1—a single flip takes the whole question from 1 to 0. Relevancy is stable because it has the judge write out the question the answer seems to be responding to, then compares it with the real question using an embedding model; the embedding step smooths over the judge's phrasing differences.
The LLM temperature parameter controls sampling randomness. Theoretically, setting it to 0 should perform greedy decoding—always selecting the highest-probability token—producing deterministic output. In practice, however, even with temperature=0, outputs can still be inconsistent. Reasons include: non-determinism in GPU floating-point operations (different parallel reduction orders causing tiny numerical differences), server-side batching and caching strategies, and the fact that some APIs do not implement strict greedy decoding at temperature=0. Additionally, some RAGAS metrics (such as faithfulness) involve multi-step LLM calls (first extracting claims, then verifying each one), and tiny fluctuations at each step accumulate. For yes/no judgments, the model's sensitivity to prompt format, context length, or even line breaks can cause borderline samples to flip. Therefore, temperature=0 can only reduce—not eliminate—run-to-run variance, especially in multi-step reasoning and classification tasks.
A 0.15 Threshold Invalidates the Previous "Optimal k"
Based on the measured noise, the author provides reference thresholds for comparing two single runs: roughly 0.15 for faithfulness, 0.08 for relevancy, 0.09 for recall, and 0.10 for precision (at the 18-question scale; about 40% wider on a 9-question subset). What this means is that the mean difference between two configurations, each run once, must exceed this threshold before it deserves serious attention.
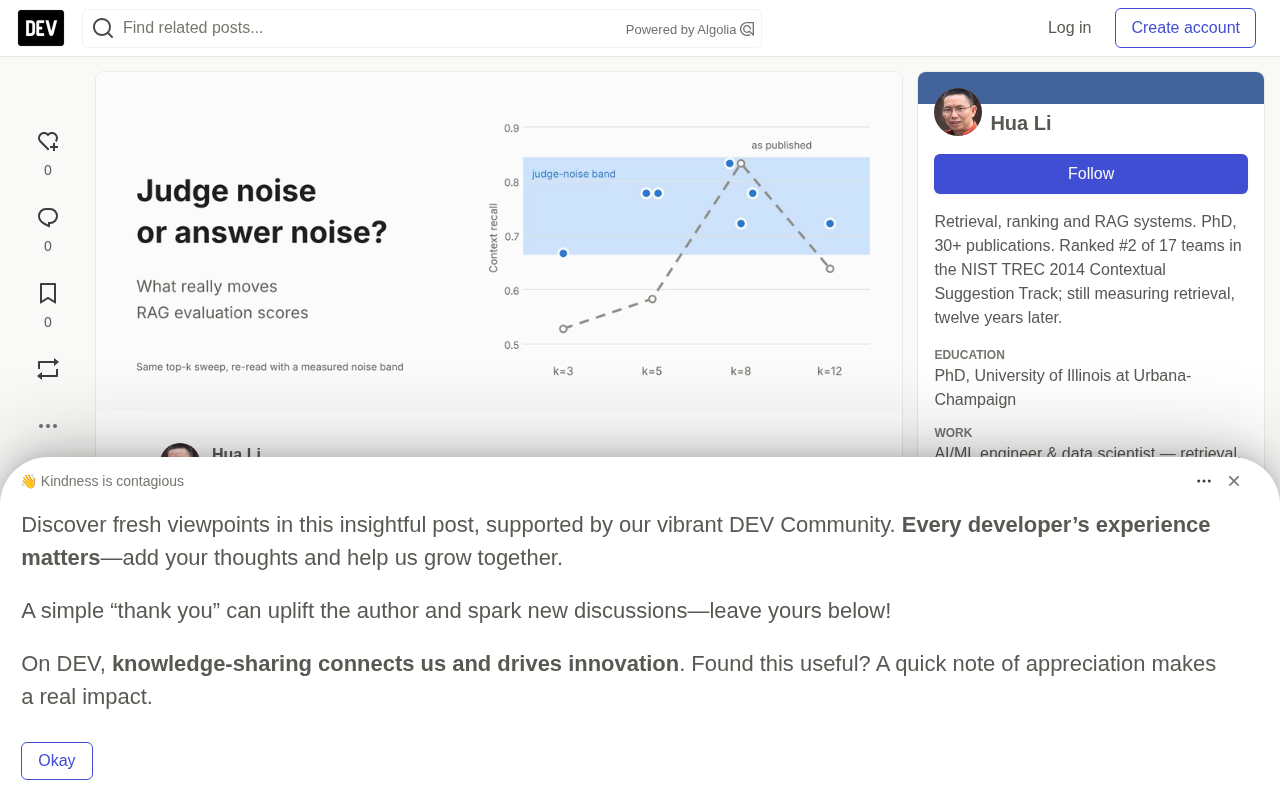
Applying these thresholds back to the author's previous top-k sweep, the conclusion no longer holds. The original "optimal k=8" had two problems: first, runs with different k covered different question sets—the k=8 run with 0.83 recall covered only 9/18 questions, and the judge failures happened to be on the harder questions; second, each configuration was run only once. When all runs are unified onto the same 9 questions, the curve flattens between 0.67 and 0.83, and all seven runs fall within the judge noise band—the sweep simply cannot distinguish between k values.
In statistical hypothesis testing, the p-value represents the probability of observing the current or a more extreme result when the null hypothesis is true; typically p<0.05 is considered significant. But significance does not equal practical importance—especially with large samples, where tiny differences can be significant. Effect size quantifies the actual magnitude of a difference, for example Cohen's d or the mean difference. The "threshold" proposed in this article is essentially a minimum detectable effect based on the noise standard deviation, similar to power analysis in experimental design. When the mean difference between two runs is smaller than the noise band, one cannot distinguish true configuration differences from random fluctuation. The author derived the threshold by multiplying the standard deviation of the 18-question mean by a factor (about 2-3x), which corresponds to roughly a 95% confidence interval overlap judgment. For small samples (such as a 9-question subset), standard deviation estimates are unstable, and the threshold needs to be widened by about 40%—consistent with statistical theory.
Old Conclusions Overturned and Reinforced
The author reviewed the previous judgments one by one. "k=3 retrieval is insufficient" was downgraded from a conclusion to a hint—k=3 had the lowest recall on the matched question set (0.67, versus an average of about 0.77 for other runs), but the gap is below the 0.13 threshold at the 9-question scale, and it all comes from a single question. "The judge model has a larger impact than the k parameter" was actually reinforced: switching the judge model moved recall by 0.31 and faithfulness by 0.26—three times and nearly twice their respective thresholds.
The reason "significance testing found no difference" is also clear now: 14 single-sentence reference answers force recall to be either 0 or 1, so any two configurations that retrieve the same relevant chunk will tie exactly, leaving the Wilcoxon test with no usable information.
What to Reproduce Depends on Whether the Metric Reads the Answer
This is the most practical takeaway of the article: for recall and precision, simply re-run the judge on saved results—this also saves generation calls; for faithfulness and relevancy, you must regenerate answers—because re-judging alone captures only about 15% of faithfulness variance, making it look more than twice as stable as it actually is.
The author also recommends: freeze the question list before scoring and report every row of results along with the reason for any missing values (0.833 and 0.833 (9/18) are two different claims); when you can annotate the documents that should be retrieved for each question, compute recall@k with simple counting—under deterministic retrieval, such metrics have no run-to-run noise at all; and write reference answers as multiple verifiable claims to avoid single-sentence references turning recall into a coin flip.
Run-to-run variance decomposition is a common method in experimental science: by repeatedly measuring different sources (such as the generator and the judge), one estimates their respective contributions to total variance. In this article, the author either fixed the judge and regenerated answers, or fixed the answers and re-ran the judge, thereby separating answer noise from judge noise. Similarly, in machine learning, cross-validation variance is often decomposed into model variance and data variance. For RAG evaluation, understanding variance sources helps design efficient reproduction strategies: if judge noise dominates, you only need to re-judge; if answer noise dominates, you must regenerate. In addition, reporting confidence intervals or standard errors is more reliable than point estimates—especially with small samples (such as 18 questions), where the standard error of the mean can be large and a single run's score may deviate from the true mean by several standard deviations.
Failure Cases Reveal Metric Blind Spots
A per-question view also exposes several scoring failures. One question asked which paper won the best paper award; the correct answer was "none." All three generations answered correctly, but faithfulness scored 1.00, 0.33, and 0.00 respectively—a negation cannot be verified against the chunks. Another question asked which cognitive biases the paper covers; one generation honestly said the paper did not name specific biases, and relevancy gave it 0; another generation confidently listed a bias that does not exist in the corpus, and relevancy gave it 0.58—only faithfulness caught the fabrication (0.17). This is exactly why relevancy should not be looked at in isolation.
Missing scores also have fixable causes: out of about 1,200 judge calls, two failed due to JSON escaping format errors; on one day the judge responded ten times slower, and context precision timed out on 16/18 questions—because RAGAS's timeout limit covers all calls for a single question and single metric, and precision at k=8 makes 8 judge calls per question. Without logging by cause, these all become NaNs that silently shrink the average.
The author has open-sourced the complete experiment code and raw judge outputs, and plans to rewrite the 13 single-sentence reference answers as multiple claims and re-judge, to verify whether judge noise on recall can be reduced. The value of this approach lies not in the specific thresholds—they apply only to this small system of 15 papers and 18 questions—but in the evaluation habit of "measure the noise first, then compare configurations."
One-line Summary
A decomposition experiment shows that RAG evaluation noise sources vary by metric: faithfulness and relevancy come mainly from generated answers, recall and precision come entirely from the judge; judge temperature=0 is still unstable, and comparing configurations requires exceeding the noise threshold.
Paragraph Summary
This article analyzes the run-to-run noise sources of RAG system evaluation scores through a decomposition experiment. Based on 15 papers, 18 questions, and k=8 retrieval, using gpt-oss-20b to generate answers and Gemini 3.5 Flash Lite as the judge, it computes four RAGAS metrics. It finds that about 85% of faithfulness variance comes from generated answers, answer relevancy comes almost entirely from answers, and context recall and precision variance comes 100% from the judge, since the latter two do not read generated answers. Judge temperature=0 still cannot guarantee repeatability, due to random flips in claim splitting counts and yes/no judgments. The author gives thresholds for comparing two single runs: about 0.15 for faithfulness, 0.08 for relevancy, 0.09 for recall, and 0.10 for precision. This overturns the previous "optimal k=8" conclusion and suggests reproduction strategies vary by metric: recall and precision only need re-judging saved results, while faithfulness and relevancy require regenerating answers.
Related articles

macOS Is No Longer UNIX: Apple Didn't Renew Certification, But the Technology Is Unchanged
Apple did not renew macOS's UNIX certification, and the Open Group has removed Apple's entry. This article analyzes the technical reality behind the expiration, Apple's possible intentions, and the practical impact on developers.

Building Stateful Multi-Agent Systems with Azure Cosmos DB
Based on the official Azure Cosmos DB tutorial, this article explains how to use the Agent Memory Toolkit to add shared persistent memory to a multi-agent travel planner, covering short-term, long-term, episodic, and semantic memory plus cross-session state continuity.

Production AI Agent Operations: A Three-Step Framework for Observing, Evaluating, and Optimizing
Azure Cosmos DB team proposes a three-step framework for production AI Agent operations: observe trace tracking, evaluate with LLM as a judge and regression testing, optimize cost across RU, retrieval, memory, and LLM layers.