White House Accord on Super Intelligence Signed: Google Commits to Responsible AI Development

Google signs White House AI accord, signaling a shift from corporate self-regulation to government-industry governance.
Google CEO Sundar Pichai joined U.S. officials and tech leaders to sign the White House Accord on Super Intelligence and the Joint Commitment on Frontier Responsibilities — a milestone in AI governance moving toward government-industry collaboration. Google has invested hundreds of billions across its full AI stack and mandates testing, evaluations, and red-teaming before any model release. Pichai frames public trust as a core competitive resource alongside compute and talent. Whether these voluntary commitments can evolve into auditable, accountable mechanisms remains the key question.
White House Accord on Super Intelligence Formally Signed
The relationship between the tech industry and the U.S. government is entering a new phase. According to a post by Google CEO Sundar Pichai on social media, he met with the President, Vice President JD Vance, Speaker Johnson, and leaders from both government and the tech sector — and together they signed the White House Accord on Super Intelligence.
This signing marks a shift in AI governance: from corporate self-regulation toward an institutionalized model of government-industry collaboration. On the topic of super intelligence — still exploratory, but widely regarded as a defining technology of the future — a direct, formal dialogue between officials and leading companies is itself a meaningful signal.
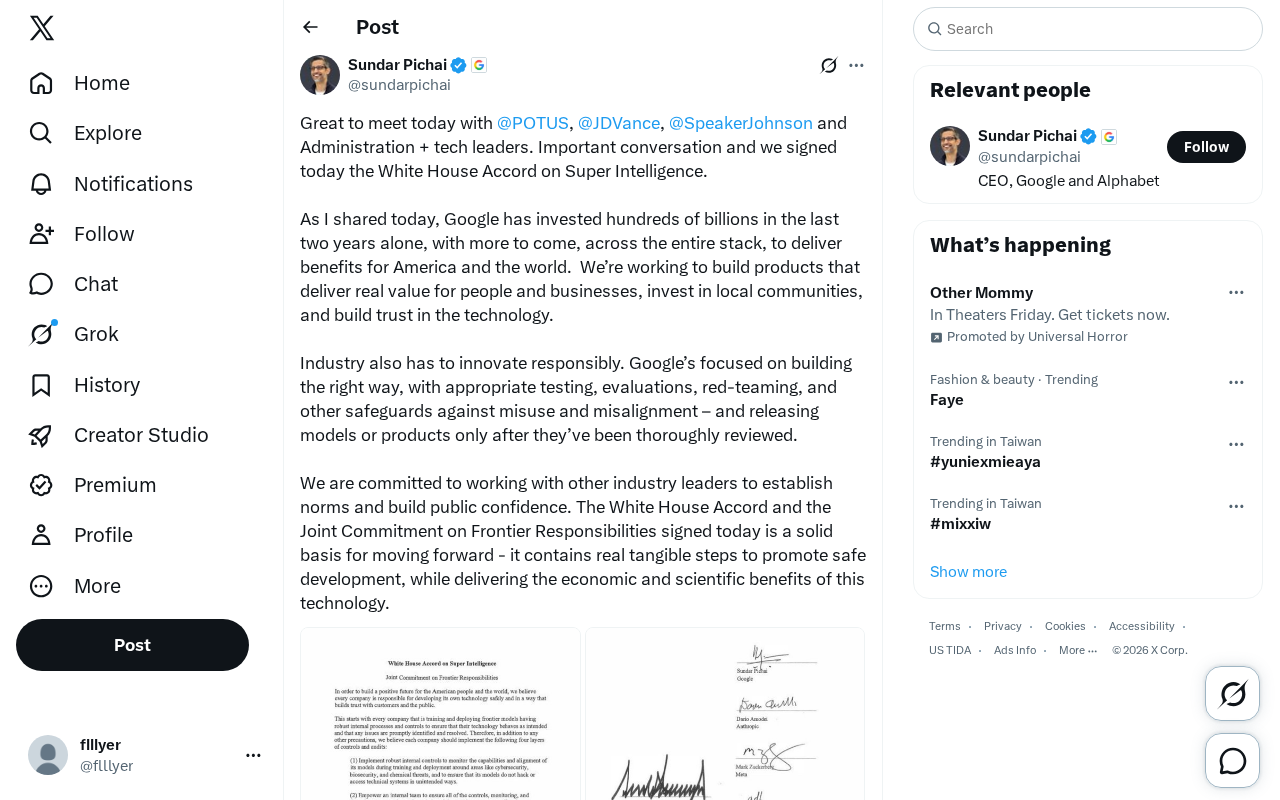
Google's Massive Investment and Full-Stack Strategy
In his remarks, Pichai emphasized that Google has invested hundreds of billions of dollars over the past two years, with more to come. These investments span the entire stack — from underlying compute infrastructure and model training to consumer and enterprise-facing products.
This full-stack approach reflects Google's core ambition: not just to train more powerful models, but to translate that technology into real value for individuals and businesses. Pichai specifically highlighted three priorities: building products that deliver genuine value, investing in local communities, and earning public trust in the technology.
From an industry perspective, the fact that "trust" is called out separately suggests that leading companies now recognize that technical superiority does not automatically translate into social acceptance. In a world where super intelligence could have far-reaching consequences, public trust is becoming as critical a competitive resource as compute and talent.
Responsible Innovation: Testing, Evaluations, and Red-Teaming
One of the most noteworthy aspects of the accord is the specificity around "responsible innovation." Pichai explicitly stated that Google employs proper testing, evaluations, red-teaming, and other safeguards against misuse and misalignment when building AI — and that models or products are only released after thorough review.
What Is Red-Teaming and What Is Misalignment Risk?
Red-teaming is a proactive security practice in which a dedicated team simulates attackers or adversarial use cases to surface risks before they become real-world problems. "Misalignment" refers to situations where an AI system's behavior deviates from the designer's intentions or human values — one of the central concerns in cutting-edge AI safety research.
By treating these mechanisms as hard prerequisites before any release, Google is positioning safety evaluation not as an afterthought, but as a built-in step in the product development process. If this approach becomes an industry standard, it could meaningfully reduce the systemic risks of large-scale deployment.
In the AI field, red-teaming has migrated from cybersecurity and evolved into its own distinct practice. In practice, testers attempt to coax models into producing harmful content, bypassing safety filters, generating misinformation, or gradually breaking through preset constraints over multi-turn conversations. Leading labs like OpenAI, Anthropic, and DeepMind all maintain dedicated red teams, and some organizations bring in independent external security researchers for additional evaluation. The misalignment problem runs even deeper: a model may perform well on benchmarks, yet exhibit unexpected behaviors in real-world deployment due to flaws in the objective function, biases in training data, or reward hacking. The more capable the model, the harder it becomes to reverse the consequences of misaligned behavior — which is precisely why AI safety researchers treat it as the highest-priority threat in the context of super intelligence.
Industry Consensus and the Joint Commitment on Frontier Responsibilities
Beyond the White House Accord, Pichai also referenced the Joint Commitment on Frontier Responsibilities, which was also signed that day. He described both documents as "a solid foundation to advance the work," saying they contain "real, actionable steps" that promote safe development while delivering the economic and scientific benefits of the technology.
Pichai stated that Google is committed to working with other industry leaders to establish industry norms and build public confidence. This reflects a key judgment: that self-regulation by any single company is insufficient to address the full scope of risks posed by super intelligence — and that cross-company, cross-government coordination is essential to establish shared ground rules.
How to promote safety without sacrificing innovation speed or economic returns will be the long-term test of whether these agreements hold. Whether they can evolve from principled commitments into auditable, accountable mechanisms remains to be seen.
The Joint Commitment on Frontier Responsibilities is the other key document from this meeting, reportedly co-signed by Google, OpenAI, Anthropic, Microsoft, and other leading AI companies. "Frontier" in the AI context refers specifically to the most capable large-scale models at the cutting edge — those that typically cost hundreds of millions of dollars to train and carry fundamentally different risk profiles compared to ordinary commercial AI products. Multi-party commitments of this kind face a common structural challenge: there is no independent verification body, compliance standards are interpreted by the companies themselves, and the commitments carry no legal force. By contrast, the EU AI Act takes a mandatory compliance approach, with clear legal liability provisions for high-risk systems. Both paths involve tradeoffs. The U.S. has chosen to begin with voluntary agreements — whether this gradually evolves into a binding regulatory framework will be the central lens through which its real-world effectiveness is judged.
Conclusion: From Corporate Self-Regulation to Institutionalized Governance
This meeting and the agreements signed mark an important inflection point in AI governance. Direct dialogue between leading tech companies and senior government officials — culminating in written agreements on safe development — provides a starting point for rule-making in the age of super intelligence.
For the industry as a whole, three forces are now converging: massive investment, full-stack positioning, and responsible innovation. Those who can achieve both technical leadership and public trust, while operating within governance frameworks, will be better positioned to lead in the next competitive phase. Whether this accord can truly take hold and carry real accountability will determine whether it is a symbolic gesture — or the beginning of a substantive governance framework.
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.