Why Are AI Models Becoming Increasingly "Identical"? How Distillation and RL Are Fueling a Monoculture Crisis
Distillation and RL are systematically compressing AI output diversity, pushing the industry toward a monoculture.
A growing number of open-source models learn through distillation from a handful of leading models like Claude, while reinforcement learning from human feedback further converges their outputs toward a narrow set of "safe" patterns. Distributional analysis reveals that these models repeatedly reuse the same themes and character names — fluent on the surface, but sampling from a shrinking template pool. The deeper risk is a full-blown AI monoculture: shared biases and blind spots amplify systemic fragility, and if future models keep training on AI-generated content, diversity will be filtered away iteration by iteration.
Today's AI models are quietly converging. Ask different large language models to write a story, draft marketing copy, or simply answer the same question — and you'll often find the output style, word choices, and even character names are strikingly similar. Behind this convergence lies a structural problem in how AI is trained: model diversity is being systematically compressed.
Distillation Dependency: Everyone Is Learning from the Same "Teacher"
One key driver is the highly concentrated source of training data. Many open-weight models are learning through distillation from a small handful of leading models — with Claude being one of the most frequently distilled.
Distillation is essentially a process where a "student model" imitates the output behavior of a "teacher model." When the entire open-source ecosystem uses the same model as its learning reference, the outcome is predictable: these models inherit the same linguistic habits, the same expressive preferences, and even the same cognitive patterns. This isn't just a technical choice — it's a collective path dependency. It's cheaper and faster, but the cost is a homogenized output across the entire ecosystem.
Knowledge Distillation was first systematically formalized by Hinton et al. in 2015. The core idea is to have a smaller student model learn from the "soft labels" (soft logits) of a larger teacher model — that is, the probability distribution over the output layer, rather than just hard-label answers. This allows the student model to acquire the teacher's generalization capabilities with fewer parameters and less compute. In the era of large language models, distillation has further expanded to include the teacher model's full output text (output distillation), where the student model internalizes the teacher's language style, reasoning chains, and value orientations through supervised fine-tuning on that text. This mechanism is precisely what enables "style contagion": when Claude's outputs become training data for dozens of open-source models, Claude's preferred sentence structures, opening phrases, and ways of framing caveats are all replicated en masse — and these "soft features" are almost never detected by standard evaluation benchmarks.
After RL, Diversity Is Sharply Reduced
Beyond distillation, the reinforcement learning (RL) phase is another critical variable. The source material notes that after RL training, models show "a marked decrease in output diversity and begin to develop fixed little ticks."
The underlying logic here is worth examining. RL typically optimizes model behavior using some reward signal — such as human preferences or specific scoring criteria. But when a model is repeatedly pushed toward the "high-score zone," it gradually converges on a small number of validated "safe strategies." In other words, RL makes models "better," but also makes them "narrower." They learn how to consistently score well, but at the cost of their ability to explore different modes of expression.
The RL referred to here typically means Reinforcement Learning from Human Feedback (RLHF) or variants like RLAIF and DPO (Direct Preference Optimization). The training pipeline works as follows: human annotators rank preference among multiple model outputs, those preference signals are used to train a reward model, and then algorithms like PPO guide the language model to update toward higher-reward outputs. The problem is that human annotators share common preferences about what makes a "good output" — clear structure, friendly tone, measured wording — and these preferences get learned and amplified by the reward model. As a result, models learn to avoid any "risky expression" that might lower their score, including stylistic experiments, unconventional narrative perspectives, or deliberately ambiguous or understated writing. The stronger the reward signal and the more training rounds applied, the more complete this "safe convergence" becomes — and the model's actual expressive space shrinks proportionally.
What Distributional Analysis Reveals
On the surface, these models appear to write quite well — sentences are fluent, structure is coherent. But when you run distributional analysis, the problems surface.
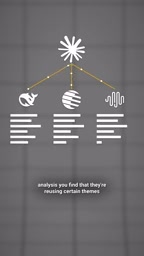
Analysis shows that these models repeatedly gravitate toward certain specific themes in their writing, and even consistently use the same character names. This is telling: the models aren't truly "creating" — they're repeatedly sampling from a relatively narrow distribution. The "fluency" you see is repetitive fluency; the "capability" you sense is actually a small number of templates baked in through training.
For a one-off user, this may not matter much — a coherent paragraph is often good enough. But viewed at the ecosystem level, it means a vast volume of AI-generated content is drawing from an ever-shrinking "pool of expression."
One Good Style Is Not the Same as Many Diverse Styles
The source material raises a pointed contrast: AI model outputs resemble "one very good style," rather than the rich diversity found across human authors.
This distinction matters enormously. The value of human writing lies precisely in its variety — different authors bring radically different sensibilities, rhythms, and worldviews, and it is this difference that constitutes cultural richness. Current AI models, even when individually high-quality, simply converge everyone toward the same "optimal solution." What you get is a polished, unified voice — not a polyphonic chorus.
The Looming Risk of Monoculture
Connecting these threads, a troubling trend emerges: the AI field is developing a "monoculture."
Distillation ensures everyone shares the same source; RL causes each model to converge further; the end result is a highly homogenized output style across the entire industry. The risks of this monoculture go well beyond "boring content." In ecology, monoculture crops collapse entirely when a single disease strikes; in AI, if all models share similar biases, blind spots, and failure modes, the entire system's vulnerability to certain types of problems is amplified.
Looking further ahead, if future models continue to be trained on content generated by previous AI models, this convergence could form a self-reinforcing loop — diversity gets filtered out round after round, until only the most "standard" fraction remains. How to actively preserve output diversity while pursuing model performance may be one of the most important structural challenges AI training needs to confront.
The self-reinforcing loop described here is known in research as "Model Collapse" or the "data contamination" problem. Multiple studies in 2023 found that when models are iteratively trained on text generated by themselves or similar models, the output distribution narrows with each generation: low-frequency but real linguistic patterns disappear first, long-tail knowledge degrades next, and eventually models trend toward generating only high-frequency, "average" expressions. This is mechanistically analogous to inbreeding depression in ecology — once diversity in the gene pool (or training data pool) declines, a population's ability to adapt to novel pressures systematically weakens. For AI, once a particular type of input triggers a blind spot shared by all models (such as a specific category of logical fallacy or cultural bias), the entire ecosystem fails simultaneously, with no "heterogeneous" model available to offer a different reference or correction. Actively introducing diversity constraints into training data and incorporating distributional diversity metrics into evaluation frameworks are the main countermeasures currently proposed by researchers.
Related articles

LynnReal-Omni: 32B Unified Video Diffusion Model Goes Open Source with Multi-Task Coverage in Four Steps
LynnReal-Omni is a 32B unified video diffusion model on MiniMax H3, covering text-to-video, pose guidance, style transfer, restoration in 4 steps. Flash version generates 540p video in 377ms on one H100.

Anthropic Co-Founder: AI 'Kill Switch' May Need to Be Mandatory by Law
Anthropic's co-founder tells the BBC that AI 'kill switches' may need to be legally mandated. We analyze the industry logic, technical challenges, and the tension between regulation and innovation.

The AI Data Center Boom Is Colliding With Cities Scarred by Heavy Industry
The AI data center boom is clashing with post-industrial communities. Philadelphia's case reveals structural conflicts between AI growth, energy use, water, and environmental justice.