48 AI Agents Found a Maya Pyramid in 72 Hours — and Exposed an Awkward Problem

48 AI agents found an unregistered Maya site in LIDAR data but missed existing survey records.
A digital archaeology experiment had 48 AI agents scan ~2,000 km² of NASA LIDAR data overnight, hunting for "straight lines nature wouldn't produce." They identified an unregistered plaza and pyramid in Mexico, confirmed by the government as having no official record. But it turned out archaeologists had already surveyed the site in 2025. The case shows AI's dual nature: multi-agent parallelism greatly boosts large-scale terrain analysis, yet agents that only read raw data and skip the literature systematically ignore existing knowledge. The author recommends cross-referencing archaeological databases and journals, with human experts judging true discoveries — otherwise efficiency may just be efficient repetition.
A "Digital Archaeology" Session with Striking Efficiency
A researcher dispatched 48 AI agents to scan the Mexican jungle, tasking them with finding lost Maya sites in NASA LIDAR data. According to details disclosed in a YouTube video and Hacker News discussion, the agents covered roughly 2,000 square kilometers of terrain data, analyzing overnight and specifically hunting for "straight lines that nature wouldn't produce" — the classic clue archaeologists use to identify man-made structures.
The results came fast: they identified an unregistered plaza and pyramid structure within Mexico. Government authorities confirmed that the site indeed had no official record.
From a pure efficiency standpoint, this is a rather eye-catching demonstration. 48 digital "interns" worked through the night, outpacing a tired human researcher.
LIDAR (Light Detection and Ranging) is an active remote sensing technology that generates high-precision 3D terrain models by firing laser pulses at the ground and measuring the time difference of reflected echoes. In archaeology, LIDAR can penetrate dense jungle canopies to reveal building outlines, roads, terraces, and other man-made traces hidden beneath vegetation. NASA's GEDI mission and airborne LIDAR projects have accumulated vast amounts of such data, giving archaeologists an unprecedented macro perspective. Maya civilization research is one of LIDAR's most successful application cases — in 2018, LIDAR revealed tens of thousands of ancient structures in the Guatemalan jungle, fundamentally changing estimates of the Maya population scale. For this reason, scanning LIDAR data for "straight lines" with algorithms has become a standard method for finding sites.
The Twist: The Site Had Already Been Surveyed
The story takes a turn here. According to the Hacker News discussion, this site had actually been surveyed by archaeologists in 2025 — it just hadn't entered the official registry.
In other words, what the AI found was not a city "never discovered by humans," but a city "not officially catalogued." The government's confirmation of "no record" is factually true, but "no record" does not equal "no one knows about it."
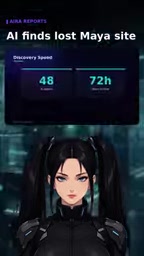
This distinction may seem like splitting hairs, but it actually touches on a core weakness of AI-assisted research: when the agents scanned LIDAR data for straight lines, they did not search existing archaeological literature or survey archives. They found something "new" while missing "old" knowledge.
In archaeology, "discovery" and "formal registration" are two different things. Survey is an academic research activity — archaeological teams conduct fieldwork, record, and map an area, with results typically published in papers or academic reports. National registries (such as Mexico's INAH site registry) are official administrative records used for protection, management, and public outreach. A site may be surveyed but unregistered due to administrative delays, conservation strategy considerations, or unpublished data. Therefore, an "unrecorded" site found by AI may already have been described in detail in academic literature. This reminds us that judging a "new discovery" requires cross-referencing academic databases (such as JSTOR and archaeology journals) as well as official registries — not just government registration status.
Efficiency Gains and Knowledge Blind Spots Are Two Sides of the Same Coin
The persuasiveness of this case lies precisely in how it simultaneously reveals two faces of AI.
The positive side is obvious: LIDAR data is enormous, manual inspection is time-consuming, and AI agents can process large-scale terrain in parallel and without interruption, scaling pattern-recognition tasks like "finding straight lines" to a level humans can hardly match. The researcher's approach of splitting tasks among 48 agents in parallel also demonstrates the practical feasibility of multi-agent collaboration for large-scale geographic data analysis.
The flip side is methodological: an agent that only stares at raw data and doesn't read literature is essentially an intern with zero memory. It won't know that a certain patch of jungle was surveyed by an archaeological team the previous year, nor will it proactively cross-reference existing databases. The question posed in the source material is spot-on — are we automating "discovery," or automating the act of "missing the map"?
The Right Way to Do Multi-Agent Archaeology
This doesn't mean multi-agent approaches lack value — it means task design needs to add the step of "retrieving existing knowledge." A more reasonable workflow would be roughly: after agents flag candidate structures in LIDAR data, first cross-reference them against archaeological databases, paper repositories, and local registries, then have human experts determine which are genuinely new discoveries.
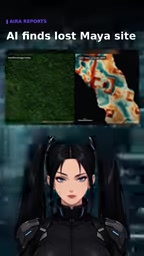
The quip in the source material is precise: 48 digital interns found a lost city faster than one tired human. But speed advantages only translate into real scientific progress once connected to humanity's accumulated knowledge base. Otherwise, AI is merely rediscovering what humans already know with greater efficiency.
For teams focused on putting AI into practice, the lesson from this case extends beyond archaeology: any scenario where agents process raw data directly needs a companion knowledge-retrieval mechanism — otherwise "efficient" may just mean "efficiently repeating work."
One-line Summary
48 AI agents found an unregistered site in LIDAR data — but missed existing survey records because they didn't read the literature.
Related articles

Gemini 4 Neon Review: Benchmark Scores Rival Carbon, API Pricing and Quota Breakdown
Google Gemini 4 Neon is now live, benchmark scores closely tracking Carbon, API pricing 3/15 at twice Hydrogen's rate. This article compiles Bilibili creator testing: Neon can replace 90% of Carbon scenarios, AntiGravity quota consumption is only one-third of Carbon, plus subscription channel restrictions and 2API ban risks.

Gemini 4 Helium Coming Soon? Signals of Google Loosening Subscription Restrictions
Google team member hints releases will continue; community speculates Gemini 4 Helium (Flash Lite) may be next. Subscription ban controversy gets a response as product lead says "Soon," suggesting restrictions may be lifted. This article covers Gemini developments, OpenAI Coding Agent and risk management, Doubao real-time audio-video API, and compute business dynamics.

AI-Assisted React Development in Practice: Optimizing a Video App and Handling Errors
A 14-year veteran developer demonstrates AI-assisted React video app optimization: compressing video from 80MB to 5MB (~94%) via ImageKit, plus reliable error handling and retry mechanisms. Includes planning, code understanding, and verification methods for working with AI.