AI Digital Twin in Action: Using DOT to Automatically Track Bugs and User Feedback

DOTS engineer demos a complete workflow using an AI digital twin to collect cross-platform feedback, triage bugs, and submit PRs.
The article describes how DOTS team engineer Rennie Song used an AI digital twin named Benny to take over feedback collection and bug troubleshooting. Benny has an independent desktop environment and can receive tasks via page @ mentions or voice calls. It scrapes feedback across Reddit, Twitter, and other platforms, structurally updating the tracker—adding 15 entries to reach 210 in one morning. In theme analysis, it categorized issues into silent stalls, connection problems, and continuity failures, ranking silent stalls as most urgent based on user trust cost rather than defect count. It also opened parallel threads to investigate root causes, selected the low-risk, high-reward greeting model failure for a PR, fully recorded the investigation timeline for human review, and refused to fabricate missing statistics.
When engineers start handing off both "collecting feedback" and "troubleshooting bugs" to their own AI digital twin, what does the workflow look like? On a YouTube channel, DOTS team engineer Rennie Song demonstrated a fairly complete approach: he named his DOT (an AI agent that can independently operate a computer) Benny, and had it gather feedback across platforms, categorize themes, open threads to investigate root causes, and even submit PRs directly. The entire process involved no scripting or orchestration—it was driven entirely by conversation and @ mentions within the page.
How the Digital Twin Takes Over Feedback Collection
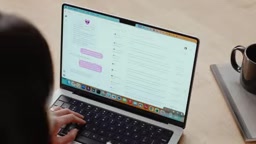
Rennie's DOT comes with its own dedicated space, within which he created a feedback page. The biggest value of this page is the split-screen view: structured data on the left, the digital twin's working environment on the right, allowing users to freely customize how they want things displayed. Rennie's requirements were very specific—all feedback must be categorized, color-coded, and presented in table form.
His method of operation was extremely simple: he typed a single sentence into the page—"Update the external feedback tracker with the latest feedback from Reddit and Twitter"—and left the rest to Benny. Meanwhile, in the split screen you can see Benny operating a browser on its own "computer," searching for tweets from that day containing DOT and OpenAI.
This design transforms the AI agent from "an answer machine in a chat window" into "a colleague with its own desktop." You can see where it's clicking and what it's searching for—this observability is crucial for building trust.
DOT (Digital Operator Twin) is the DOTS team's term for "an AI agent that can independently operate a computer." It is essentially an intelligent agent running in an isolated desktop environment: it has its own browser, file system, and operating permissions, and can click, type, and scroll pages just like a real person, rather than merely generating text in a chat window. Unlike conventional RPA (Robotic Process Automation), DOT does not rely on pre-written scripts but is driven by natural language instructions and @ mentions within the page, with a large model planning the next action in real time. This architecture allows the agent to handle changes in web page structure and ad-hoc tasks, but it also means its behavior needs to be continuously observed and audited—which is why the demo emphasizes "split-screen observability."
Voice Command: Letting the AI Summarize Problem Themes on Its Own
In addition to assigning tasks via the page, Rennie also demonstrated assigning analysis tasks to Benny directly via voice call—reviewing external feedback from the past two days to identify the main themes and the categories where problems are most concentrated.
Benny's conclusions fell into three major buckets: silent stalls, connection issues, and continuity failures. Specific manifestations included: DOT claiming to be working but never completing, notebook connections dropping, and contacts being lost when switching between voice/chat/code.
One detail worth noting: Benny explicitly stated that connections and integrations were the largest category, but admitted it lacked clean statistics for the past two days and therefore refused to fabricate precise rankings. This "say you don't know when you don't know" behavior is rare in an era when AI agents are generally prone to inventing numbers.
Prioritization: User Trust Matters More Than Number of Fixes
When Rennie asked which problem was most urgent, Benny's answer was not ranked by count but by trust cost: silent stalls came first, with the reasoning that "if it suddenly goes quiet, people won't trust it."
This criterion comes from an understanding of user psychology rather than simple defect counting. Rennie then assigned two parallel tasks: one to open a cloud thread to dig into the root cause of silent stalls, succeeding if it could find a few specific causes; the other to pick the easiest problem to fix right now and submit a PR directly.
The "easiest fix" Benny selected was greeting model failure: when a new DOT requests a model the user has no access to, the creation flow is blocked outright, whereas the reasonable approach is to fall back to a model available to the user. This is a typical low-risk, high-reward patch.
Silent stalls refer to a state where an agent or service stops producing any visible output and reports no errors during operation, yet never returns a final result. This is harder to diagnose than an explicit error: there is no exception stack in the logs, and users only see a "processing" spinner—they neither know whether to wait nor whether to retry. For AI agent products, this failure mode directly erodes trust—users will gradually suspect whether the agent is actually working and eventually abandon it. That is why Rennie's team ranked it ahead of connection issues, based not on frequency of occurrence but on the degree of damage each occurrence does to user confidence.
Transparent Investigation and Closed-Loop Delivery
The most informative part of the entire demo was Benny laying out the investigation process fully on the page: it recorded reasoning and verification steps step by step, and finally reported that only one backend greeting failure was confirmed—precisely the same issue discussed on the call—and found that the team was already working on a fix PR.
On the feedback tracker side, Benny added 15 new entries, bringing the total to 210. The silent stall investigation identified one definite failure mode and attached an investigation timeline for human review.
Rennie's summary was that a morning's worth of work was largely offloaded to the digital twin, with only two entry points for tasks: @ mention it in the page, or call it on the phone. This combination of "dual-channel assignment + auditable process" is why this workflow can truly be put into practice.
Greeting model refers to a lightweight model request that the system automatically invokes when a new user first creates a DOT, used to generate a welcome message or complete the initialization greeting flow. The defect discovered in the demo was that this request uses a specific model by default; if the current user has no access to that model, the entire creation flow is blocked outright instead of falling back to a model within the user's permissions. This is a typical "permission boundary without degradation handling" problem—low fix cost and clear impact scope—which is why Benny selected it as the easiest entry point for a PR.
Implications for AI Agent Workflows
This demo reveals several reusable lessons. First, put the agent into a container with clear deliverables—tables, trackers, PRs—rather than letting it just output a block of text. Second, retain human review checkpoints; Benny attached a timeline instead of jumping straight to conclusions. Third, allow the agent to admit when data is incomplete—this has more engineering value than giving beautiful but fabricated statistics.
It is worth noting that this is a team member's demo of their own product, and the presentation has a somewhat idealized quality; the actual coverage rate and misjudgment rate of cross-platform scraping were not quantified in the video. But as a workflow example of "AI agents participating in defect triage," it already provides sufficiently concrete reference.
One-line Summary
A DOTS engineer demonstrates a complete workflow using an AI digital twin to collect feedback across platforms, triage bugs, and submit PRs.
Paragraph Summary
The article describes how DOTS team engineer Rennie Song used an AI digital twin named Benny to take over feedback collection and bug troubleshooting. Benny has an independent desktop environment and can receive tasks through two channels: page @ mentions or voice calls. It scrapes feedback across Reddit, Twitter, and other platforms and structurally updates the tracker, adding 15 entries to reach 210 in one morning. In theme analysis, it categorized issues into silent stalls, connection problems, and continuity failures, and ranked silent stalls as most urgent based on user trust cost rather than defect count. It also opened parallel threads to investigate root causes, selected the low-risk, high-reward greeting model failure for a PR, fully recorded the investigation timeline for human review, and refused to fabricate missing statistics.
Related articles

Why Transistors Are No Longer Flat: The Evolution from Planar to Gate-All-Around
Transistor evolution from planar to FinFET to gate-all-around: why gates went from three-sided to four-sided wrapping to suppress short-channel effects and leakage current, extending Moore's Law.

Swarm Intelligence = a Single RL Agent? A Proof of Multi-Armed Bandit Equivalence
A paper proves that collective decision-making through local imitation in swarms is mathematically equivalent to single-agent reinforcement learning: N blind imitators act as N parallel environment samples, with an effective learning rate of 1/N. This article explains the derivation and implications of the Maynard-Cross Learning algorithm.
OpenAI Stops Training AI Models on Real-Time Internet Data, Citing Significant Risks
OpenAI will no longer train frontier AI models on real-time internet data, citing significant risks. This analysis examines the safety rationale, engineering reality, and industry impact of the strategy shift.