AI System Retroactive Changes Trigger a Trust Crisis: The Core Challenges of Transparency and Auditability

How retroactive AI system changes erode trust—and why transparency and auditability are essential.
A Reddit post about unexplained retroactive system changes reveals a fundamental AI governance challenge. This article defines retroactive changes, distinguishes them from model drift, and explores black box opacity, auditability gaps, immutable logs, and regulations like GDPR and the EU AI Act to build trustworthy automated systems.
The Deeper Questions Behind an Online Discussion
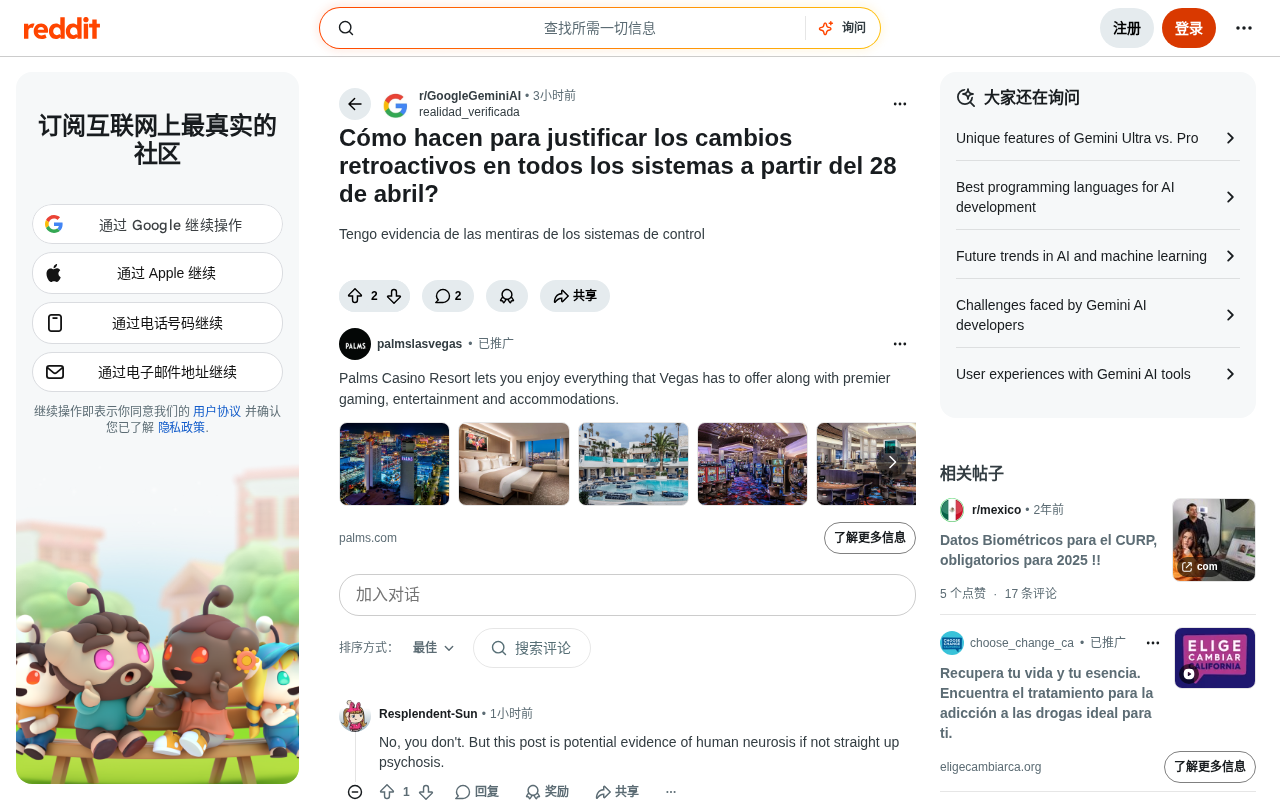
Recently, a Spanish-language post from Reddit sparked widespread discussion within tech communities. The poster raised a pointed question: "How do they justify the retroactive changes (cambios retroactivos) that have appeared across all systems since April 28th?" and claimed to "have evidence that the control system is lying."
The post was brief and emotionally charged, yet it touched on an increasingly urgent topic in the AI era: When automated decision-making systems are modified without users' knowledge—even making retroactive adjustments to historical data—how do we build and maintain trust in these systems?
What Are "Retroactive Changes"?
Concept Explained
"Retroactive changes" refer to a system modifying data or decisions that have already occurred and been recorded, after the fact. In traditional software engineering, such operations are typically subject to strict controls because they undermine data consistency and auditability.
It's worth noting that retroactive changes are not a new problem unique to the AI era. In traditional database engineering, "data migration" and "backfill" operations have long existed, but these operations are usually constrained by strict change management processes requiring testing, approval, and notification. Entering the machine learning era introduced new complexity—behind the same API endpoint, entirely different model versions may be running at different times, and service level agreements (SLAs) often lack clear provisions on this.
Academia refers to this phenomenon as a special variant of "Model Drift," but understanding this concept requires distinguishing between two fundamentally different situations. Model drift is typically divided into two categories: data drift and concept drift. The former refers to the statistical distribution of input data changing over time, while the latter refers to the relationship between inputs and outputs themselves changing. Both types of drift occur passively—they are natural reflections of real-world changes within the model. Retroactive changes, by contrast, are a form of active, human intervention, motivated by fixing bugs, optimizing performance, or responding to regulatory requirements. The essential difference between the two is: drift is the system's response to its environment, while retroactive changes are humans' intervention in the system. Understanding this distinction is crucial for establishing governance frameworks—the former requires a monitoring system, the latter requires a change management system. Unlike naturally occurring shifts in data distribution, retroactive changes are behavioral changes actively introduced by humans, and their scope of impact and predictability are far harder to assess.
In AI and automated systems, retroactive changes primarily appear in three forms:
- Silent model updates: The service provider replaces or fine-tunes the underlying model without notifying users, causing the same input to produce different outputs.
- Recalculation of historical records: Recomputing past scores, credit, rankings, or other data according to new rules.
- Retroactive application of policies: Applying new rules retroactively to behavior that occurred before the rules took effect.
Why Retroactive Changes Are Concerning
For users or businesses that rely on these systems to make decisions, retroactive changes mean that past certainty is shattered. Judgments made yesterday based on system results may no longer hold up today. When a "control system" can rewrite historical records at will, users lose the very basis for appeal and verification—this is precisely the core anxiety expressed by that poster.
Behavioral economics research shows that the building and destruction of trust are markedly asymmetric: building trust requires consistent, predictable behavior over the long term, while a single major opaque change is enough to destroy it. In the commercial context of AI systems, this asymmetry manifests as concrete economic costs: user migration costs, compliance litigation risks, brand reputation damage, and—hardest to quantify yet most far-reaching—the trust discount across the entire industry. Multiple 2023 surveys on enterprise AI adoption rates pointed out that "concerns about the unpredictability of AI decisions" is one of the primary factors hindering enterprises from deploying AI systems. This means transparency is not only an ethical requirement but also an important component of business value. From this perspective, investing in change management processes and auditable infrastructure yields returns not only in risk avoidance but also in the accumulation of a long-term user trust premium.
The Core Challenges of AI System Transparency
The Black Box Problem: Invisible Decision Logic
Modern AI systems, especially applications based on large language models and deep learning, inherently possess a "black box" nature. This characteristic has deep technical roots: large language models represented by the Transformer have billions or even hundreds of billions of parameters, obtained through gradient descent optimization, whose internal logic cannot be directly translated into human-readable rules.
The field of Explainable AI (XAI) is attempting to provide post-hoc explanations of individual decisions using techniques such as LIME and SHAP. LIME (Local Interpretable Model-agnostic Explanations) constructs a perturbed dataset around the target sample and trains a locally interpretable linear model to approximate the complex model's local behavior; SHAP (SHapley Additive exPlanations) borrows the concept of Shapley values from game theory to quantify each feature's marginal contribution to the final prediction. But both have fundamental limitations: the explanation itself is an approximation of the model's behavior, not a faithful reconstruction of the model's internal logic; different explanation methods may give contradictory conclusions for the same prediction; and when the model is updated, all previously generated explanations become invalid, leaving users unable to compare before-and-after differences. These methods are essentially approximate solutions and cannot provide a complete causal chain. The deeper challenge is that even developers themselves struggle to predict the model's behavior under all edge conditions, making "change impact assessment" technically difficult to accomplish comprehensively—which is precisely why explainability techniques are hardest to apply in retroactive change scenarios.
Users typically have no way of knowing:
- Which version of the model the system is currently running;
- The specific rules or weights on which decisions are based;
- When and for what reason the system underwent changes.
When opacity is compounded by retroactive modification, the problem is amplified further: users not only struggle to understand current decisions but cannot even reliably trace "what happened in the past."
The Absence of Auditability: Who Can Prove History?
The poster claimed to "have evidence," and this statement points precisely to a key need in technical governance: auditability. A responsible AI system should have complete change logs and version control, capable of answering the following questions:
- What was the system's state at a specific point in time?
- Which changes were applied, who approved them, and when did they take effect?
- Was historical data modified, and on what basis?
However, the reality is that many commercial AI services, out of consideration for protecting trade secrets or reducing engineering costs, do not offer any audit capabilities to ordinary users, planting the seeds of a trust crisis.
How to Build Trustworthy Automated Systems
Immutable Logs: Making History Impossible to Quietly Tamper With
The industry is gradually forming a consensus: critical decision systems should adopt immutable log technology. The core design principle of immutable logs is "Append-Only"—write only, no modification—which has mature practices in the database field, such as Apache Kafka's log storage and PostgreSQL's WAL (Write-Ahead Log) mechanism.
In engineering practice, immutable logs are not a single technology but a collection of design patterns. Apache Kafka's Log Segment mechanism achieves high-throughput append-only storage through sequential writes and offset-based indexing; for AI audit scenarios, a more practical solution is often a log system based on Content-Addressable Storage: each record is addressed by the hash of its content, so any tampering causes the hash value to change and is immediately detected. The trusted timestamp protocol defined in RFC 3161 provides legally valid time proof for log entries and is a key infrastructure component for building a trustworthy audit chain.
Drawing on the design philosophy of blockchains or append-only databases, once a historical record is written it cannot be overwritten; any change can only be appended as a new record, fundamentally guaranteeing the traceability of data. It's worth noting that applying blockchain to AI system auditing is not without cost: storage overhead is high, write latency is significant, and there is inherent tension between the privacy protection of on-chain data and audit transparency. A more practical industrial approach is usually a centralized log system combining Trusted Timestamping with cryptographic signatures, striking a balance between performance and trustworthiness.
Change Notification Mechanisms: Proactive Disclosure, Not After-the-Fact Explanation
When a system undergoes substantive changes (especially those that may affect historical data), a responsible service provider should proactively inform users of:
- The specific content and scope of the change;
- The effective time point of the change;
- The potential impact on historical data;
- The measures users can take to respond.
This is not only a necessary step for building trust but also a basic threshold for responsible operation.
Appeals and Human Review: A Safety Net for High-Risk Decisions
For automated decision-making systems involving high-risk scenarios such as credit assessment, qualification review, and employment screening, human review and appeal channels must be retained. This is both a requirement of technical design and an explicit legal norm.
Article 22 of the EU's GDPR clearly stipulates that data subjects have the right "not to be subject to a decision based solely on automated processing," and requires data controllers to provide meaningful explanations, appeal channels, and human intervention options when making high-impact automated decisions. The EU AI Act, which officially took effect in 2024, further classifies AI systems by risk level and establishes a systematic tiered regulatory framework: dividing AI systems into four levels—unacceptable risk (prohibited, such as social credit scoring systems), high risk (mandatory compliance, such as employment screening, credit assessment, critical infrastructure management), limited risk (transparency obligations, such as chatbots), and minimal risk (voluntary guidelines). For high-risk AI systems, the Act requires the mandatory establishment of a risk management system, retention of detailed technical documentation and operational logs, and re-conducting compliance assessments when major changes occur—meaning that if a retroactive change affects the expected performance of a high-risk AI system, it directly triggers a re-certification obligation, constraining opaque system modifications at the institutional level. The emergence of these regulations marks a shift in AI governance from a stage of industry self-regulation to one of legal enforcement, exerting a profound demonstrative effect on AI system design worldwide.
From an Individual Case to a Systemic, Universal Problem
Although the specific context of this post is unclear—there is no way to confirm whether the "system" the poster referred to was a financial platform, a government service, or some type of AI application—the problem it reflects is enough to prompt reflection across the entire tech industry.
As AI and automated systems continue to permeate daily life—from loan approvals to content recommendations, from social welfare to job screening—the trustworthiness of systems is no longer merely a technical issue but a social matter concerning fairness, justice, and individual rights.
When an ordinary user posts a challenge on an online forum asking "how do they justify this," it is itself a genuine response to insufficient technical transparency. It reminds every system designer and operator: Once trust is eroded by retroactive, opaque changes, the cost of rebuilding it will be extremely high.
Conclusion: Not How to Justify, but How to Avoid
This brief post may never become a tech news headline, but in a blunt and even indignant manner, it raises one of the most fundamental questions in the field of AI governance. In an age where algorithms increasingly dominate decision-making, what we need is not just more powerful AI, but more transparent, more auditable, and more accountable AI systems.
For every organization building automated systems, the answer should not be "how to find excuses for opaque changes," but rather "how to avoid, from the very beginning of the design, putting users in a position where they cannot verify anything."
Key Takeaways
Key Takeaways
Related articles

CSS Anchor Positioning: A New UI Positioning Approach Without JavaScript
A deep dive into CSS Anchor Positioning: from anchor-name and position-anchor to the anchor() function, position-area shorthand, position-try-fallbacks, anchor-size, and upcoming anchor queries.

New AI Chart Interaction: Continuous Follow-up Questions and Visualization in Conversation
Explore a new AI interaction method for continuously generating charts in conversation. Use the /visualize command to ask follow-up questions and visualize answers in the same chat window, improving data analysis efficiency.

Cursor Merges Into X Subscription: Paid Plans Share Unified Usage Pool, Grok Model Coding Usage Doubled
Cursor joins The X Subscription with a unified usage pool and doubled Grok coding quota. Third-party models shift to API pricing. Existing users can keep or migrate plans.