Anthropic Releases Mythos and Fable Models, RSI Concerns Emerge
Anthropic releases Mythos and Fable, citing gains in coding, reasoning, vision, and communication, while sparking RSI concerns.
Anthropic launched Mythos and Fable, claiming improvements in coding, reasoning, vision, and clearer user communication, in line with current large-model competition trends. But disclosure is restrained, with no benchmark data or comparisons, so gains await third-party and real-world verification. Reports also mention RSI (recursive self-improvement) concerns, though available material does not detail them or their direct link to the new models. Readers are advised to watch for official technical reports, third-party validation, and Anthropic's safety statements.
Anthropic recently launched two new models—Mythos and Fable. According to the company, both models show improvements in coding, reasoning, and vision, as well as in communicating more clearly with users. The news was first disclosed via RSS channels, but along with the new models came concerns about RSI (recursive self-improvement).
Core Improvements of the New Models: Coding, Reasoning, Vision, and Communication
According to official statements, the improvements in Mythos and Fable span multiple dimensions. Coding capability remains a key focus, and reasoning and vision are also on the list of enhancements. Another easily overlooked but equally critical point is "communicating more clearly with users"—this suggests the models may have been optimized in expression style, instruction following, and interaction experience.
These improvement directions align with the main themes of current large-model competition: code generation and understanding are essential for developer scenarios, reasoning capability determines the ceiling for complex tasks, vision capability relates to the deployment of multimodal applications, and communication clarity directly affects user experience and trust. By listing all these dimensions at once, Anthropic signals its intention to achieve comprehensive capability upgrades in both new models.
However, the official disclosure is relatively restrained, providing no specific benchmark data or performance comparisons. Therefore, the actual magnitude of these "improvements" still needs to be verified through subsequent real-world use and third-party evaluations.
Benchmarks are a common means of comparing large-model capabilities, with well-known examples including HumanEval and SWE-bench for coding, GPQA and MATH for reasoning, and MMMU for multimodality. When vendors release new models, publishing benchmark scores serves both to provide comparable evidence of capability and to enable third-party reproduction and verification. This article notes that the official announcement "provided no specific benchmark data," which means outsiders cannot currently judge the extent of improvement of Mythos and Fable relative to previous-generation models or models from other vendors, nor can they rule out the possibility that the "improvements" are reflected only in specific tasks or specific prompt styles. Benchmarks themselves have limitations: issues such as data contamination, overfitting to evaluation sets, and disconnection from real-world usage scenarios mean that even if data is published later, it still needs to be combined with real-world feedback for comprehensive judgment.
RSI Concerns: The Other Side of Efficiency Gains
The report's title specifically mentions "RSI concerns" (recursive self-improvement concerns), which is a noteworthy backdrop surrounding the new model release. RSI refers to the ability of AI systems to participate in improving themselves or subsequent AI systems; once an accelerating loop forms, it may bring challenges in safety and controllability.
Anthropic has long focused on AI safety. The simultaneous emergence of a new model release and RSI concerns indicates that the industry remains alert to the tension between capability enhancement and self-improvement risks. It should be noted that the available material does not elaborate on the specific content of the RSI concerns, nor does it explain the degree of direct association between those concerns and Mythos or Fable. Therefore, this is more of a signal requiring continued observation rather than a clear conclusion.
At a stage of rapid model capability iteration, how to balance the pace of safety evaluation and capability release is an unavoidable question for Anthropic and the entire industry.
Recursive self-improvement (RSI) is a core concept in the AI safety field, foreshadowed as early as I. J. Good's 1965 "intelligence explosion" hypothesis: if a system can design a next-generation system stronger than itself, it may form a positive feedback loop that causes capabilities to surge dramatically in a short time. In the modern context, RSI does not require AI to fully autonomously rewrite its own code; as long as it can significantly accelerate the AI R&D process—for example, by automatically proposing architectural improvements, generating training data, optimizing training recipes, or autonomously conducting alignment research—it can be regarded as partially realizing recursive improvement. The main concerns surrounding RSI include: the rate of capability growth may exceed the pace at which safety evaluation and regulation can keep up; if the direction of improvement deviates from human intent, the difficulty of correction will amplify as system capabilities rise; and human oversight links in the R&D chain may be gradually diluted. Anthropic has discussed risk thresholds for this kind of "AI R&D automation" in its "Responsible Scaling Policy," so it is not surprising that the new model release has been linked to RSI discussions.
Cautious Interpretation Under Multi-Source Information
Currently, information about Mythos and Fable comes mainly from official statements and brief reports from RSS channels, leaving limited room for cross-verification across multiple sources. The official emphasis on improvements in coding, reasoning, vision, and communication is directional description lacking quantifiable details; the RSI concerns appear in the report's title, but the body does not elaborate in depth.
For developers and readers following AI progress, a more pragmatic approach is to watch whether the official side subsequently publishes benchmark data and technical reports, pay attention to third-party evaluations verifying coding and reasoning capabilities, and track Anthropic's public statements on safety. The actual performance of the new models will ultimately be tested by usage feedback in real-world scenarios.
(Note: This article is written based on available material; some details await further official disclosure.)
One-line Summary
Anthropic released two new models, Mythos and Fable, which the company says improve coding, reasoning, vision, and communication while also raising RSI concerns.
Paragraph Summary
Anthropic launched two new models, Mythos and Fable, which the company says show improvements in coding, reasoning, vision, and communicating more clearly with users—directions consistent with the main themes of current large-model competition. However, the official disclosure is restrained, with no benchmark data or performance comparisons, so the extent of improvement awaits third-party evaluation and real-world verification. The report's title also mentions RSI (recursive self-improvement) concerns—the safety and controllability challenges that may arise when AI participates in improving itself or subsequent systems—though the available material does not elaborate on the specific content of these concerns or their direct connection to the new models. The article suggests readers follow official technical reports, third-party capability verification, and Anthropic's safety statements, and view this release with a cautious attitude.
Related articles
How Do Cursor, Devin, TRAE, and Copilot Compare on Price? Calculate Your Credits Before You Compare Monthly Fees
Side-by-side comparison of individual and team pricing for Cursor, Devin Desktop, TRAE, and Copilot, breaking down credit rules, third-party model inclusion, overage billing, and practical methods for measuring usage before paying, setting spending caps, and choosing the right tool.
Copilot Retires Three Models: Pro Users Left With Only One Alternative
GitHub Copilot retires Claude Opus 4.8, Claude Opus 5, and GPT-5.6 Tera on Nov 16 across Chat, code completion, and Agent mode. Pro users have only GPT-6 Luna left; Legacy annual plans miss Opus 5.5; admins must enable replacements manually.
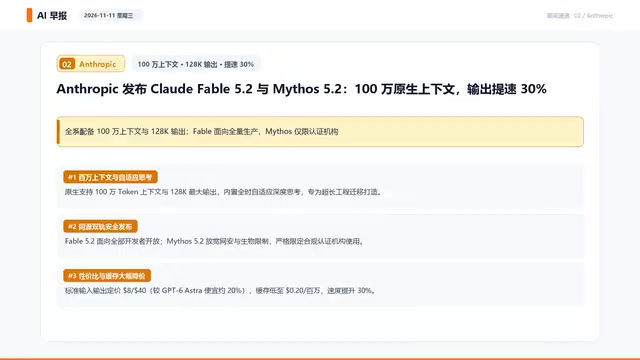
Gemini 4 Carbon Arrives: The LLM Race Enters the Era of Million-Token Context and Trillion-Parameter Open Source
Google launches Gemini 4 Carbon and multi-agent tool Swarm; Anthropic debuts million-context Fable 5.2 and Mythos 5.2; OpenAI releases security-focused GPT-6 Cyber; Mistral and Kimi open-source trillion-parameter models — the LLM race accelerates across the board.