Asymmetric Loop Transformer: A New Paradigm with Fixed Global Representations and Iterative Decoding

AsymLoop separates single-pass context encoding from recurrent state refinement, improving looped language models with lower perplexity and higher accuracy.
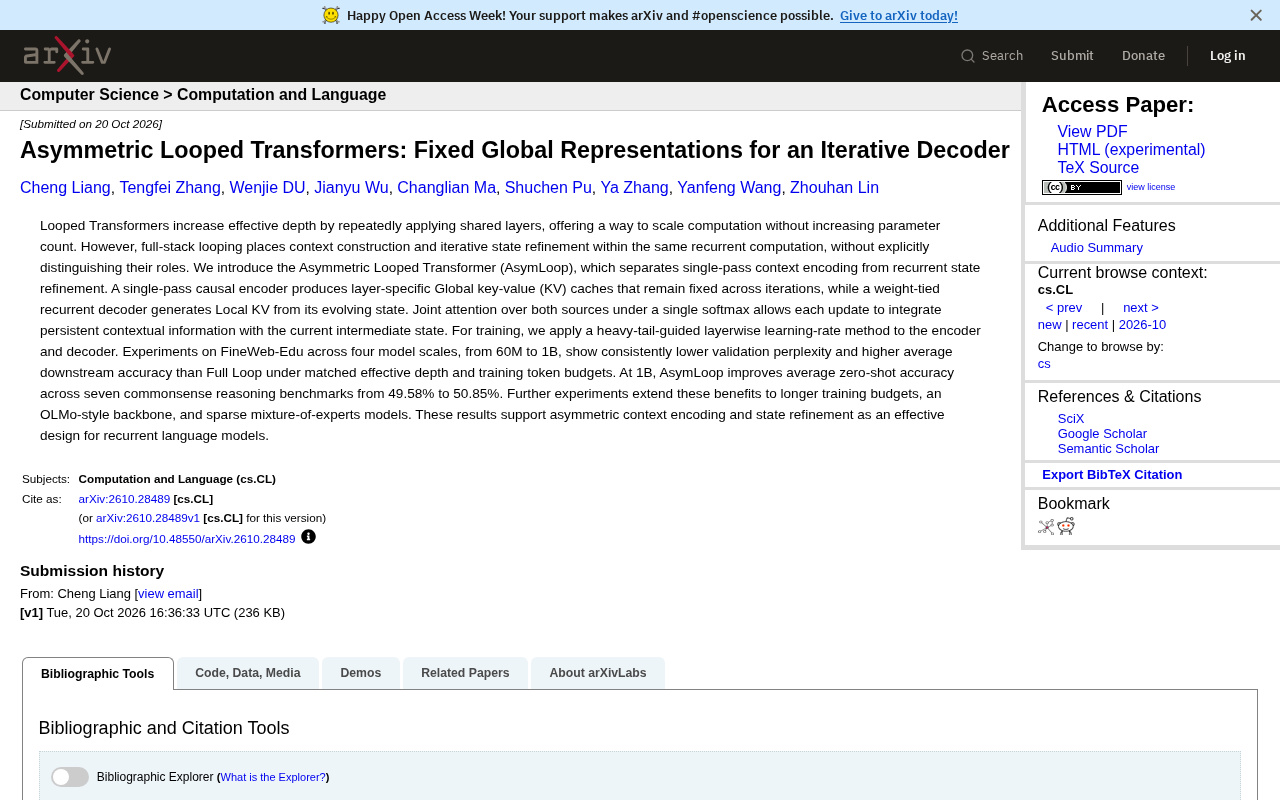
Loop Transformers increase effective depth by repeatedly applying shared layers, but full-stack looping mixes context encoding and state refinement in the same loop, causing functional coupling and representation drift. The new AsymLoop uses a single-pass causal encoder to generate a fixed global KV cache and a weight-tied recurrent decoder to generate local KVs, integrated via a single softmax joint attention. On FineWeb-Edu from 60M to 1B parameters, AsymLoop outperforms Full Loop under matched effective depth and token budgets, raising average zero-shot accuracy on seven commonsense reasoning benchmarks from 49.58% to 50.85% at 1B scale, with consistent gains on longer training budgets, OLMo-style backbones, and MoE models.
Title
Asymmetric Loop Transformer: A New Paradigm with Fixed Global Representations and Iterative Decoding
Meta Description
Asymmetric Loop Transformer (AsymLoop) separates single-pass context encoding from recurrent state refinement and fixes the global KV cache, raising average commonsense reasoning accuracy from 49.58% to 50.85% at 1B scale, offering a new design paradigm for looped language models.
Article Content
Loop Transformers increase effective depth by repeatedly applying shared layers, scaling computation without adding parameters. However, full-stack looping places context construction and iterative state refinement within the same recurrent computation, without clearly distinguishing their roles. A new paper proposes the Asymmetric Loop Transformer (AsymLoop), which separates single-pass context encoding from recurrent state refinement, offering new insight into the design of looped language models.
Limitations of Full-Stack Looping and the Proposal of AsymLoop
The core idea of the Loop Transformer is weight-shared recurrent computation: the same set of layers is applied repeatedly, achieving greater effective depth with fewer parameters. The problem, however, is that this full-stack looping conflates two distinct things—context encoding of the input sequence and iterative optimization of intermediate states. The former is inherently a one-time, deterministic process, while the latter requires repeated adjustment. By bundling the two into a single loop, the model cannot allocate different computational resources or learning dynamics to them.
AsymLoop's solution is straightforward: split them apart. It uses a single-pass causal encoder to generate layer-specific global key-value (KV) caches that remain unchanged throughout the iterative process, while a weight-tied recurrent decoder generates local KVs from its evolving state. A single softmax performs joint attention over both sources, so that each update integrates persistent contextual information with the current intermediate state. This design allows context encoding to happen only once while state refinement can proceed repeatedly.
KV cache (Key-Value Cache) is a common acceleration technique in Transformer inference. During autoregressive generation, the model must compute attention over all previous tokens each time it generates a new token; since the key (Key) and value (Value) projections of historical tokens do not change with new tokens, they can be cached and reused to avoid redundant computation. In Loop Transformers, the concept of the KV cache is extended to the layer level: each layer produces its own KV representation for subsequent attention queries. AsymLoop's key modification is to divide this cache into two categories—global KVs generated once by the single-pass encoder and frozen throughout, and local KVs regenerated at each iteration by the recurrent decoder—striking a balance between cache reuse and state updates.
Technical Details: Joint Attention over Fixed Global KVs and Local KVs
AsymLoop's architecture can be understood as an asymmetric encoder-decoder division of labor. The encoder is a single-pass forward causal structure that outputs a global KV cache for each layer and remains fixed across all subsequent iterations. The decoder is a weight-tied recurrent module whose hidden state is updated at each iteration, from which it generates local KVs. The attention mechanism attends to both global and local KV sources simultaneously, normalized through the same softmax, enabling the model to leverage both the original context and the current intermediate representation at every step.
One direct benefit of this separation is computational efficiency: the global KVs need only be computed once, and only the local KVs and state need updating during recurrent iterations. Another benefit is representation stability: the fixed global cache provides an unchanging contextual anchor for the iterative process, avoiding the context representation drift seen in full-stack looping.
For training, the authors apply a heavy-tail-guided layerwise learning-rate method to the encoder and decoder to coordinate the different learning dynamics of the two parts.
Heavy-tail-guided layerwise learning-rate is a training technique for deep or recurrent networks. In recurrent structures where the same set of weights is applied multiple times, different "effective layers" have different sensitivities to gradients: layers near the input often need more stable updates, while layers near the output may need larger step sizes to adapt to rapidly changing states. This method assigns different learning rates to each layer based on the "heavy-tail" characteristics of the gradient or loss distribution (i.e., the presence of a few extremely large update signals), suppressing the interference of extreme gradients during training. In AsymLoop, the learning dynamics of the encoder and decoder differ significantly, and this method is used to coordinate the two so that the single-pass encoder and the recurrent decoder can converge in sync.
Experimental Results: Lower Perplexity and Higher Downstream Accuracy
The paper conducts experiments on four model scales on the FineWeb-Edu dataset, ranging from 60M to 1B parameters. Under matched effective depth and training token budgets, AsymLoop consistently exhibits lower validation perplexity and higher average downstream accuracy than Full Loop.
Specifically, at 1B scale, AsymLoop raises the average zero-shot accuracy on seven commonsense reasoning benchmarks from 49.58% to 50.85%. In addition, the authors extend experiments to longer training budgets, OLMo-style backbones, and sparse Mixture-of-Experts (MoE) models, observing consistent gains in all cases. These results support asymmetric context encoding and state refinement as an effective design for looped language models.
Sparse Mixture-of-Experts (MoE) is an architecture that expands model parameter capacity while keeping inference computation manageable. It consists of multiple "expert" feed-forward networks and a gating router, where each token activates only a few experts, so the total parameter count can be far larger than the number of parameters actually involved in computation. Extending AsymLoop to MoE backbones means the layers within the recurrent decoder are themselves sparsely activated, further amplifying the theme of "parameter efficiency": reducing parameters through weight-shared looping while reducing per-forward computation through sparse activation. The authors still observe consistent gains under this setting, indicating that the asymmetric loop design does not conflict with sparsification and can be combined with it.
Implications for Looped Language Model Design
The value of AsymLoop lies not only in performance numbers but in the design principle it proposes: different functional modules within recurrent computation should not be treated equally. Context encoding is single-pass and static, while state refinement is iterative and dynamic, and the two have different computational and parameter requirements. Separating them preserves the advantages of recurrent structures in effective depth while avoiding the representation drift and computational waste caused by functional coupling.
This idea may inspire more variants of asymmetric loop architectures, such as introducing different looping strategies on the encoder or decoder side, or extending the idea of fixed global representations to multimodal or long-context scenarios. For researchers and engineers pursuing efficient inference and parameter utilization, AsymLoop provides a noteworthy baseline.
One-line Summary
AsymLoop separates single-pass context encoding from recurrent state refinement, improving looped language models with lower perplexity and higher accuracy.
Paragraph Summary
Loop Transformers increase effective depth by repeatedly applying shared layers, but full-stack looping mixes context encoding and state refinement in the same loop, leading to functional coupling and representation drift. A new paper proposes the Asymmetric Loop Transformer (AsymLoop), which uses a single-pass causal encoder to generate a fixed global KV cache and a weight-tied recurrent decoder to generate local KVs, integrating both through joint attention with a single softmax. In experiments on FineWeb-Edu from 60M to 1B parameters, AsymLoop outperforms Full Loop under matched effective depth and token budgets, raising the average zero-shot accuracy on seven commonsense reasoning benchmarks from 49.58% to 50.85% at 1B scale, and verifies consistent gains on longer training budgets, OLMo-style backbones, and MoE models.
Related articles

WorkBuddy in Action: How AI Agents Automate Batch File Conversion and Archiving
Bilibili creator Teacher Shanyao tests WorkBuddy vs. Doubao on batch file conversion, showing how AI Agents move from "giving solutions" to "direct execution," with a full workflow and credit cost reference.
High-Frequency AI Agent Interview Topics: RAG, Multi-Agent Systems, and Token Optimization
Based on a Bilibili Agent interview video, this article covers high-frequency AI Agent interview topics: RAG evaluation, single vs. multi-agent selection, token cost control, infinite loop troubleshooting, and project presentation techniques.
The Complete AI Agent Development Workflow: From Technical Build to Compliant Launch
A full AI agent development workflow for education: architecture, four teaching modules, deep synthesis and large model filings, high-concurrency deployment, and operations.