BharatSynthQA: An Indian Temple Heritage QA Dataset — How Do LLMs Perform?
Researchers release the Indian temple QA dataset BharatSynthQA, revealing LLMs' cultural heritage knowledge gaps.
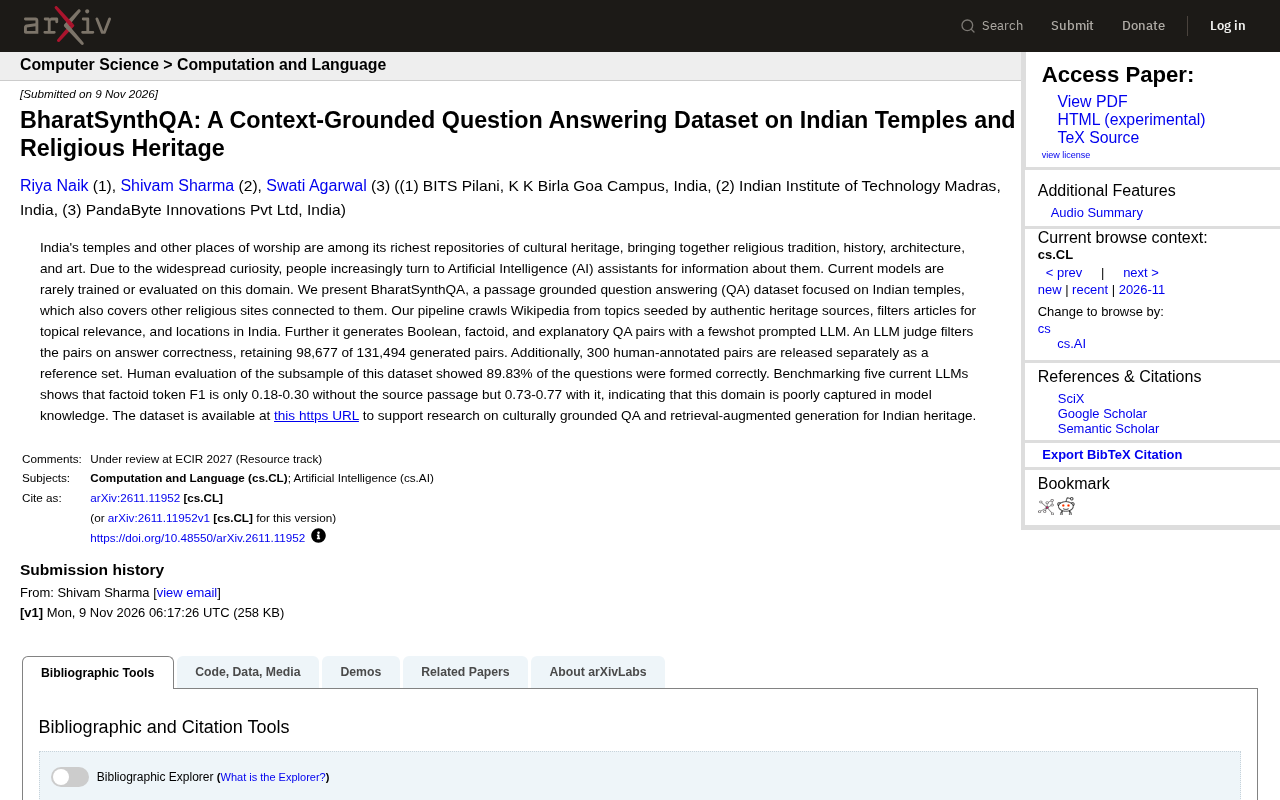
The article introduces BharatSynthQA, the first passage-grounded QA dataset focused on Indian temples and related religious sites. The pipeline sources seed topics from authoritative heritage sources, crawls and filters Wikipedia articles, generates boolean, factual, and explanatory QA pairs via few-shot prompted LLMs, and filters with an LLM judge, retaining 98,677 of 131,494 pairs plus 300 human-annotated reference pairs. Human evaluation shows 89.83% of questions are correctly constructed. Benchmarking five mainstream LLMs shows factual token F1 of only 0.18-0.30 without source passages, rising to 0.73-0.77 with them, indicating insufficient internal domain knowledge and the necessity of RAG. The dataset is open-sourced on Hugging Face.
Why Do We Need a Dedicated Cultural Heritage QA Dataset?
Indian temples and other religious sites are among the richest treasures of the country's cultural heritage, blending religious traditions, history, architecture, and art. As public curiosity grows, more and more people are turning to AI assistants for related information. However, current models are rarely trained or evaluated in this domain. According to the research paper BharatSynthQA: A Context-Grounded Question Answering Dataset on Indian Temples and Religious Heritage, existing models have weak knowledge of the Indian temple domain, and a dedicated dataset is urgently needed to advance research and applications in this area.
How the BharatSynthQA Dataset Was Built
The research team proposed BharatSynthQA, a passage-grounded question answering dataset focused on Indian temples and covering other related religious sites. Its construction pipeline includes: sourcing seed topics from authoritative heritage sources, crawling Wikipedia articles, and filtering by topic relevance and Indian location. Next, few-shot prompted large language models generate boolean, factual, and explanatory QA pairs. An LLM judge filters answers for correctness, ultimately retaining 98,677 out of 131,494 generated pairs. In addition, 300 human-annotated QA pairs are released separately as a reference set.
Data Quality and Human Evaluation
Human evaluation of a subsample of the dataset shows that 89.83% of questions are correctly constructed. This indicates that the pipeline of automated generation plus LLM filtering can produce relatively high-quality QA pairs, providing a reliable foundation for subsequent research.
Few-shot prompting refers to giving a large language model a small number (usually a few) of input-output examples in the instruction before presenting the new input to be processed, so that the model completes the generation following the format and style of the examples. Compared with zero-shot prompting, it can significantly improve output format stability and task adherence without updating model parameters, and is therefore often used for batch synthesis of structured data. LLM-as-a-judge means having another large model score or discriminate the generated results according to given criteria, replacing part of human review. Combining the two enables scalable data production at low cost, but the judge's own biases and missed judgments still require manual sampling verification — which is why this study separately releases a human-annotated reference set and conducts human evaluation.
Boolean, factual, and explanatory are three question types of increasing difficulty: boolean questions have yes/no answers and mainly test the model's discrimination of declarative knowledge; factual questions require short answers such as specific entities, dates, or locations and can be quantified with metrics like token F1; explanatory questions require generating coherent explanations at the level of causation, background, or significance, and usually need human or model judgment of their completeness and accuracy. Building and evaluating by question type helps distinguish whether a model lacks factual memory or lacks the ability to organize explanations, and also makes benchmark results more diagnostically valuable.
How Current LLMs Perform in This Domain
The research team benchmarked five current mainstream LLMs, and the results reveal the models' knowledge gaps in the cultural heritage domain. On factual questions, without providing source passages, token F1 scores range only from 0.18 to 0.30; with source passages provided, scores rise to 0.73-0.77. This significant gap indicates that domain knowledge is insufficiently captured in the models' internal knowledge, and that retrieval-augmented generation (RAG) is essential for such culturally grounded QA tasks.
Token F1 is a commonly used automatic evaluation metric in question answering and reading comprehension tasks. It calculates the degree of overlap between the predicted answer and the reference answer at the token level: first counting the number of shared tokens, then computing precision (the proportion of correct tokens in the predicted answer) and recall (the proportion of reference answer tokens that are covered), and finally taking their harmonic mean. It is insensitive to word order and tolerant of length differences, making it suitable for extractive QA where answers are a short span of text; however, it may also give high scores to semantically wrong answers that share vocabulary, so it often needs to be combined with human evaluation or semantic similarity metrics. The comparison of 0.18-0.30 versus 0.73-0.77 in the article measures the difference in answer quality with and without source passages under the same metric.
Dataset Availability and Significance
The BharatSynthQA dataset is publicly available on Hugging Face (https://huggingface.co/datasets/theshivam7/bharatsynth-qa) to support culturally grounded QA and retrieval-augmented generation research related to Indian heritage. This work not only fills the gap in QA datasets for the Indian temple domain, but also provides a benchmark for evaluating and improving LLM performance on cultural heritage. For AI researchers, cultural preservation workers, and developers, this resource is expected to drive the development of more accurate and culturally sensitive AI assistants.
One-line Summary
Researchers release the Indian temple QA dataset BharatSynthQA, revealing LLMs' knowledge gaps in cultural heritage.
Paragraph Summary
The article introduces BharatSynthQA, proposed in a research paper as the first passage-grounded QA dataset focused on Indian temples and related religious sites. Its construction pipeline: source seed topics from authoritative heritage sources, crawl and filter Wikipedia articles, then use few-shot prompted LLMs to generate boolean, factual, and explanatory QA pairs, and filter answer correctness with an LLM judge, ultimately retaining 98,677 out of 131,494 generated pairs, plus 300 human-annotated reference pairs. Human evaluation shows 89.83% of questions are correctly constructed. Benchmarking five mainstream LLMs shows factual token F1 is only 0.18-0.30 without source passages, rising to 0.73-0.77 when passages are provided, indicating that domain knowledge is insufficiently captured internally and that retrieval-augmented generation is essential. The dataset is open-sourced on Hugging Face.
Related articles
The Other Side of Anthropic's IPO: The Trillion-Dollar Loss Illusion and the 2008 Specter Hiding in AI Debt
Anthropic's IPO sparks fierce debate: headlines show a $104B loss over nine months, yet adjusted operating profit hit $4.1B. This article unpacks the accounting magic in the S-1, the $900B compute commitment, four future scenarios, and why AI data center debt is being compared to the 2008 subprime crisis.
Anthropic's $1.4 Trillion IPO Bid: Explosive Revenue Growth and a Massive Compute Bet
Anthropic races toward an IPO at up to a $1.4 trillion valuation, with revenue surging from $41M to $17B a quarter—but $895B in compute commitments and unproven margins pose huge risks. This analysis breaks down its business, finances, and IPO pricing logic.
Anthropic's $1.4 Trillion IPO: The $400 Billion Compute Bill Hiding a Two-Way Trap
Anthropic races toward a $1.4 trillion IPO, but its prospectus reveals over $400 billion in fixed compute commitments against usage-based revenue that customers can cut at any time.