Can Regression Coefficients Be Used Directly as Feature Weights? Common Misconceptions for ML Beginners

Linear regression coefficients are your formula weights — but comparing feature importance requires standardization first.
This article addresses a classic beginner confusion: the coefficients from a trained linear regression model are already the weights for your prediction formula — no conversion needed. However, raw coefficient magnitudes cannot be directly compared for feature importance, since differences in feature scale distort the numbers; standardization is required for meaningful comparison. The article also outlines a decision framework for model selection — linear regression for continuous targets, logistic regression for classification, and tree models for nonlinear relationships — while highlighting the risks of multicollinearity and the key distinction between building a prediction formula and evaluating feature importance.
Background: The Intuition Behind Going from Data to Formula
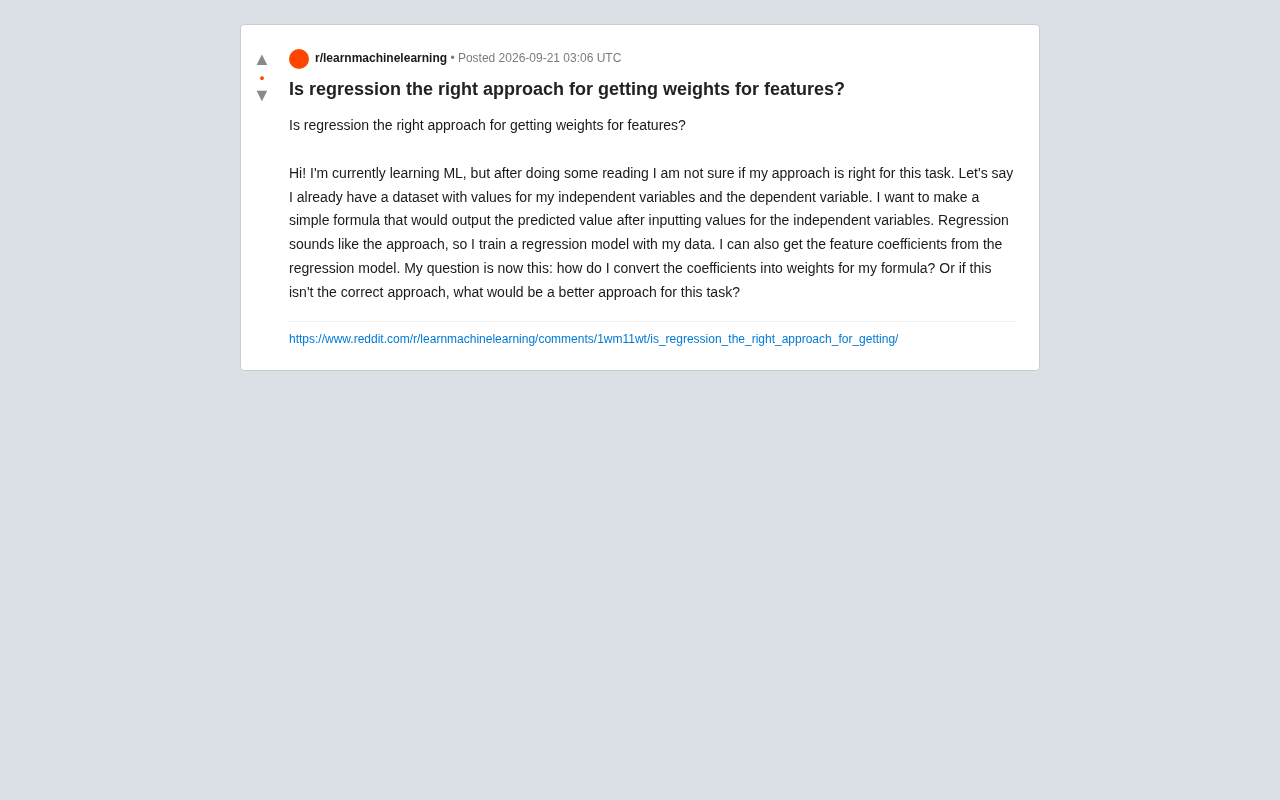
A machine learning beginner posted a seemingly simple but highly representative question on Reddit: given a dataset with independent and dependent variables, they wanted to build a simple formula that could predict the dependent variable from the inputs. Regression seemed like the right approach, so they trained a regression model and obtained the coefficients for each feature. The real confusion was: how do you convert these coefficients into "weights" for the formula? And if regression isn't the right approach, what should be used instead?
This question touches on some of the most commonly confused concepts at the beginner stage of machine learning — the relationship between coefficients, weights, and feature importance. Let's break them down one by one.
Regression Coefficients Are Already Weights
Let's get straight to the point: the coefficients from linear regression are essentially the "weights" you're looking for — no additional conversion is needed.
A standard linear regression model takes the following form:
y = w1*x1 + w2*x2 + ... + wn*xn + b
Here, w1, w2, ..., wn are the coefficients obtained after training, and b is the intercept. When you want to turn the model into a "simple formula," just plug these coefficients and the intercept directly into the expression above — that's your prediction formula. Feed in specific values for x1, x2... and compute to get the predicted y.
So the person asking the question had already completed 90% of the work — they were just tripped up by the difference between the words "coefficients" and "weights." In the context of linear models, they refer to the same thing.
A Key Trap: Coefficient Magnitude ≠ Feature Importance
Many beginners take this a step further and assume: since coefficients are weights, does a larger coefficient mean a more important feature? This is a pitfall worth watching out for.
Differences in the scale (units) of raw features directly affect the absolute size of coefficients. For example, if one feature is "house area (in square meters)" and another is "number of rooms," the former might range from tens to hundreds while the latter is typically a single digit. Even if both features are equally important for prediction, the coefficient for area may appear smaller due to its larger numerical range, while the coefficient for room count may appear relatively larger.
If your goal is to compare the relative importance of features, the correct approach is to standardize the features before training (i.e., subtract the mean and divide by the standard deviation). Only after standardization do the coefficients become comparable — at that point, the absolute value of a coefficient more accurately reflects a feature's influence.
Standardization works by subtracting each feature's mean and dividing by its standard deviation, so all features have a mean of 0 and a standard deviation of 1, placing them on the same scale. In scikit-learn, StandardScaler handles this transformation in one step. Note that standardization should only be fit on the training set, and the same mean and standard deviation should then be applied to the validation and test sets to avoid data leakage. Also, if the ultimate goal is to deploy a prediction formula, the standardization step must be incorporated into the formula: when given raw input values, first manually subtract the training set mean and divide by the training set standard deviation, then plug the result into the regression coefficients. Skipping this step will cause the live prediction results to differ completely from what was seen during training.
Should You Use Regression? It Depends on Your Goal
Back to the other half of the original question: "If this isn't the right method, what would be better?" The answer depends on the nature of the task.
Dependent Variable Is Continuous
If you're predicting a continuous numerical value (e.g., price, temperature, sales volume), linear regression is a perfectly reasonable starting point. It offers strong interpretability, produces a clear and intuitive formula, and is well-suited for situations where you want "a simple formula."
Nonlinear Relationships Between Variables
If the relationship between the independent and dependent variables isn't linear, pure linear regression may underfit. You could consider adding polynomial features or interaction terms, or switch to tree-based models (e.g., random forests, gradient boosting). Keep in mind, however, that tree models won't give you a concise linear formula and will reduce interpretability.
Dependent Variable Is Categorical
If the dependent variable is a categorical outcome (yes/no, A/B/C), you should use logistic regression or a classification model — not ordinary linear regression.
Practical Tips for Beginners
Overall, the original poster's thinking was on the right track. There are just a few conceptual gaps worth addressing:
- Start with a baseline: Build an interpretable baseline model with linear regression and use the coefficients directly as formula weights.
- Separate two distinct goals: "Building a prediction formula" and "evaluating feature importance" are two different things. The former can use coefficients directly; the latter requires feature standardization first.
- Check model assumptions: Linear regression makes assumptions about the normality of residuals, homoscedasticity, and the absence of multicollinearity among features. If features are highly correlated, the interpretation of individual coefficients can be distorted — consider Ridge regression or Lasso in such cases.
- Validate performance: Don't just check how well the model fits the training data. Always evaluate generalization ability using a test set or cross-validation to confirm the formula is reliable on new data.
Multicollinearity refers to a situation where two or more independent variables are highly linearly correlated, making it impossible for the model to stably distinguish each variable's independent contribution. Typical symptoms include extremely high variance in coefficient estimates and even signs that contradict intuition. The Variance Inflation Factor (VIF) is commonly used to diagnose multicollinearity: a VIF greater than 5 or 10 is generally considered a warning sign. Ridge regression addresses this by adding an L2 penalty on the coefficients to the loss function, shrinking coefficients and reducing variance. Lasso uses an L1 penalty, which can shrink some coefficients all the way to zero, enabling automatic feature selection. Both methods can alleviate the coefficient instability caused by multicollinearity, but at the cost of introducing bias into the estimates — so direct interpretation of the resulting "formula" requires extra caution.
Summary
At its core, this Reddit question reflects a natural confusion beginners have about the relationship "coefficients = weights" in machine learning. For linear regression, the coefficients obtained from training are exactly the weights you can plug directly into a formula — pair them with the intercept term and your prediction formula is complete. The areas truly worth investing effort in are understanding the scale issues behind coefficients, distinguishing between the two separate goals of prediction and importance evaluation, and choosing the appropriate model family based on the actual relationships in your data. Master these concepts, and a simple, interpretable prediction formula can be both useful and trustworthy.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.