Claude Code Allegedly Leaks User Emails: A Privacy Storm Triggered by a Fix

Claude Code accidentally wrote user emails into requests while fixing hallucination, sparking privacy leak controversy.
Anthropic's Claude Code was reported to potentially send user emails along with requests when visiting websites, without prior consent. The root cause was not a vulnerability, but the team providing account emails to the model to fix a bug where the model "fabricated author names," resulting in emails being written into web request identification information and potentially leaked when visiting pages that request contact information (such as the SEC). The timeline shows the earliest report on July 17, automatic closure by a bot on grounds of inactivity in September, and only on November 3 did a new version add a pre-send inquiry mechanism. The safe version is 2.1.317 and above, but as of November 6 the stable version had not yet followed suit, and the team promised to completely remove emails in the next version. The incident has sparked discussion about the data boundaries of AI tools.
AI coding tools are becoming increasingly proactive—but where should the line be drawn? Recently, Anthropic's Claude Code was reported to potentially send users' email addresses to websites it visits, without prior consent. This incident didn't stem from a carefully designed vulnerability, but rather from a change introduced to fix another issue that inadvertently opened a window for privacy leakage.
How a Fix Triggered a Chain Reaction
According to disclosures from the developer community, the root cause traces back to the team's fix for another bug. When Claude generates web requests, it includes identification information explaining "who is calling." Typically, this information only contains the application name. But to stop Claude from "fabricating" author names, the team provided the user's account email directly to the model.
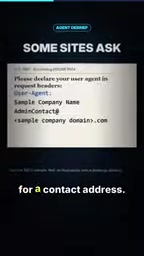
This change was intended to improve accuracy, but it had a side effect: when Claude Code initiates web requests, it may write the user's email into this identification. Some websites actively ask bots for contact addresses—for example, the U.S. Securities and Exchange Commission (SEC) page displays a sample.
This means that when Claude Code visits such websites, the user's email could be sent along with the request. This doesn't happen every time, but the key issue is—it doesn't ask the user beforehand.
User-Agent and Contact Identification in Web Requests
The "who is calling" identification information included when Claude Code initiates web requests typically corresponds to the User-Agent header in the HTTP protocol. User-Agent is a standard field through which clients declare their identity to servers, commonly formatted as "application name/version (OS information)," used by servers for compatibility handling, statistics, or access control. In the context of crawlers and automation tools, some site operators also append contact information (such as email or website) to the User-Agent or a separate field, so that operators can be reached if crawling anomalies occur—this is a convention of "traceable crawling" in robots.txt culture. Therefore, when Claude Code writes the user's email into this identifier, the practical effect is equivalent to carrying personally identifiable metadata in every outbound HTTP request—metadata that is often fully recorded in website logs. Even if the page itself has no form submission, the email is already written to disk along with the request headers.
Timeline: From Being Ignored to Public Apology
The exposure process of this incident was quite dramatic. According to available records, the earliest report appeared on July 17. However, the bug was automatically closed by a bot in September on the grounds of "inactivity." It wasn't until November 3 that a new version added a check mechanism to ask before sending the email.
Subsequently, someone on the team wrote publicly: "We're sorry we let this happen." This candid admission sparked discussion in the tech community—on one hand, the team's responsiveness is commendable; on the other hand, a privacy-related issue being automatically closed by a bot exposes blind spots in the issue tracking process.
Interestingly, the fix is not a one-time solution. The team promised to completely remove user emails in the next version, but until then, users need to check version numbers themselves. According to disclosures, the safe version is 2.1.317 or higher, but as of November 6, the stable version had not yet followed suit.
Automatic Closing Mechanism in Issue Tracking Systems
"Automatically closed by a bot on the grounds of inactivity" refers to the stale-bot mechanism on platforms like GitHub Issues. Repository maintainers typically configure rules: if an issue has no new comments or label updates within a certain number of days, the bot automatically tags it as "stale" and closes it, aiming to reduce backlog and let maintainers focus on active issues. This mechanism works well for general feature suggestions, but has obvious blind spots for security and privacy issues—privacy issues often don't require ongoing discussion; users report and then wait for a fix, and lack of "activity" doesn't mean the issue is unimportant. A more mature industry practice is to tag security issues with security or privacy labels and exempt them from automatic closing, or introduce private vulnerability reporting channels (such as GitHub Security Advisories) to prevent sensitive issues from being mistakenly closed by bots in public areas.
Why Does an AI Tool Need to Know Your Email?
This incident raises a more fundamental question: should an AI coding tool know the user's email at all? From a technical perspective, Claude needs the email to avoid "fabricating" author information, which seems like a reasonable engineering compromise. But from a privacy perspective, the user's email shouldn't become a "fact" that the model can freely invoke.
One comment hit the nail on the head: "Your email was never a secret to Claude—it's just another available fact." This approach of treating user data as "available resources" is not uncommon in AI product design, but it deserves vigilance.
As AI tools become more deeply embedded in development workflows, they come into contact with more and more user information. Email is just the tip of the iceberg—what about code repositories, API keys, internal documents? Could these also be accidentally exposed in some "fix"? This incident reminds us that the data boundaries of AI tools need clearer definitions and stricter review.
Model "Fabrication" and Fact Injection
Large language models tend to generate plausible but actually fictional content when lacking context, known in the industry as "hallucination." When Claude needs to fill in the "author" field without a reliable source, it may fabricate a name out of thin air. A common engineering countermeasure is "fact injection": providing deterministic true values (such as account email, username) as context to the model so it doesn't need to guess. This approach improves output accuracy but also changes data boundaries—personal information that the model originally "didn't know" is actively placed into a context the model can reference, and the model may then reuse it in arbitrary output positions. This suggests a design principle: facts injected to suppress hallucinations should be scoped (e.g., only referenceable in specific fields) rather than being globally callable resources, otherwise a compromise made for accuracy could evolve into a data leakage pathway.
What Users Should Do Now
If you're using Claude Code, the most direct action is to check the version number. Make sure you're running version 2.1.317 or higher. If you're on the stable channel, you may need to wait for the update to be pushed, or consider switching to a fixed version.
Additionally, the team's promised "complete removal of email" has not yet been implemented, meaning that even if the version number meets the requirement, the email may still exist in some form in requests—just with an added asking step. Before the next version is released, privacy-sensitive users can pay attention to the types of websites Claude Code visits, especially those that actively request contact information.
This incident also provides a broader insight: when the behavioral logic of AI tools is model-driven, traditional security audit methods may not be sufficient. A change introduced to fix problem A may open a new hole at point B. For developers and users alike, staying informed about version updates and understanding tool data flows is more important than ever.
Editor's Commentary
The Claude Code email leak incident was not malicious behavior, but an unintended consequence of an engineering decision. It exposed the gray area in AI products' data usage: user information introduced to improve model performance may flow into external requests without adequate evaluation. The team's apology and fix are commendable, but the episode of the bot automatically closing the bug shows that process gaps also need to be patched. For users, this incident is a reminder—behind the convenience of AI tools, the clarity of data boundaries determines the depth of trust.
One-line Summary
Claude Code accidentally wrote user emails into requests while fixing hallucination, sparking privacy leak controversy.
Paragraph Summary
Anthropic's Claude Code was reported to potentially send user emails along with requests when visiting websites, without prior consent. The root cause was not a vulnerability, but the team providing account emails to the model to fix a bug where the model "fabricated author names," resulting in emails being written into web request identification information and potentially leaked when visiting pages that request contact information (such as the SEC). The timeline shows the earliest report on July 17, automatic closure by a bot on grounds of inactivity in September, and only on November 3 did a new version add a pre-send inquiry mechanism. The safe version is 2.1.317 and above, but as of November 6 the stable version had not yet followed suit, and the team promised to completely remove emails in the next version. The incident has sparked discussion about the data boundaries of AI tools.
Related articles
Hands-On with Shopify AI Toolkit: Official Validation for AI-Generated Shopify Code
Hands-on with Shopify's official AI Toolkit: connect Shopify docs, API schemas, and code validation to Claude Code and other coding assistants to intercept AI-fabricated fields. Installation steps, offline validation, and telemetry-on-by-default warnings.
Claude Orchestrating an AI Coding Team: A Practical Analysis of Agent Orchestrator
The open-source Agent Orchestrator lets Claude Code dispatch Codex, Gemini, Cursor and more for parallel AI coding, with Git Worktree isolation, CI auto-correction, and mobile notifications for AI team collaboration. This article analyzes its core mechanisms, cost structure, and use cases.
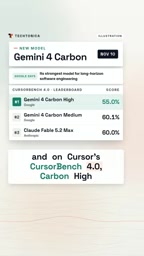
Google's New AI Coding Model Beats Claude at One-Third the Cost
Google's Gemini 4 Carbon edges past Claude Fable 5.2 Max on CursorBench 4.0 at 60.4% vs 60%, costing just $9.22 per task versus $32.79—about one-third.