Claude Sonnet 5.5 Released: A New Coding Powerhouse with Better Performance at the Same Price

Claude Sonnet 5.5 delivers 30% faster speeds and near-sevenfold benchmark gains with no price increase.
Anthropic's Claude Sonnet 5.5 raises the bar for mid-tier AI models — running over 30% faster while maintaining the same pricing. Its terminal benchmark skyrocketed from 10.3% to 70.6%, signaling a qualitative leap in agentic and automation capabilities. In real-world coding tasks, it handles tens of thousands of lines of code while excelling at debugging, documentation, and everyday productivity work. Most notably, it scores within just 2 points of the twice-as-expensive Opus 5.5, redefining what developers can expect from a cost-effective AI coding model.
Sonnet 5.5 Arrives: Faster, Stronger, Same Price
Anthropic's Claude Sonnet 5.5 has quickly become one of the most talked-about AI coding models of late. Billed officially as "the fastest Sonnet generation yet," it runs more than 30% faster than its predecessor while keeping the same pricing — $3 per million input tokens, $15 per million output tokens, and $0.20 per million for caching (some sources cite $2 / $10 / $0.20 per million tokens).
The core pitch can be summed up in one sentence: equal or better performance at the same price as before. By comparison, the sibling Opus 5.5 is priced at twice the cost of Sonnet 5.5, making Sonnet 5.5's value proposition hard to ignore.
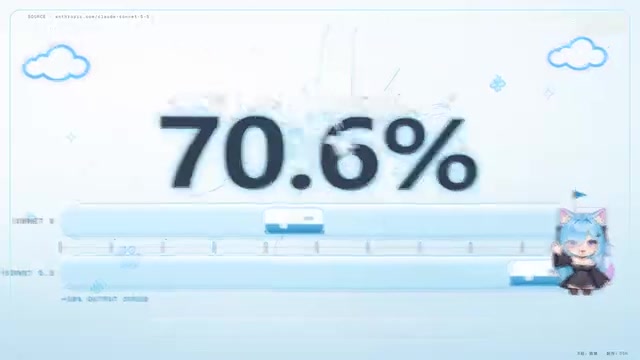
Benchmark Scores Jump Across the Board
The most striking change is the dramatic leap in benchmark scores. On terminal-related benchmarks, Sonnet 5.5 hits 70.6%, up from just 10.3% in the previous generation — nearly a sevenfold improvement. This directly reflects the model's upgraded ability to handle real-world scenarios like command-line operations and environment interaction.
On knowledge work benchmarks, the score climbed from 1449 to 1844, while coding ability jumped from 34.1 to 55.5. All three core benchmarks showed significant gains, and in some dimensions, Sonnet 5.5 trails the more expensive Opus 5.5 by just 2 points.

This means that for many real-world tasks, there's simply no reason to pay double for Opus 5.5 — Sonnet 5.5 can already handle the vast majority of use cases.
Terminal Benchmark refers to a comprehensive score measuring a model's ability to complete tasks in a command-line/shell environment, covering file operations, script execution, package management, process control, and other real system interactions. Unlike static code generation tests, terminal benchmarks require the model to interact continuously with the operating system — like a real user or automated agent — observe outputs, and self-correct. The leap from 10.3% to 70.6% signals a shift from "occasionally completing simple commands" to "reliably handling complex, multi-step tasks in a terminal environment" — a critical capability for making AI coding agents practically useful. Knowledge work benchmarks (1449→1844) are typically based on an Elo rating system, measuring overall model performance on professional tasks like code review, technical documentation, and system design, with scores comparable across models.
Real-World Performance in Coding and Productivity
Beyond benchmarks, Sonnet 5.5 also shines in real workflows. It performs well across everyday tasks like debugging, writing documentation, and creating spreadsheets — a genuinely well-rounded model.
In high-complexity scenarios like game development, the model can work with tens of thousands of lines of game code, demonstrating strong comprehension and generation capabilities for large codebases. This is especially appealing for indie developers and small teams, as it significantly lowers the barrier to tackling complex projects.

Also worth noting is an efficiency improvement: in tools like Slack, output volume is reduced by approximately 14%. Less verbosity combined with faster inference means real-world usage saves both time and, indirectly, token costs. Overall, Sonnet 5.5 delivers a "30% faster, 30% leaner" combination.
Why This Upgrade Matters
The significance of Sonnet 5.5 isn't just about impressive scores — it's about redefining the upper limit of what a mid-tier model can do. The jump from 10.3% to 70.6% on terminal benchmarks indicates a qualitative shift in agentic operations, tool use, and automated workflows, not just incremental parameter scaling.
For developers, the decision framework becomes much clearer: go with Opus 5.5 if you need maximum capability, but if budget is a concern or you're running at scale, Sonnet 5.5 delivers performance just 2 points behind at half the cost — a far more pragmatic choice. The combination of unchanged pricing and a performance leap means this update delivers more real-world value than its minor version bump might suggest.

In an increasingly competitive AI coding model landscape, a "same price, more power" strategy often resonates more deeply with actual users than simply topping a performance leaderboard. Sonnet 5.5 is a prime example of this approach.
Agentic Operation refers to an AI model that doesn't just passively answer questions, but actively plans steps, calls tools (such as code executors, browsers, and file systems), and adjusts its actions based on intermediate results — forming an autonomous loop of "perceive–decide–execute." The major gains on terminal benchmarks are a direct reflection of this agentic capability: the model must independently carry out multi-step processes like installing dependencies, running tests, interpreting error messages, and fixing code — all without human intervention. This is fundamentally different from the traditional "one question, one answer" completion model. For teams looking to integrate AI into CI/CD pipelines, automated code review, or unattended task processing, a qualitative leap in agentic capability delivers far more production value than a simple improvement in code completion accuracy.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.