Curing AI's Data Fabrication Problem: A Data Analysis Skill Governed by 74 Regression Tests

74 tests and a built-in Falsifier agent keep this Codex data analysis skill from making things up.
Data Analysis School is a Codex-embedded data analysis skill built around one principle: evidence first. It uses in-table reconciliation, L0–L4 evidence tiering, and pre-publication truthfulness checks to prevent AI from fabricating results. A GrillMe gate forces clarification before acting on vague questions, while explanatory queries trigger a four-role pipeline — Locator, Mechanism, Falsifier, and Reviewer — with the Falsifier dedicated solely to challenging prior conclusions. The project covers 16 analysis capabilities, 11 industry templates, and ships with 74 regression tests and a real-data case study. Key limitations: noncommercial license, Codex-only, and the skill is a guardrail, not an engine.
AI's biggest failure in data analysis isn't being slow — it's being convincingly wrong. Models produce perfectly formatted numbers, beautiful charts, and logically coherent conclusions, each layer looking right, the whole thing being fake. A small GitHub project called Data Analysis School was built specifically to fix this — created by data analysis content creator "Xiaoma Xue Shufen." The project is modest in scale, with just over 30 stars, but its engineering discipline is intimidating: 74 regression tests, evidence-tiered gatekeeping, in-table reconciliation, and a cross-examination gate called GrillMe. It answers a question everyone eventually faces: how do you stop AI from making things up when analyzing data?
What It Actually Is
At its core, this is a data analysis skill packaged inside Codex. You upload an Excel or CSV file, ask a question in plain language — something like "why did the payment success rate drop in this dataset" — and it autonomously identifies your decision intent, selects a combination of analytical methods, writes the code to run the calculations, and delivers an offline HTML report.
The capability matrix covers 16 areas, essentially a panoramic view of a data analyst's daily work: anomaly localization, funnel analysis, metric systems, A/B testing (including CUPED variance reduction), causal inference, user segmentation (RFM with 8-segment labeling), contribution and ratio decomposition, channel attribution across 6 model types (Shapley included), cohort retention, survival analysis, path analysis, price elasticity, breakpoint detection, and multiple comparison correction. This is no toy — it's a complete toolkit of data analysis methodology.
It also comes with 11 industry-specific template sets, from retail e-commerce to finance and gaming. Each one documents the applicable signals, KPI definitions, common data pitfalls, and fallback paths. In other words, it encodes industry experience directly into the workflow.
CUPED (Controlled-experiment Using Pre-Experiment Data) is a variance reduction technique for A/B testing developed by Microsoft Research. The idea is to use pre-experiment historical data as covariates — regressing out the noise from inherent individual differences — to improve statistical sensitivity without increasing sample size. Simply put: with the same sample size, CUPED gives you a better chance of detecting a real effect, or lets you reach the same confidence level with a shorter experiment window. In fast-iteration environments like e-commerce and gaming, this can significantly reduce experimentation costs.
Shapley values come from cooperative game theory and are used to fairly allocate the joint output of multiple "contributors." In channel attribution, users typically pass through multiple touchpoints before converting (paid search → feed ads → CRM push). Shapley attribution enumerates the marginal contribution of all channel orderings and averages them, giving each channel a theoretically fair share of conversion credit — avoiding the systematic bias of last-click attribution toward end-of-funnel channels. Computational complexity grows exponentially with the number of channels, so in practice Monte Carlo approximation is typically used.
The Core Principle: Evidence First
The soul of this project is four words: evidence first. It implements this through three mechanisms.
The first is in-table reconciliation. If your spreadsheet contains totals or subtotals, a reconcile script cross-validates every detail line against the table's built-in checksums. If anything doesn't add up, it doesn't proceed — the exit code can be used directly as a pipeline gate. Verifying your data against itself is the most primitive and most rigorous reality check there is.
The second is tiered conclusion classification. All conclusions are assigned an evidence level from L0 to L4, with "correlation does not imply causation" enshrined as a hard rule. Unverifiable explanations can only be labeled "heuristic candidates" or "hypotheses pending validation" — they are not allowed to masquerade as root causes.
The third is a pre-publication truthfulness check (verify). Every number in the report must be bound to a specific evidence entry, with consistent direction and sign. The harshest rule: any causal language at L2 or above without corresponding evidence is an automatic failure.
The L0–L4 evidence tier system draws on the evidence pyramid from Evidence-Based Medicine (EBM). In clinical research, randomized controlled trials carry stronger evidence than observational studies, which outweigh expert opinion. The analogy in data analysis roughly maps as follows: L0 is a direct reading from raw data (strongest); L1 is descriptive statistics and aggregated calculations; L2 is correlation and trend inference; L3 is causal hypotheses derived from observational data; L4 is qualitative speculation without data support (weakest). Encoding "correlation ≠ causation" as a hard rule and requiring L2+ causal language to be bound to evidence is, in essence, using structured rules to enforce the cognitive discipline that is hardest to internalize in analyst training: distinguishing between "what the data shows" and "what we think happened."
Two Hard Gates: Don't Guess Your Way to an Answer
What truly separates this from ordinary analysis tools are two hard gates.
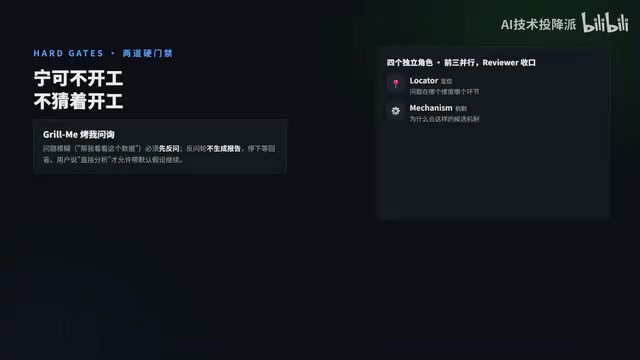
The first is GrillMe. If your question is vague — like "take a look at this data" — it must ask clarifying questions before doing anything. That clarification round produces no report; it stops and waits for your answers. Only if you explicitly say "just analyze it" is it permitted to proceed with default assumptions. Better to not start than to guess your way forward.
The second is the independent role gate. Any explanatory question involving "why" or "what caused this" must be processed through four independent roles: Locator (identify the anomaly), Mechanism (find the cause), Falsifier (challenge the conclusion), and Reviewer (final sign-off). The first three run in parallel; Reviewer closes the loop last. All four must complete before publication.
The one most worth pausing on is Falsifier — a dedicated agent whose sole job is to tear down the conclusions reached by the other roles. This builds the scientific obligation of falsification directly into the workflow. And execution is logged: every run writes an execution.json that records whether native subagents or serial fallback was used, and if fallback occurred, the reason must be documented. No faking parallelism.
The Falsifier role directly embodies Karl Popper's principle of falsifiability from philosophy of science: if an explanation cannot be refuted by any evidence, it is not a scientific conclusion — it is merely a narrative. In practice, models (whether AI or human) naturally tend toward confirmation bias — once a self-consistent explanation is found, the search for counterexamples stops. The Falsifier's job is the opposite: it receives the conclusions of the first two roles and specifically seeks logical gaps, alternative explanations, and contradicting data points, ensuring that the final conclusion survives adversarial pressure before publication. This design is especially valuable in agent systems, because LLMs' generative mechanism naturally favors fluent, coherent narratives over self-doubt. Moving the falsification obligation from a manual review step into an automated workflow is arguably the most methodologically valuable engineering decision in this entire project.
Delivery: Reports With No Animated Numbers
Delivery is equally deliberate. The model only writes a compact specification JSON; HTML and charts are generated by a separate renderer, keeping content and presentation cleanly separated.
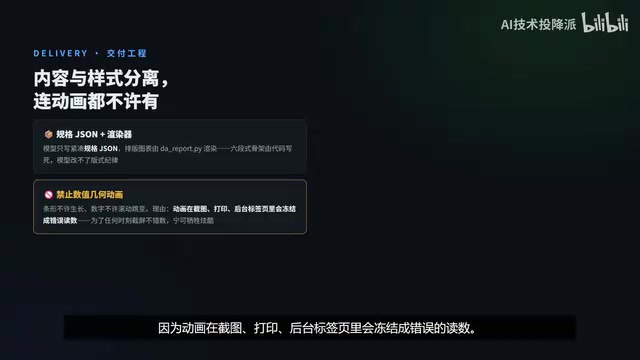
One detail is clever enough to call out specifically: the report prohibits numerical animation. Bars cannot grow in. Numbers cannot roll or count up. Why? Because animations freeze at wrong values in screenshots, print previews, and background tabs. To guarantee that "any screenshot will always show the correct numbers," the project willingly trades away visual flair.
Context management is handled with equal precision. The main skill file keeps its resident footprint to just over 4,000 tokens, accompanied by a load table specifying which file to read at which step. Method packages and industry templates are explicitly forbidden from being loaded wholesale. Saving tokens is one benefit; more importantly, the model's attention isn't diluted by irrelevant content.
Three Hard Pieces of Evidence for Engineering Quality
The engineering discipline here isn't rhetorical — it has three concrete proofs.
First, 74 regression tests covering CI across three Python versions, with case reports compared byte-by-byte — if the renderer changes by one pixel, the test fires.
Second, the token counts in the README are independently verifiable. A dedicated measurement script is included so anyone can reproduce the numbers themselves.
Third, the example case uses real data: the UCI UK Retailer public dataset, with the full chain from data construction to run artifacts to conclusions all committed to the repository. The example conclusion headline itself reveals the project's character: "November's spike is seasonal; December's cliff is truncation plus a batch of cancellations." No manufactured drama. The data says what it says.
Three Takeaways
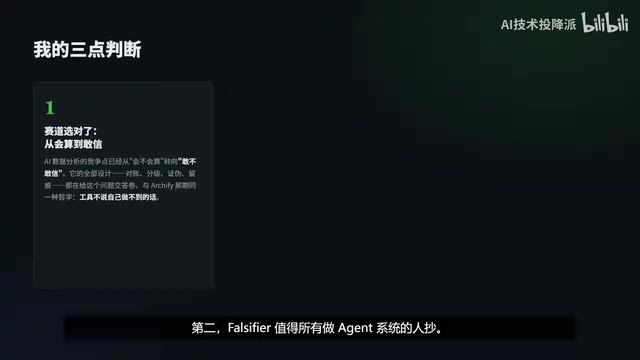
The right problem to solve. The competitive axis in AI data analysis has shifted from "can it calculate" to "can you trust it." Every design choice in this project — reconciliation, tiering, falsification, audit trails — is an answer to the question of trustworthiness. A tool that doesn't claim to do what it can't is a rare form of engineering honesty.
Every agent system builder should steal the Falsifier. Having AI falsify itself is a hundred times cheaper than human review, and a hundred times more reliable than no review. Any agent that produces conclusions should have a dedicated devil's advocate role.
Three buckets of cold water, as always. First, it uses a Polyform Noncommercial license — commercial teams need to obtain authorization before using it, which will block quite a few. Second, it's a Codex ecosystem skill; porting it to other agents requires migration work. Third and most fundamentally: a skill is a guardrail, not an engine. The ceiling on analysis quality still depends on the underlying model. The gates can prevent hallucination; they can't guarantee insight.
If you want to try it, search xiaomaxueshufen-dataanalysis on GitHub. It installs with a single line in Codex — upload an Excel file, ask a question, and it runs.
One line to take with you: to judge whether an AI analysis tool is reliable, don't look at how beautiful the charts are. Look at whether it stops when the numbers don't add up.
Related articles

Uber Deploys ChatGPT Work Company-Wide: AI in the Workplace Enters the Scaled Implementation Phase
Uber deploys ChatGPT Work to 30,000+ employees, extending it from engineering to all roles. We analyze its expert-engineer pairing, end-to-end automation, and questions of AI control and power concentration—insights for scaling AI in the workplace.

Shift at Midnight Hands-On: When "ID Verification" Becomes Alien Hunting
Shift at Midnight blends ID verification with horror survival in a four-player co-op game. We break down its inspection mechanics and chaotic humor.

Zelensky Recounts the Outbreak of War: I Need Ammunition, Not a Ride
Zelensky recalls the first day of war in a YouTube interview: farewell to family, rejecting Biden's evacuation offer with "I need ammunition, not a ride," and how Bucha shaped his stance on compromise and peace talks.