Decision Models Capture 26% of Requests: Anthropic's New Team Wins Nearly 2:1

Decision models rise, voice penetration doubles, model half-life shrinks to six weeks — a structural shift in enterprise AI.
AI Gateway's October production index shows a structural shift in enterprise AI. Decision models captured about a quarter of requests within six weeks at one-seventieth the per-request cost of language models, yet account for only 0.53% of spend. Voice penetration among paid teams rose from ~4% to ~11%. Anthropic's preferred rate among new teams is nearly double OpenAI's, with OpenAI's spend share rising from ~9 to ~15 cents. Model half-life has shrunk to about six weeks.
AI Gateway's latest monthly production index shows a structural shift in the enterprise AI landscape. Decision models captured about a quarter of routed requests within six weeks, Anthropic's win rate among new paid teams is nearly double OpenAI's, and the "half-life" of language models has shrunk to about six weeks. Behind these numbers is a clear signal that AI applications are diverging from "generation" toward "judgment."
Decision Models: A New Layer of "Judgment" Infrastructure
In the past, when software needed to make quick judgments, there were only two paths: hard-coded rules — cheap but rigid — or calling a language model — smart but slow and expensive. Decision models have become a third option: they don't generate text, they only classify, score, or choose among candidates.
According to AI Gateway's statistics, the cost per request for a decision model is about one-seventieth that of a language model. Since launching in late September, 15 decision models from eight vendors have become available. In October, nearly a third of paid teams used decision models, and about 11% of teams sent no requests at all to text-generation models.
Because decision models return extremely short answers at very low unit prices, they consumed about a quarter of request volume while accounting for only 0.53% of total spend. This "high-frequency, low-value" profile fills exactly the gap between traditional rule engines and general-purpose large models.
Who Uses Decision Models
The larger the team, the more it relies on decision models. Among teams processing fewer than 10 million tokens per month, just over one-fifth used decision models; in the 100 million to 1 billion range, nearly half did; among teams exceeding 1 billion tokens, seven in ten were using them.
This is partly because large teams use more of everything — the median team in the top 1% by spend uses 29 different models, while teams in the bottom 10% use just one — and partly because the greater the request volume, the more obvious the payoff from replacing simple judgments with decision models.
One detail: nearly all decision model requests went to TypeSafe AI's Jev, whose request volume was close to four times Anthropic's total. But by spend, for every $1 a team spends on Jev, it spends $64 on Anthropic models — the two product lines sit in entirely different positions on the value chain.
AI Gateway is a unified routing layer between applications and multiple model providers: developers use a single interface to distribute requests to models from OpenAI, Anthropic, Google, and other vendors, and the gateway handles authentication, billing, rate limiting, fallback, and observability. Because all requests pass through the same entry point, the gateway naturally produces aggregated usage data across vendors and models — which is exactly the source of the statistics in this article. Note that this data only reflects traffic "routed through this gateway," so the sample skews toward teams that have already adopted multi-model architectures and cannot be directly extrapolated to the entire enterprise AI market; spend figures are also estimated at public list prices, not actual transaction prices.
Decision Models refer to models trained specifically for tasks such as classification, ranking, scoring, and choosing among a limited set of candidates, with typical forms including small classifiers, reranking models, and structured discriminative models. They do not generate free-form text; their output is usually just a label, a score, or an option, so the compute overhead and latency per request are far lower than those of general-purpose language models. Compared with rule engines, decision models can learn boundary conditions from labeled data without manually enumerating if-else branches; compared with language models, they avoid the cost and latency of lengthy reasoning. Jev, mentioned in the article, belongs to this category.
Voice Models: Paid Team Penetration More Than Doubles
In October, about one in nine paid teams used voice models, up 161% from one in twenty-four in July. The growth came from two directions: new teams chose voice directly, while existing teams layered voice capabilities onto their existing stacks. Among teams that paid in both July and October, voice usage rose from 5% to 14%.
Deep usage is also increasing. The share of teams sending at least 100 voice requests per month grew fivefold; six in ten teams that used voice in September continued in October, up from less than half the retention rate in July.
A voice conversation typically has three steps: speech-to-text, language model generates a reply, text-to-speech. Most teams use only one or two of these stages. Since July, usage of speech-to-text models has nearly tripled, and text-to-speech has grown more than threefold.
Architecture choices are also flipping: in July, about a quarter of voice teams used an integrated model and one-sixth assembled the three stages themselves; by October, these two proportions had exactly swapped. For most teams, voice is a new interaction entry point added to an existing application or agent, with the middle language model unchanged and voice capabilities added at one or both ends.
The three stages of the voice pipeline each have dedicated models: speech-to-text (STT/ASR) converts audio to text, text-to-speech (TTS) synthesizes replies into speech, and the language model in the middle handles intent understanding and content generation. A so-called "integrated model" (speech-to-speech) is a single model that directly performs end-to-end conversion from audio input to audio output, skipping the intermediate text relay, with lower latency and better preservation of tone and emotion, but weaker controllability and debuggability; "self-assembled" means chaining three independent stages — STT, LLM, TTS — making it easy to swap out any component and reuse existing language models and prompt systems, at the cost of a longer pipeline and higher cumulative latency. The swap in the proportions of these two architectures shows that after experimenting, teams prefer to embed voice as a pluggable capability within their existing tech stacks.
Anthropic vs. OpenAI: The Battle for New Teams
In December of last year, 70 out of every 100 paid teams on AI Gateway used OpenAI models, and 48 used Anthropic models. By October, the two were nearly even: OpenAI at 55, Anthropic at 54.
Among existing teams already on the gateway in December, penetration rose for both, but Anthropic gained more — from about half to about two-thirds, while OpenAI went from about three-quarters to four-fifths.
Anthropic's gains came mainly from new teams: in October, it was the preferred lab for nearly twice as many new teams as OpenAI. However, among the highest-spending teams, both have near-total coverage — more than nine in ten of the top 1% by spend use both Anthropic and OpenAI, and the competition has shifted from "can you get in" to "how much workload can you win."
By spend share, Anthropic still leads, but OpenAI is catching up. OpenAI now takes nearly 15 cents of every dollar spent on the gateway, up from about 9 cents in December; Anthropic's share halved over the same period to about 32 cents.
"Preferred lab" and "penetration" are two different metrics, and understanding the difference is key to reading this section. Penetration measures "how many teams are using" a vendor; the same team can use multiple vendors, so the two vendors' penetration rates can sum to more than 100%. Preferred-lab rate measures "who new teams chose when they first onboarded," reflecting the outcome of competition in the incremental market. This is the source of the seemingly contradictory phenomenon in the article: Anthropic's preferred rate among new teams is nearly double OpenAI's, yet penetration among existing teams is nearly even. And spend share is a third dimension, measuring "where the money flows" — a team may call both vendors' models but place heavier production workloads on one of them. The three metrics correspond to customer acquisition, existing base, and wallet share; looking at any one alone yields a one-sided conclusion.
Six-Week Model Half-Life: Loyalty Is Disappearing
In October, more than half of language model requests went to models launched less than 60 days earlier. Before September, that share had never exceeded 30%.
The median version iteration for model families is once every 61 days, and a typical model reaches peak usage within one month of launch. Four weeks after the peak, three-quarters of the teams using it at the time had moved on — regardless of whether the family released a successor version. Most of these teams remained on AI Gateway, they just switched to other models.
Switching is very frequent, and often across labs. In October, about half of teams processing at least 10 million tokens per month changed their most-used model; four-fifths of them moved to a newer version, and six in ten moved to a different lab.
Older models haven't disappeared; they often coexist with the new primary model. Among these same large teams, seven in ten still use a model at least ten months old, but on a median basis it handles less than 3% of tokens.
This data reveals a cold reality: the "half-life" of a model for a team is about six weeks. Labs can only speak through their latest models, and every new version must win customers back.
"Model half-life" is an analogical metric, not a strict definition: it borrows the concept of radioactive decay to describe the timescale over which a model maintains primary status before being replaced by a new version. The measurement method in the article is to observe that about three-quarters of in-use teams leave within four weeks after a typical model reaches peak usage, from which it infers that a team's attention span for a single model is about six weeks. This metric matters because it converts "model iteration speed" from the lab's perspective to the demand side: the pace of version releases is decided by vendors, but the speed at which teams actually migrate determines how much commercial value each version can realize. Note that "leaving" here mostly means no longer treating it as the primary model, not completely discontinuing it; older models often coexist long-term as fallbacks or for specific tasks, so a short half-life does not equal elimination of old models.
Other Notable Signals in October
By spend, Opus 5.5 became the most popular model in its first full month, capturing about one-seventh of all team spend. Of the six most widely used models on the gateway, four are from Anthropic: Sonnet 5.5 (covering 26% of paid teams), Haiku 5.5 (22%), Haiku 4.5 (20%), Opus 5.5 (18%); the other two are Jev (28%) and GPT-6 Luna (19%).
Both image and video models set their biggest months ever on AI Gateway. About a third of the top 1% of teams by spend used image models, up from a quarter in July; one-sixth used video models, up from one-tenth in July. OpenAI's latest GPT-Image-2.5 Sunburst led image spend in its first full month, while ByteDance's Seedance 2.5 led video spend for the third consecutive month, ahead of Google's Veo 3.1 and Kuaishou's Kling 3.0.
The above data is based on anonymized aggregated traffic routed through Vercel AI Gateway, with spend estimated at public list prices.
One-line Summary
Decision models rise, voice penetration doubles, model half-life shrinks to six weeks — a structural shift in the enterprise AI landscape.
Paragraph Summary
AI Gateway's October production index shows that the usage structure of enterprise AI is shifting. Decision models captured about a quarter of requests within six weeks of launch, and with a per-request cost about one-seventieth that of language models, they have become a new judgment layer between rule engines and general-purpose large models — though because of their extremely low unit price they account for only 0.53% of total spend, and adoption rises with team usage volume. Voice model penetration among paid teams rose from about 4% in July to about 11% in October, with the proportions of integrated and self-assembled architectures swapping. On the vendor landscape, Anthropic's preferred rate among new paid teams is nearly double OpenAI's, the two are nearly even in existing-team penetration, and OpenAI's spend share rose from about 9 cents to nearly 15 cents. The most critical signal is that model half-life has shrunk to about six weeks: more than half of language model requests go to models launched less than 60 days ago, and teams switch frequently, often across labs.
Related articles
How Do Cursor, Devin, TRAE, and Copilot Compare on Price? Calculate Your Credits Before You Compare Monthly Fees
Side-by-side comparison of individual and team pricing for Cursor, Devin Desktop, TRAE, and Copilot, breaking down credit rules, third-party model inclusion, overage billing, and practical methods for measuring usage before paying, setting spending caps, and choosing the right tool.
Copilot Retires Three Models: Pro Users Left With Only One Alternative
GitHub Copilot retires Claude Opus 4.8, Claude Opus 5, and GPT-5.6 Tera on Nov 16 across Chat, code completion, and Agent mode. Pro users have only GPT-6 Luna left; Legacy annual plans miss Opus 5.5; admins must enable replacements manually.
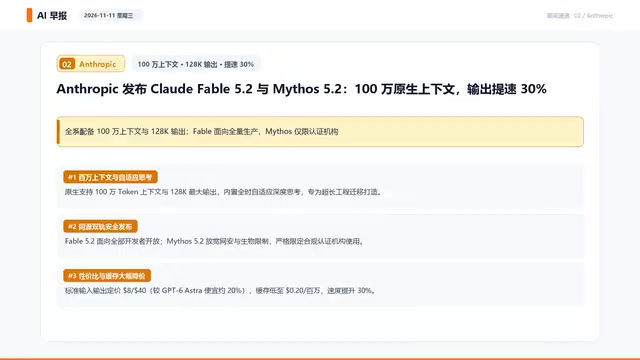
Gemini 4 Carbon Arrives: The LLM Race Enters the Era of Million-Token Context and Trillion-Parameter Open Source
Google launches Gemini 4 Carbon and multi-agent tool Swarm; Anthropic debuts million-context Fable 5.2 and Mythos 5.2; OpenAI releases security-focused GPT-6 Cyber; Mistral and Kimi open-source trillion-parameter models — the LLM race accelerates across the board.