DeepSeek V4.1 Flash Tops Global Usage Charts: Open Source Demolishes AI Pricing Floors

DeepSeek V4.1 Flash tops global AI usage with MIT open source, self-deployment, and a fraction of the cost.
DeepSeek V4.1 Flash combines top-tier benchmark performance with prices one-tenth of competitors, pushing weekly token usage to 15.8 trillion — up 219% week-over-week. Its MIT license and self-deployment support eliminate data sovereignty concerns for Western enterprises. Using the Pareto Frontier framework, the model offers the optimal capability-to-cost balance, though developers should note its 43% higher output token count means lower unit prices don't always mean lower per-task costs.
DeepSeek V4.1 Flash: Top-Tier Performance at One-Tenth the Price
DeepSeekAd's recently released V4.1 Flash has sent shockwaves through the global developer community. According to analysis from Bilibili content creators, this model matches or even outperforms the industry-leading Claude Opus 5 on certain benchmarks — at just one-tenth the price. What makes it even more significant is that it's open-sourced under the MIT license and supports self-deployment.
This combination of high performance, low cost, and open-source availability has fundamentally reshuffled the usage rankings. For the first time, V4.1 Flash topped the global model usage charts last week, with a weekly token count of 15.8 trillion — a staggering week-over-week increase of 219%. Behind this growth curve lies not just the model's technical appeal, but a deep market hunger for cost efficiency and control.
Open Source + Self-Deployment Resolves Western Enterprises' Data Concerns
For a long time, Western enterprises have harbored a core concern about using Chinese AI models: the fear that their data would pass through Chinese vendors' servers. This concern has historically been the primary barrier to Chinese models gaining traction abroad.
V4.1 Flash's MIT open-source license, combined with self-deployment capabilities, neatly sidesteps this issue. Enterprises can deploy the model within their own controlled cloud environments — Azure, Tencent Cloud, AWS, and others — with data never touching the model vendor's infrastructure. This goes straight to the heart of a key concept: data sovereignty.
When enterprises control where their data lives and how it flows, the trust penalty associated with the "Chinese model" label diminishes dramatically. This is precisely why usage exploded so quickly — it unlocked a whole segment of enterprise users who had previously been held back by these concerns.
The MIT license is one of the most permissive open-source licenses available. It allows users to freely use, copy, modify, merge, publish, distribute, sublicense, and even incorporate the software into commercial products — with the sole requirement of retaining the original copyright notice. Unlike "copyleft" licenses such as GPL, MIT does not require derivative works to be released under the same terms, meaning enterprises can integrate the model into proprietary systems without exposing their own code. For companies looking to privately deploy AI capabilities, the MIT license means minimal legal compliance risk and maximum commercial flexibility. This is a key institutional reason why V4.1 Flash has been so rapidly adopted by Western enterprises — it removes not just technical barriers to self-deployment, but legal ones as well.
The Pareto Frontier: The Optimal Balance Between Intelligence and Price
The concept of the Pareto Frontier from economics helps explain V4.1 Flash's positioning. AI model competition shouldn't be understood as a pure race for raw intelligence — it's about finding the optimal balance across two dimensions: capability and cost.
V4.1 Flash sits squarely on that frontier curve. It may not be the most powerful model in absolute terms, but it delivers unmatched value for the price, given that it's "good enough" for most tasks. This positioning philosophy is instructive: for the vast majority of real-world applications, a model doesn't need to be the "smartest" — it just needs to be affordable while still getting the job done.
The Pareto Frontier originates from economist Vilfredo Pareto's theory of "Pareto optimality," referring to the boundary state in which no competing objective can be improved without sacrificing another. In the context of AI model selection, "intelligence" (capability) and "price" (cost) are two competing dimensions that trade off against each other. Every point on the Pareto Frontier represents an optimal combination of capability and price under current technological conditions — you can pay more for a stronger model, or accept a weaker model for a lower price, but you cannot get stronger capability at the same price. A model that falls inside the frontier curve means a competitor exists that offers either stronger capability at the same price, or the same capability at a lower price — and such models will gradually be eliminated from the market. This framework helps developers break free from the "chase the strongest model" mindset and instead ask: "Given my budget and task requirements, which model sits on the frontier?"
How to Use It: Plan with Flagship Models, Execute with Flash
The optimal usage strategy varies depending on how you access AI models.
Subscription Users
If you're on a subscription plan, keep using premium models for building complex applications and run as many tasks as you can before hitting rate limits.
API Pay-Per-Token Users
If you're on an API pay-per-token model, the more pragmatic approach is tiered routing: assign complex planning tasks to flagship-tier models, and hand execution off to V4.1 Flash. Tasks like code review, document extraction, and the "read" and "summarize" steps in long-chain agents are standardized enough to be handled efficiently by a lower-cost model.
A Commonly Overlooked Cost Trap
Here's an important caveat: V4.1 Flash generates an average of 43% more output tokens per task compared to its predecessor, V4 Flash. In other words, the model got smarter — but also more verbose.
A lower per-token price doesn't automatically translate to lower per-task costs. For cacheable, high-concurrency scenarios, the value proposition remains excellent. But for tasks with heavy output — like long-form creative writing — the significantly increased token count may actually make it less cost-effective. Users need to run the numbers for their specific use cases.
In large language model API billing, the token is the fundamental unit of cost — and input tokens and output tokens are typically priced differently, with output tokens usually costing more. "Token caching" (Prompt Caching) refers to a mechanism where, when multiple requests share the same prefix content (such as a system prompt or a long document), the API provider charges full price only for the first processing pass, with subsequent cache hits billed at a discounted rate — sometimes as low as 10% of the original price. This can dramatically reduce costs in high-concurrency scenarios where input content is highly repetitive. However, for output-heavy tasks like creative writing or long-form report generation, the caching advantage is limited, and an increase in model verbosity will directly inflate your bill. When evaluating the real-world savings of switching models, it's essential to separately measure your input-to-output token ratio and then calculate costs at their respective unit prices — rather than relying solely on the headline per-token rate.
A Striking Stat: China's Weekly AI Model Usage Is 4.7x That of the US
The analysis also surfaced a data point worth paying attention to: last week, China's AI large model weekly usage reached 67.46 trillion tokens — 4.7 times that of the United States — and has led for 21 consecutive weeks.
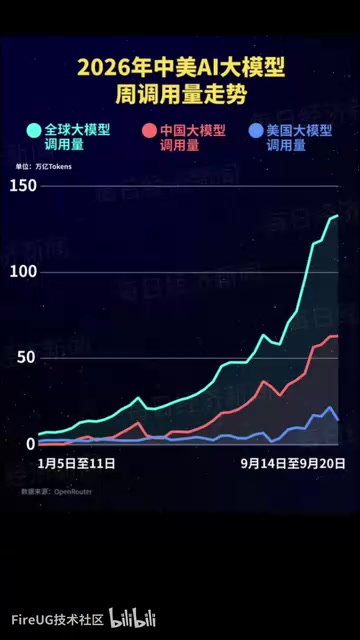
This number reflects China's enormous scale in AI application deployment and usage volume. V4.1 Flash's rise to the top is a microcosm of this trend — using a "good enough" philosophy, it's pulling a massive volume of tasks that previously required expensive models down to a much lower cost tier.
Final Thoughts: Cheaper or Stronger — Pick One
Small models can be good enough. That's the most direct takeaway from V4.1 Flash. For larger models, the logic becomes crystal clear: either get cheaper, or get meaningfully stronger — otherwise there's no reason to exist. As open-source models continue to demolish pricing floors, the next generation of flagship models will struggle to justify their price tags if they can't either cut costs or deliver a significant capability leap.
For developers currently on API pay-per-token plans, here's the practical question: what model are you running right now? If you switched to V4.1 Flash, how much "intelligence" would you be willing to trade away for how much savings? That may be the cost equation every team needs to recalculate.
Related articles

AI Compute Is the New Oil, But the Market Mechanism Has Yet to Take Shape
Hacker News compares AI compute to the new oil, noting the lack of price discovery, concentrated supply, and no hedging tools. The article analyzes structural issues in compute trading and explores a possible three-tier market of spot, contracts, and derivatives, plus the real impact on AI practitioners' cost management.

Running Full iOS 16.5 Firmware on Android Devices: Technical Demo or Marketing Gimmick?
A Hacker News post claims full iOS 16.5 firmware can run on Android, with 315 upvotes. This analysis argues it is more likely a web UI simulation than a true firmware port, and explores the value and risks of such projects.

Etsy Cracks Down on AI Slop: Addressing Buyer and Seller Anxieties
Etsy introduces stricter rules limiting AI-generated content in listings, addressing buyer confusion over AI products and seller fears of original work being diluted by AI slop.