Devin's Memory System & OpenAI's $30B Fundraise: Key AI Industry Developments This Week

OpenAI eyes $30B raise, Devin gets persistent memory, and EU rules drive AI watermarking.
This week in AI: OpenAI is reportedly in talks for a $30B funding round anchored by UAE sovereign funds, reflecting a national-scale race for AI infrastructure. OpenAI's TextGrain invisible watermarking technology aims to meet EU AI Act transparency requirements, though editing and translation can degrade the signal. Coding assistant Devin launched a "dreaming" memory system that reorganizes cross-session knowledge, moving toward a long-term collaborative partner. Reflection unveiled Beam, a sparse MoE model with 501B total parameters and ~23B activated. The throughline: AI companies are building technology and monetization infrastructure in parallel, with the moat extending well beyond the model itself.
AI packs a week's worth of major news into every seven days. From OpenAI's rumored $30 billion fundraising round, to Devin's memory system described as "dreaming," to invisible text watermarks designed to satisfy EU regulators — these developments reflect both technical progress and how AI companies are building business models around their models. Based on an edition of TLDR AI, this article traces the most noteworthy threads.
OpenAI's $30 Billion Fundraise and the Capital Landscape
The headline grabber is that OpenAI is reportedly in talks for a funding round that could reach $30 billion. According to reports, investment funds from the United Arab Emirates may serve as a key anchor for the deal, with several funds said to be discussing a combined commitment of up to $10 billion. Other potential participants include BlackRock, Thrive Capital, Andreessen Horowitz, and the University of California endowment.
The operative word here is "talks." This is an ongoing round where participants and amounts may still change. But even so, the spectacle of sovereign wealth funds and top-tier VCs entering together tells us something about how capital markets are betting on frontier AI companies: this is no longer just venture investment — it's a national-scale scramble for AI infrastructure.
Invisible Text Watermarks: A Transparency Tool Driven by Regulation
OpenAI plans to add text watermarks to eligible ChatGPT and Codex outputs to meet the transparency requirements of the EU AI Act. The method, called TextGrain, works by subtly adjusting word choices to form patterns that detection tools can identify.
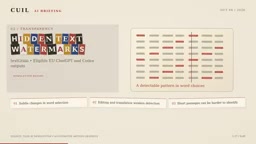
In other words, what you see still reads as normal prose — the watermark hides in the choice of words. But the approach has obvious limitations: editing, translation, or using very short excerpts can all degrade the signal. It shouldn't be treated as a foolproof way to identify all AI-generated content. This also reflects a broader reality — regulatory requirements can push technology into production, but the reliability boundaries of that technology remain, and transparency tools are more "best effort" than ironclad proof.
The EU AI Act came into force in 2024 as the world's first comprehensive legislation systematically regulating artificial intelligence. It classifies AI systems by risk level, and for "general-purpose AI" (GPAI) models — large foundation models like GPT and Claude — it requires transparency disclosures including training data summaries and technical documentation. For consumer-facing generative AI systems, the Act also explicitly requires users to be informed when content is AI-generated. Watermarking techniques like TextGrain represent an engineering path to meet this requirement: by injecting machine-readable hidden markers at the model output layer, compliance can be achieved without altering the user experience. It's worth noting that the EU AI Act has a phased enforcement timeline, with different provisions taking effect between 2025 and 2027 — meaning AI companies deploying watermarks now are also positioning themselves ahead of stricter future audit windows.
Devin's "Dreaming" Memory System
What really sparked discussion is the new memory system Devin launched. It's designed to retain user preferences, correction records, and project knowledge across sessions. If you explain how a project works or correct a recurring mistake, that information can inform future work.
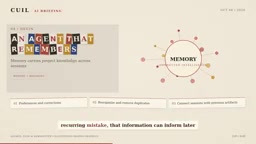
The "dreaming" process refers to the system periodically reorganizing these memories, removing duplicates, and linking them to past sessions and outputs. Science-fiction name aside, this is fundamentally an information management mechanism aimed at making accumulated experience more useful to the user. For a long-term collaborative coding assistant, persistent memory is the critical step from "one-off tool" to "growable partner."
What Happens When a Company Runs Many Coding Agents
The memory system raises a bigger question: what happens when a company runs many coding agents simultaneously? The news cited an analysis using Uber as its primary case study, exploring the concept of the "AI-native software factory."
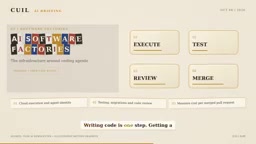
The analysis goes well beyond code generation to cover cloud execution, model access, agent identity, testing, migration, and code review. It also raises a very practical financial question: how much does it cost to get a pull request merged? Writing code is just the first step — getting a reliable change all the way to production requires an entire supporting workflow. This reminds us that the key metric for AI coding value is shifting from "can it write code?" to "can it reliably deliver?"
Agent identity is an infrastructure problem that's easy to overlook in the "AI-native software factory" context. When dozens or hundreds of coding agents are running in an enterprise, each needs to be granted access to code repositories, CI/CD pipelines, cloud resources, and external APIs. Traditional IAM (Identity and Access Management) systems were designed around human users, and agents' operating patterns — high-frequency, batch, cross-system — make permission boundaries harder to control and audit logs harder to interpret. Part of what makes the Uber case noteworthy is this: the maturity of an enterprise AI engineering practice is measured not just by how much code agents can generate, but by whether agent behavior can be brought within existing security compliance, change management, and accountability frameworks. This is the governance-layer problem engineering organizations must solve when upgrading from "AI-assisted coding" to "AI-native development workflows."
New Developments at the Model and Tooling Layer
On the model side, Reflection launched Beam. As described in the news, Beam is a sparse Mixture of Experts (MoE) model with 501 billion total parameters, activating roughly 23 billion for any given input. This architecture invokes only selected portions of the model during inference, targeting coding, reasoning, and agent tasks. Open weights and developer materials are planned for later in the month, so the release itself still bears watching.
Liquid AI is expanding its D1 decision model with visual capabilities. It can take images, text, or both, then return probabilities for questions like yes/no judgments, multiple choice, or scoring. Rather than writing long-form responses, it makes focused decisions — the company reports significant speed and cost advantages in comparisons, though these figures should be understood in the context of specific test tasks and benchmarks.
For creators, there's Frame Fields. It lets coding agents write TypeScript compositions for visual effects, kinetic typography, motion graphics, and 3D scenes, then inspect frames and render to MP4.
This gives developers another path to "build video with code," extending programming capabilities into content production.
Sparse Mixture of Experts (MoE) is a neural network architectural design approach. Unlike traditional "dense" models that activate all parameters on every inference pass, MoE models group parameters into multiple "expert" sub-networks and route each input to only a few of them. The core advantage: the model's total parameter count (which determines its knowledge capacity ceiling) can be made very large, while the actual computation per inference (which determines speed and cost) stays relatively small. Google's Gemini 1.5 and Mixtral both use similar architectures. Beam's 501 billion total parameters with ~23 billion activated represents an activation ratio of about 4.6%, meaning it aims to acquire the knowledge base of a much larger model at roughly the inference cost of a 23-billion-parameter dense model. This architecture is particularly attractive for coding and agent tasks, which demand both knowledge breadth (understanding many languages and frameworks) and sensitivity to inference latency.
Two Threads in AI Commercialization
The last two items point toward broader industry direction. One is an analysis of the OpenAI commercial marketplace, sketching a possible future where enterprises buy AI applications through a shared platform with simpler budgeting and billing. The other is OpenAI expanding its advertising business within ChatGPT, rolling out new visual formats and additional measurement tools.
Taken together, these two developments clearly illustrate how AI companies are simultaneously building technology and business — the model is the product, but the real moat lies in the distribution, billing, and monetization infrastructure built around it. From fundraising to watermarks, from memory systems to ad formats, the week's news assembles a picture of an AI industry rapidly moving from laboratory to commercial infrastructure.
Related articles

The Chaotic Aesthetics of Apple's HomeView Ad: A Marketing Code Only Parents Can Read
Apple's HomeView smart display ad ditches minimalist style for chaotic family mornings to win over parents. We analyze why it confuses most viewers but resonates instantly with families — and the trade-offs and risks of Apple's targeted marketing.

Cerebras CEO Pushes Back on AI Doomerism: Stop Spreading Panic
Cerebras CEO Andrew Feldman publicly pushes back on AI doomerism at TechCrunch Disrupt, arguing excessive risk focus drowns out AI's real opportunities.

Retooling in Minutes: Industrial Next Redefines Factory Robot Flexibility
Industrial Next aims to let factory robots retool in minutes instead of weeks, automating complex delicate tasks and advancing flexible manufacturing and small-batch production.