Gemini 4 Hydrogen Explained: Google's Lightweight, High-Speed AI Model

Google splits Gemini 4 into three models; Hydrogen targets lightweight use via speed and tiered reasoning budgets.
Based on a Gemini 4 Hydrogen breakdown video, the article outlines Google's Gemini 4 family: Carbon and Argon handle complex reasoning, while Hydrogen sells on speed with four thinking levels (Low to Extra High) that allocate reasoning by task. It covers Google's multi-model orchestration in Antigravity, where an orchestrator splits tasks across agents to match capability and cost. Hydrogen adds multimodal support and ~100K token context for fast screening, and the piece warns that benchmarks don't equal real performance and model selection is now an ongoing engineering decision.
Title
Gemini 4 Hydrogen Explained: Google's Lightweight, High-Speed AI Model
Meta Description
An analysis of Google's Gemini 4 Hydrogen model: a lightweight, high-speed AI assistant with four thinking levels, multimodal support, and a ~100K token context, plus the Carbon/Argon model family and multi-agent orchestration.
Article Content
Google's Gemini 4 series isn't a single model but a family split by task complexity. According to a breakdown video on Gemini 4 Hydrogen from a Bengali-language tech channel on YouTube, the series includes at least three members—Carbon, Argon, and Hydrogen—each with a distinctly different role: Carbon and Argon target complex reasoning and hard problem-solving, while Hydrogen's core selling point is just one thing—speed.
This "tiered release" approach isn't new, but Google singling out "speed" as its own model tier sends a clear signal: the center of gravity in AI product competition is shifting from "who's smarter" to "who's more cost-effective in which scenario."
Hydrogen's Positioning: Trading Depth for Speed
The video puts it plainly: Hydrogen's goal is to "provide lightweight AI assistance in less time." In other words, it doesn't try to go head-to-head on hard problems; it serves everyday tasks that need fast responses and don't require deep thinking.
This positioning maps directly to Google's tiered design around thinking budget. Hydrogen offers four thinking levels—Low, Medium, High, and Extra High—so users and developers can choose how much reasoning resources to invest based on task difficulty. According to Google as cited in the video, Hydrogen's scores at the Extra High level are "close to top-tier"—but that claim needs to be read carefully, as discussed below.
The implication at the application layer is that making a lightweight model fast enough often unlocks more product forms than making a large model slightly smarter. Real-time assistants, batch task processing, embedded AI features—these scenarios are far more sensitive to latency than to reasoning depth.
Thinking budget is an important engineering concept on the inference side of large models in recent years, referring to the amount of reasoning tokens or compute a model is allowed to consume before generating an answer. It's typically implemented by letting the model expand a longer internal "chain of thought": the higher the budget, the more likely the model is to try multiple solution paths, self-check, and correct errors, improving accuracy on hard problems; the lower the budget, the shorter the first-token latency and total time, and the lower the cost. This mechanism breaks the traditional assumption that "model capability is fixed," allowing the same model to be continuously adjusted between "fast and shallow" and "slow and deep." For product teams, the thinking budget is effectively a billable knob that lets a single set of model weights cover everything from real-time conversation to complex reasoning, and lets developers make explicit trade-offs among latency, accuracy, and cost.
Reasoning Levels: The Engineering Philosophy of Allocating Compute by Task
Hydrogen's four thinking levels are essentially a "reasoning budget" management mechanism. The video's description of each level can be summarized as:
- Low: Handles simple, routine tasks with the fastest response;
- Medium: A transitional level between the two;
- High: The default level, suited to complex code completion, bug localization, complex mathematical proofs, and other scenarios that need "a bit more thought";
- Extra High: The highest reasoning investment reserved for the hardest tasks.
The video makes a point worth expanding on: not every task needs the maximum reasoning capability, and allocating reasoning on demand is the "smart" way to use it. This is in fact a core consensus in current AI engineering practice—using a large model for a simple classification task is as wasteful as using a calculator to solve a linear equation.
But there's a real tension here: the finer the thinking levels, the higher the cost of tuning and evaluation. Developers need to judge "which level this task should use," and that judgment itself may take longer than the task. Whether Google can automate this choice will directly affect the practical value of the mechanism.
Not Relying on a Single Model: Multi-Agent Orchestration
The video raises a valuable key question: why should completing a full piece of work require only one large model?
The answer is that complex software engineering tasks are naturally suited to decomposition. The example given is: an orchestrator model handles overall planning and breaks the task into small pieces; then different agents respectively write code for specific features, write unit tests, and review whether the code works. These agents can run in parallel or serially as needed.
The "orchestration" mechanism Google provides in Antigravity allows switching between different models like Carbon and Hydrogen within the same session as needed—calling a strong reasoning model where deep planning is required, and switching to a lightweight model where fast execution is required. This "model routing" approach builds cost control and capability matching into the architecture, rather than making users manually shuffle between multiple tools.
This also explains why Hydrogen's existence makes sense: in an orchestration system, you need both a "brain" and "hands and feet," and the hands and feet don't need to be as expensive as the brain.
Multi-agent orchestration refers to an architectural pattern in which an orchestrator decomposes a complex task into subtasks, dispatches them to role agents with different capabilities or prompts, and finally aggregates the results. The fundamental difference from single-model one-shot generation is that the task is explicitly split, each subtask can use a different model, tool, or context, and scheduling can be parallelized to shorten total latency. Common roles include planner, coder, test writer, and reviewer, passing intermediate artifacts to one another via structured messages. The key engineering challenges are the granularity of task decomposition, state synchronization among sub-agents, failure retries, and result merging. The orchestration layer is also where cost control lands—routing simple subtasks to lightweight models and calling strong reasoning models only for planning and review can significantly reduce overall overhead while preserving quality.
Multimodal Capabilities: Hydrogen's Practical Side
The video mentions that Hydrogen can handle multiple types of information such as text, images, audio, and video, and can be used to analyze data, spot important trends and anomalies, and handle tasks like chart, screenshot, audio, and video analysis.
Multimodality appearing at this model tier shows two things. First, multimodality is no longer exclusive to flagship models and is trickling downward; second, for lightweight models, the practical value of multimodality lies more in "fast screening" than "deep understanding"—for example, quickly scanning a batch of screenshots for anomalies or quickly processing a batch of audio for preliminary classification. These tasks demand less precision but high throughput, which fits Hydrogen's positioning perfectly.
The video also mentions a context capacity of about 100K tokens, enough for multi-file analysis within a single session but still noticeably short of flagship models that reach millions. For full analysis of large code repositories, Hydrogen will most likely need to be paired with retrieval or chunking strategies.
Context window refers to the upper limit on the total number of tokens a model can simultaneously read and reference in a single session, covering user input, model output, and retrieved documents injected into the context. 100K tokens is roughly equivalent to several hundred pages of text or dozens of medium-length source code files, enough to support multi-file comparative analysis within a single session. But it's important to distinguish "fitting it in" from "using it well": as context grows, the model's attention to mid-context information often decays—the so-called "needle in a haystack" retrieval reliability declines—and long contexts linearly increase latency and cost. Therefore, when dealing with large code repositories, it's usually necessary to combine retrieval-augmented generation (RAG), chunked summarization, or on-demand loading to feed only the truly relevant fragments into the window, rather than cramming everything in at once.
Limitations and Model Selection: A Clear-Eyed View of Benchmarks
The video offers several relatively clear-eyed judgments at the end that deserve separate mention.
First, benchmark scores don't equal real-world performance. The video explicitly warns that good scores don't mean the model is reliable on every real task. Although Hydrogen has multiple thinking levels, it still doesn't guarantee a correct solution to complex problems; some scenarios may require stronger reasoning models, domain-specific fine-tuning, or specific tooling.
Second, model selection can't rely on intelligence alone. The video's advice is: when choosing an AI model, consider performance and cost in addition to intelligence. The strongest model isn't necessarily the most suitable choice—matching to needs is the right approach. This view is especially important today—after the explosion in the number of models, "which one to choose" has become a more common engineering question than "is there one."
Third, AI is still a tool. The gist of the video's original wording is: AI is a powerful tool, but building reliable software still requires sound engineering practices. In an era saturated with narratives of "AI replacing programmers," this is a pragmatic reminder.
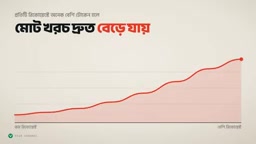
The gap between benchmarks and real-world performance is a common pitfall in model evaluation. Benchmarks are usually measured on fixed datasets, fixed prompt templates, and single-turn Q&A settings, whereas real tasks often involve multi-turn clarification, tool calls, long-document references, and ambiguous instructions—a distribution that doesn't match the evaluation set. In addition, public benchmarks risk contamination by training data, and models may appear inflated on questions they've seen before. A more reliable approach is to build a small private evaluation set close to your own business, compare candidate models on accuracy, latency, and per-call cost using real inputs, and combine human spot checks to identify failure modes. For tier-level claims of being "close to top-tier," it's especially important to confirm the specific test conditions and task types they correspond to.
Practical Implications for Developers
Putting the video's content together, the core message of Gemini 4 Hydrogen is: competition among AI models is shifting from single-dimensional capability contests to a combination of "model family + orchestration system."
The direct impact on developers comes in three points. First, model selection will become an ongoing engineering decision rather than a one-time configuration; second, parameters like thinking budget, context length, and multimodal support will become configuration items that need tuning, much like database connection counts; third, multi-agent collaboration architectures will become increasingly common, and understanding how to decompose tasks and allocate models will matter more than simply knowing how to use a particular model.
The video's final judgment about the future is: software development won't be a solo human endeavor but a product of collaboration among developers, intelligent AI models, and automated agents. Whether that judgment is accurate remains to be verified over time, but at least judging from the emergence of "lightweight but sufficient" models like Hydrogen, the direction is clear.
One-line Summary
Google splits Gemini 4 into three models, with Hydrogen targeting lightweight scenarios through speed and tiered reasoning budgets.
Paragraph Summary
Based on a breakdown video of Gemini 4 Hydrogen, the article outlines the family layout of Google's Gemini 4 series: Carbon and Argon handle complex reasoning, while Hydrogen's core selling point is speed, allocating reasoning resources by task through four thinking levels from Low to Extra High. The article further discusses Google's multi-model orchestration mechanism in Antigravity, which lets an orchestrator model decompose tasks and different agents execute them separately, thereby matching capability and cost at the architectural level. Hydrogen offers multimodal capabilities across text, images, audio, and video plus a ~100K token context, positioned toward fast screening rather than deep understanding. The conclusion reminds readers that benchmarks don't equal real-world performance, that model selection should weigh intelligence, performance, and cost together, and that model selection is becoming an ongoing engineering decision.
Related articles
vLLM v0.34.0 Released: The Inference Engine Levels Up Again
vLLM releases v0.34.0, tagged by khluu with two asset files. This article reviews the release info and how developers should cautiously evaluate upgrades given missing release notes.
Gemini 4 Argon Lands on Anti-Gravity: How Multi-Agent Systems Are Reshaping the Development Workflow
Google's agent-first platform Anti-Gravity integrates Gemini 4 Argon, using multi-agent looping workflows to generate 3D worlds from text, turn photos into racing games, and enable end-to-end hardware design, now available on desktop, CLI, and Android Studio.
Antigravity Deep Dive: The Agent Command Center After Gemini CLI's Retirement
Google pivots its 107k-star Gemini CLI, migrating users to Anti-Gravity. This article breaks down its Agent Manager multi-agent collaboration, browser self-verification, Artifacts evidence chain, quota pricing, and migration pitfalls, analyzing which developers it suits.