Gemini 4 Hydrogen xhigh Hands-On: Generates Playable Game in One Shot, Still Trails Opus
Gemini 4 Hydrogen with default high reasoning produces broken games; xhigh delivers one-shot playable results but still trails Opus and Fable.
A YouTube creator ran a reasoning-effort comparison on Gemini 4's Hydrogen model, giving each result only one prompt with no second-round fixes. Under default high, the generated game had a clickable UI and triggerable skills, but the interaction chain broke and abilities vanished—rated "basically unusable." Switching to xhigh changed everything: the game had a Nexus-like framework, W/E keys mapped to dash/teleport, and the ultimate and smooth animations all worked, making it the best Gemini-series result the creator tested. Still, character modeling remained weird and clearly behind Opus and Fable. The takeaway: higher reasoning effort fixes functional correctness, not aesthetic or creative quality—and benchmark scores are worth exploring but still need hands-on verification.
Can a single prompt actually produce a working game?
A YouTube creator ran a reasoning-effort comparison test on Gemini 4's Hydrogen model. The testing method was strict: each result got only one prompt, with no second-round bug fixes—the model had to produce a runnable game or interactive page "in one shot."
The conclusion is dramatic. Under the default high reasoning setting, the same model's output was "basically unusable"—the UI was clickable and skills could fire, but some abilities would mysteriously disappear, and the whole thing was extremely buggy. When reasoning effort was switched to xhigh, the result was completely different.
Default high reasoning: it runs, but it's far from usable
The creator's assessment of the high reasoning version was blunt: straight up doesn't work. It wasn't completely dead—the mouse could click and character skills could trigger—but the interaction chain was broken, and some abilities would vanish as you used them.
This detail is worth noting: the failure wasn't "nothing was generated," but rather a half-finished product that looked complete on the surface but was riddled with holes underneath. For vibe coding scenarios, this failure mode is more troublesome than an outright error, because someone has to locate exactly which link in the chain broke.
Reasoning effort is a common adjustable parameter in current large model APIs, representing the "thinking budget" the model is allowed to consume before giving its final answer. It typically manifests as the length of the internal reasoning chain, the number of sampling candidates, or the upper limit of thinking tokens. Lower settings respond faster and cost less, suitable for simple Q&A; higher settings let the model do more self-checking and planning before generating code, thereby reducing logic error rates. Naming conventions vary across vendors—common tiers include low / medium / high, plus xhigh (extra high) which extends further. Note that reasoning effort doesn't change the model parameters themselves; it adjusts "how long to think," so it delivers the biggest gains on tasks requiring multi-step state maintenance (such as game loops, skill cooldowns, collision detection), while having limited impact on aesthetic-style outputs.
xhigh reasoning: one-shot generation, silky-smooth animation
The creator originally planned to give up, but because benchmarks showed xhigh performing better than Argin, they gave it a second chance. This time, Hydrogen on xhigh was rated as "even better than what Carbon produced."
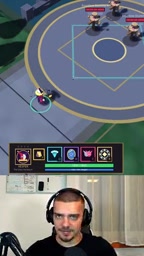
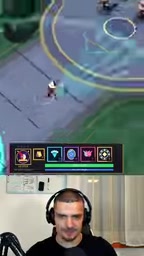
In terms of specifics, the game had a framework similar to Nexus, the skill system worked, the W and E keys each corresponded to some kind of dash/teleport ability, and there was also an ultimate. The creator specifically mentioned the animation was "very smooth" and expressed liking the overall look and feel.
Vibe coding refers to a development approach where intent is described in natural language and the model directly produces runnable code, with the developer acting more as an "acceptor" than a line-by-line writer. Its typical workflow is: one sentence or a description → the model generates complete files → run directly in the browser or locally → add prompts to patch issues when found. Since it skips the traditional manual coding and unit testing steps, one-shot correctness becomes a key metric. That's precisely why "give only one prompt, no second-round fixes" is a meaningful stress test: it exposes the model's real delivery capability without human error correction—a capability that directly determines time costs in the prototyping phase.
Side-by-side comparison: beats its own siblings, loses to Opus and Fable
Looking at the results together, Hydrogen on xhigh is the best of the Gemini series the creator has tested. But it still has two obvious weaknesses:
- Character modeling is still weird, and the art quality hasn't reached a usable level;
- A clear gap with competitors—the creator said outright it's "far from the results of Opus and Fable."
This shows that raising reasoning effort solves the problem of logic and functional correctness—getting code to run and interactions to close the loop; but aesthetics, character design, and other areas leaning toward creativity and expressiveness did not leap forward in step with reasoning effort.
The Hydrogen, Carbon, Argin, Opus, and Fable mentioned in this article are all codenames for different models or model versions. In cross-comparison evaluations, different versions from the same vendor often share architecture and training data distribution, with differences mainly in scale, post-training strategy, and reasoning budget—so wins and losses among "siblings" reflect tuning priorities more than anything. Cross-vendor comparisons, on the other hand, are more likely to expose systemic gaps in expressiveness dimensions like art assets, character modeling, and animation curves. This is why, under the same prompt, functional logic can be patched up by raising reasoning effort while character design still lags noticeably—the latter depends on design priors in the training data and multimodal generation capability, not mere compute budget.
What this hands-on test reveals
First, reasoning effort has an order-of-magnitude impact on Gemini 4's output quality. Same model, same prompt—high and xhigh span everything from "unusable" to "best in the series." Developers who draw conclusions after only trying the default setting may well underestimate the model's true ceiling.
Second, generating complete interactive content in a single prompt is still lossy. The creator insisted on no second-round debugging precisely to test the model's one-shot capability. From the results, xhigh can already deliver a playable prototype, but it's still some distance from "ready to use."
Third, there's tension between benchmark rankings and subjective experience. The creator only went back to retry because benchmark scores pointed the way, and the actual experience did confirm xhigh > Argin. This reminds us that benchmark scores can serve as a reference for exploring directions, but ultimately you still need to run things yourself.
Related articles

Gemini 4 Neon Review: Benchmark Scores Rival Carbon, API Pricing and Quota Breakdown
Google Gemini 4 Neon is now live, benchmark scores closely tracking Carbon, API pricing 3/15 at twice Hydrogen's rate. This article compiles Bilibili creator testing: Neon can replace 90% of Carbon scenarios, AntiGravity quota consumption is only one-third of Carbon, plus subscription channel restrictions and 2API ban risks.

Gemini 4 Helium Coming Soon? Signals of Google Loosening Subscription Restrictions
Google team member hints releases will continue; community speculates Gemini 4 Helium (Flash Lite) may be next. Subscription ban controversy gets a response as product lead says "Soon," suggesting restrictions may be lifted. This article covers Gemini developments, OpenAI Coding Agent and risk management, Doubao real-time audio-video API, and compute business dynamics.

AI-Assisted React Development in Practice: Optimizing a Video App and Handling Errors
A 14-year veteran developer demonstrates AI-assisted React video app optimization: compressing video from 80MB to 5MB (~94%) via ImageKit, plus reliable error handling and retry mechanisms. Includes planning, code understanding, and verification methods for working with AI.