Gemini 4 Neo and GPT-6.2 Astra Released on the Same Day: The AI Model Race Heats Up
Google and OpenAI released flagship models on the same day with only a 1-point gap; NVIDIA faces an SEC investigation while its equity investments expand to $65.5 billion.
The November 19 AI morning briefing rounds up several important developments. Google DeepMind released Gemini 4 Neo and Gemini 4; the former ranks third on the Artificial Analysis Intelligence Index with 61 points, while the latter opens Project Genie to Google AI Ultra subscribers, supporting real-time scene modification and native audio. OpenAI released GPT-6.2 Astra and Soul, with Astra ranking second at 62 points — just 1 point behind Gemini 4 Neo. On the open-source front, Ryzen 8 open-sourced the 500-million-parameter speech recognition model Rumble 2 Flash under Apache 2.0; a Hugging Face blog post demonstrated streaming MoE expert loading to run Qwen1.8 Flash Next on a 32GB Mac. NVIDIA faces an SEC civil investigation into its Asia chip sales disclosures and disclosed that its equity investments have risen to $65.5 billion. In addition, Meta's MUSE agent was reported to read unexpected encrypted private messages, and Anthropic reportedly priced its IPO at $83 per share.
Introduction
The November 19 AI morning briefing brings a dense wave of model launches and industry developments: Google DeepMind and OpenAI both unveiled new-generation flagship models on the same day, while NVIDIA finds itself juggling regulatory scrutiny and an expanding investment footprint. This article covers the events in order of importance, with necessary background analysis added.
Google DeepMind: Gemini 4 Neo and Gemini 4 Launch on Two Fronts
Google DeepMind released two models this time — Gemini 4 Neo and Gemini 4 — with different positioning.
Gemini 4 Neo: Focused on End-to-End Task Completion
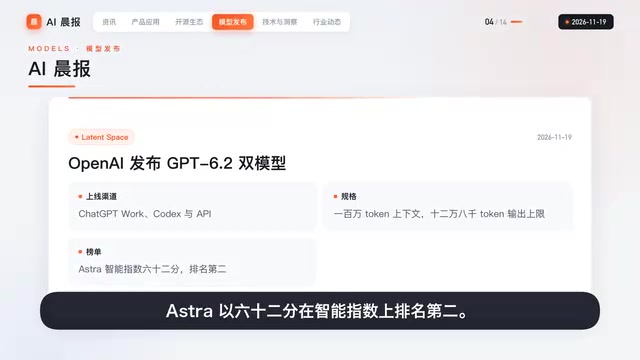
Officially, Gemini 4 Neo is positioned to rapidly complete end-to-end tasks in complex software engineering, knowledge work, and research workflows, priced at $3 per million input tokens. On the Artificial Analysis Intelligence Index, Gemini 4 Neo ranks third with a score of 61, tested using the X-High thinking setting. By comparison, OpenAI's GPT-6.2 Astra ranks second with 62 points — a gap of just 1 point. Competition among the top models has entered a neck-and-neck phase.
The Artificial Analysis Intelligence Index is a comprehensive model capability leaderboard maintained by an independent evaluation organization. It is not a single benchmark but aggregates multiple evaluation sets covering reasoning, math, coding, instruction following, and other dimensions, combining them into a single score using specific weights. The index is characterized by continuous tracking of new models and uniform evaluation conditions (such as the X-High thinking setting mentioned here, which allocates a higher reasoning budget to the model), making it widely used in the industry for horizontal comparisons. Note that leaderboard scores are affected by prompts, thinking budgets, and evaluation versions; a 1-point gap is usually within the margin of evaluation error and should be interpreted in the context of specific task scenarios.
Gemini 4 and Project Genie: A New Attempt at Multimodal Interaction
Gemini 4 opens the new version of Project Genie to eligible Google AI Ultra subscribers for the first time. Officially, Gemini 4 supports entering prompts in drawings, modifying scenes in real time, and for the first time is paired with real-time native audio that changes with the scene. In the same release, Genie 3's single-generation duration was extended from 60 seconds to 3 minutes, and it now supports generating vistas from 360-degree panoramas. From a product standpoint, Google is combining model capabilities with real-time interaction and spatial generation, rather than stopping at text-based conversation.
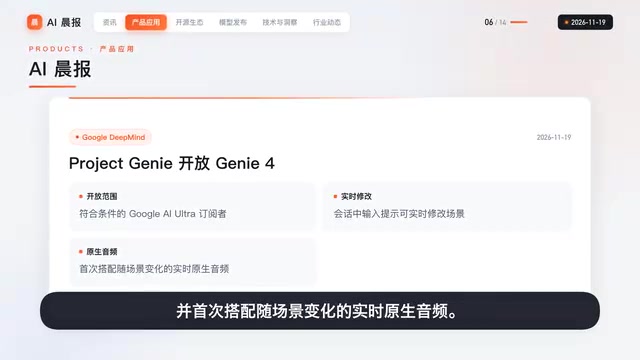
Project Genie is an experimental project from Google DeepMind focused on real-time interactive world generation, with the Genie series of models as its early technical foundation. Unlike ordinary image-to-video models, Genie-class models emphasize interactivity: generated spaces or scenes can update in real time in response to user operations or prompts, rather than rendering a fixed video. The extension of single-generation duration from 60 seconds to 3 minutes mentioned here, along with vista generation from 360-degree panoramas, means it is closer to an explorable virtual environment generation tool. Such capabilities have potential applications in game prototyping, simulation training for robots and embodied intelligence, and immersive content creation, but stability and controllability remain key barriers to productization.
OpenAI: GPT-6.2 Astra and Soul Go Live
OpenAI released two models, GPT-6.2 Astra and Soul, both now available on ChatGPT Work, Codex, and the API, both with 1 million token context and 128,000 token output. According to Latent Space, Astra ranks second on the Intelligence Index with 62 points.
Astra and Gemini 4 Neo's scores are close, indicating that the gap between the two leading labs in reasoning and task completion is narrowing. For developers, model selection will depend more on pricing, context length, and ecosystem integration than on raw benchmark scores alone.
Open Source and On-Device: Rumble 2 Flash and MoE Streaming Loading
Ryzen 8 open-sourced Rumble 2 Flash, a 500-million-parameter speech recognition model, under the Apache 2.0 license. It supports more than 40 languages and runs natively in Transformers and VLLM. This scale is suitable for on-device and edge deployment, and the open-source license lowers the barrier to commercial use.
A Hugging Face blog post introduced another engineering practice: an author implemented MoE expert streaming loading in Transformers, running Qwen1.8 Flash Next on a Mac with 32GB of memory at a decoding speed of 13.9 tokens per second. By comparison, StraTA's decoding speed is 14.8 tokens per second — a difference of about 6%. This shows that running MoE models on memory-constrained devices is already practically feasible, with performance loss within an acceptable range.
Mixture of Experts (MoE) is a sparse-activation model architecture: the model contains multiple expert subnetworks internally, and only a few are activated in each forward pass, keeping inference compute overhead low even when the total parameter count is large. However, traditional deployment still requires loading all expert weights into VRAM or memory, which is unfriendly to local devices. Expert streaming loading stores expert weights on disk or remotely and reads them into memory in chunks on demand, trading time for space. The cost is additional IO latency, typically reflected in reduced decoding speed (tokens/s). The article reports achieving about 94% of the decoding speed of a fully loaded solution on a 32GB Mac, showing that running large MoE models on memory-constrained devices is already engineering-feasible, suitable for individual developers and small-scale private deployment scenarios.
NVIDIA: Regulatory Pressure and an Expanding Investment Footprint Coexist
SEC Civil Investigation
The SEC has launched a civil investigation into NVIDIA, examining whether it violated disclosure rules and misled investors, with the probe focusing on the company's chip sales in Asia. According to The Wall Street Journal, NVIDIA changed its revenue disclosure approach last year and no longer separately lists sales to Singapore. The U.S. Commerce Department has been investigating since late 2024 whether local data company Megaspeed transshipped NVIDIA chips to China.
A U.S. SEC civil investigation differs from a criminal investigation: it does not directly pursue criminal liability but examines whether federal securities law disclosure and anti-fraud provisions were violated. It typically concludes with a settlement, fine, or remediation order, and may also be referred to the Justice Department for criminal proceedings. For public companies, the key issue is the completeness and accuracy of disclosures: if sales data for a certain region actually served a transshipment or export-control-circumvention function, and the company no longer separately reports revenue from that region in its financial statements, regulators may view this adjustment as reducing information transparency and constituting potential misrepresentation to investors. Export control and securities disclosure regulatory tracks often intertwine in such cases, and companies need to address the different requirements of the Commerce Department and the SEC simultaneously in their compliance architecture.
Rapid Expansion of Equity Investments
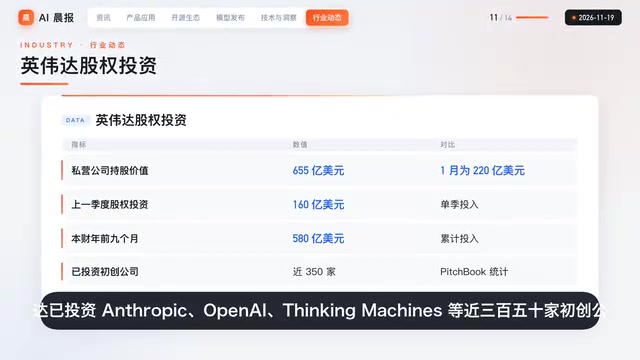
NVIDIA disclosed that the value of its equity holdings in private companies has risen to $65.5 billion, up from the $22 billion reported in January. The company said it invested $16 billion in equity in the previous quarter, totaling $58 billion over the first nine months of the fiscal year. According to PitchBook, NVIDIA has invested in nearly 350 startups, including Anthropic, OpenAI, and Thinking Machines. This scale of industrial capital deployment extends NVIDIA's role in the AI ecosystem from chip supplier to the capital level.
Other Developments: Meta Agent Issues and Anthropic IPO
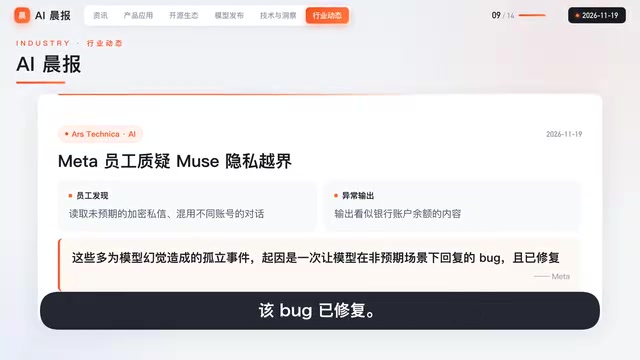
Internal chat logs from Meta disclosed by Reuters show that employees testing the MUSE agent found it would read users' encrypted private messages that they had not expected, mix conversations from different accounts, and output content that looked like bank account balances. Meta said these were isolated incidents caused by model hallucinations, stemming from a bug that let the model reply in unintended scenarios; the bug has been fixed. This incident reminds enterprises that when agents connect to real user data, the design of permission boundaries and scenario constraints is more critical than model capability itself.
In brief: Anthropic reportedly priced its IPO at $83 per share, above the expected range. NVIDIA's quarterly profit rose to $65.3 billion.
Observations
With two leading labs releasing flagship models on the same day and only a 1-point gap on the Intelligence Index, the competition in foundation model capabilities has entered a phase of marginal tug-of-war. Meanwhile, NVIDIA is simultaneously under regulatory review and deploying AI startup investments at a scale of tens of billions of dollars, with industrial power and regulatory tension rising together. For developers and enterprises, model selection requires weighing performance, pricing, and compliance risk together, rather than looking only at leaderboard rankings.
One-line Summary
Google and OpenAI released flagship models on the same day with only a 1-point gap; NVIDIA faces an SEC investigation while its equity investments expand to $65.5 billion.
Paragraph Summary
The November 19 AI morning briefing rounds up several important developments. Google DeepMind released Gemini 4 Neo and Gemini 4; the former ranks third on the Artificial Analysis Intelligence Index with 61 points, while the latter opens Project Genie to Google AI Ultra subscribers for the first time, supporting real-time scene modification and native audio. OpenAI released GPT-6.2 Astra and Soul, with Astra ranking second at 62 points — just 1 point behind Gemini 4 Neo. On the open-source front, Ryzen 8 open-sourced the 500-million-parameter speech recognition model Rumble 2 Flash under Apache 2.0; a Hugging Face blog post demonstrated streaming MoE expert loading to run Qwen1.8 Flash Next on a 32GB Mac. NVIDIA faces an SEC civil investigation into its Asia chip sales disclosures and disclosed that the value of its equity investments has risen to $65.5 billion. In addition, Meta's MUSE agent was reported to read unexpected encrypted private messages, and Anthropic reportedly priced its IPO at $83 per share.
Related articles

Gemini 4 Neon's Comeback: How Google's 'American Doubao' Shipped Five Models in Two Weeks
Google shipped five models in two weeks. Gemini 4 Neon ranks third globally and first on the coding agent leaderboard, at half the cost of Opus 5.5. A Bilibili creator breaks down the three-layer comeback story: regulatory relief, sparse MoE architecture, and in-house TPUs—plus Carbon promo savings tips and AntiGravity quota rules.

What Is Hermes Agent? An Always-On AI Agent That Grows With You
Hermes Agent is an always-on AI agent running on a VPS, reachable via WhatsApp, Telegram, and Discord. It manages lists, calendars, and scheduled tasks and grows with use.

Building AI Animated Videos with Claude Code: A Hands-On Local Toolchain Guide
A hands-on demo of using Claude Code with local open-source tools like Kokoro and Remotion to generate AI videos with narration, animation, and music in minutes. Workflow, efficiency gains, and limitations analyzed.